Compression is prediction | ngrok blog
Compression and LLMs are trying to solve the exact same problem: predicting what comes next. Learn the fundamentals of compression and how better prediction leads to better shrinkage.
Compression and LLMs are trying to solve the exact same problem: predicting what comes next. Learn the fundamentals of compression and how better prediction leads to better shrinkage.
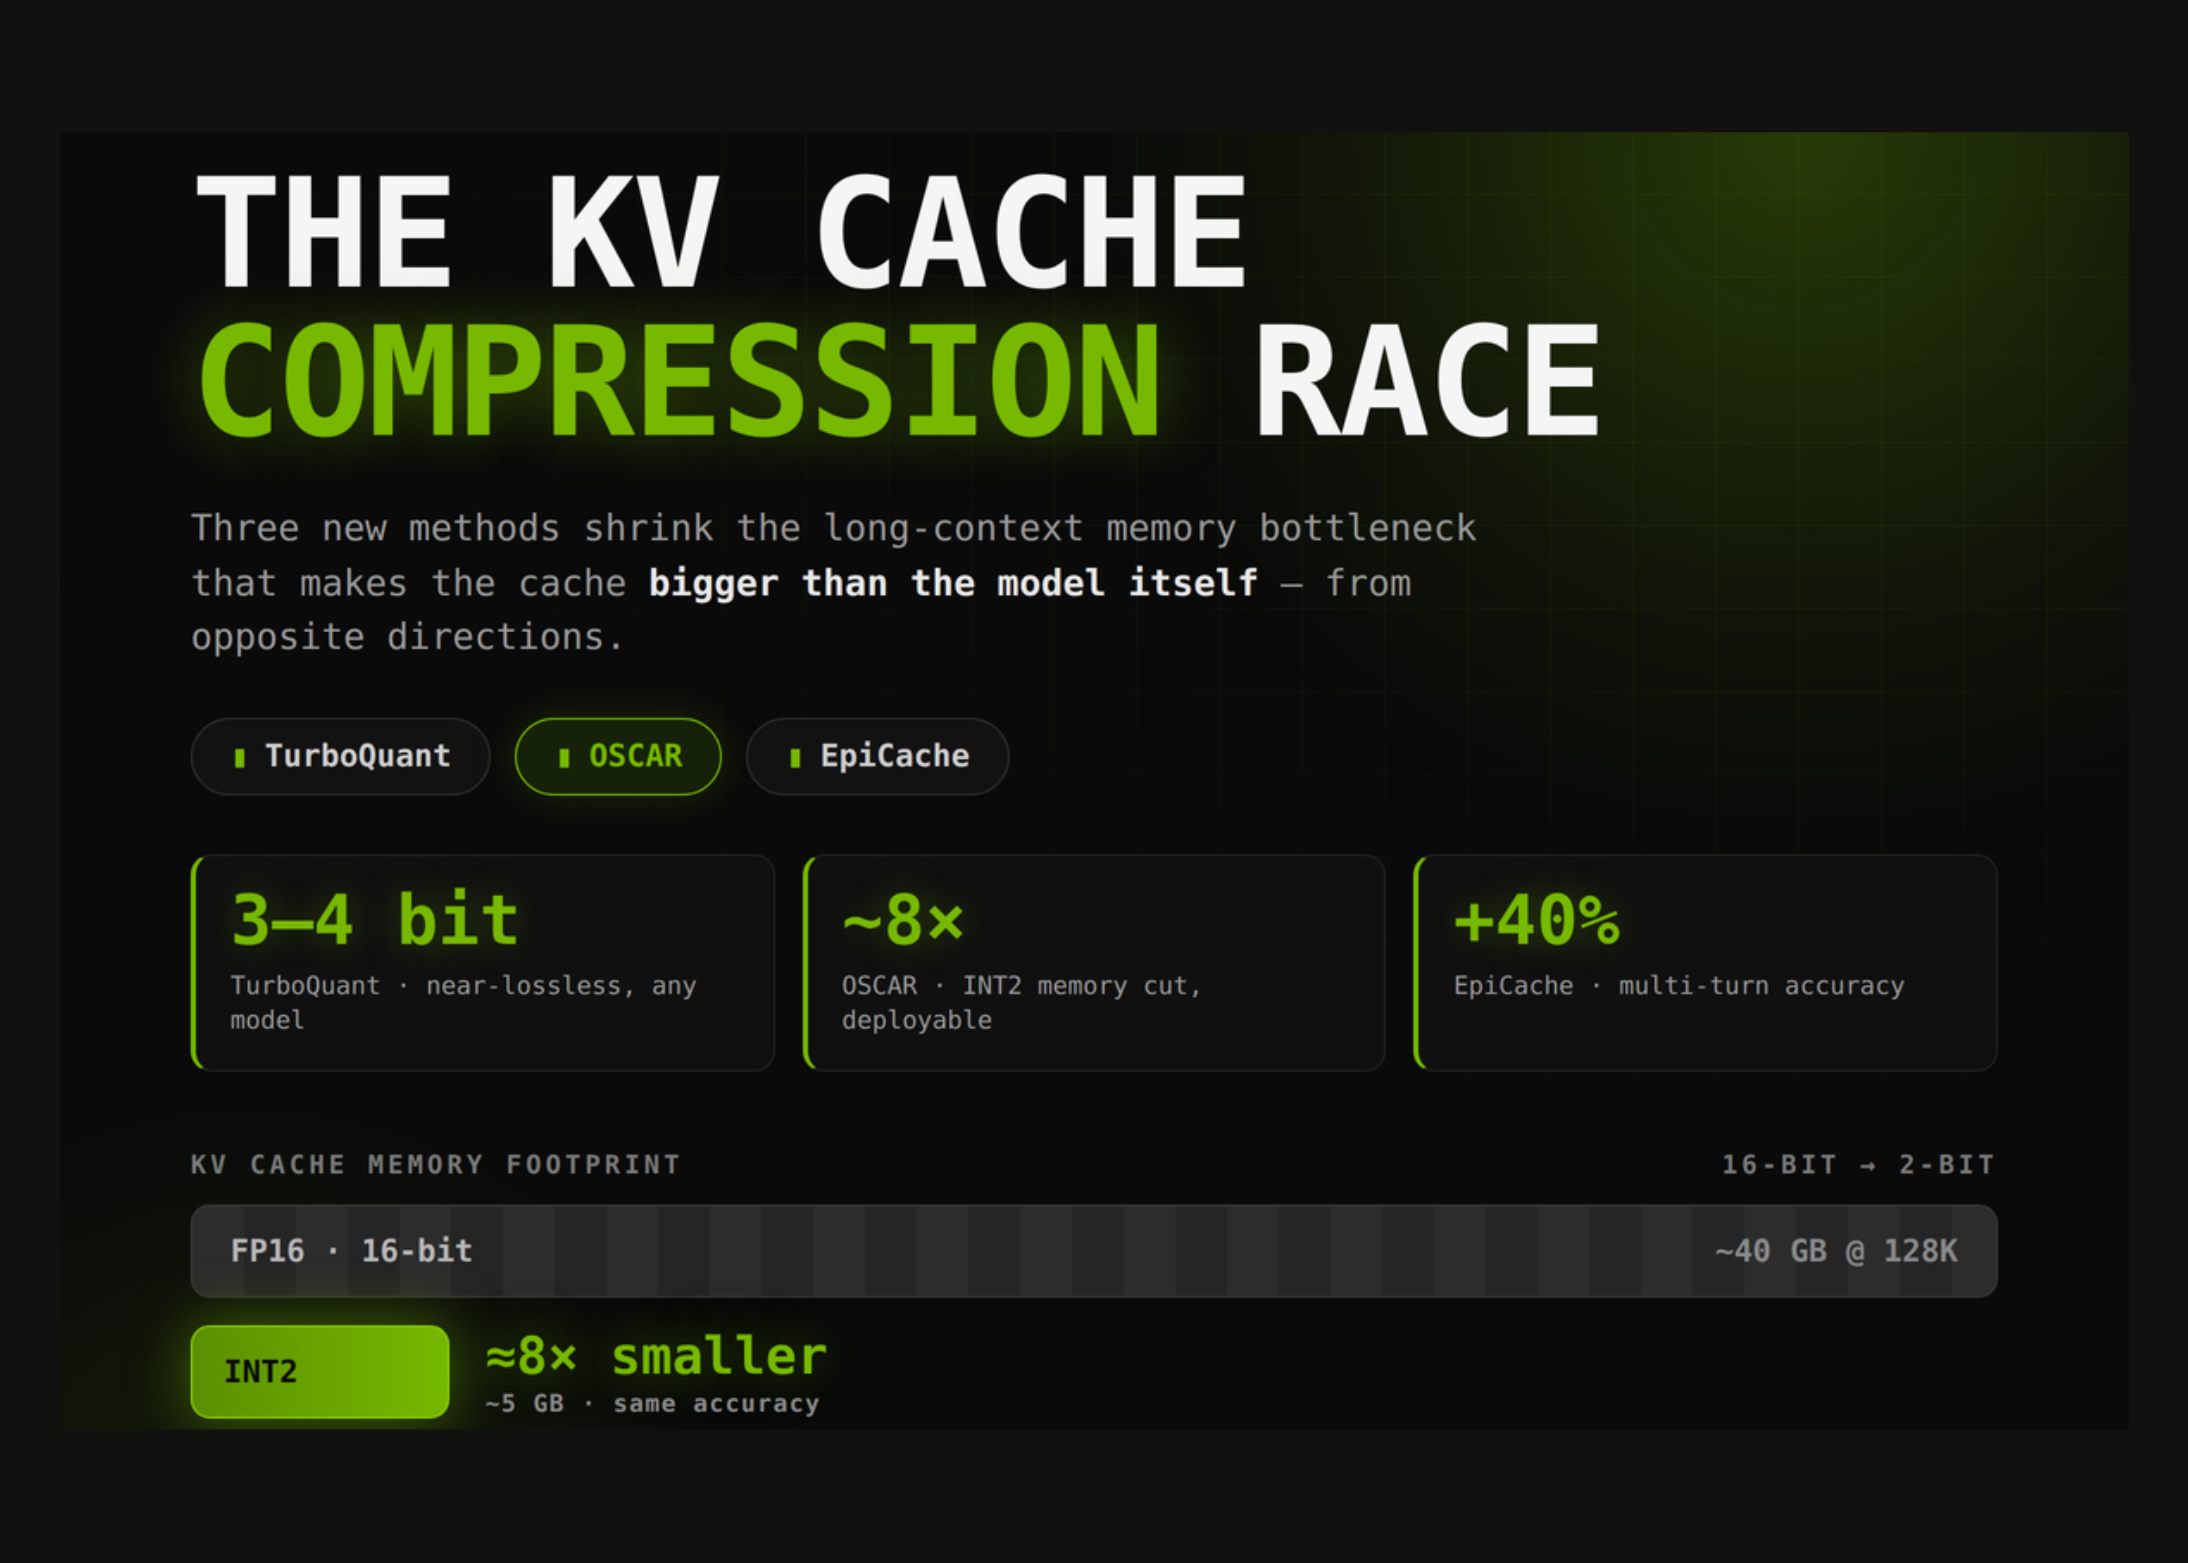
Compare TurboQuant, OSCAR, and EpiCache: three 2026 methods compressing the LLM KV cache to cut long-context memory cost

Learn how understanding LLM distillation techniques improves model training through innovative teacher-student approaches.
n this article, we will explore three major approaches used for training one LLM using another:
Make stronger and simpler models by leveraging natural order
A simple yet highly practical feature
Efficient vector quantization for machine learning optimizations (eps. vector quantized variational autoencoders), better than straight…
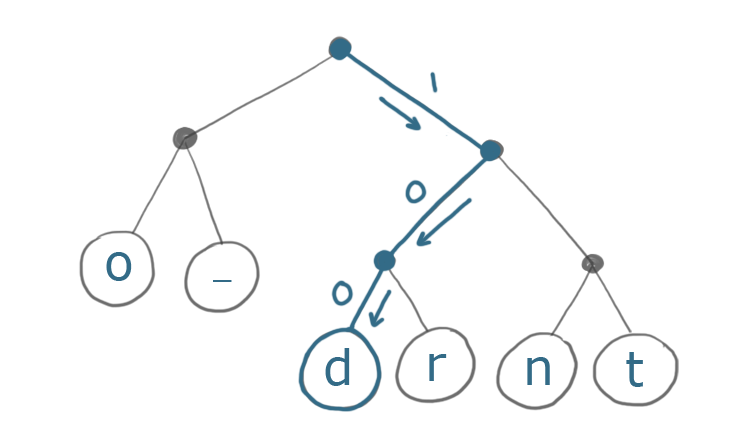
The Huffman Coding algorithm is a building block of many compression algorithms, such as DEFLATE - which is used by the PNG image format and GZIP.

This article shows a comparison of the implementations that result from using binary, Gray, and one-hot encodings to implement state machines in an FPGA. These encodings are often evaluated and applied by the synthesis and implementation tools, so it’s important to know why the…
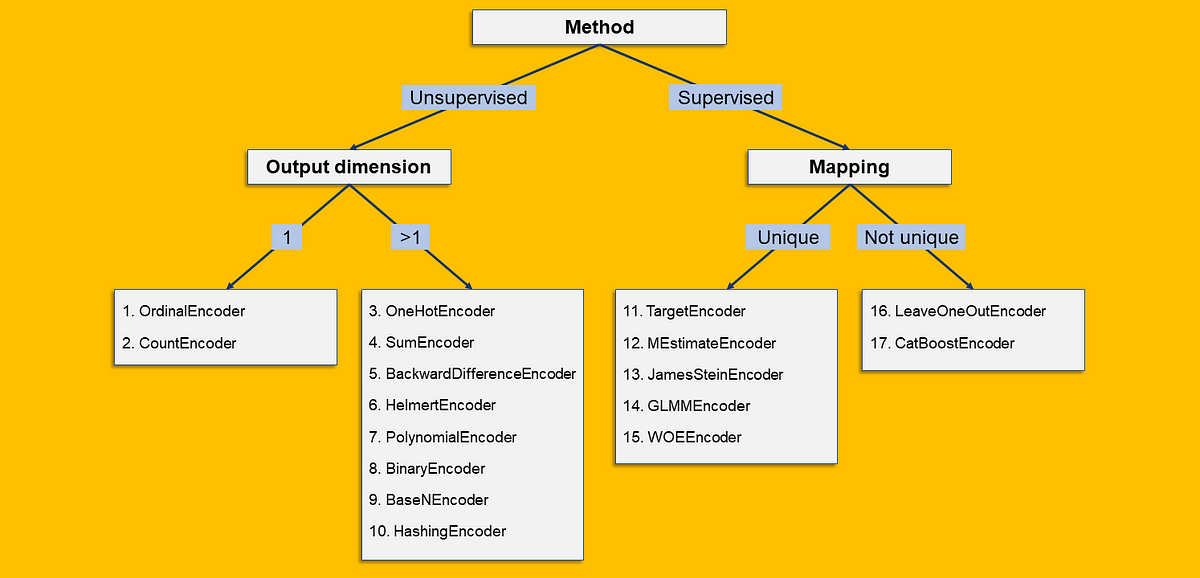
All the encodings that are worth knowing — from OrdinalEncoder to CatBoostEncoder — explained and coded from scratch in Python
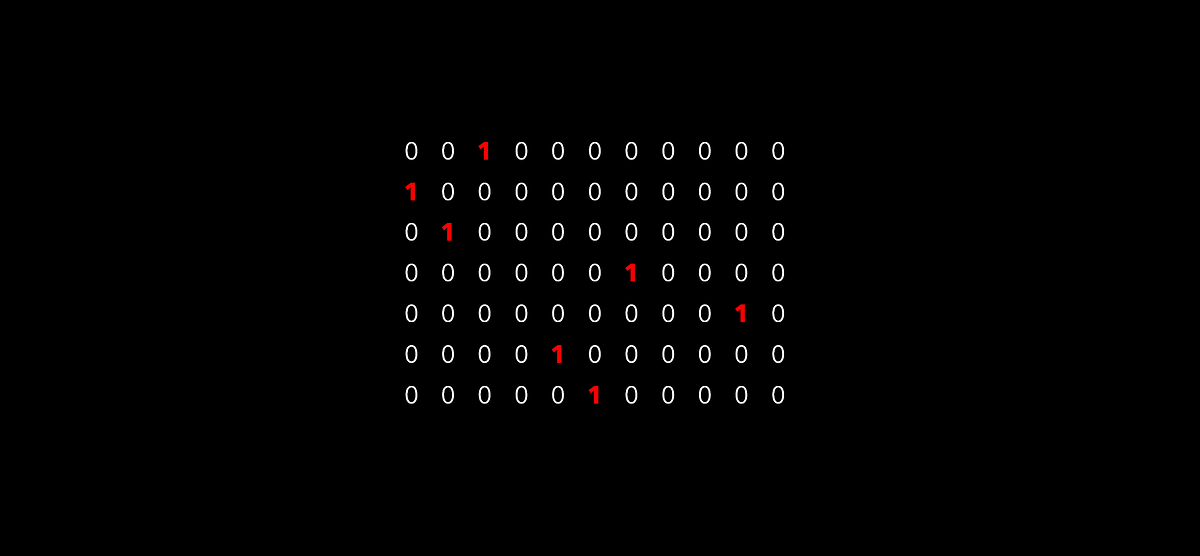
There are many better alternatives
How to reduce storage size without losing information.
Intro If you're into Cryptography For Beginners, you're in the right place. Maybe you're j...
A gentle introduction to Hamming codes, error correcting binary codes whose words are all a Hamming distance of at least 3 apart.
A Self-Contained Tutorial on RSA Algorithm Theories for Number Theory Noobs

Audiophile On lists the best audio codecs for your music if you want the best sound quality, including descriptions of FLAC, OGG, ALAC, DSD, and MQA.

Knowledge distillation is a model compression technique whereby a small network (student) is taught by a larger trained neural network (teacher). The smaller network is trained to behave like the large neural network. This enables the deployment of such models… Continue reading…