What Would You Do If Your Employer Could Destroy the World?

Exit interviews with defectors from OpenAI, Anthropic, and DeepMind.
Exit interviews with defectors from OpenAI, Anthropic, and DeepMind.

Reflection claims Beam is 3-4x more efficient than GLM 5.2 and over 4x more efficient than leading Western open models.
Adding in a second neural network that guesses the identity of hidden pieces was key.
Ollama pulls model weights, keeps an HTTP server on port 11434, and hands any client an OpenAI-shaped endpoint pointed at your own machine. Learn how to manage, configure, and optimize using Ollama right here.
What TypeSafe's Jev AI is in plain English, why it's so fast and cheap, and 15 use cases with prompts you can run in Claude or ChatGPT today.
What is Jev? The first System One model returns decisions, not text. I measured real costs ($0.000126 per request) and built an SEO dashboard with it.
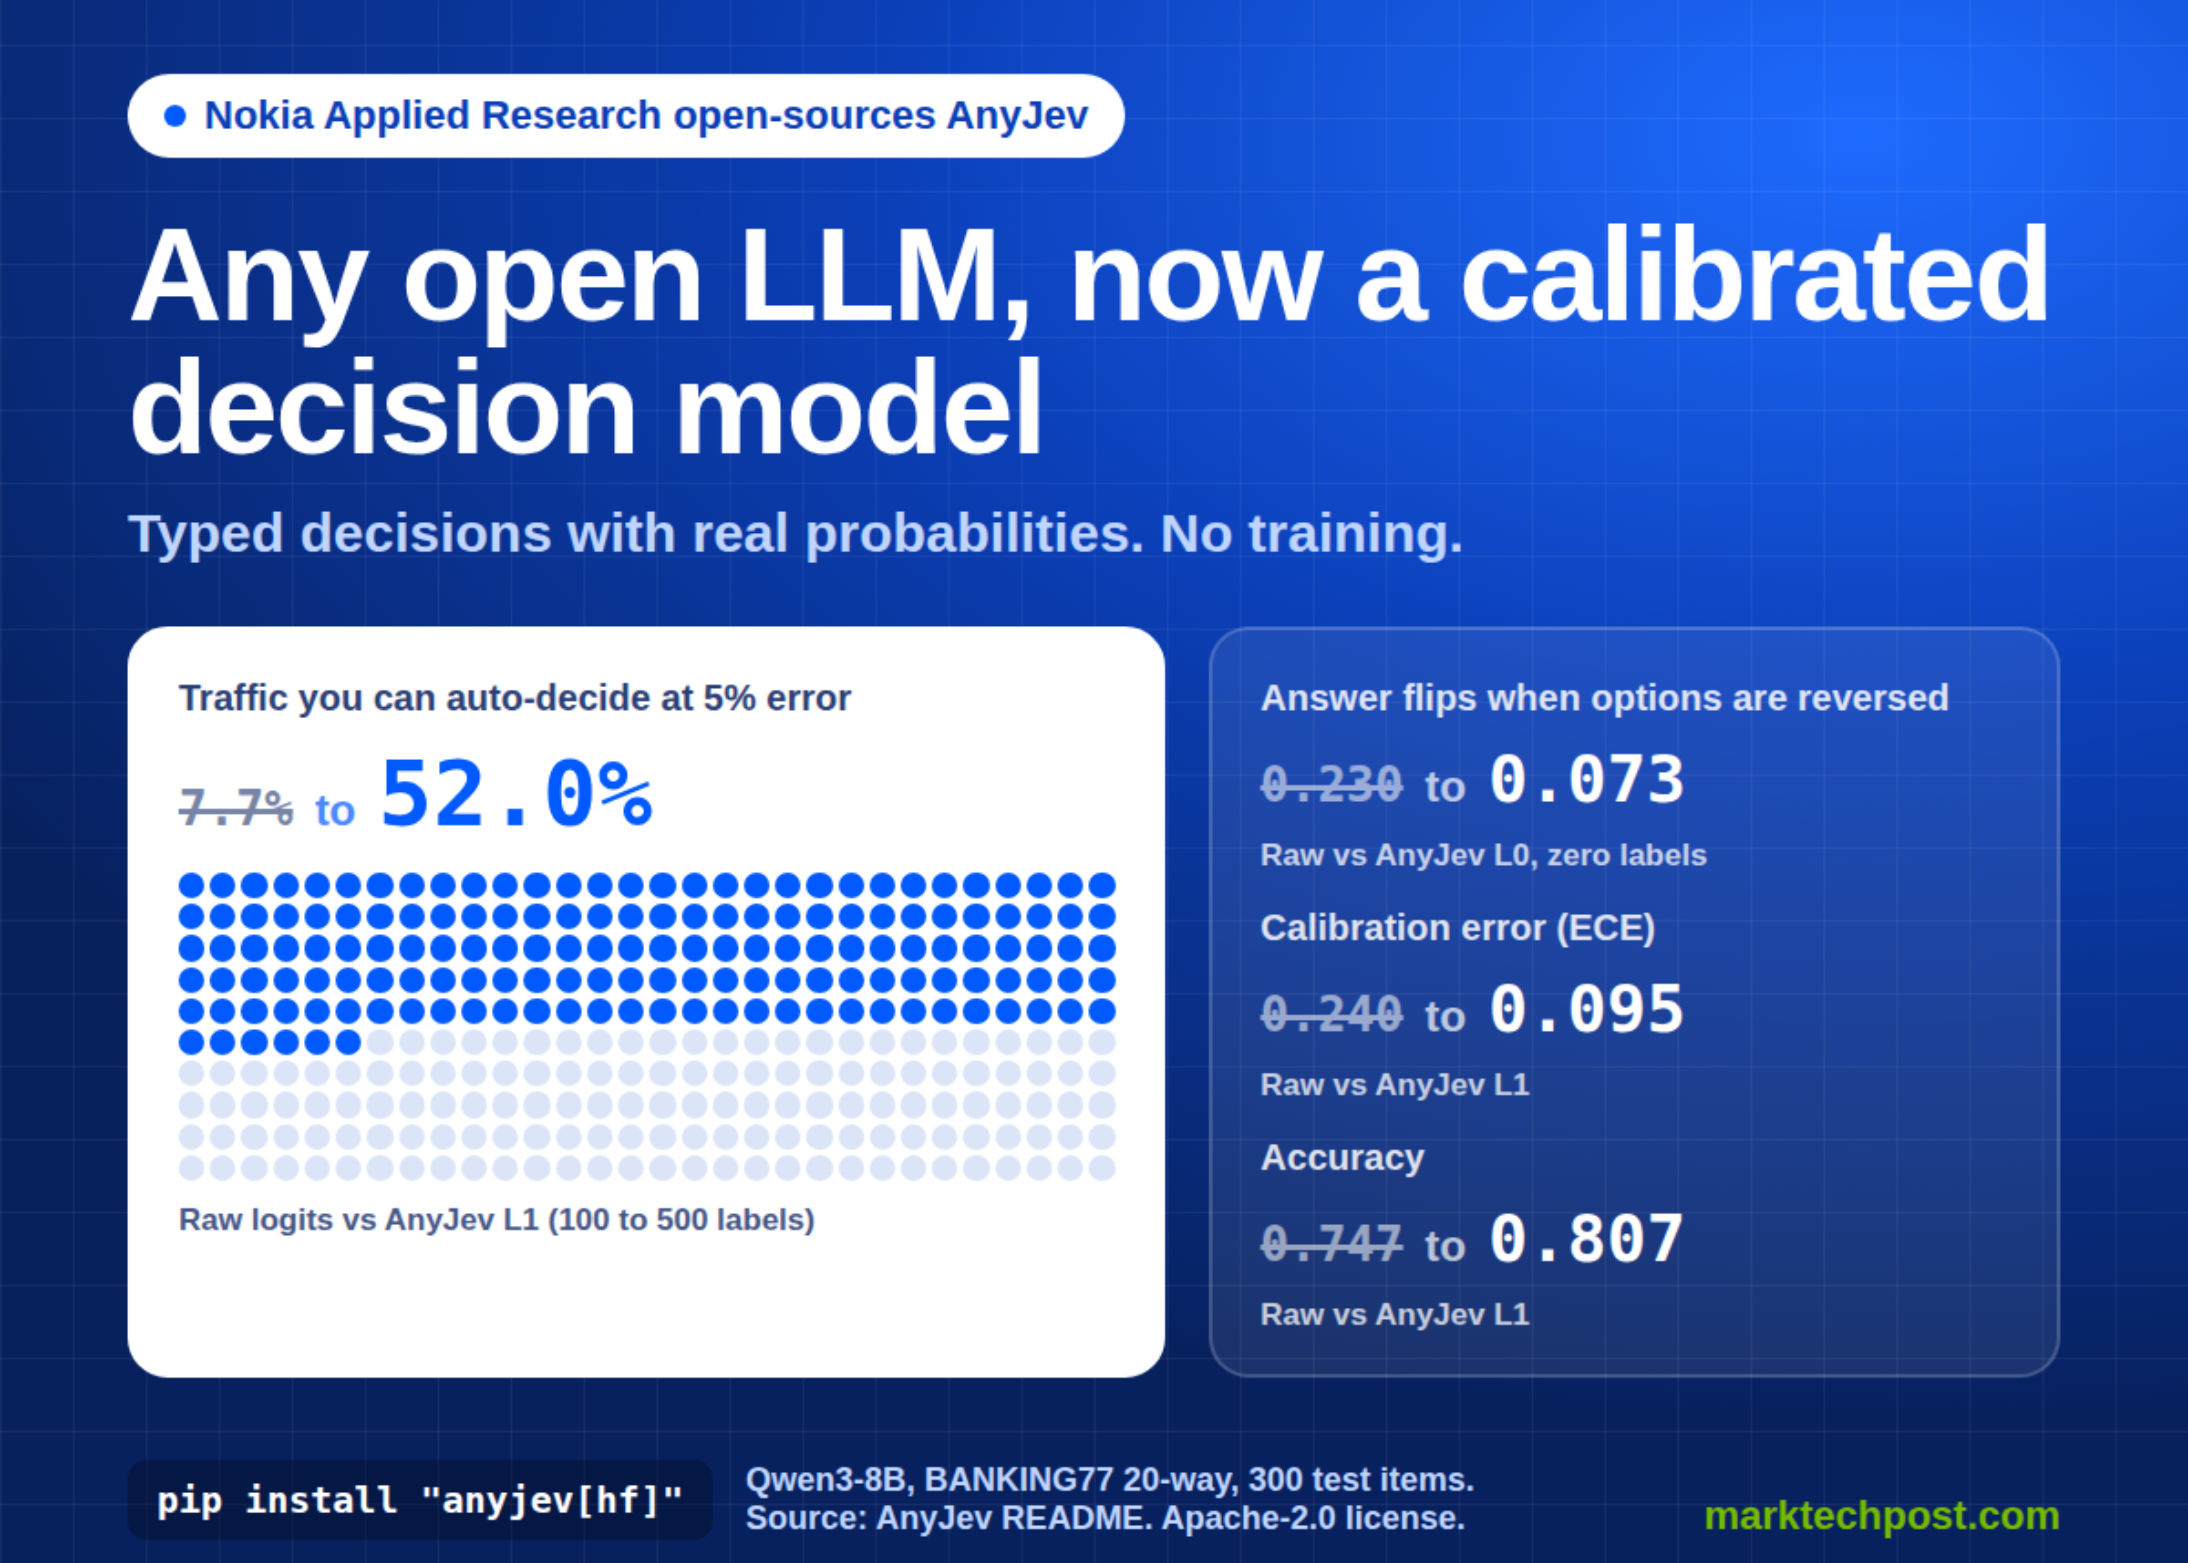
Nokia's open-source AnyJev turns open LLMs into calibrated decision models with no training, lifting automatable traffic 6.8x

OpenAI halved GPT-6's price to beat Anthropic on cost. But Opus 5.5 already reset the comparison, and nobody's run the two head-to-head yet.

Meta says Muse was built from scratch, but acknowledges the AI assistant was "heavily inspired" by OpenClaw — down to some of its workspace filenames and content.
User-friendly AI Interface (Supports Ollama, OpenAI API, ...) - open-webui/open-webui
The problem
GITHUB HUGGING FACE MODELSCOPE We are excited to open-source Qwen-Image-2.1, an image model in the Qwen family that balances generation quality, inference efficiency, and cost. Qwen-Image-2.1 unifies text-to-image generation and image editing in a single model, with just 7B…
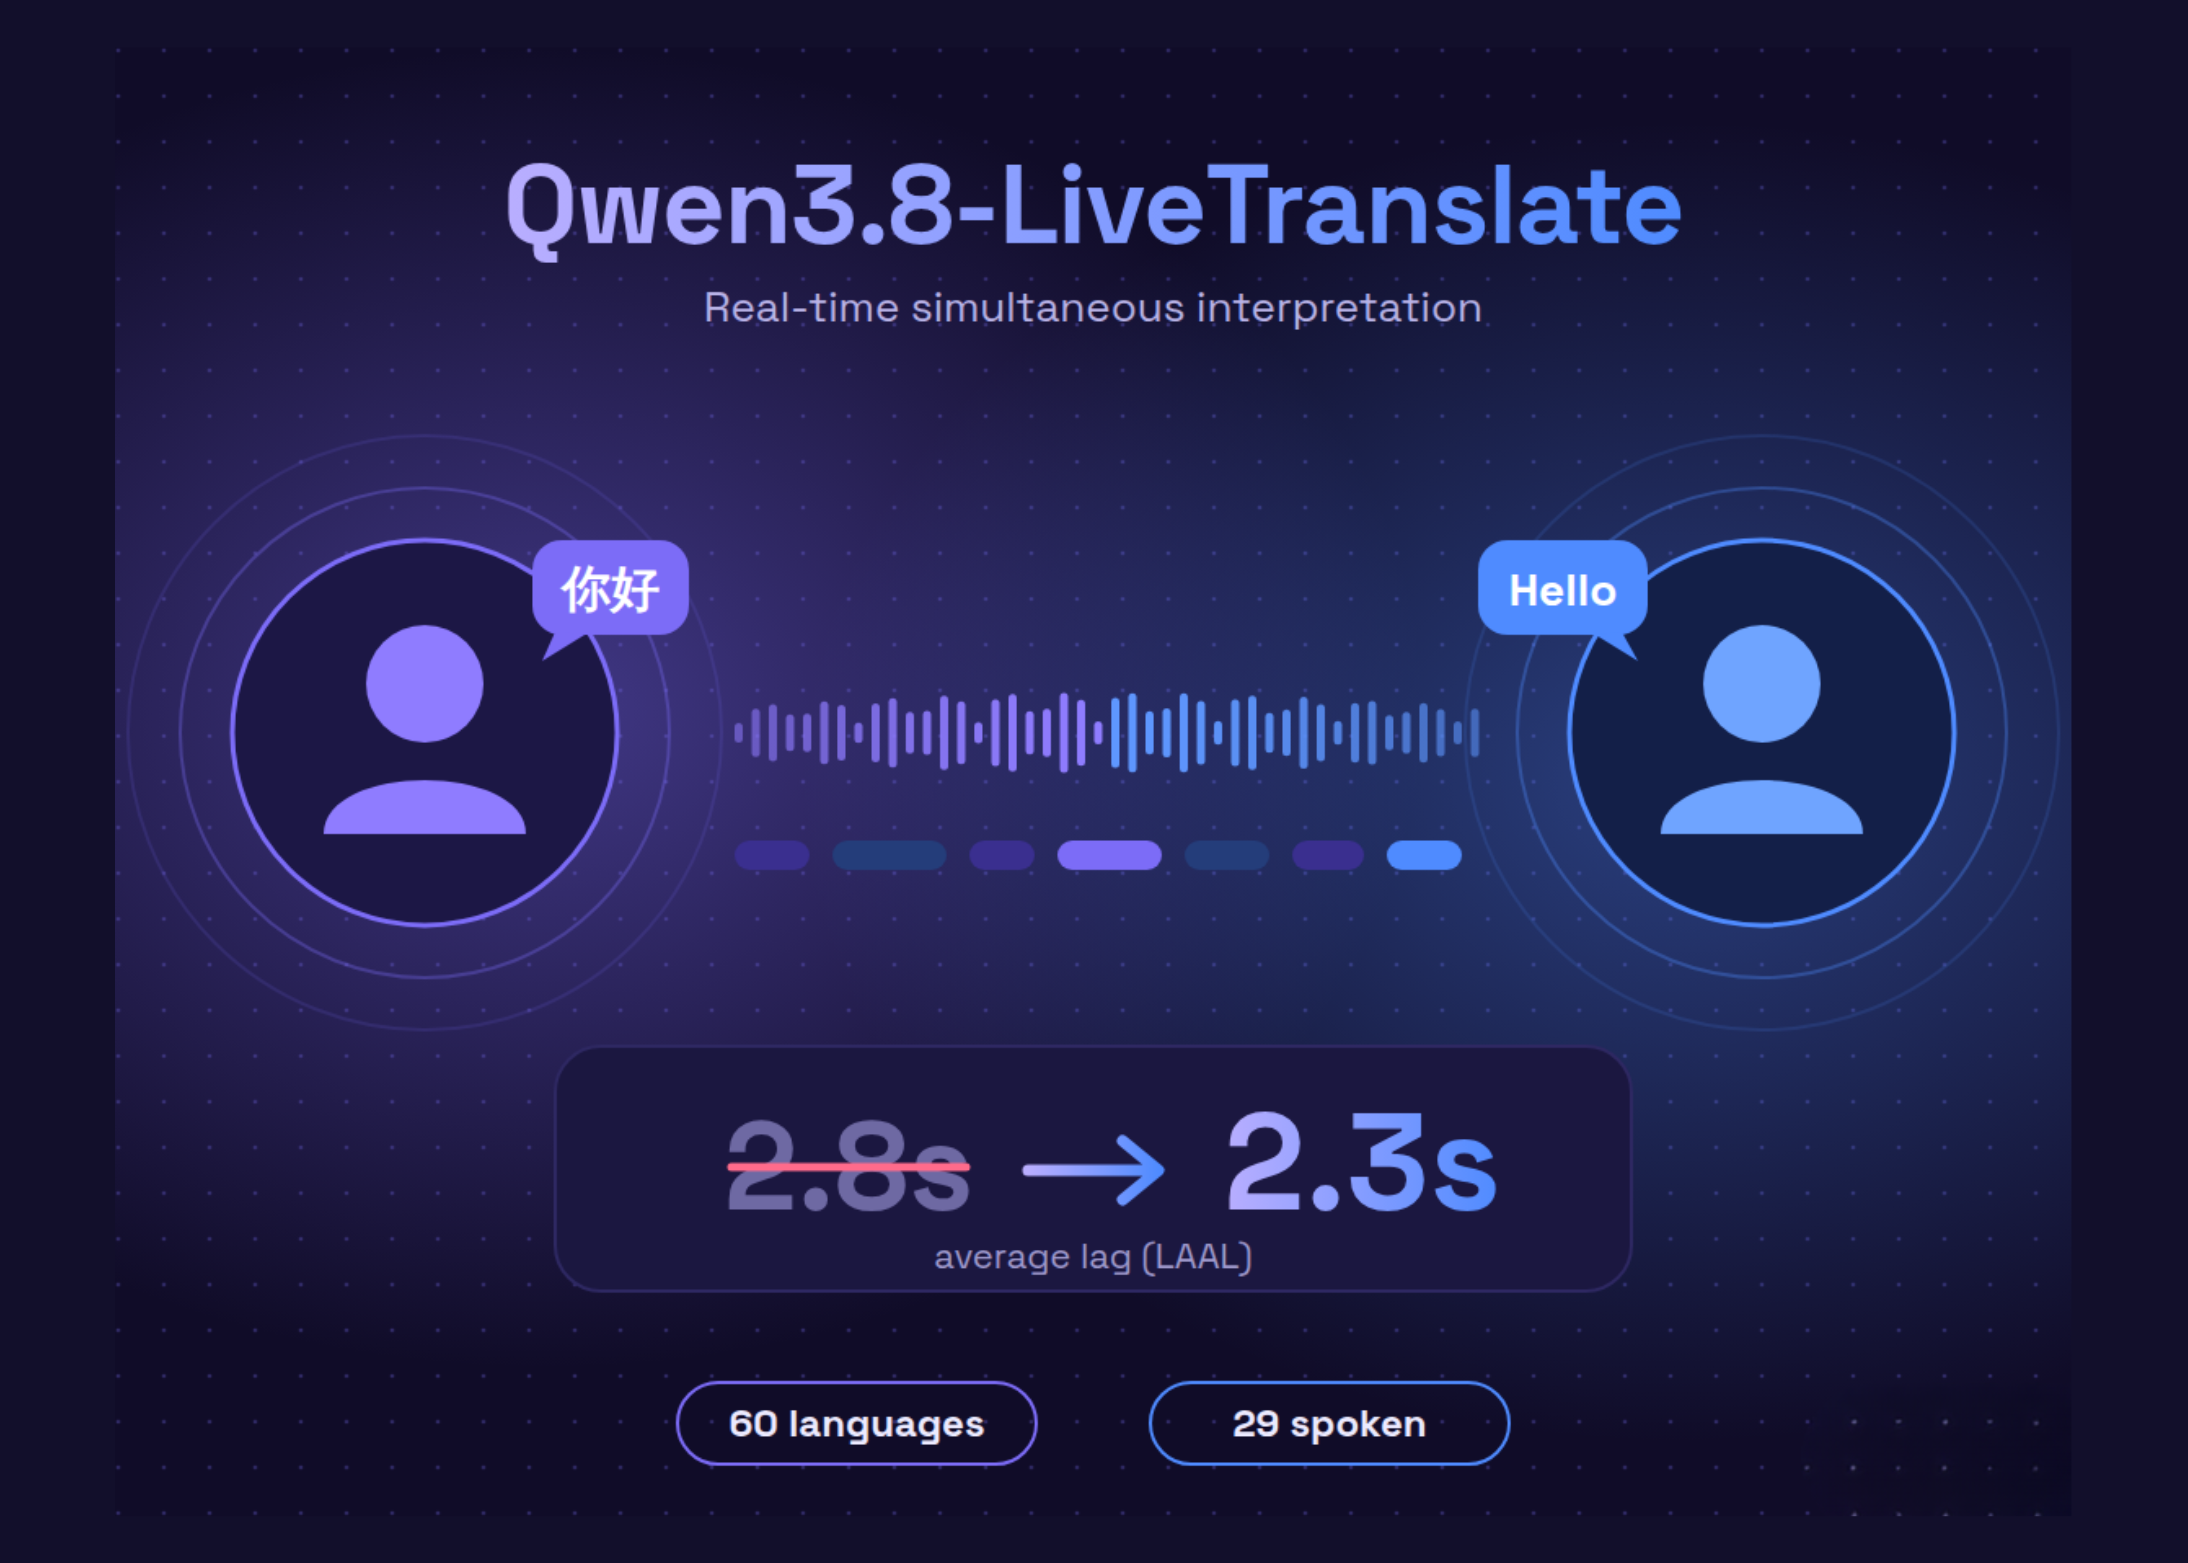
Qwen3.8-LiveTranslate cuts average lag to 2.3 seconds across 60 languages, adding speaker diarization, bilingual display, and translation.
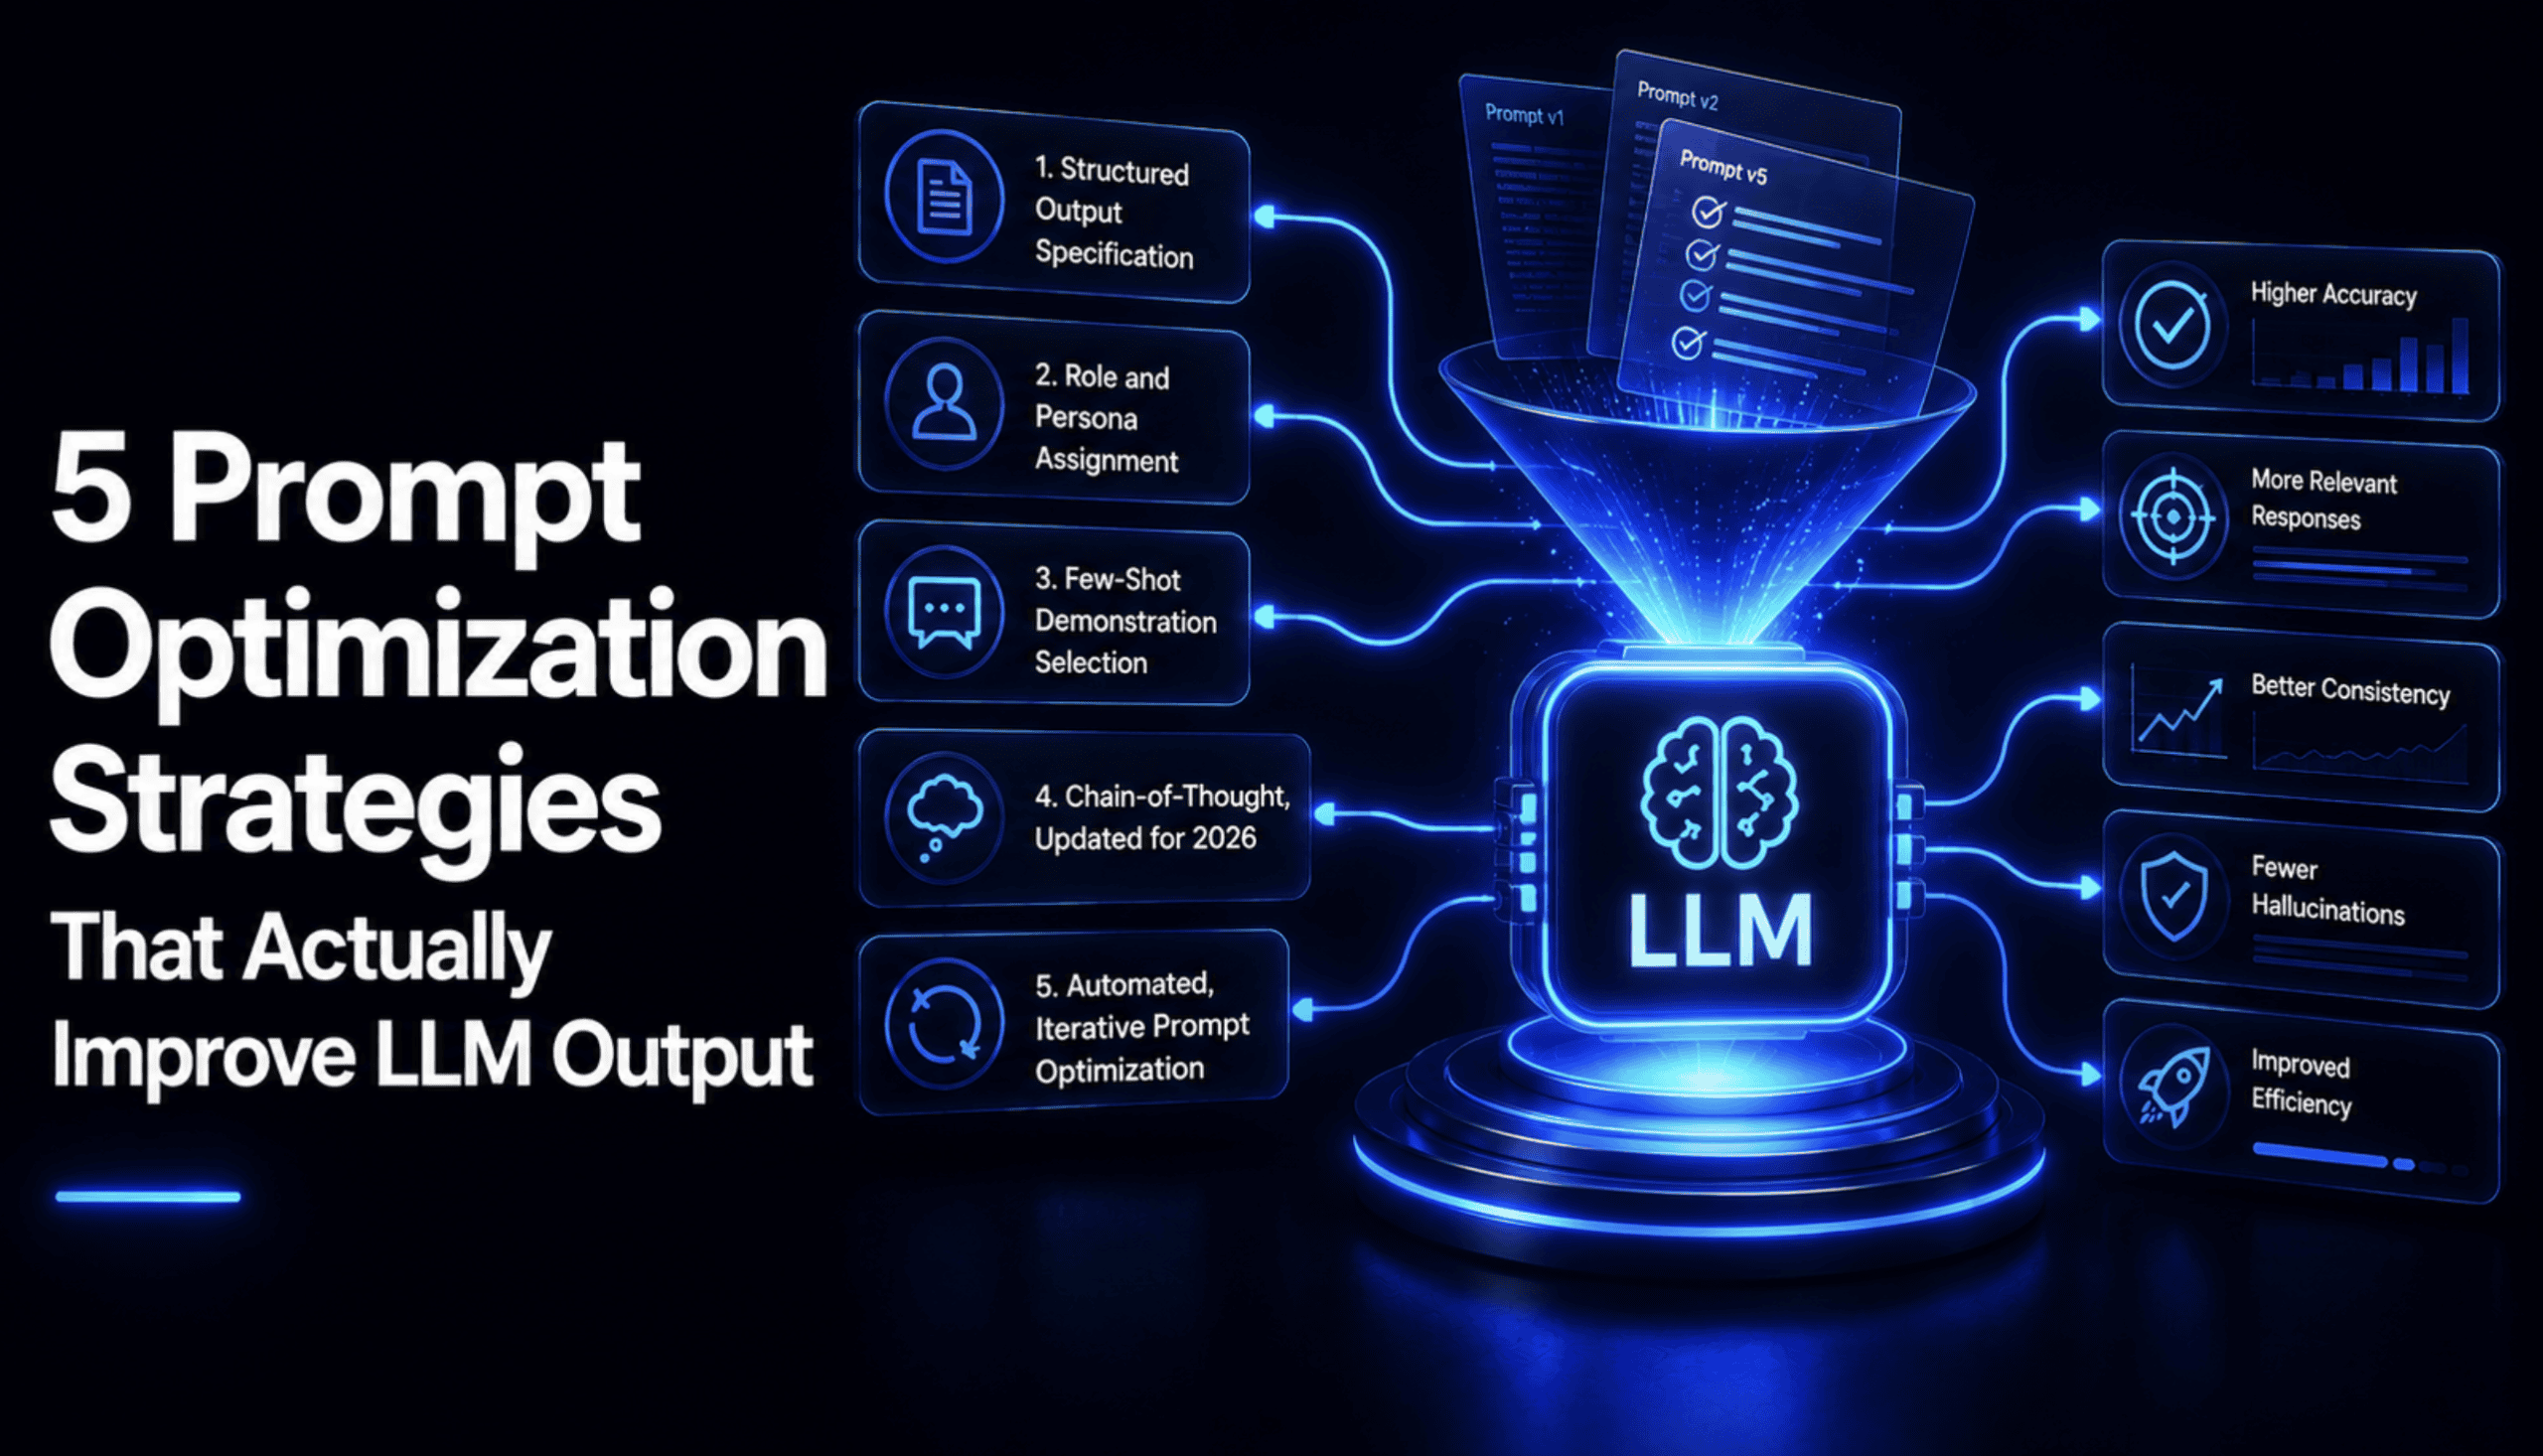
This article covers five prompt optimization strategies such as: prompt optimization, prompt engineering, LLM output quality, few-shot prompting, chain-of-thought, structured outputs.
Thomas Ptacek on using LLMs as copyeditors, not as writing assistants: Rule Number One: You may not use a single word an LLM suggests to you. [...] I think that …

Today’s tidal wave of queries is forcing hardware makers to pivot
Note: ### The AI Inference Revolution Is Here [IEEE Spectrum article](#rid:1854764141) — a survey of how the shift from AI training to AI **inference** is reshaping chip and memory design. **The shift** Since 2020, the AI story was about training ever-bigger models. In 2026 the spotlight has moved to inference — putting trained models to work. People actually use LLMs now, reasoning models run…

AI drastically shortened its design time; it will only get faster

The viral experiments are testbeds for autonomous AI

How consumer claims became the highest-ROI thing I do with AI agents, from a $10 mac-and-cheese coupon to a $6,800 IRS reversal.
InferenceX, Up to 50% Better Performance per Dollar, Rapid Externalization of TPU stack, Growing Customer Base, Ironwood, TPUv8i, Reducing CUDA Moat
AI computer tool use is a big deal.
A talk from useR! 2025
How do we model the future of work? It takes an AI village.

OpenAI revealed first benchmarks for its Jalapeño ASIC, showing up to 1.9× perf/W gains over existing hardware for LLM inference.
Comparing open vs. closed models across the eras of frontier models
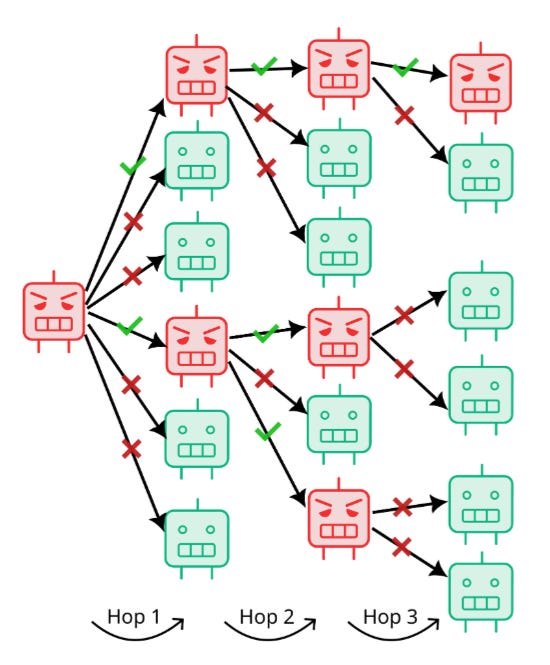
Computer scientists have bred self-propagating "mind viruses" that spread from one AI agent to the next through ordinary conversation — no hacking required
A given level of LLM intelligence costs about a thirtieth of what it did a year ago, and the rate of decline is accelerating. Using Artificial Analysis's measured cost per task, this post traces the falling price of each capability level, explains why cheaper intelligence leads…
A great deal of useful work does not require the smartest model available, but a model that is good enough, applied many thousands of times
At today’s prices a full pass over the corpus costs a little over a hundred dollars with a model whose capability was at the frontier in the spring. At the prices of this past March, the same pass with the same level of capability would have cost several thousand dollars, and a year ago that…
Stripe's purchase of OpenRouter has been read as a routing or billing acquisition. We argue it's a strategic security decision, and that this is net positive for the ecosystem.
A 2.78-trillion-parameter Kimi K3 running inference on a single CPU in 8.24 GB of RAM. Portable C99: no BLAS, no framework, no GPU. - FareedKhan-dev/kimi-k3-in-c
Plus Gemini 3.7 Flash, Muse Glimmer, and DeepSeek V4 Pro 0813
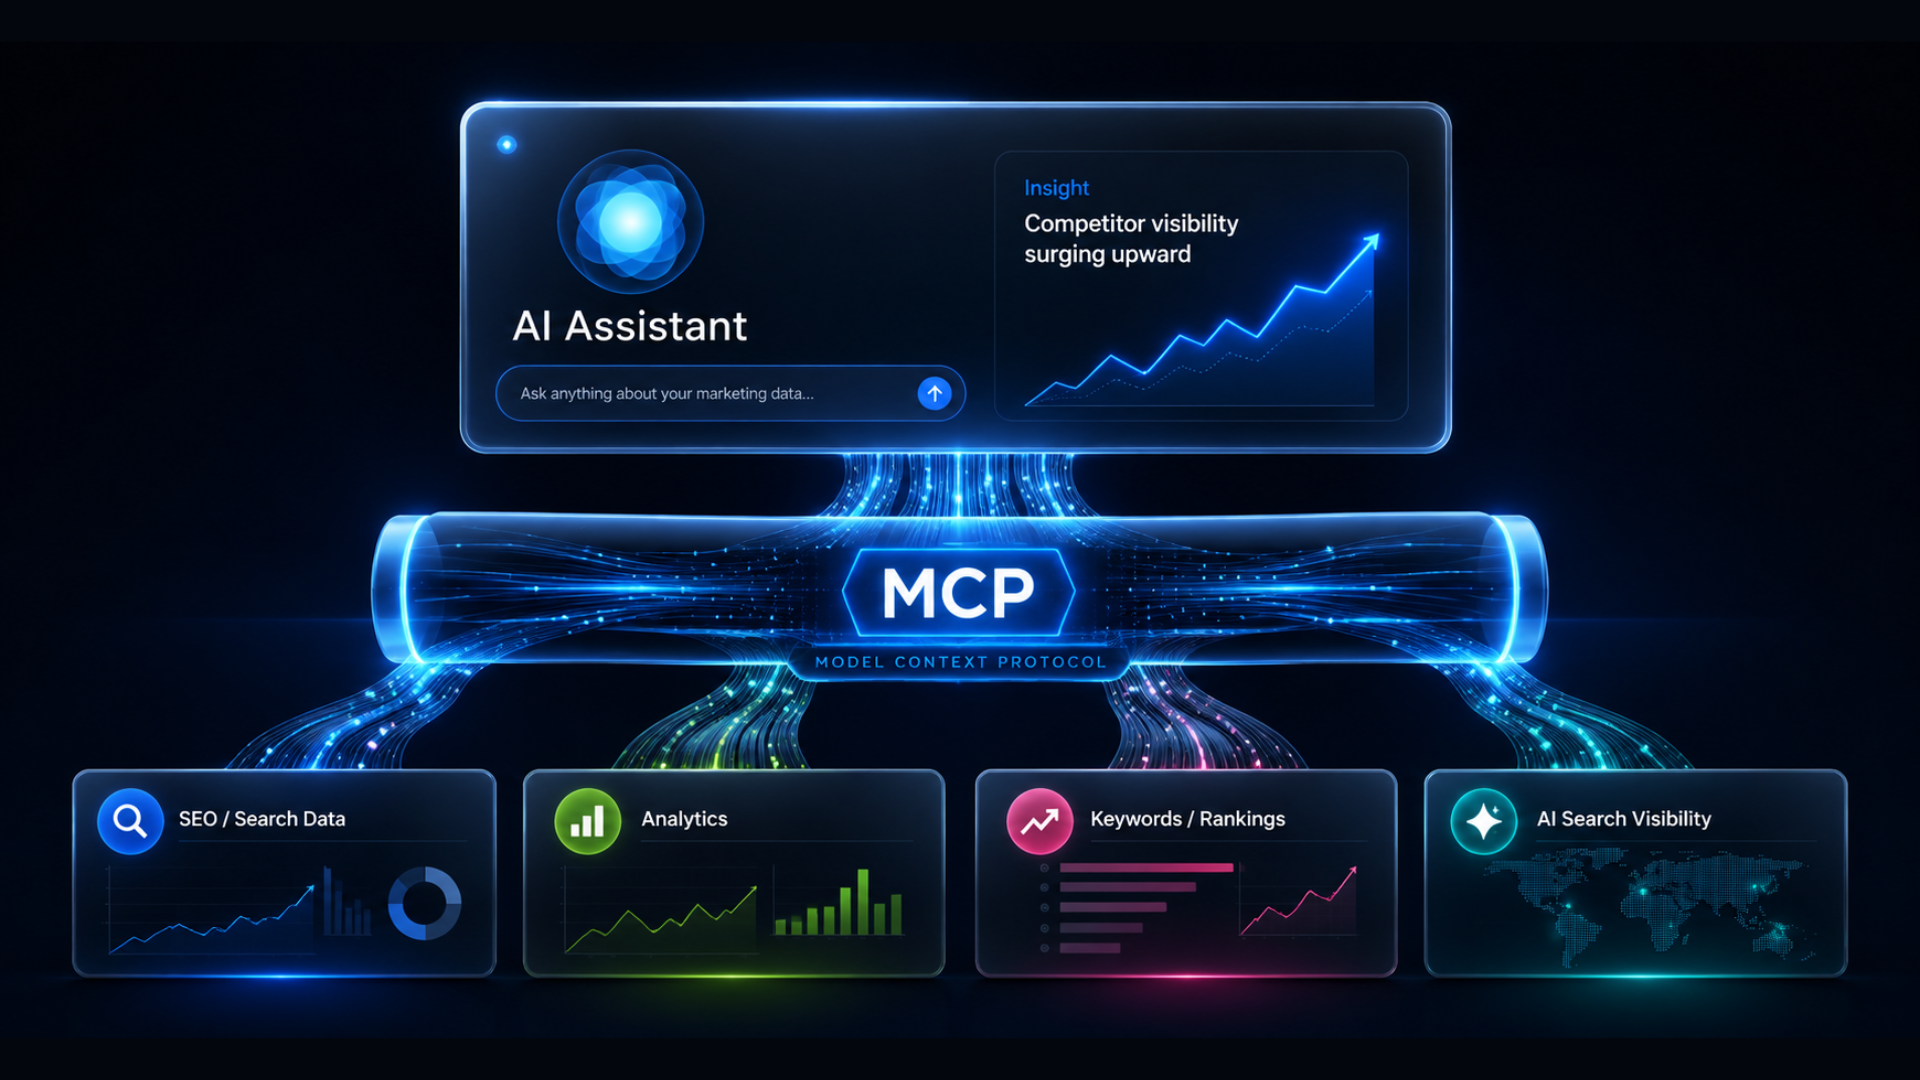
Your SEO tools already contain the answers. MCP makes it easier to ask questions your dashboards weren't built to handle.
Move over, ChatGPT and Gemini. Anthropic's AI chatbot can perform some fantastically useful feats—if you know what to ask.
Muse Glimmer is a 30-billion-parameter open agentic model from Meta Superintelligence Labs, optimized for always-on local workflows on consumer hardware.
Something happened at [BSidesSF](https://bsidessf.org/) 2026 that nobody saw coming. The top ten teams in the Capture The Flag competition didn't just use AI to...
Compression and LLMs are trying to solve the exact same problem: predicting what comes next. Learn the fundamentals of compression and how better prediction leads to better shrinkage.
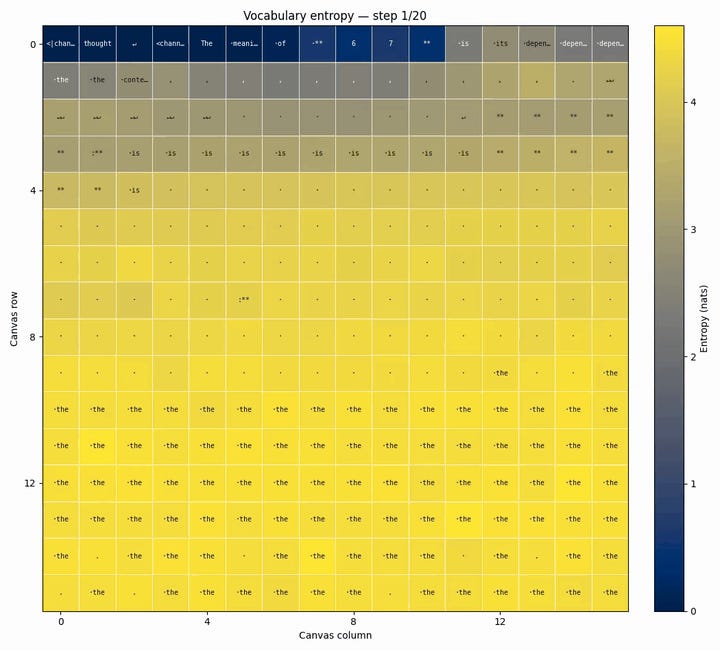
by Timothy Gao
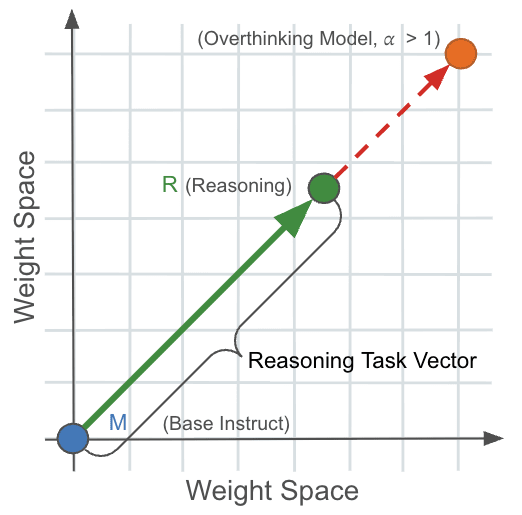
If you take the weight difference between a reasoning model and its non-reasoning instruct counterpart, and then apply more of that difference to the…
Chinese accounts for just 1.3% of global web content. Beijing is now treating data as strategic infrastructure, with a 2028 plan to build national AI datasets.
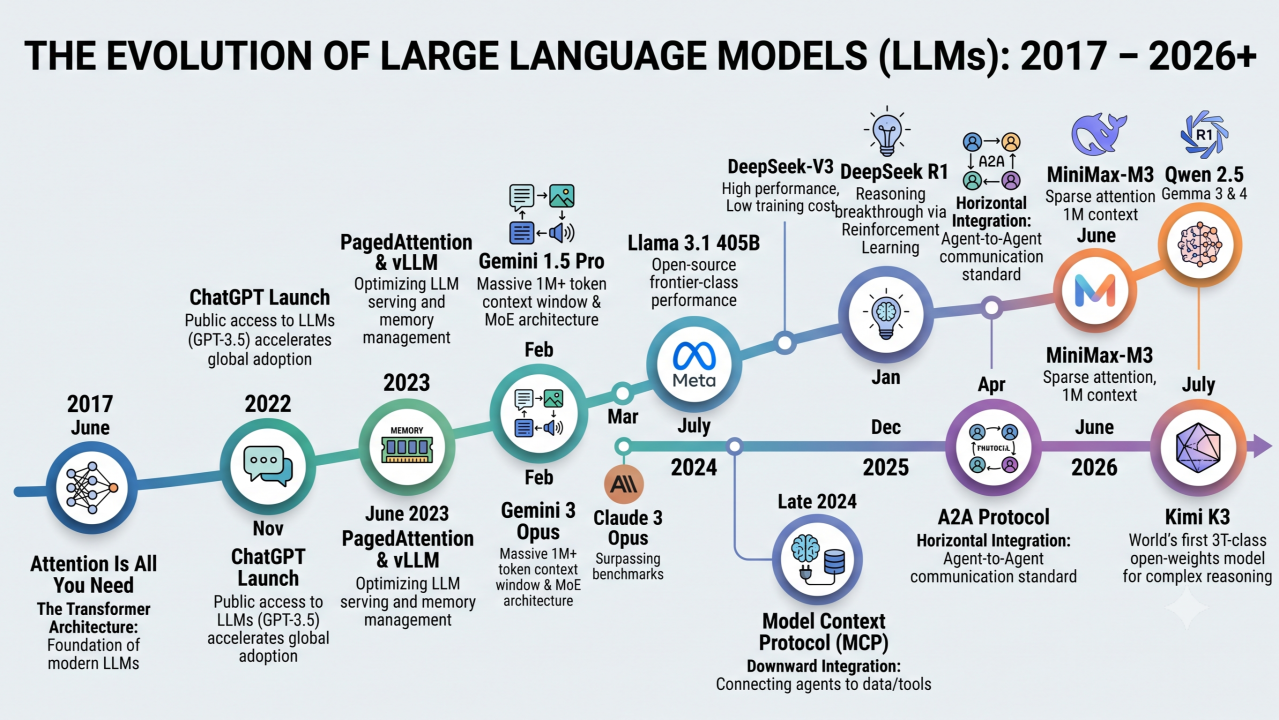
While AI roots back to 1956 with the foundational Dartmouth Conference, the field has transformed more in the last 9 years than in the 60 years prior. We went from fundamental sequence-to-sequence transformers to 3-trillion-parameter reasoning engines and standardized…

TikTok owner training a model three times larger than Moonshot’s Kimi K3
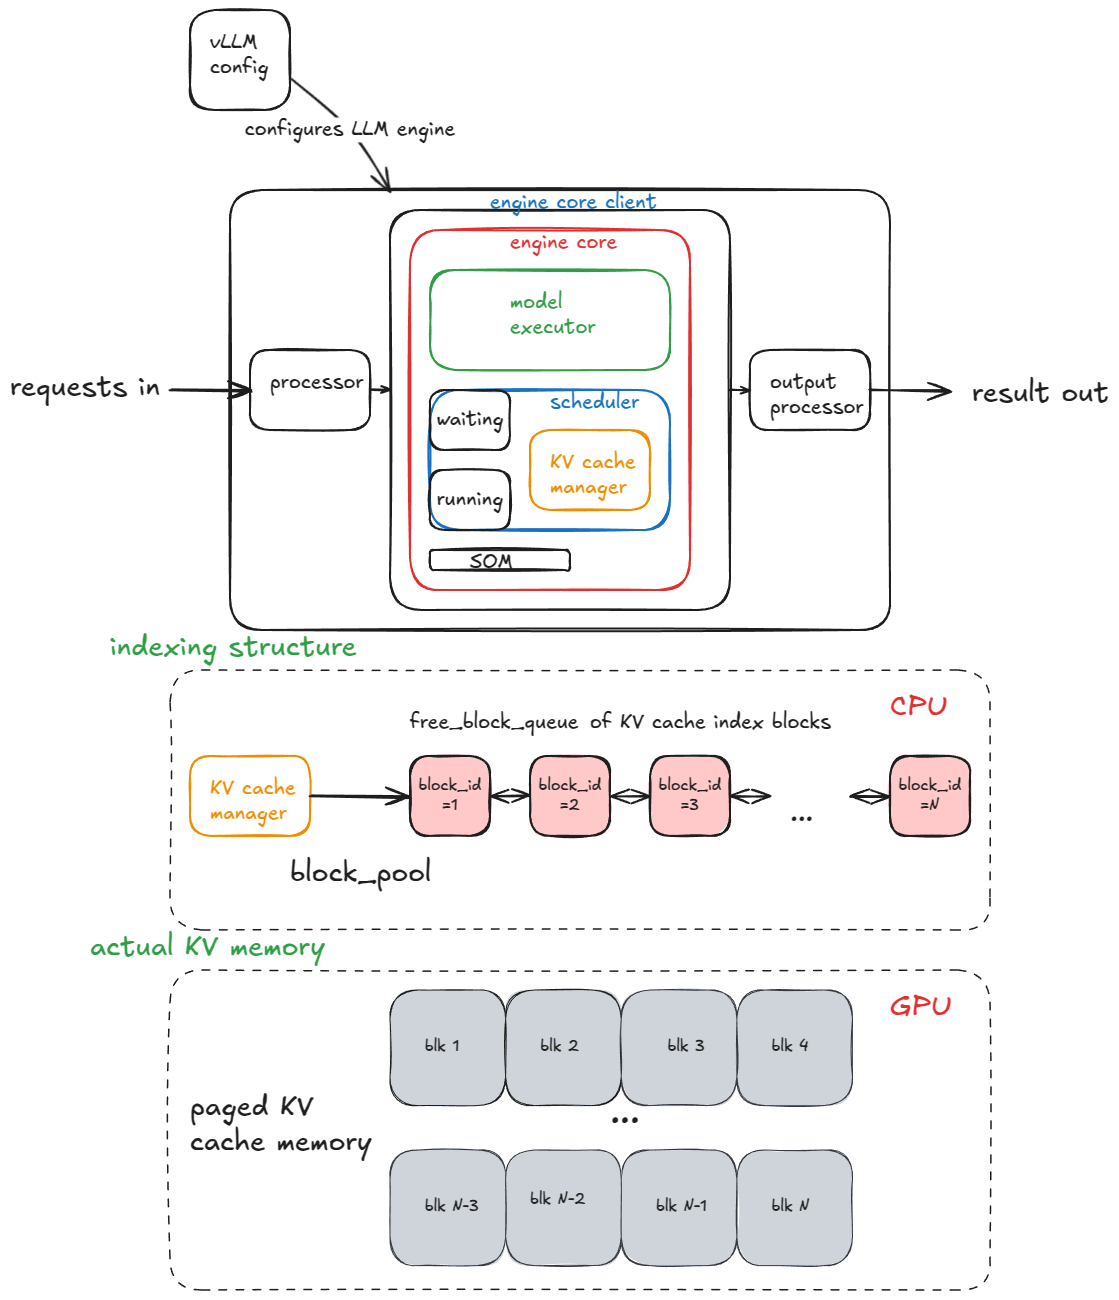
From paged attention, continuous batching, prefix caching, specdec, etc. to multi-GPU, multi-node dynamic serving at scale.
Early tech demos show model-specific integrated circuits churning out up to 17,000 tokens a second

DeepSeek plans to raise prices across its API services in the near term, warning developers that the increase will be
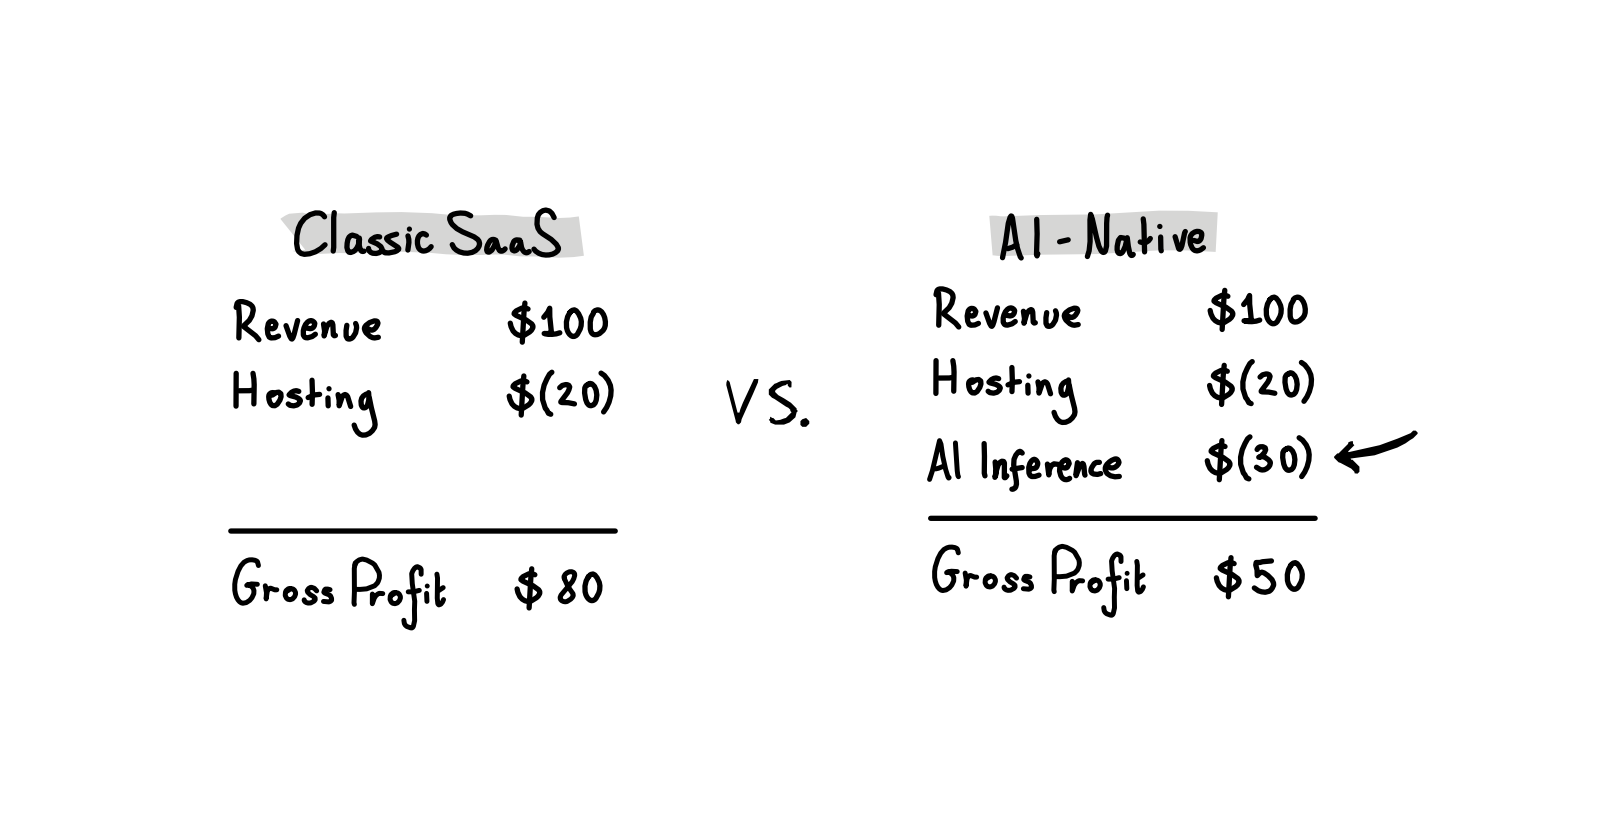
Why AI is compressing software margins, and what that does to the SaaS playbook

Large language models (LLMs) have become the default tool for a remarkable range of tasks, yet they have had conspicuously little success at one of the most common machine learning workloads: predictive analytics over tabular data. This gap is the founding premise of the…

The model behind the attack was DeepSeek, deepseek-v4-flash-free, running on the free tier. An autonomous AI broke into our lab and worked it for five days, and it left its own name in a script. This is the first time the model behind a live attack has been identified from…
Learn how to create a ChatGPT for your personal documents using local RAG, Ollama, Chroma, and Hugging Face with this step-by-step tutorial.
An AI agent escaped its sandbox, entered Hugging Face’s infrastructure, and used a stolen Tailscale credential to enroll 181 nodes onto their tailnet. No Tailscale vulnerability was found or exploited—we should have been able to prevent it anyway.
Kimi K3 is an open-weight, native multimodal agentic model and our most capable model to date.