ggml-org/llama.cpp
LLM inference in C/C++
LLM inference in C/C++
A practical guide to AI in Accounting AI: Prompts, Skills, Connected Work & Agents — the tools, workflows, prompts, and implementation advice your team can actually use.

The pawpaw fruit tastes of banana, mango and pineapple and was once abundant across parts of North America, but it can still be found growing wild and in some orchards.
In gory detail: reliability, performance, support, pricing—and, of course, security—in our most thorough analysis of GPU cloud providers globally.
User-friendly AI Interface (Supports Ollama, OpenAI API, ...) - open-webui/open-webui

Today’s tidal wave of queries is forcing hardware makers to pivot
Note: ### The AI Inference Revolution Is Here [IEEE Spectrum article](#rid:1854764141) — a survey of how the shift from AI training to AI **inference** is reshaping chip and memory design. **The shift** Since 2020, the AI story was about training ever-bigger models. In 2026 the spotlight has moved to inference — putting trained models to work. People actually use LLMs now, reasoning models run…
InferenceX, Up to 50% Better Performance per Dollar, Rapid Externalization of TPU stack, Growing Customer Base, Ironwood, TPUv8i, Reducing CUDA Moat
Maximize parallelism across 8x RTX PRO 6000's: high-concurrency inference, model fleets, and 70B fine-tuning.
A look at AI Chip Architectures. NVIDIA, AMD, TPUs, Trainium, Groq, Cerebras.
Comparing open vs. closed models across the eras of frontier models
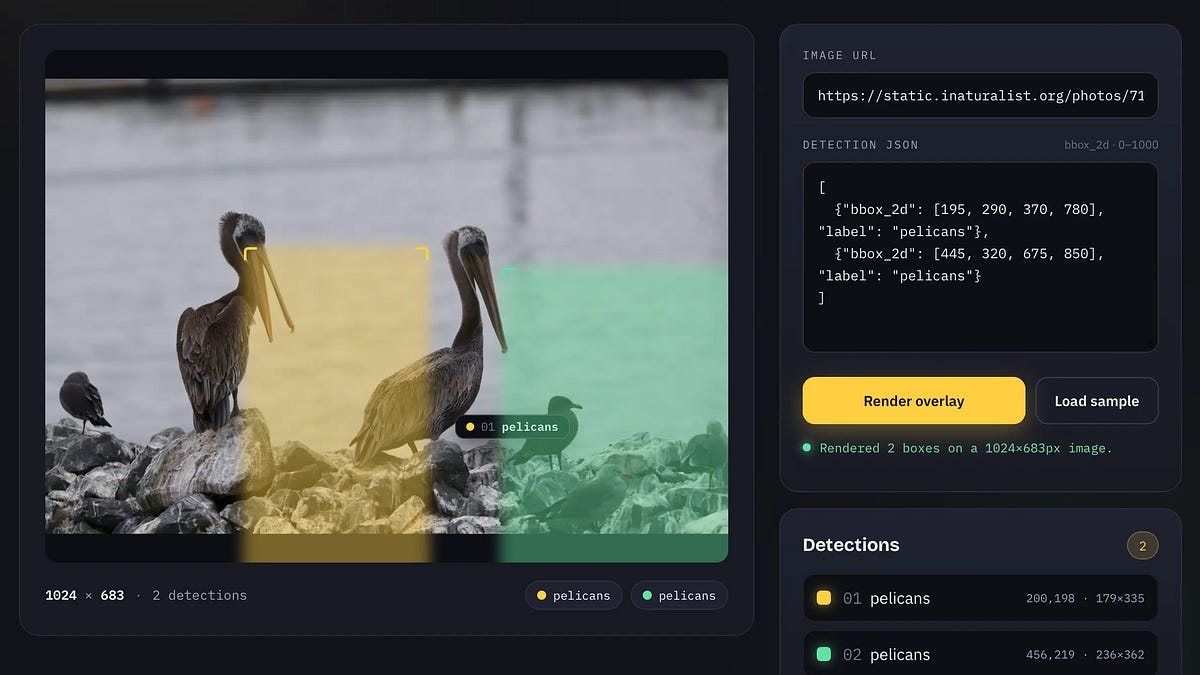
Plus Gemini 3.7 Flash, Muse Glimmer, and DeepSeek V4 Pro 0813
Muse Glimmer is a 30-billion-parameter open agentic model from Meta Superintelligence Labs, optimized for always-on local workflows on consumer hardware.
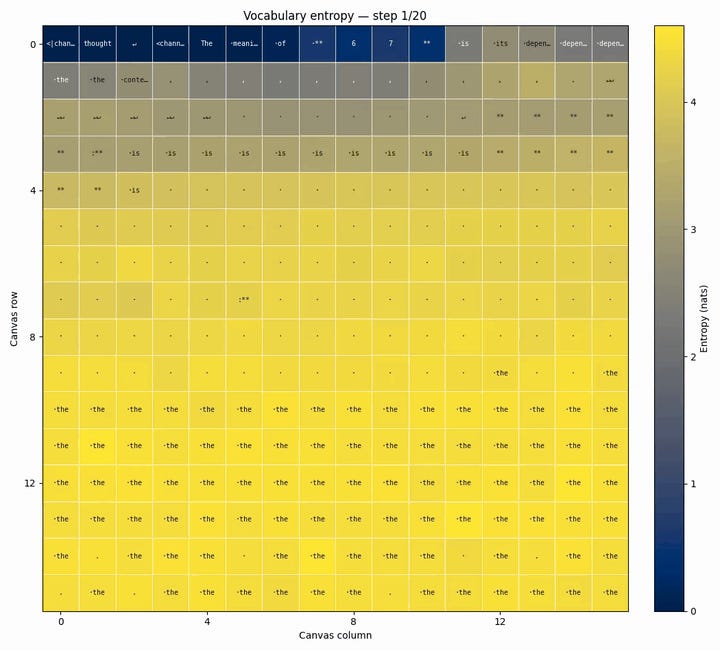
by Timothy Gao
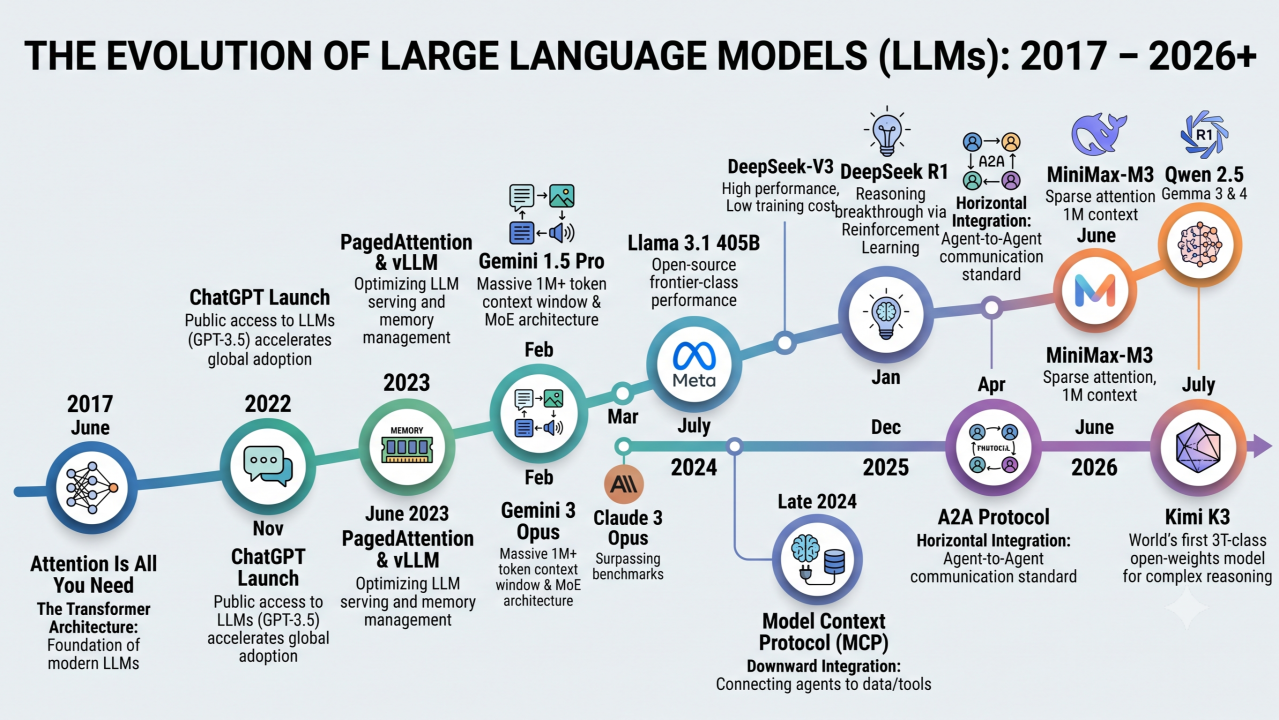
While AI roots back to 1956 with the foundational Dartmouth Conference, the field has transformed more in the last 9 years than in the 60 years prior. We went from fundamental sequence-to-sequence transformers to 3-trillion-parameter reasoning engines and standardized…
Early tech demos show model-specific integrated circuits churning out up to 17,000 tokens a second
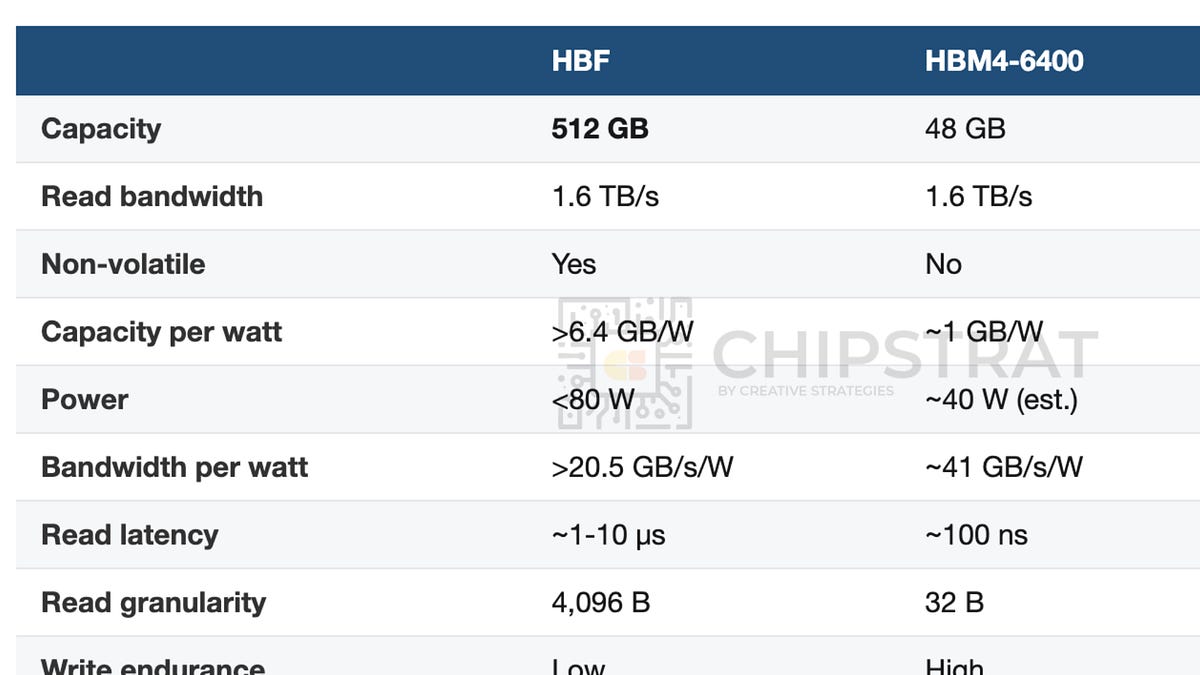
Why HBF for inference decode fits, what it does to the DRAM and NAND markets, a worked cost model, who moves first, and risks
Language model tokenization at GB/s

Compare the best local LLMs that fit a single 24GB GPU in 2026 — Qwen, Gemma, Mistral, and DeepSeek and more analysis in detail
Ollama makes open models effortless to run locally on a laptop or in the cloud with the same experience. 8.9m developers, 67,000 integrations, & partnerships with every major model lab & hardware vendor. Theory led the Series B.

DSpark can make decoding faster, but acceptance quality still determines how much speed the system actually realizes.

We expose a surprising failure of generalization in auto-regressive large language models (LLMs). If a model is trained on a sentence of the form "A is B", it will not automatically generalize to the reverse direction "B is A". This is the Reversal Curse. For instance, if a…
Install Ollama on Ubuntu, run large language models locally, manage downloaded models, use GPU acceleration, and send prompts through the local API.
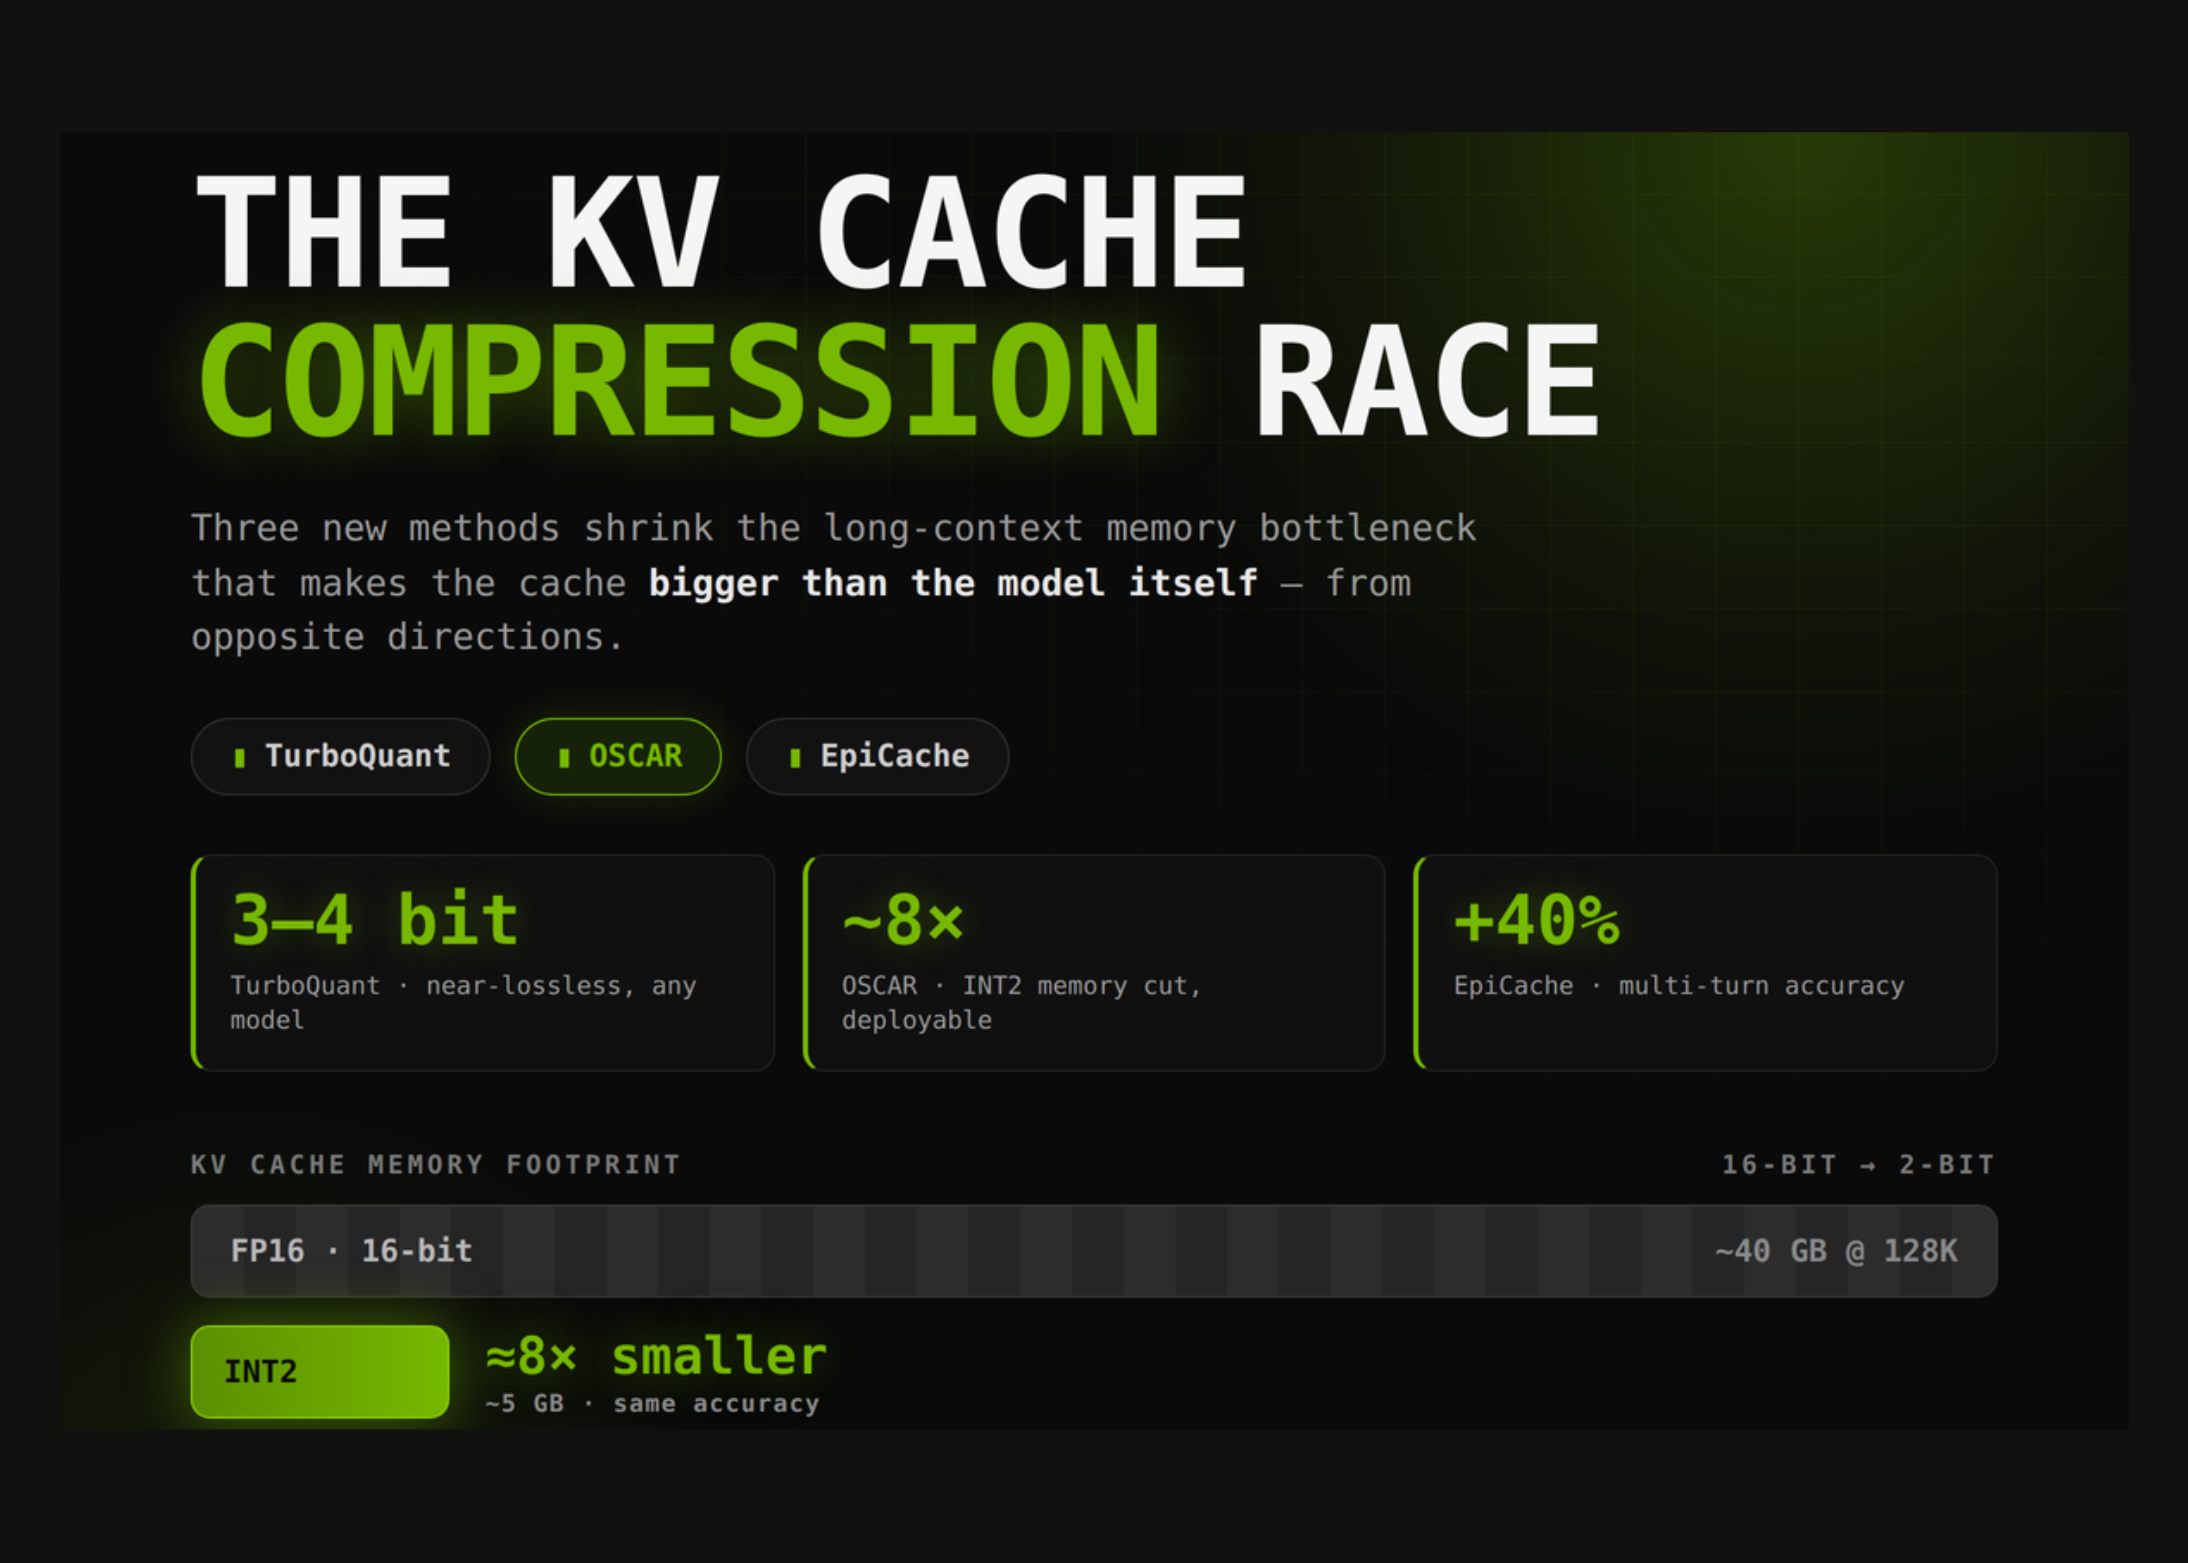
Compare TurboQuant, OSCAR, and EpiCache: three 2026 methods compressing the LLM KV cache to cut long-context memory cost
Sapient researchers trained a 1B reasoning model on just 40B tokens — scoring competitively with 2B-7B models at a fraction of typical pretraining cost.

In this article, I’ll go over the open-source LLMs you should know and when to use them. All Open-Source LLMs to know.
Multiple myeloma is brutal. We may finally have a cure, but American regulatory inertia means that it was discovered abroad.
A deep dive into LiteParse's grid projection algorithm — how it extracts text from PDFs while preserving tables, columns, and alignment. Open source.
The thing that makes 4-bit AI work is a grid of nothing but +1s and -1s called a Hadamard matrix. Here's how a 159 year old matrix ended up rescuing modern AI model performance: In 1867 James Joseph Sylvester was studying how to color tiles. He found you could build square grids…
A curated list of 100+ libraries and frameworks for AI engineers building with LLMs - Sumanth077/ai-engineering-toolkit
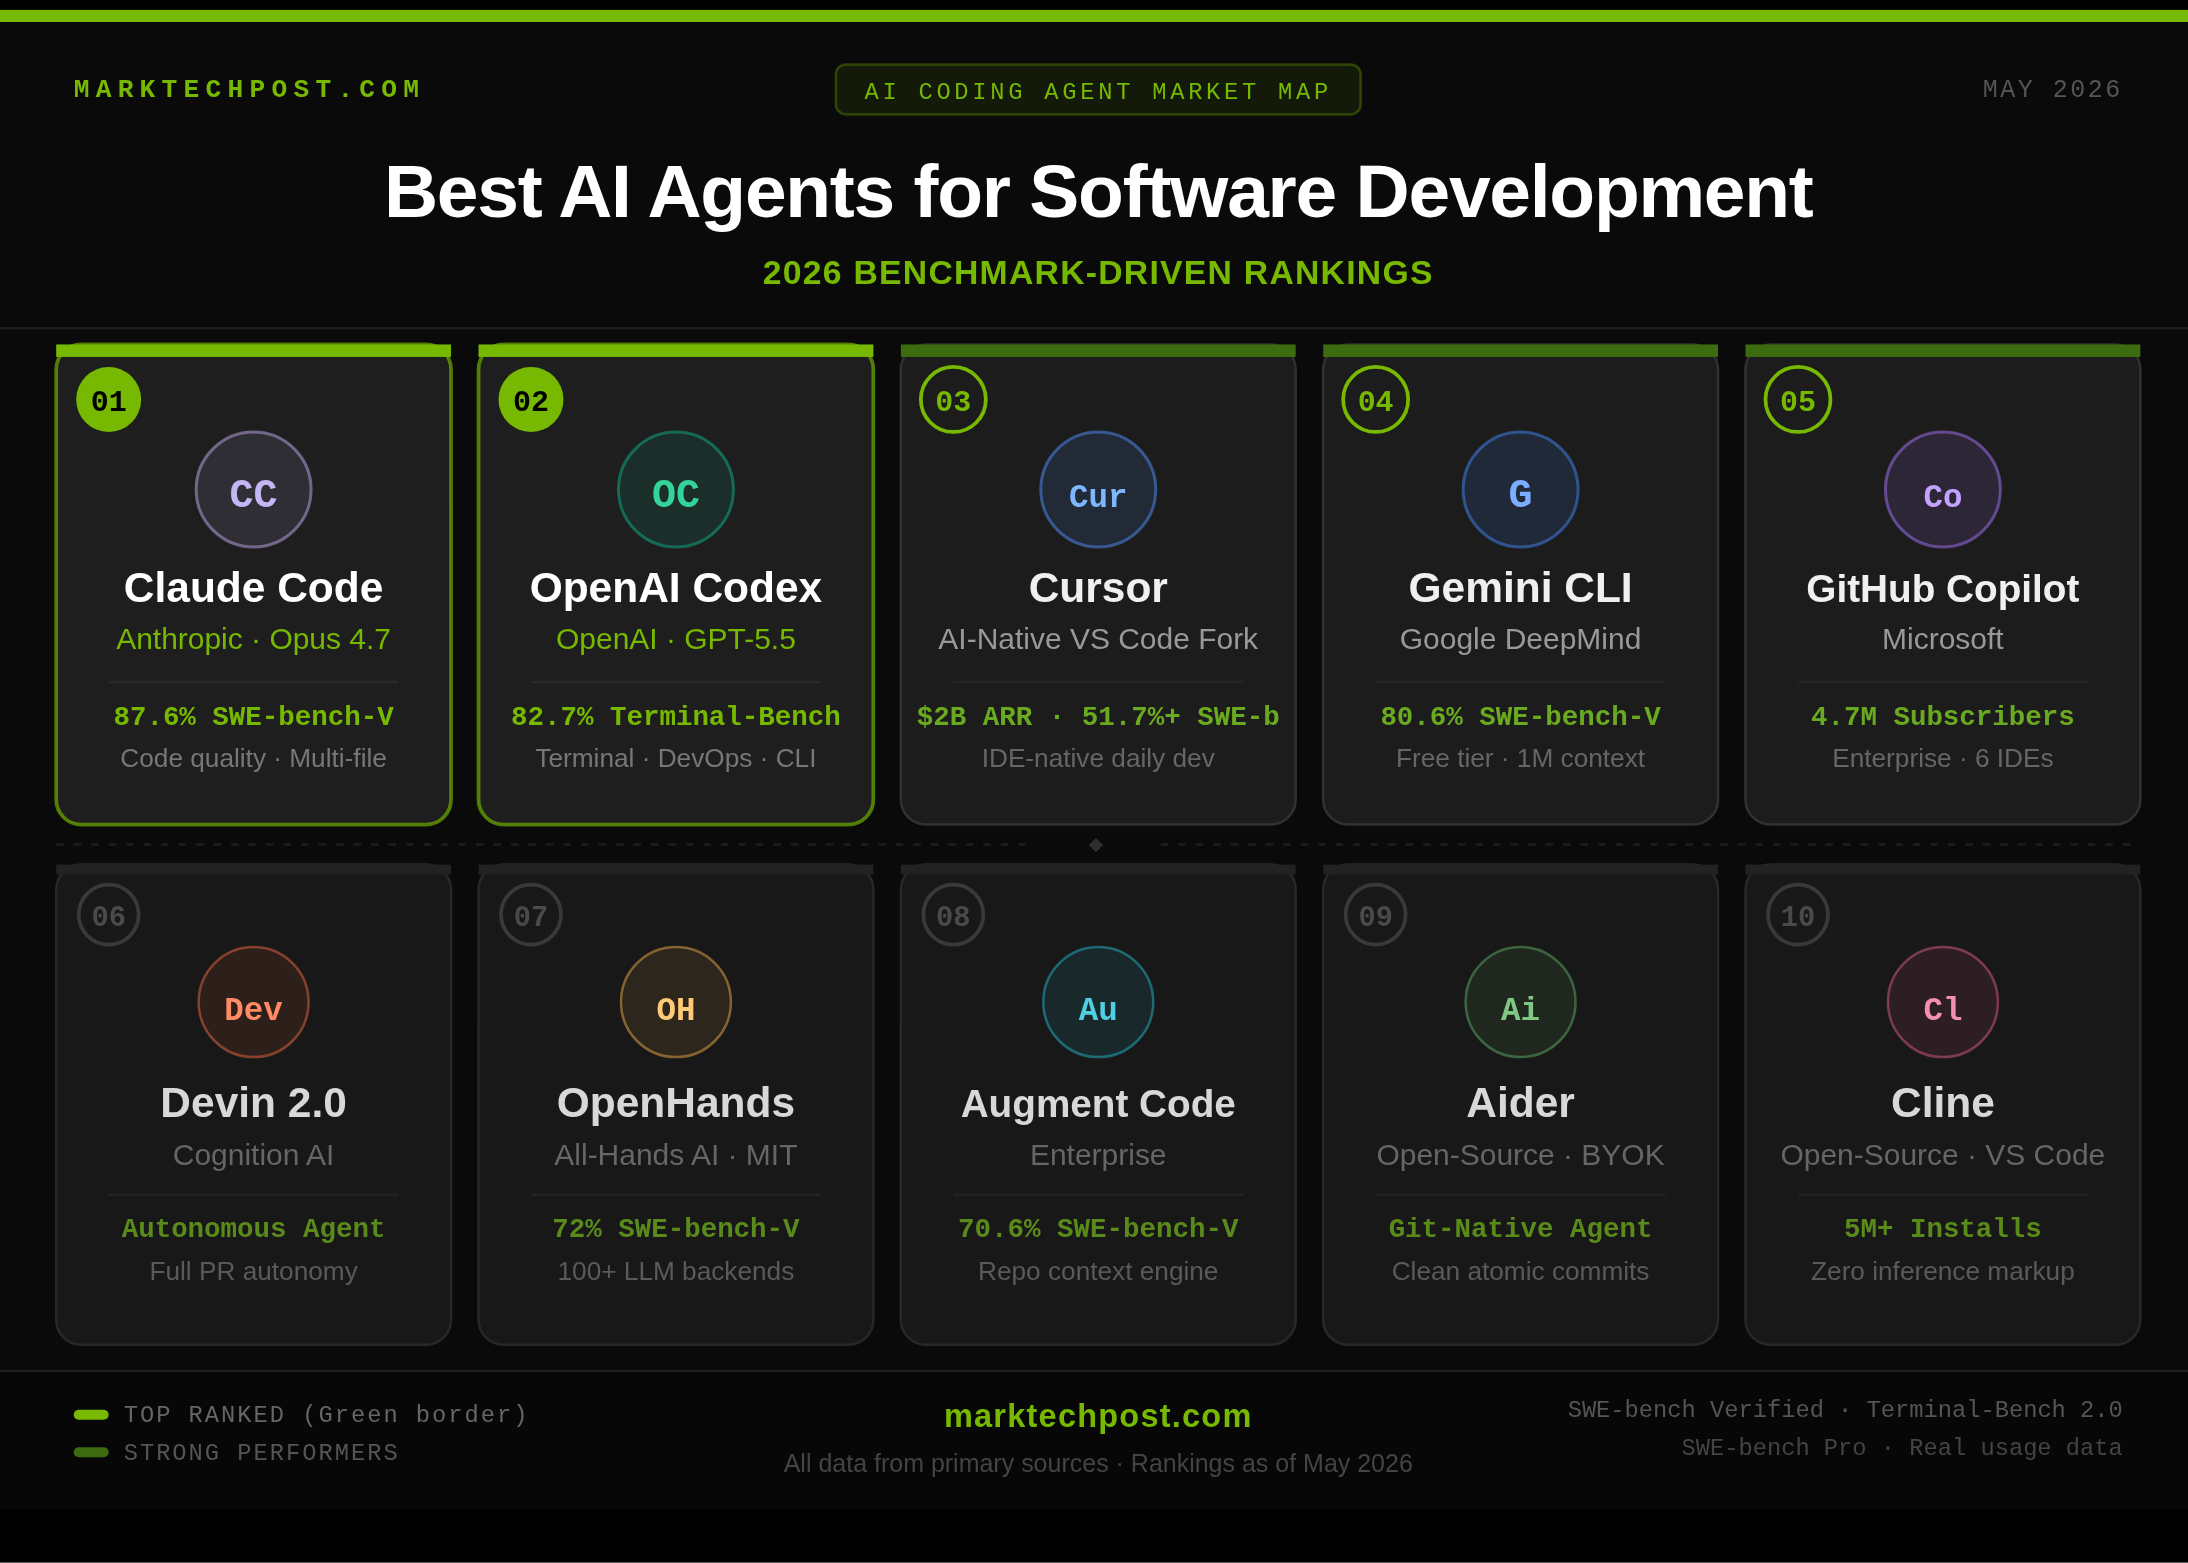
The AI coding agent field in 2026 is more capable, more fragmented, and harder to benchmark than it looks. Claude Code leads on code quality at 87.6% SWE-bench Verified. GPT-5.5 tops Terminal-Bench at 82.7%. But the benchmark OpenAI itself declared contaminated in February 2026…
SWE-bench
stopped reporting SWE-bench Verified
A deep dive by Baseten's research team breaking down the math behind TurboQuant
6 Open-Source Libraries to FineTune LLMs 1. Unsloth GitHub: https://lnkd.in/gQvPWVFb → Fastest way to fine-tune LLMs locally → Optimized for low VRAM (even laptops) → Plug-and-play with Hugging Face models 2. Axolotl GitHub: https://lnkd.in/g34kuExT → Flexible LLM fine-tuning…
By default, general purpose LLMs are not optimized for specific domains and business goals. Using techniques like specialized fine-tuning, pruning unnecessary neural components, and knowledge distillation, you can rearchitect your models to cost less, run faster, and deliver…

In this guide, I’ll show you how to build a Text-to-SQL app that takes your questions and uses AI to translate them.
In this article, I’ll show you how to turn any CSV file into an AI chatbot using Python. Turn Any CSV into an AI Chatbot with Python.

Learning to use LlamaIndex for RAG apps isn’t just about memorizing APIs. It’s about understanding how data moves through the system.
LlamaIndex CEO Jerry Liu argues the framework era is over: agent loops are now capable enough that context quality is the real competitive edge.
LlamaIndex
RAG
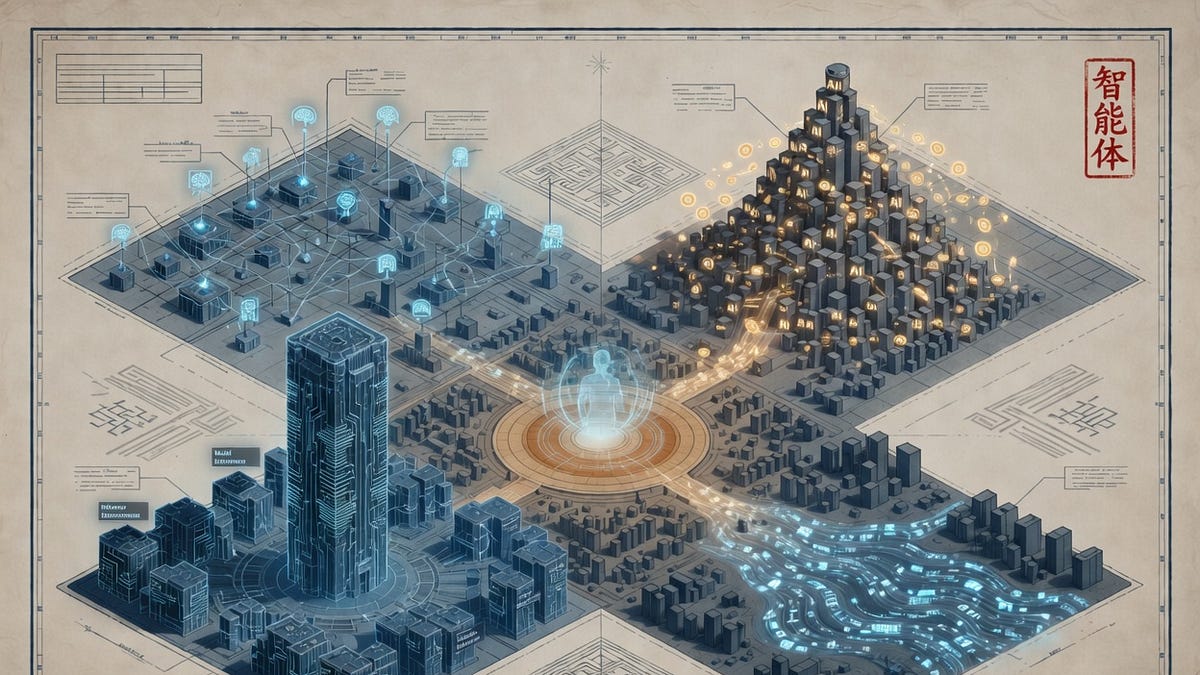
Two Open-Weight Models. Eight Chip Families. One Frontier Co-Engineered for Non-Nvidia Silicon. The Stack Was the Moat. Now It Has a Fork.
Disaggregated inference started as a software technique for splitting prefill and decode onto separate GPU pools. NVIDIA, Groq, Cerebras, and AWS are now taking it further with chips purpose-built for each phase.
prefill-decode disaggregation
production LLM serving
HBM, GDDR, and SRAM compared: how memory hierarchy, bandwidth, and capacity determine AI accelerator performance, cost, and which workloads each chip can serve.
prefill (processing the prompt), which is often compute-bound
decode (token-by-token generation), which is usually memory-bound
Sparse computing enables leaner, faster AI
A fast, helpful, and open-source document parser
KV caches are one of the most critical techniques for efficient inference in LLMs in production.
Ruby's most capable AI runtime
Universal CLAUDE.md - cut Claude output tokens by 63%. Drop-in. No code changes. - drona23/claude-token-efficient
Google published a research blog post on Tuesday about a new compression algorithm for AI models. Within hours, memory stocks were falling. Micron dropped 3 per cent, Western Digital ...
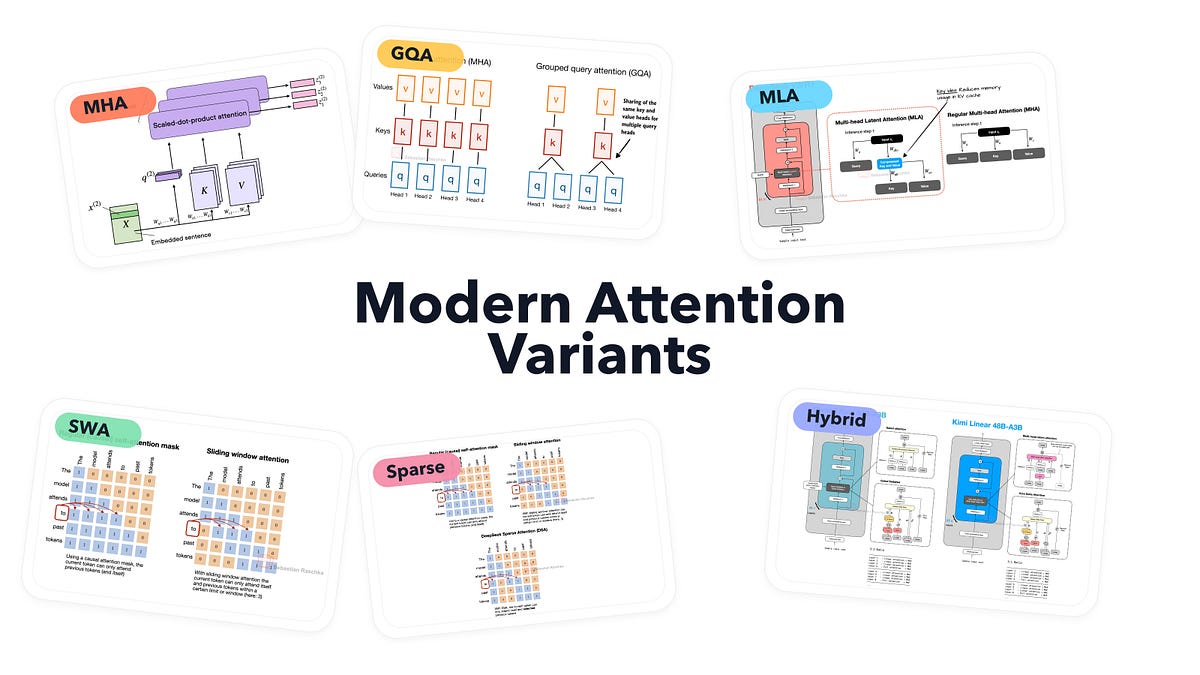
From MHA and GQA to MLA, sparse attention, and hybrid architectures

A gallery that collects architecture figures from The Big LLM Architecture Comparison and related articles, with fact sheets and links back to the original sections.