hbm
94 bookmarks · page 1 of 2
2026-09-01 · wccftech.com

d-Matrix is tackling the 3D DRAM heat problem by stacking memory beneath the XPU, but atomic-level flatness remains a brutal barrier.
2026-08-28 · hothardware.com
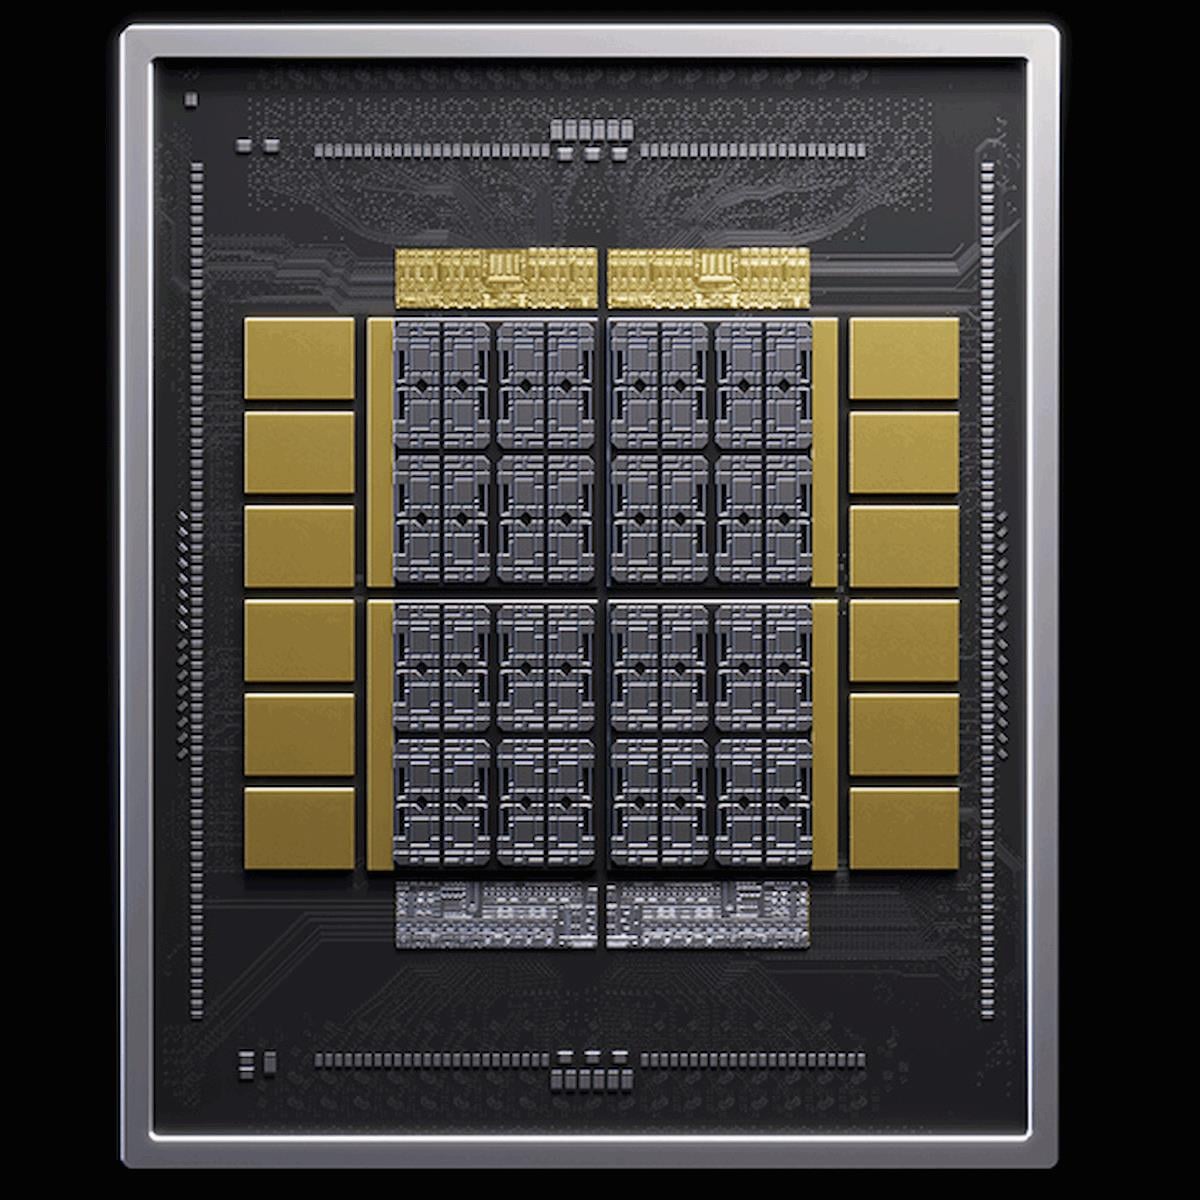
NVIDIA's NVHBM is a new memory technology that partners can license, offering improved efficiency and performance over standard HBM.
2026-08-23 · chipsandcheese.com
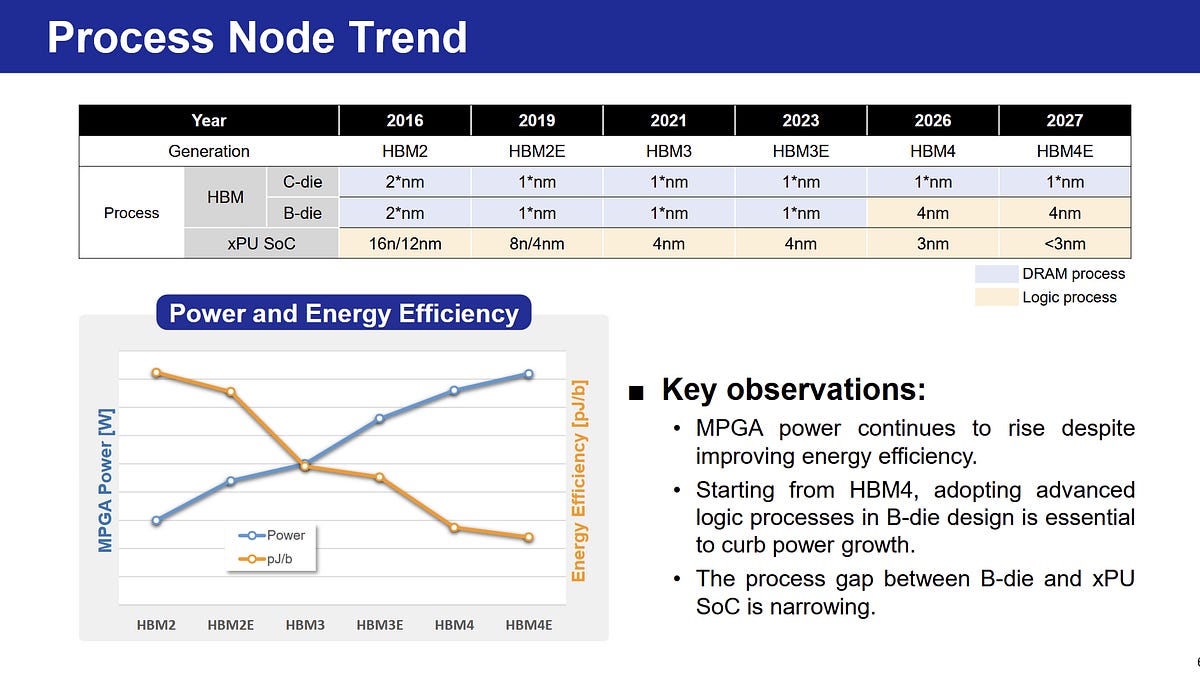
Machine learning applications demand ever more memory capacity and bandwidth. Samsung responded by fabricating their HBM base dies on a logic node, which opens up more opportunities
2026-08-16 · linkedin.com
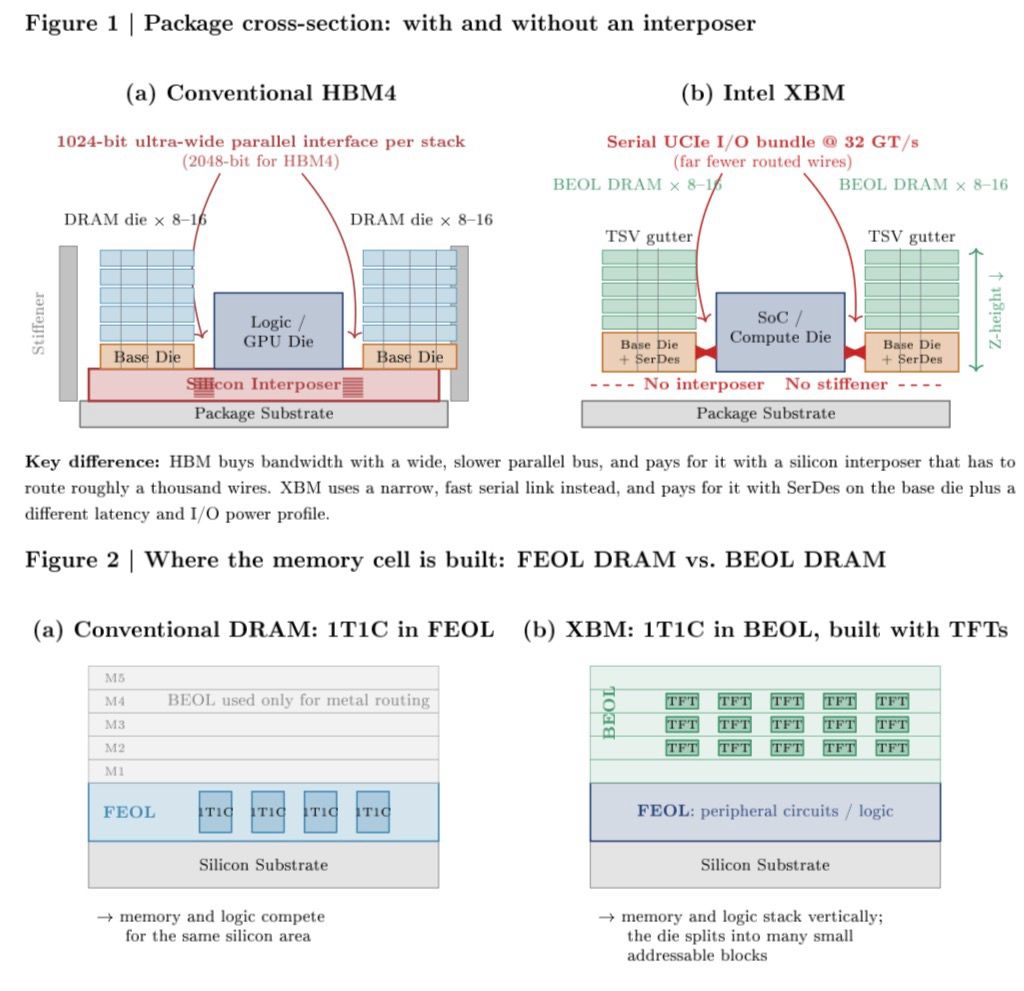
The most expensive part of HBM is not the DRAM. It is the piece of silicon underneath it. HBM moves data over a very wide parallel bus, roughly 1024 bits per stack. Every one of those wires has to be routed through a silicon interposer sitting between the memory and the compute…
2026-08-14 · wccftech.com

HBM manufacturing complexities are keeping general-purpose DRAM as Micron’s main cash cow, with DRAM gross margins projected to reach 95% by 2027
2026-07-22 · linkedin.com
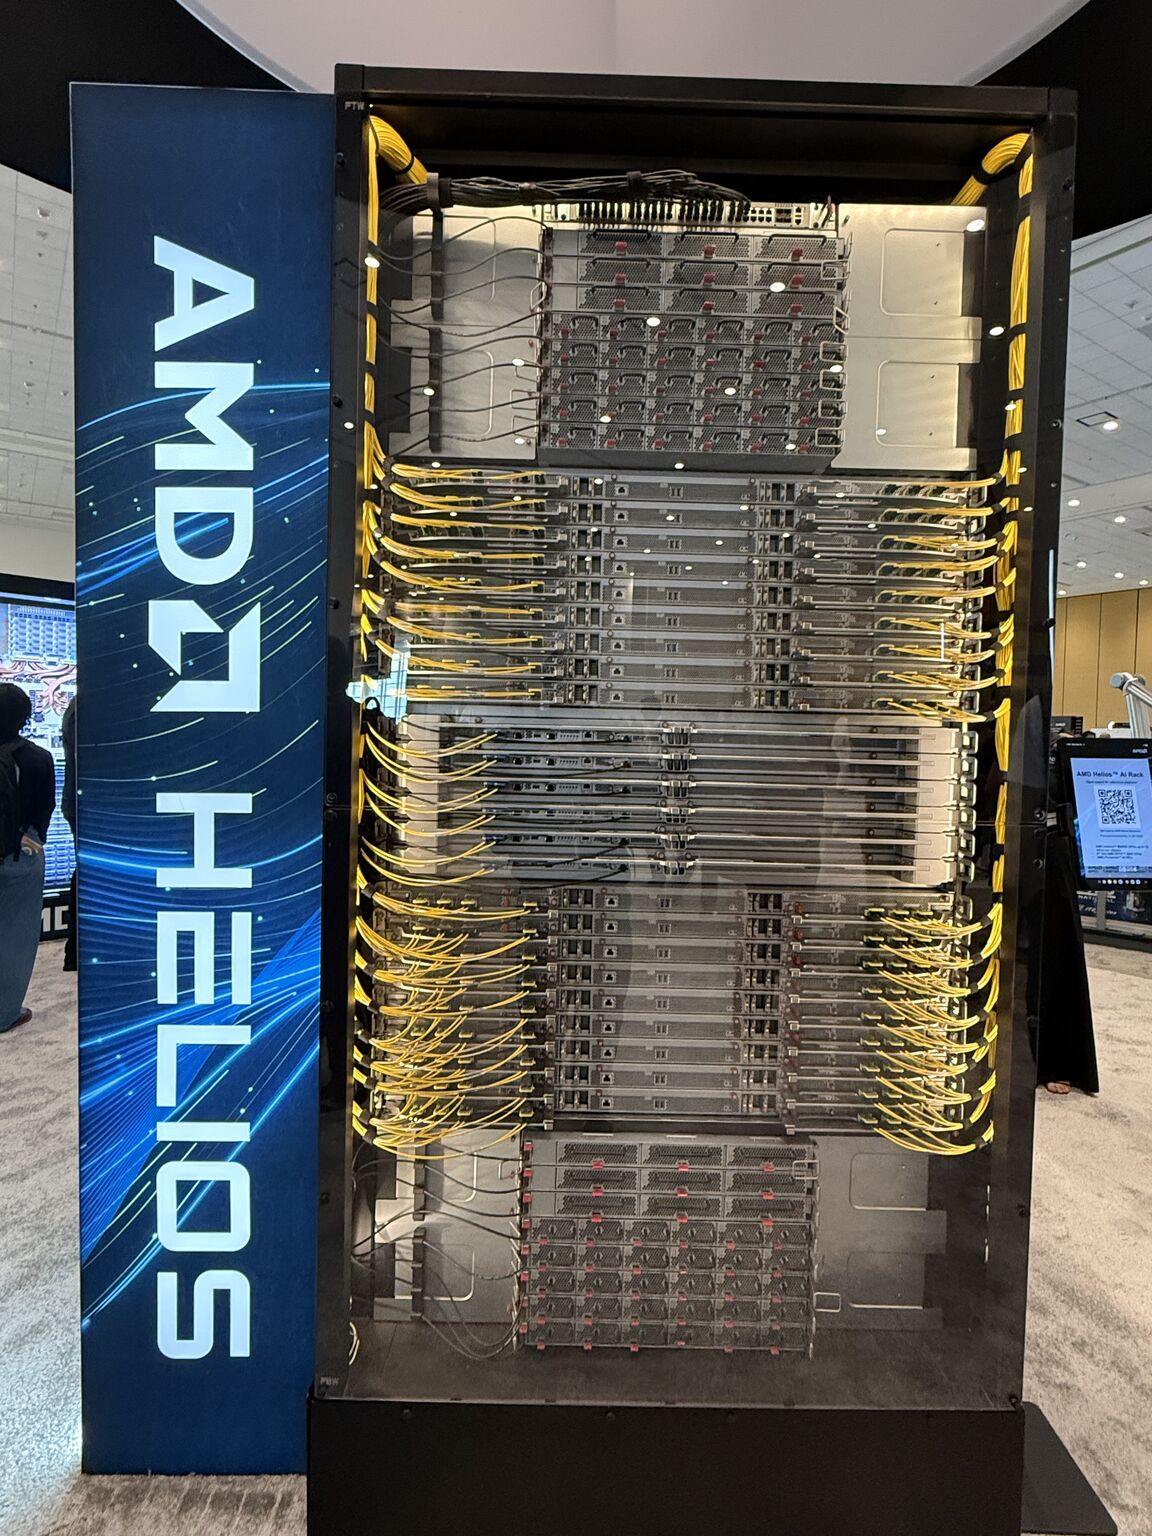
let's talk more technical details about AMD's Helios! Anthropic just signed a $5B deal with AMD. and AMD's own version of GTC, Advancing AI, is happening today and tomorrow. the high level details are: 72 MI455X GPUs, 432GB of HBM4 each, and 2.9 exaflops of FP4. but the most…
2026-07-15 · open.substack.com
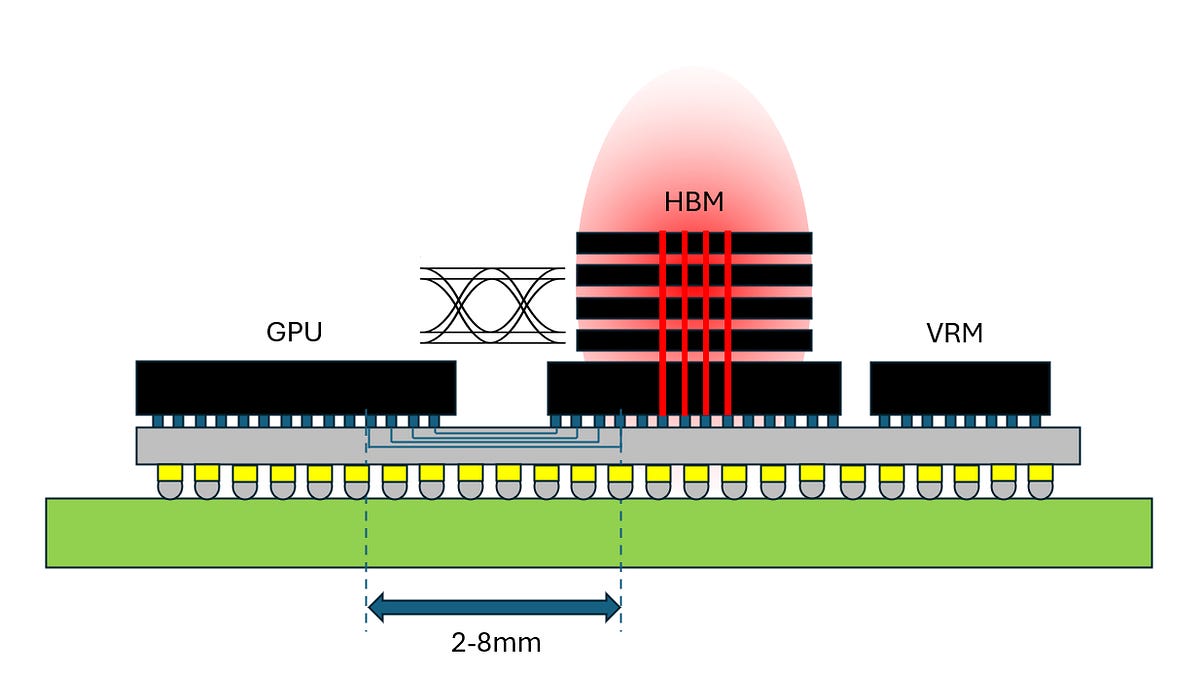
How transmission line effects and power-supply induced jitter make high-speed HBM interconnect scaling one of the most challenging co-design issues in AI racks
2026-03-25 · thenextweb.com
Google published a research blog post on Tuesday about a new compression algorithm for AI models. Within hours, memory stocks were falling. Micron dropped 3 per cent, Western Digital ...
2025-12-18 · morethanmoore.substack.com
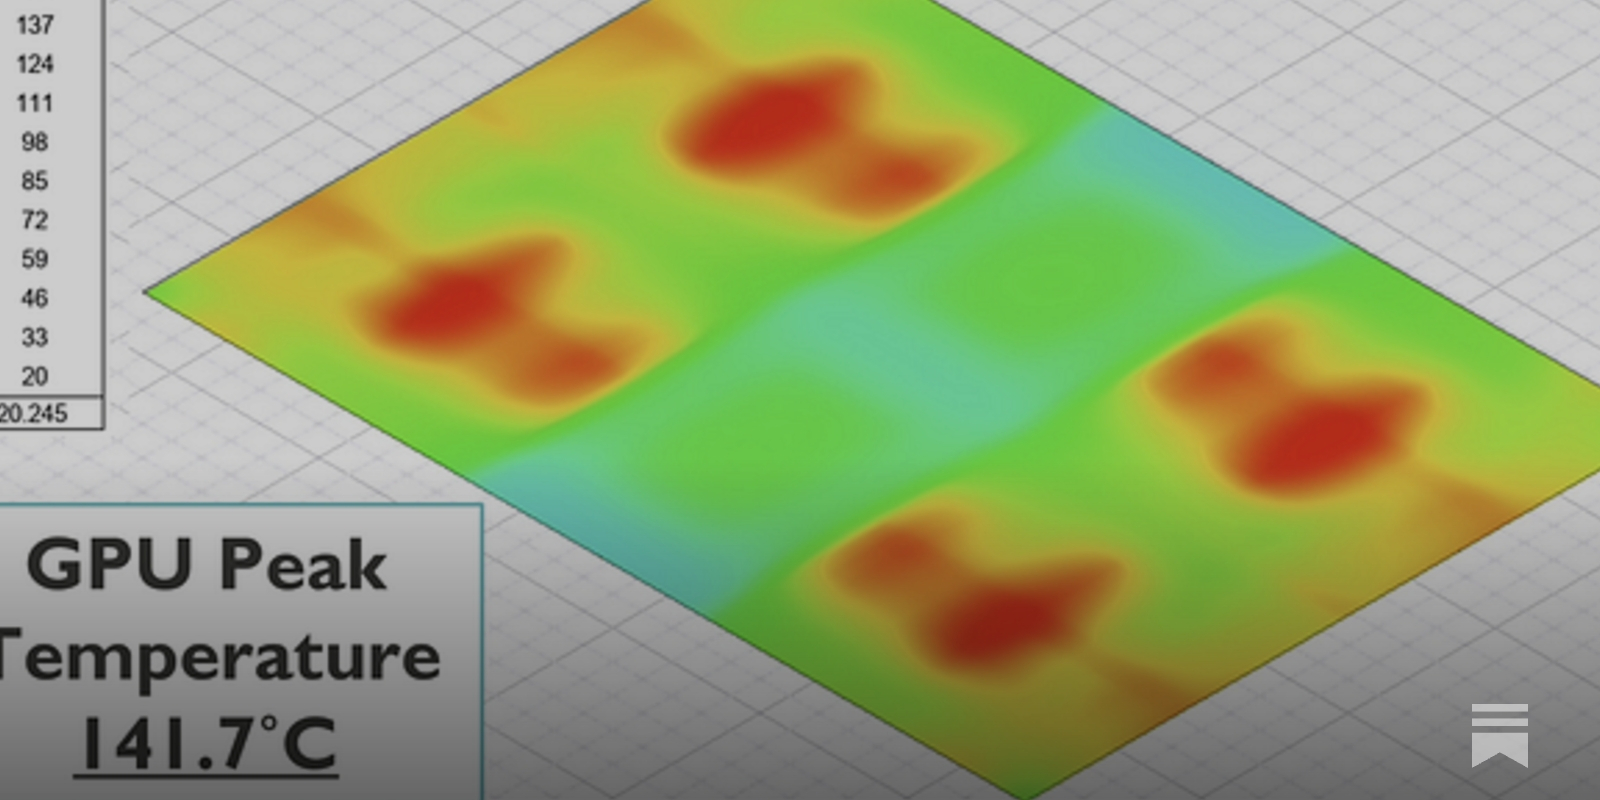
Future AI Accelerators Might Need To Be Slower To Be Faster
This means a singular high-powered compute die consuming ~400W, with multiple 12-Hi HBM stacks.
peak GPU temperature of 69.1ºC, with the HBM silicon reaching around 60ºC in its worst case.
2025-10-14 · semiengineering.com

Bump technologies are being pushed beyond what was thought to be their physical and performance limits.
2025-10-06 · venturebeat.com
The mechanism behind this is a time-resource matrix: A scheduling framework that orchestrates compute, memory and control resources across time. Much like a train timetable, scalar, vector and matrix operations move across a synchronized compute fabric without pipeline stalls or contention.
By predicting exactly when data will arrive — whether in 10 cycles or 200 — Deterministic Execution can slot dependent instructions into the right future cycle. This turns latency from a hazard into a schedulable event, keeping the execution units fully utilized and avoiding the massive thread and…
2025-09-15 · semianalysis.com

Nvidia announced the Rubin CPX, a solution that is specifically designed to be optimized for the prefill phase, with the single-die Rubin CPX heavily emphasizing compute FLOPS over memory bandwidth…
2025-09-11 · semiengineering.com
Timing is increasingly dependent on vectors. Can static techniques continue to deliver the necessary results? Maybe.
2025-09-10 · wccftech.com

NVIDIA has surprisingly unveiled a rather 'new class' of AI GPUs, featuring the Rubin CPX AI chip that offers immense inferencing power.
2025-09-10 · semiengineering.com

A new technical paper titled “On the Thermal Vulnerability of 3D-Stacked High-Bandwidth Memory Architectures” was published by researchers at North Carolina A&T State University and New Mexico State University. Abstract “3D-stacked High Bandwidth Memory (HBM) architectures…
2025-09-05 · arxiv.org

Memory latency, bandwidth, capacity, and energy increasingly limit performance. In this paper, we reconsider proposed system architectures that consist of huge (many-terabyte to petabyte scale) memories shared among large numbers of CPUs. We argue two practical engineering…
2025-08-31 · semiwiki.com
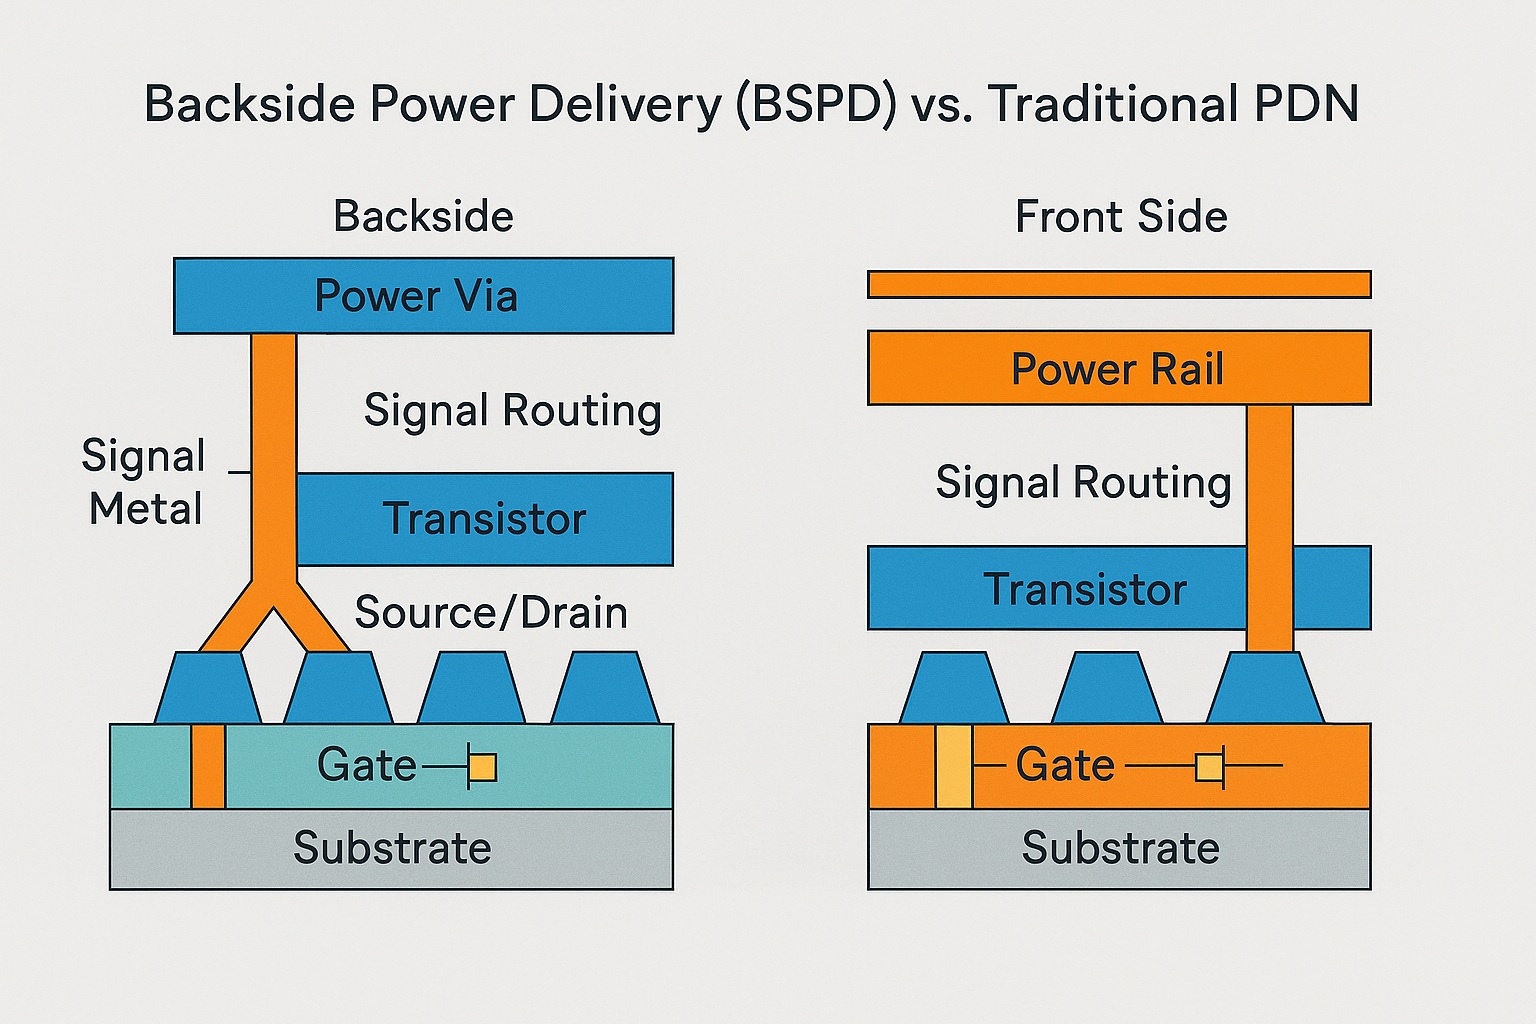
Backside Power Delivery (BSPD), also called Backside Power Delivery Network (BSPDN) or backside power via (BPV) technology, is a semiconductor manufacturing innovation in which the chip’s primary power distribution network … Continue reading "Backside Power Delivery (BSPD) Wiki"
2025-08-25 · wccftech.com

NVIDIA has provided an in-depth look at its fastest chip for AI, the Blackwell GB300, which is 50% faster than GB200 & packs 288 GB memory.
2025-07-29 · nextplatform.com
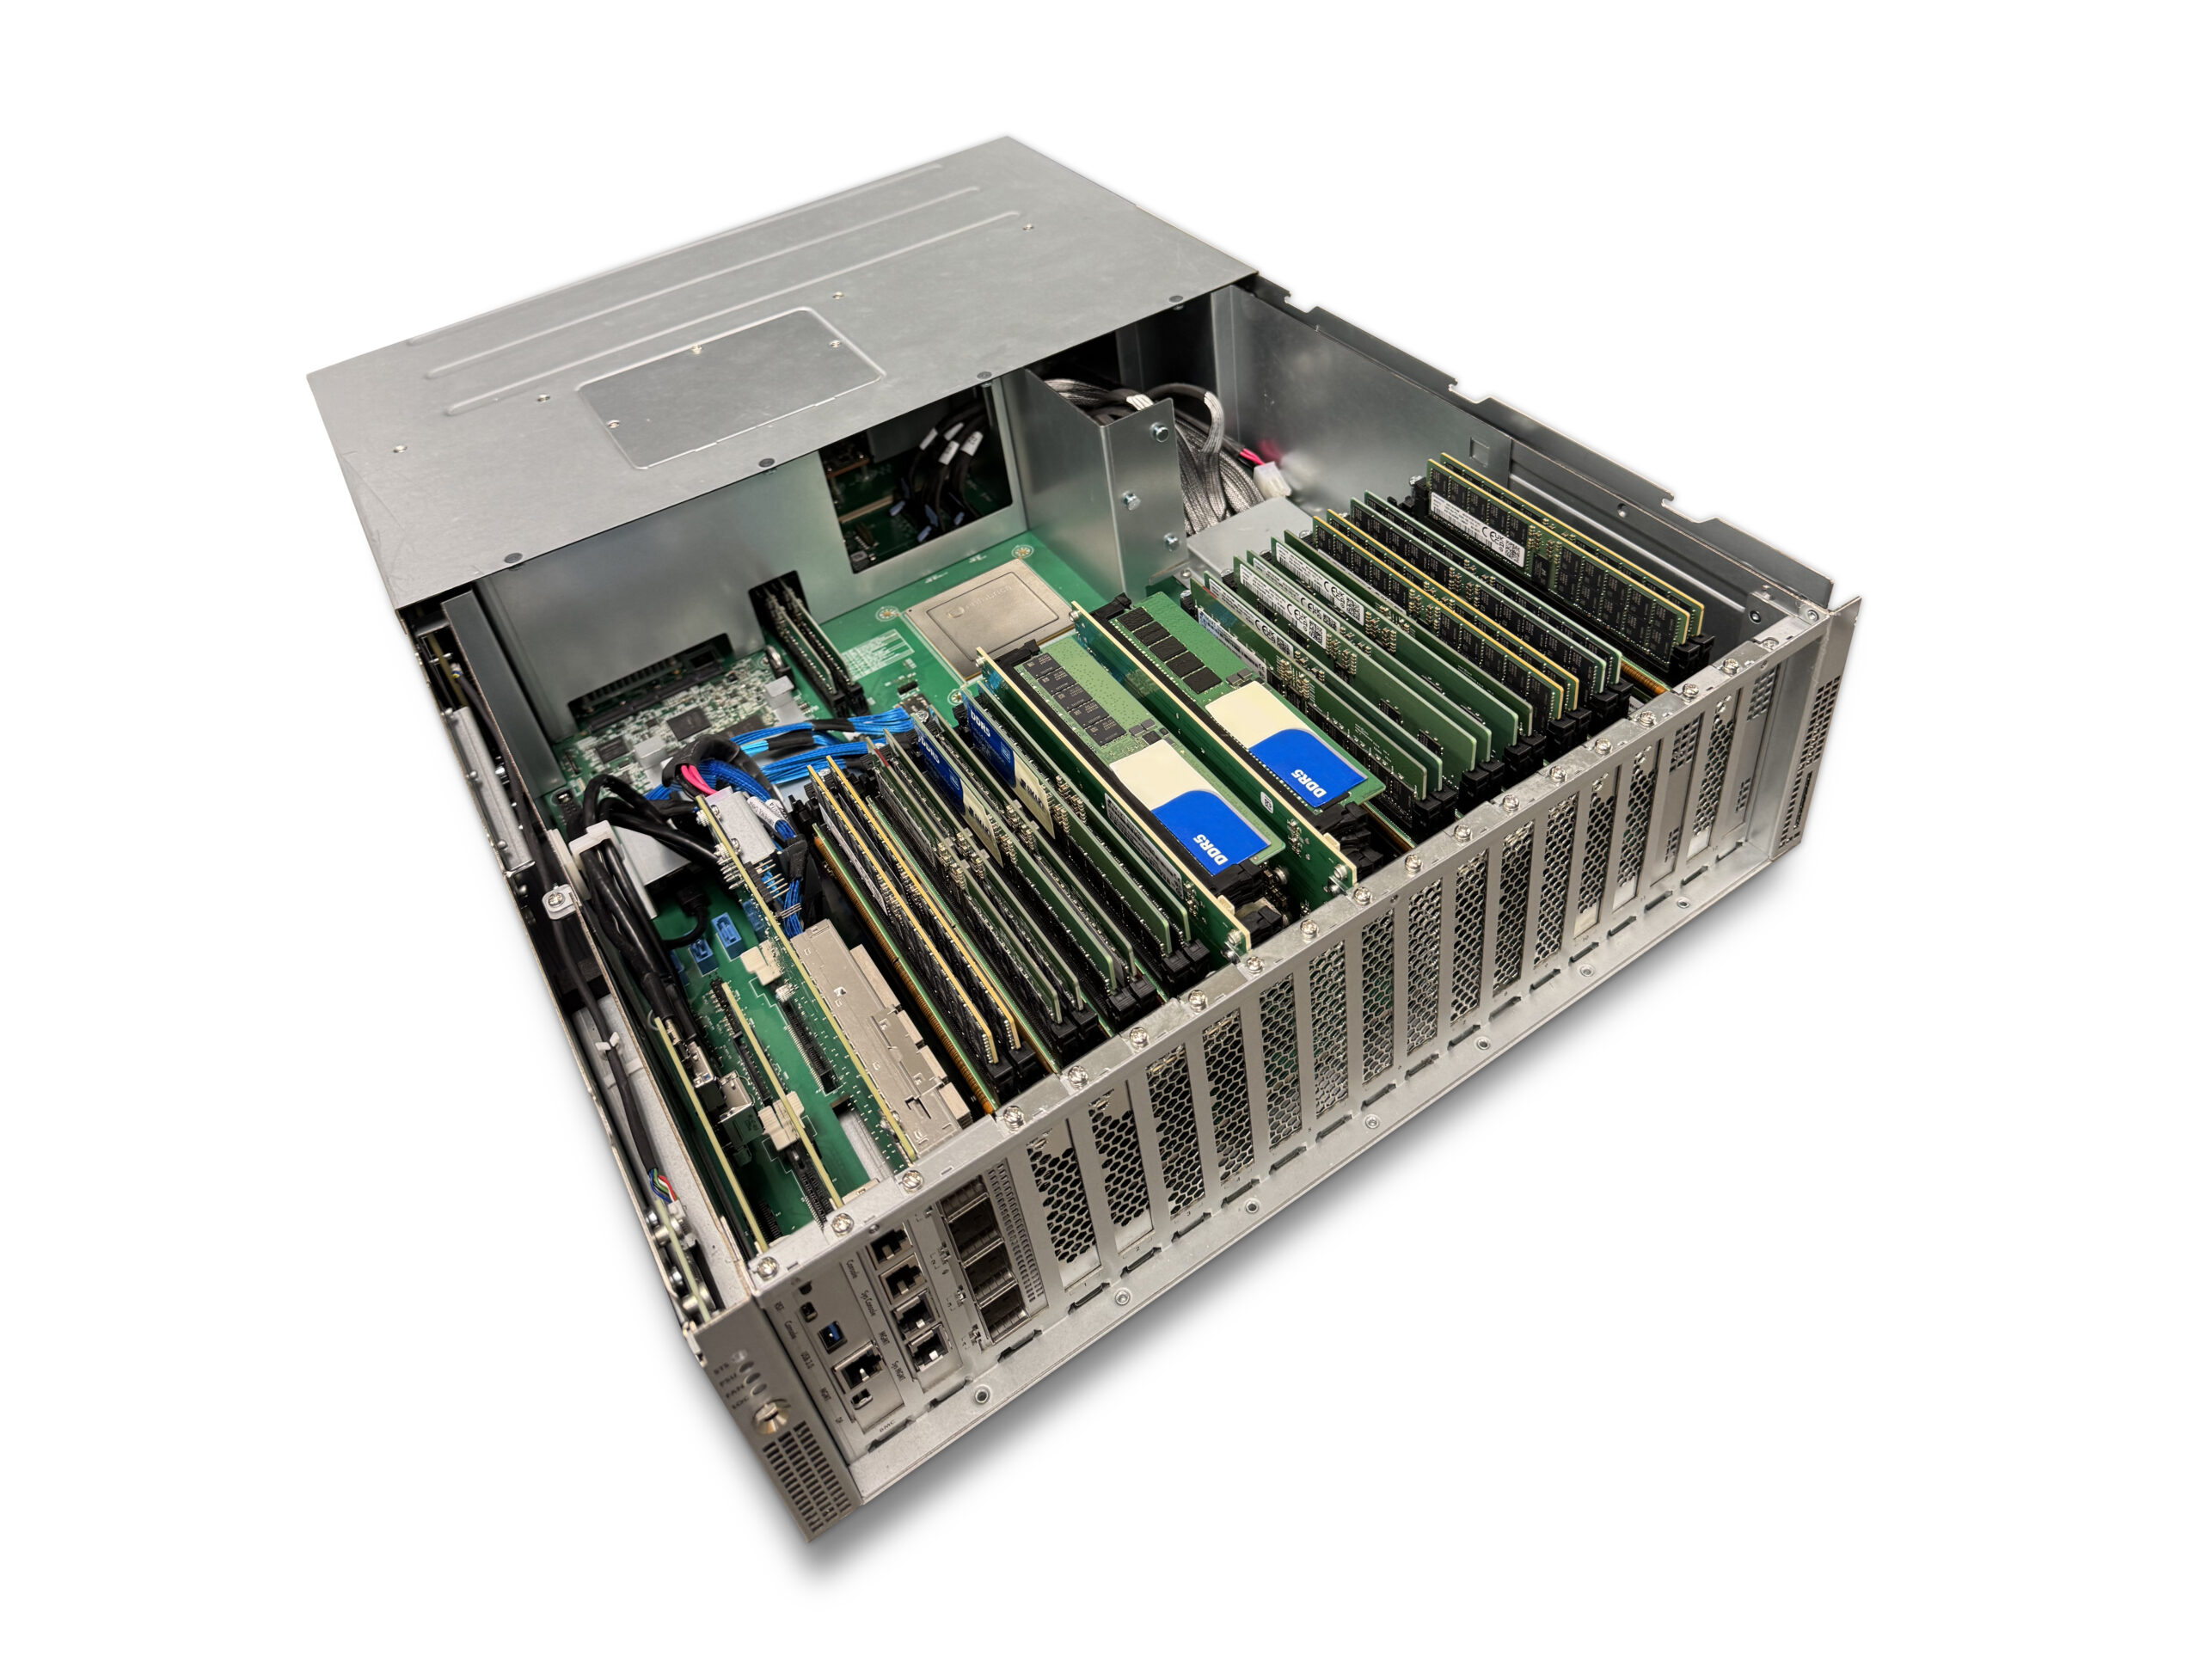
Generative AI is arguably the most complex application that humankind has ever created, and the math behind it is incredibly complex even if the results
2025-07-03 · semiengineering.com

Thin lines and limited ground planes keep RDL interconnects short.
2025-06-26 · blocksandfiles.com

Four more HBM generations have been outlined by KAIST and its Terabyte Interconnection and Package Laboratory research group.
2025-06-18 · tomshardware.com
It is going to get hot.
2025-06-17 · linkedin.com
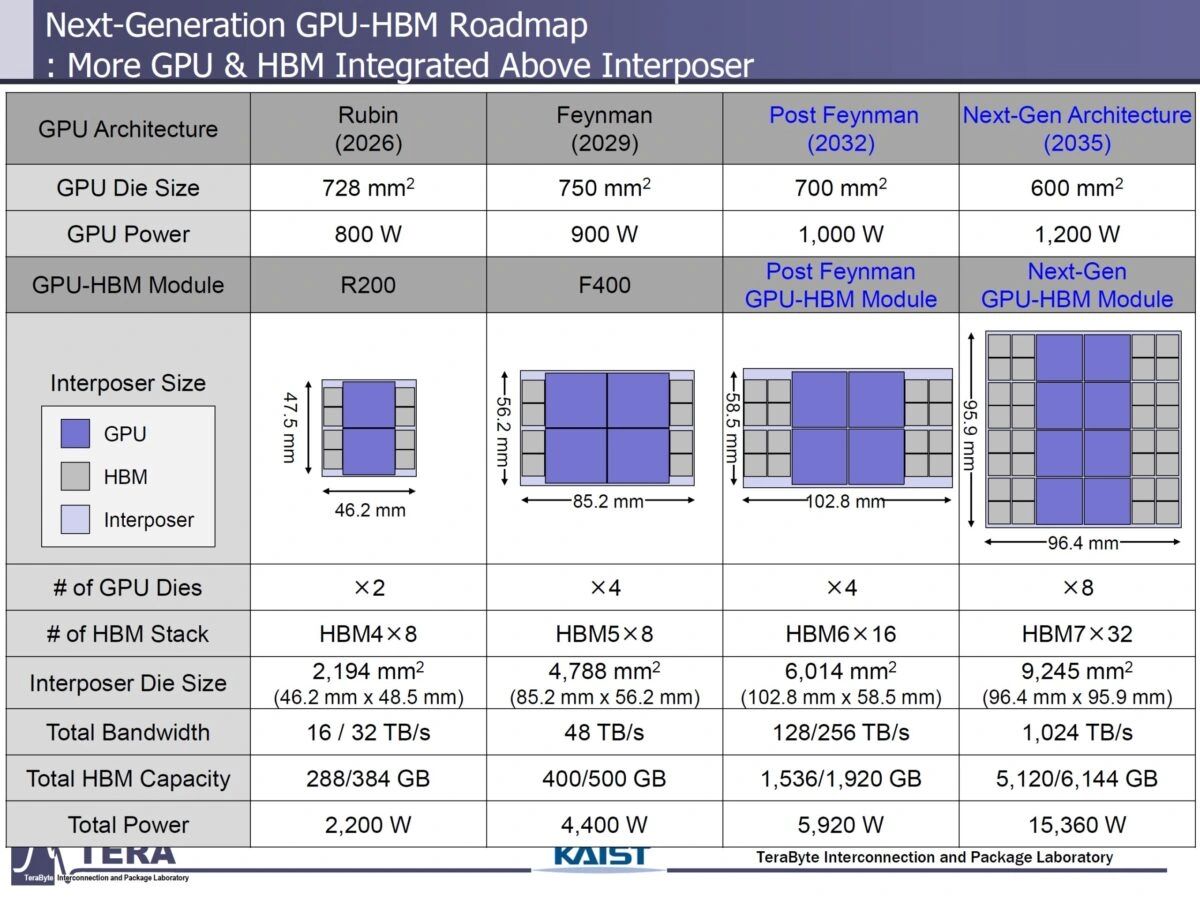
A slide deck revealing the plans (and expectations) for next-generation High Bandwidth Memory (HBM) technology was published by Korea Advanced Institute of Science and Technology and TERA (Terabyte Interconnection and Package Laboratory). Starting with HBM4. This will be the…
2025-05-15 · semiengineering.com

Many features of UCIe 2.0 seen as “heavy” are optional, causing confusion.
The spec is defined with so many variants that you can tailor it to your exact needs. It’s applicable for everything from automotive to high-performance compute to AI to mil/aero because it has so many flavors. That’s also a curse to an IP provider. How do you support all those flavors?”
the latter predominates, since virtually all projects underway are internal projects, with all chiplets being internally created and applied. Interoperability with externally sourced chiplets is therefore not a concern
2025-04-24 · wccftech.com

TSMC also revealed developments in advanced packaging technologies at the NA Technology Symposium, and they look interesting.
2025-04-02 · thememoryguy.com

High-end xPUs (GPUs, TPUs, and other AI processors) use HBM memories to get the absolute highest memory bandwidth for training the Large Language Models (LLMs) used in today's generative AI systems. These processors, used in the thousands by hyperscale datacenters, can consume a…
2025-03-26 · linkedin.com
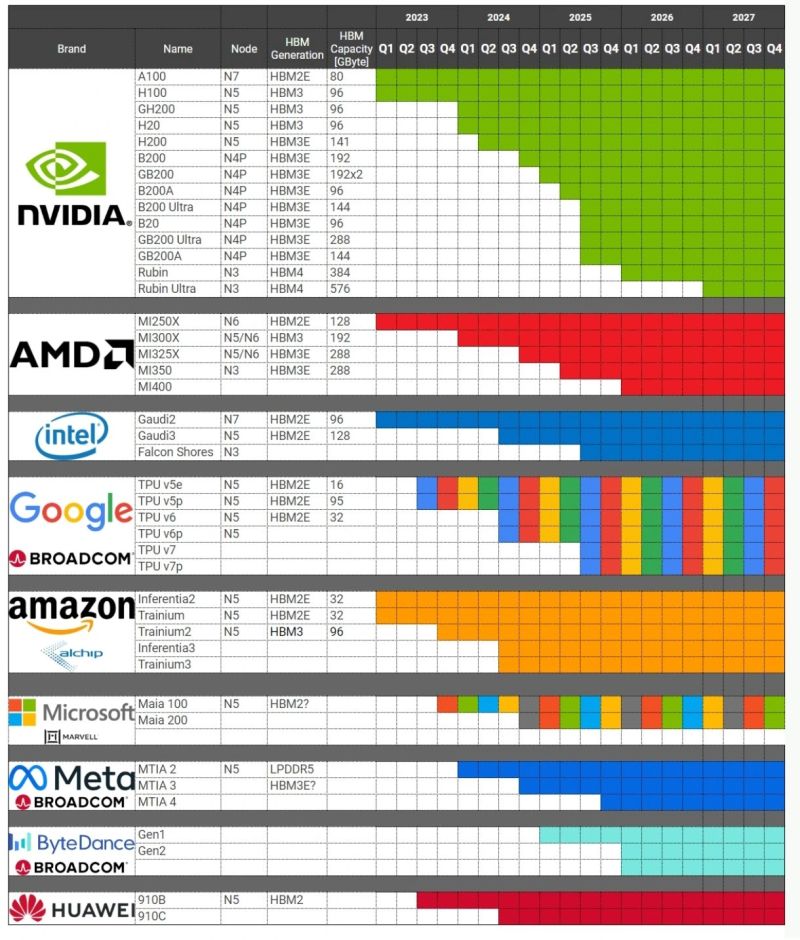
The Future of AI Accelerators: A Roadmap of Industry Leaders The AI hardware race is heating up, with major players like NVIDIA, AMD, Intel, Google, Amazon, and more unveiling their upcoming AI accelerators. Here’s a quick breakdown of the latest trends: Key Takeaways: NVIDIA…
2025-01-30 · nextplatform.com
It is often said that companies – particularly large companies with enormous IT budgets – do not buy products, they buy roadmaps. No one wants to go to
2025-01-29 · asteriskmag.com
By 2030, leading AI labs will need data centers so massive they will require the power equivalent of some of America’s largest cities. Will they be able to find it?
2025-01-18 · open.substack.com

AMD acquired ATI in 2006, hoping ATI's GPU expertise would combine with AMD's CPU know-how to create integrated solutions worth more than the sum of their parts.
2024-12-23 · eetimes.com

Discover how SK hynix’s switch to the advanced 6-phase RDQS scheme helped create the world’s best-performing HBM3E with enhanced capacity and reliability.
2024-12-12 · eetimes.com

Lumai's breakthrough in AI acceleration with free-space optics promises energy cuts and faster processing.
2024-12-12 · semiengineering.com

It hasn’t achieved commercial success, but there is still plenty of development happening; analog IMC is getting a second chance.
2024-10-29 · nextplatform.com
No matter how elegant and clever the design is for a compute engine, the difficulty and cost of moving existing – and sometimes very old – code from the
2024-10-27 · nextplatform.com
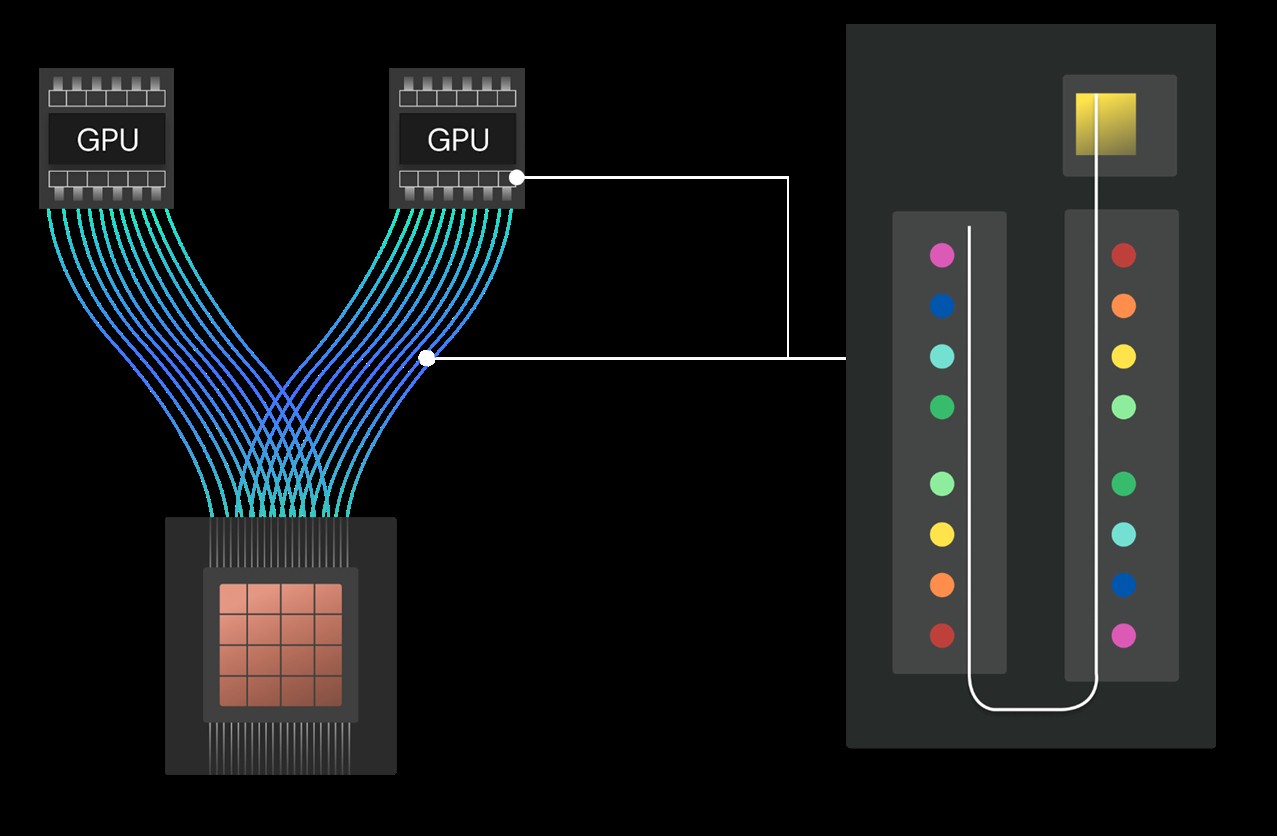
According to rumors, Nvidia is not expected to deliver optical interconnects for its GPU memory-lashing NVLink protocol until the “Rubin Ultra” GPU
2024-10-25 · eetimes.com

As awareness of environmental, social, and governance (ESG) issues grows, companies are adopting strategies for sustainable operations.
2024-10-17 · nextplatform.com
According to rumors, Nvidia is not expected to deliver optical interconnects for its GPU memory-lashing NVLink protocol until the “Rubin Ultra” GPU
2024-07-27 · semiengineering.com
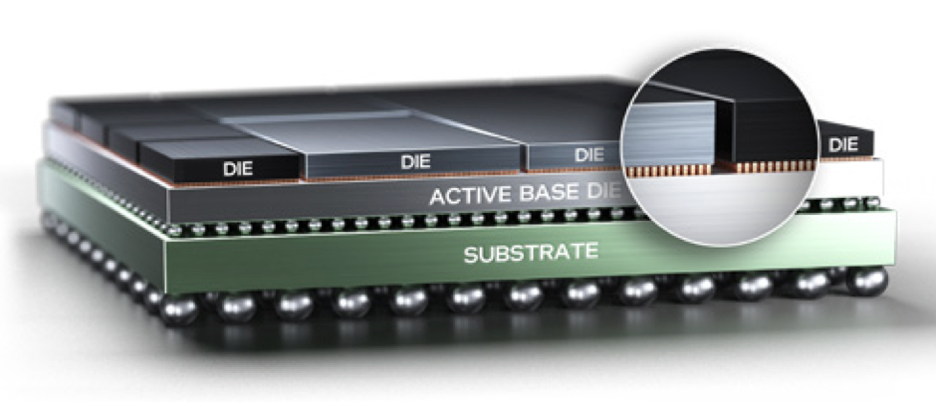
Foundry competition heats up in three dimensions and with novel technologies as planar scaling benefits diminish.
2024-07-14 · pytorch.org
Attention, as a core layer of the ubiquitous Transformer architecture, is a bottleneck for large language models and long-context applications. FlashAttention (and FlashAttention-2) pioneered an approach to speed up attention on GPUs by minimizing memory reads/writes, and is now…
2024-07-13 · hothardware.com
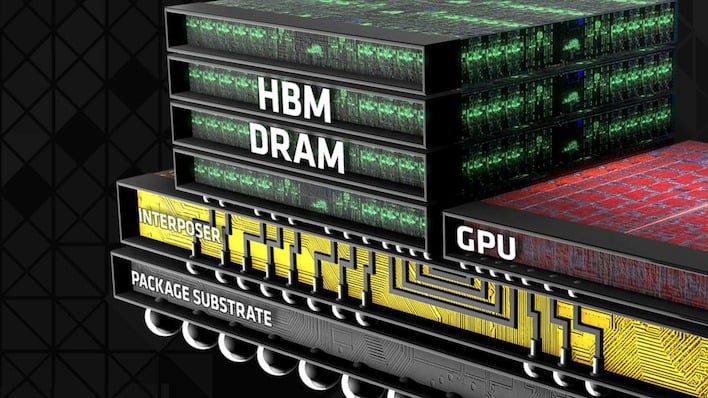
HBM4 is going to double the bandwidth of HBM3, but not through the usual increase in clock rate.
2024-06-25 · semiengineering.com
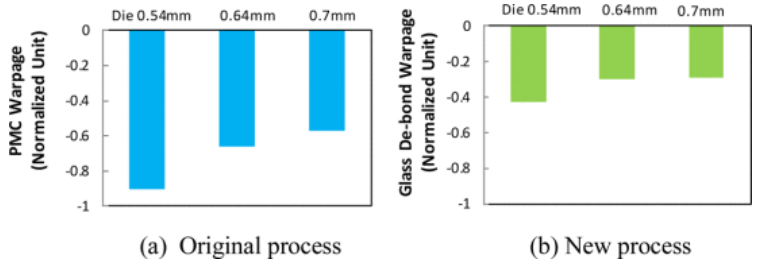
Mechanical stresses increase with larger sizes and heterogeneous materials.
2024-06-17 · yolegroup.com

Generative AI and High Bandwidth Memory (HBM) fuel DRAM market growth. OUTLINE The HBM market has the potential to grow to US$14 billion in 2024. Yole Group expects HBM revenue growth to continue with a CAGR23-29 of ~38%, reaching about US$37.7 billion in 2029. 4F2 cell designs…
2024-06-07 · spectrum.ieee.org

Tech makes millions of connections in a square millimeter of silicon
2024-05-11 · asia.nikkei.com

Demand for high-bandwidth memory is driving competition -- and prices -- higher
2024-04-23 · wccftech.com

Rambus has unveiled its next-gen GDDR7 memory controller IP, featuring PAM3 Signaling, and up to 48 Gbps transfer speeds.
2024-04-05 · nextplatform.com
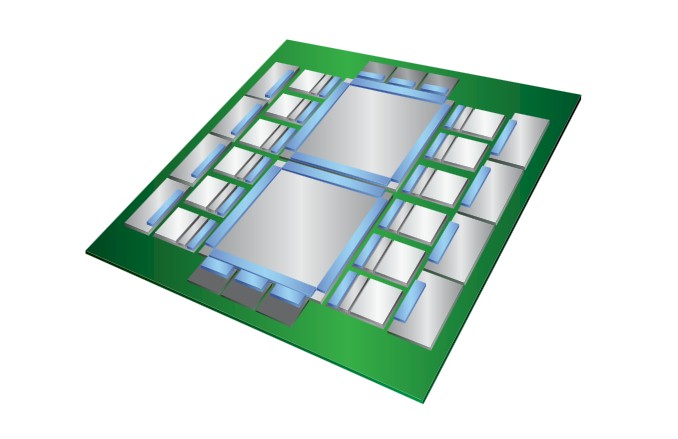
While a lot of people focus on the floating point and integer processing architectures of various kinds of compute engines, we are spending more and more
2024-03-14 · semianalysis.com
The SemiAnalysis AI accelerator model is used to gauge historical and future accelerator production by company and type.
2024-03-12 · semiengineering.com
Explore HBM3E and GDDR6 memory capabilities, including the benefits and design considerations for each
2024-02-22 · blocksandfiles.com
Startup Groq has developed an machine learning processor that it claims blows GPUs away in large language model workloads – 10x faster than an Nvidia GPU at 10 percent of the cost, and needing a tenth of the electricity. Update: Groq model compilation time and time from access…
2024-02-22 · r-bloggers.com

Machine learning is the study and application of algorithms that learn from and make predictions on data. From search results to self-driving cars, it has manifested itself in all areas of our lives and is one of the most exciting and fast-growing fields of research in the world…