sram
97 bookmarks · page 1 of 2
2026-08-24 · wccftech.com

d-Matrix's Raptor 3D DRAM delivers 100 TB/s bandwidth at 0.37 pJ/bit, offering a high-efficiency alternative to SRAM and HBM for AI workloads
2026-08-14 · open.substack.com
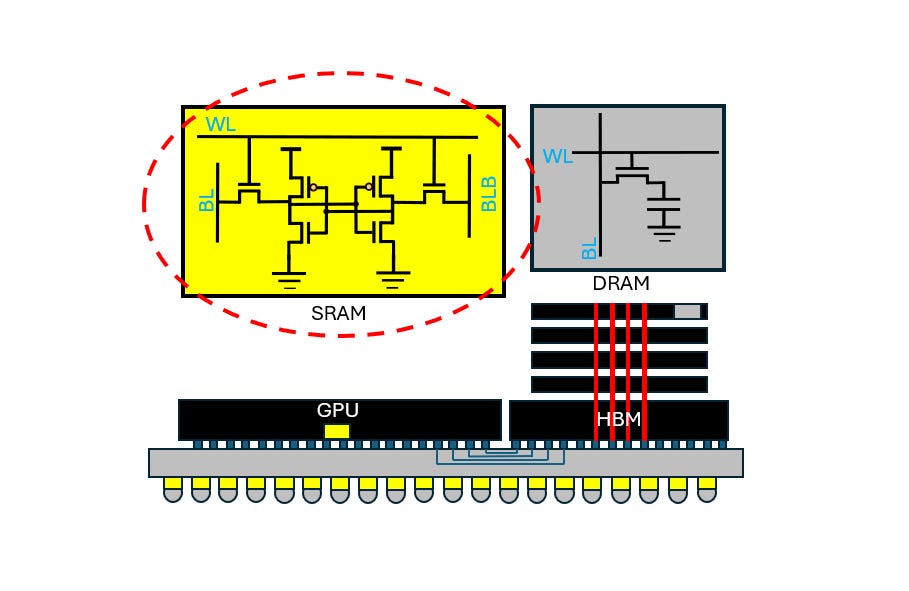
Fundamentals of SRAM and how SRAM constraints affect array size scaling and LLM inference performance
2026-05-20 · open.substack.com
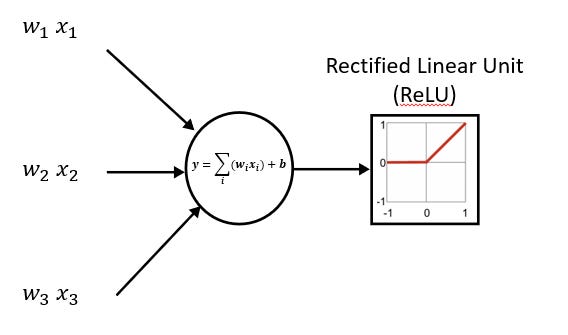
Learning from a classic AI accelerator - Eyeriss
2026-04-02 · semiengineering.com

A new embedded memory architecture with a three-transistor cell.
2026-01-04 · semiengineering.com

A new technical paper titled “Prefill vs. Decode Bottlenecks: SRAM-Frequency Tradeoffs and the Memory-Bandwidth Ceiling” was published by researchers at Uppsala University. Abstract “Energy consumption dictates the cost and environmental impact of deploying Large Language…
Our simulation methodology combines OpenRAM for energy modeling, LLMCompass for latency simulation, and ScaleSIM for systolic array operational intensity.
Counter-intuitively, high compute frequency can reduce total energy by reducing execution time and consequently decreasing static energy consumption more than the resulting dynamic power increase
2025-10-09 · synopsys.com
Discover SRAM PUF’s security benefits and how Synopsys combines it with OTP memory for advanced, secure key storage in embedded systems.
2025-10-06 · venturebeat.com
The mechanism behind this is a time-resource matrix: A scheduling framework that orchestrates compute, memory and control resources across time. Much like a train timetable, scalar, vector and matrix operations move across a synchronized compute fabric without pipeline stalls or contention.
By predicting exactly when data will arrive — whether in 10 cycles or 200 — Deterministic Execution can slot dependent instructions into the right future cycle. This turns latency from a hazard into a schedulable event, keeping the execution units fully utilized and avoiding the massive thread and…
2025-10-04 · arxiv.org

Compute-in-SRAM architectures offer a promising approach to achieving higher performance and energy efficiency across a range of data-intensive applications. However, prior evaluations have largely relied on simulators or small prototypes, limiting the understanding of their…
2025-09-22 · ams-osram.com
Fully integrated dToF modules and iToF VCSEL illuminators for short range applications. Laser sources for long range LIDAR systems.
2025-09-08 · hothardware.com
The idea isn't novel, but presents major challenges. Tensordyne thinks it has solved them, and promises massive speed and efficiency gains as a result.
By using Logarithmic Number Systems (LNS), you can slash both the energy cost and silicon area cost of AI inference computations. How much? Tensordyne says that its upcom
Because AI compute is primarily composed of matrix multiplication, this radically simplifies the workload, and allows the functional units of Tensordyne's chip to be significantly smaller. In turn, more of the die can be SRAM cache (6x as much versus the competition), which improves both…
2025-08-15 · semiengineering.com

A new technical paper titled “Energy-Accuracy Trade-Offs in Massive MIMO Signal Detection Using SRAM-Based In-Memory Computing” was published by researchers at the University of Illinois at Urbana–Champaign. Abstract “This paper investigates the use of SRAM-based in-memory…
Note: “This paper investigates the use of SRAM-based in-memory computing (IMC) architectures for designing energy efficient and accurate signal detectors for massive multi-input multi-output (MIMO) systems. SRAM-based IMCs are the state-of-the-art for executing deep learning workloads in terms of energy efficiency and compute density. However, given the more stringent accuracy requirements of massive…
2025-08-11 · arxiv.org
A100
67.77 million GPU device-hours across 10,693 GPUs.
2025-07-28 · arxiv.org
Traditional von Neumann architectures suffer from fundamental bottlenecks due to continuous data movement between memory and processing units, a challenge that worsens with technology scaling as electrical interconnect delays become more significant. These limitations impede the…
2025-07-26 · cacm.acm.org
2025-07-20 · dev.to
Table of Contents Motivation Optimization goal of GPUs Key concepts of GPUs - software and...
2025-03-27 · semiengineering.com
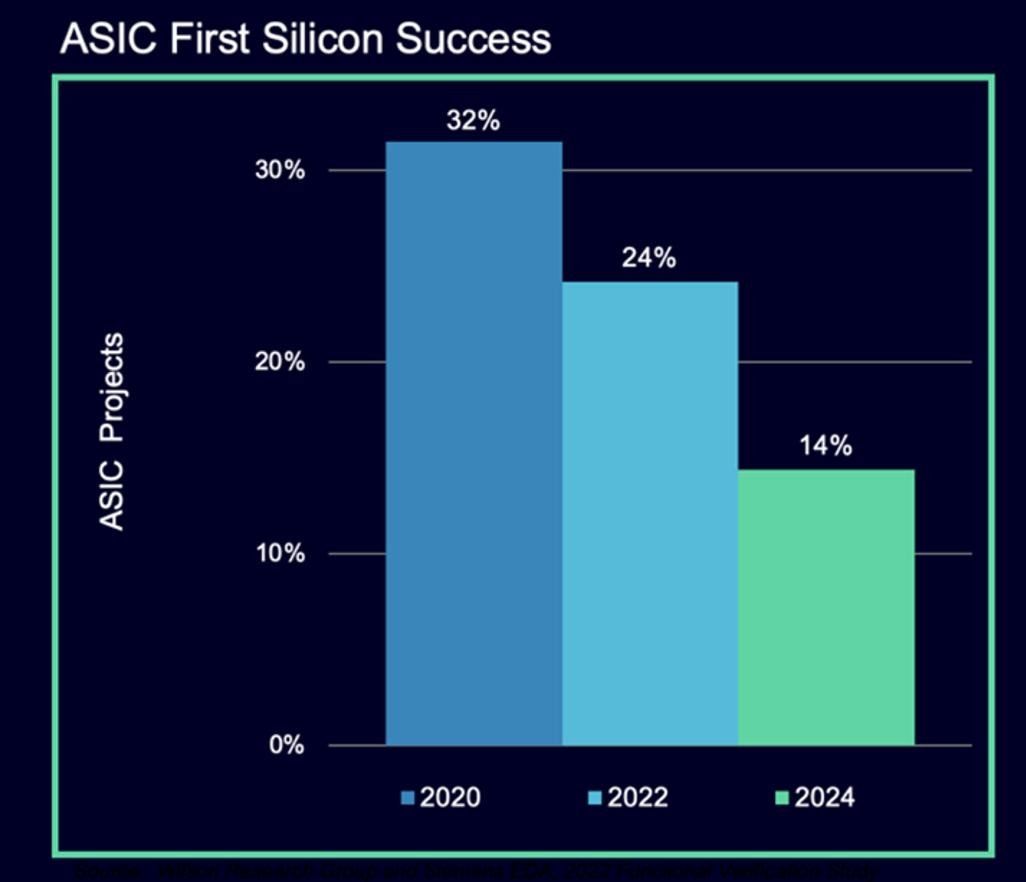
Number of designs that are late increases. Rapidly rising complexity is the leading cause, but tools, training, and workflows need to improve.
“Historically, it’s been around 30%. Two years ago it dropped to 24% from 2023 to 2024. It dropped to 14% this time around. That’s one data point. Another is that historically we’ve seen about two-thirds of projects were behind schedule. That increased to 75% behind schedule.”
2025-03-03 · spectrum.ieee.org
The move to nanosheet transistors is a boon for SRAM
2025-01-08 · hothardware.com
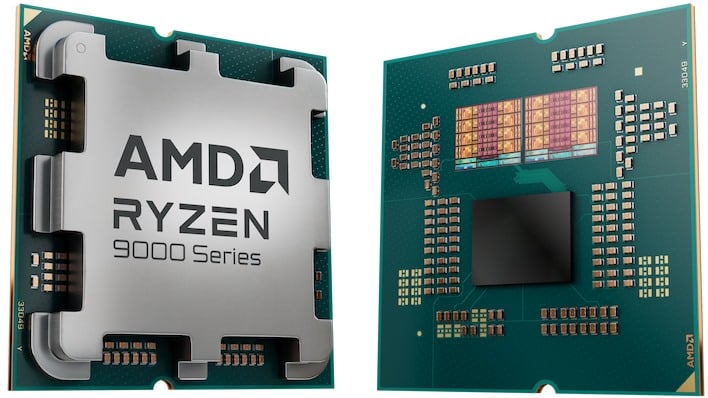
After persistent rumors refused to recede, AMD steps in with a clear explanation why dual-CCD V-Cache doesn't exist.
No, the actual reason AMD won't make a dual-V-Cache chip is much simpler: it would be pointless and a waste of money.
★ 2024-12-22 · arstechnica.com
Compute costs scale with the square of the input size. That’s not great.
This is probably why Google charges twice as much, per token, for Gemini 1.5 Pro once the context gets longer than 128,000 tokens. Generating token number 128,001 requires comparisons with all 128,000 previous tokens, making it significantly more expensive than producing the first or 10th or 100th…
In a series of papers, Princeton computer scientist Tri Dao and several collaborators have developed FlashAttention, which calculates attention in a way that minimizes the number of these slow memory operations.
2024-12-21 · wccftech.com

The CCD stack with 3D V-Cache on the AMD Ryzen 7 9800X3D is only 40-45µm in total, but the rest of the layers add up to a whopping 750µm.
stability
9800X3D brought the 3D chiplet underneath the CC
2024-12-21 · marktechpost.com

Large Language Models (LLMs) have become a cornerstone of artificial intelligence, driving advancements in natural language processing and decision-making tasks. However, their extensive power demands, resulting from high computational overhead and frequent external memory…
2024-12-15 · spectrum.ieee.org

And Intel shows how far these devices could go
2024-12-12 · semiengineering.com

It hasn’t achieved commercial success, but there is still plenty of development happening; analog IMC is getting a second chance.
★ 2024-11-26 · github.com

Notes from the Latent Space paper club. Follow along or start your own! - eugeneyan/llm-paper-notes
2024-11-25 · asap.asu.edu
2024-10-25 · eetimes.com

As awareness of environmental, social, and governance (ESG) issues grows, companies are adopting strategies for sustainable operations.
2024-08-02 · eetimes.com

There are many chip partitioning and placement tradeoffs when comparing top-tier smartphone processor designs.
2024-07-20 · anandtech.com
2024-07-14 · pytorch.org
Attention, as a core layer of the ubiquitous Transformer architecture, is a bottleneck for large language models and long-context applications. FlashAttention (and FlashAttention-2) pioneered an approach to speed up attention on GPUs by minimizing memory reads/writes, and is now…
2024-06-08 · semiengineering.com
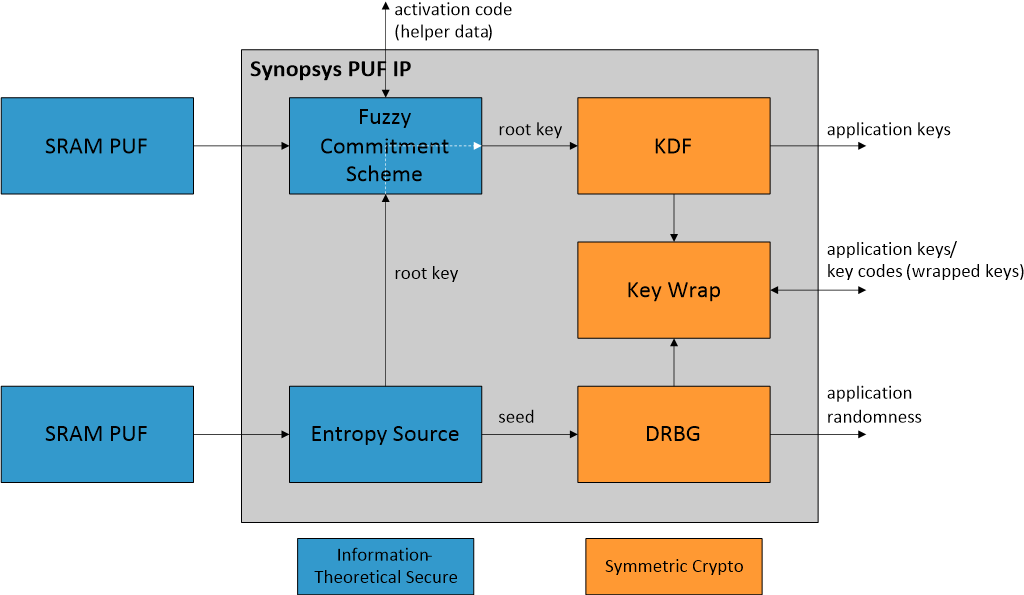
The impact of quantum algorithms on different cryptographic techniques and what can be done about it.
2024-05-23 · anandtech.com
2024-05-16 · spectrum.ieee.org
Imec’s plan to use superconductors to shrink computers
2024-05-10 · semiengineering.com
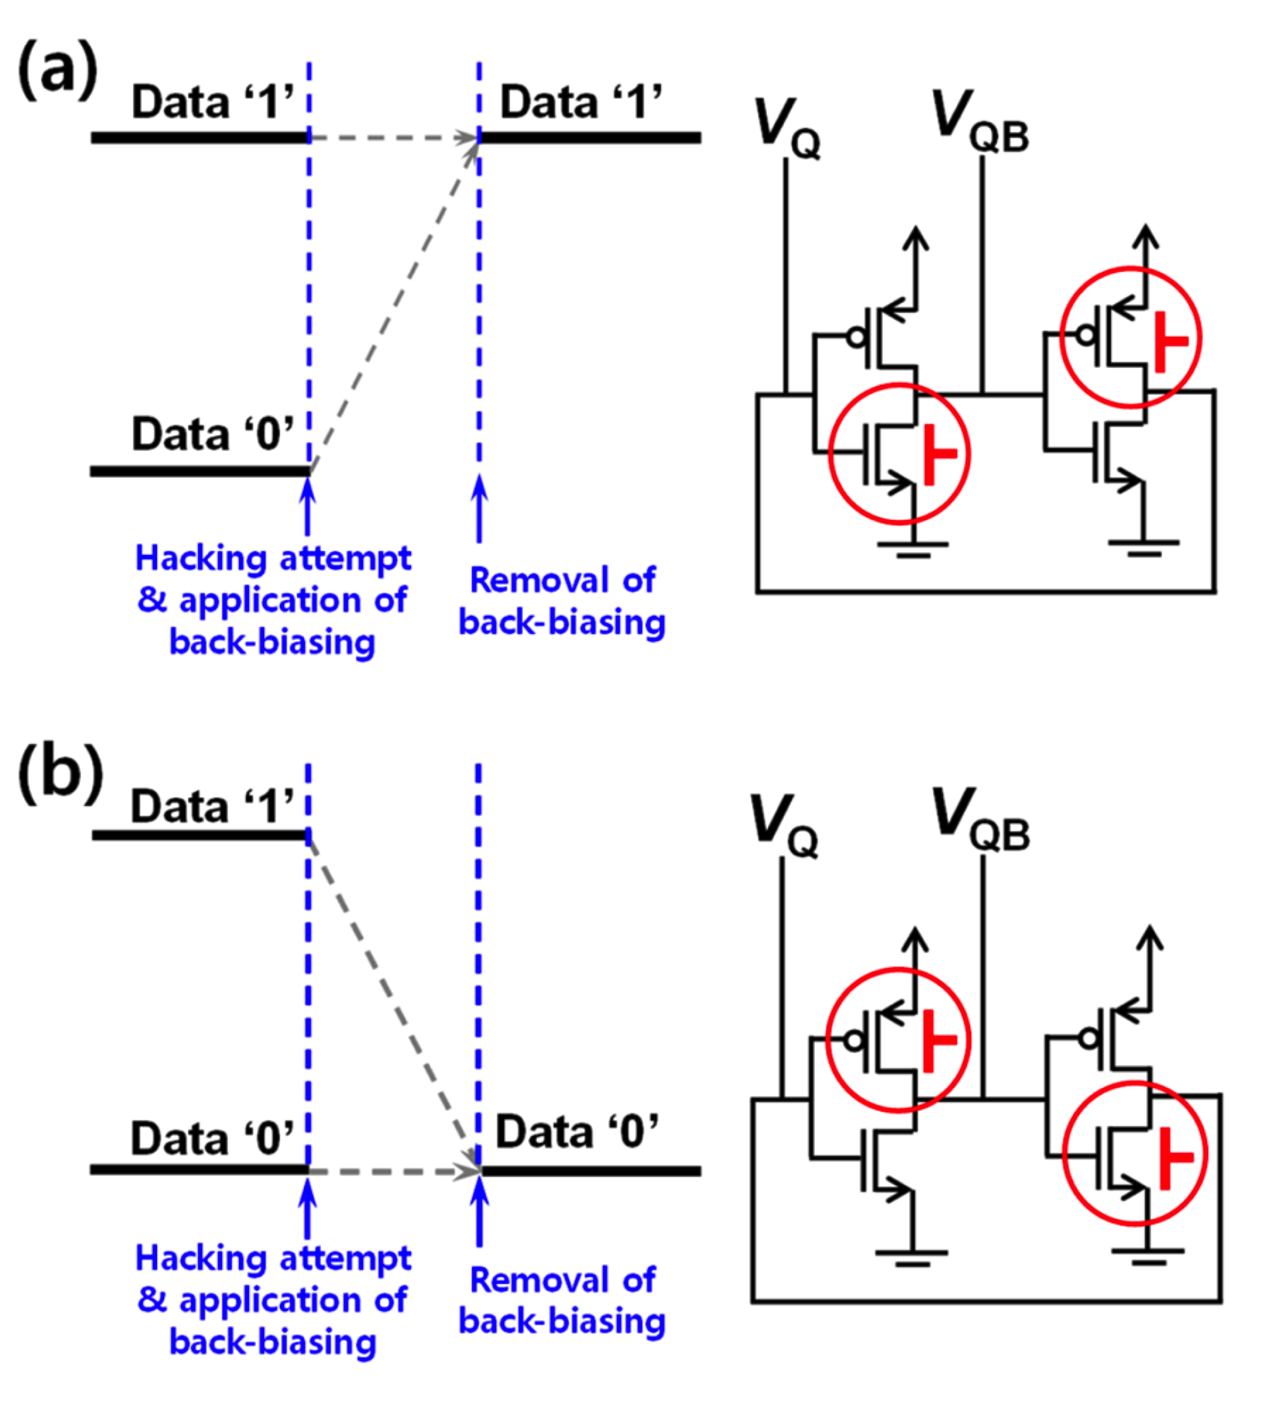
Volatile memory threat increases as chips are disaggregated into chiplets, making it easier to isolate memory and slow data degradation.
2024-02-24 · sciencedirect.com

We present a predictive process design kit (PDK) for the 5 nm technology node, the ASAP5 PDK. ASAP5 is not related to a particular foundry and the ass…
2024-02-22 · blocksandfiles.com
Startup Groq has developed an machine learning processor that it claims blows GPUs away in large language model workloads – 10x faster than an Nvidia GPU at 10 percent of the cost, and needing a tenth of the electricity. Update: Groq model compilation time and time from access…
2024-02-22 · semianalysis.com
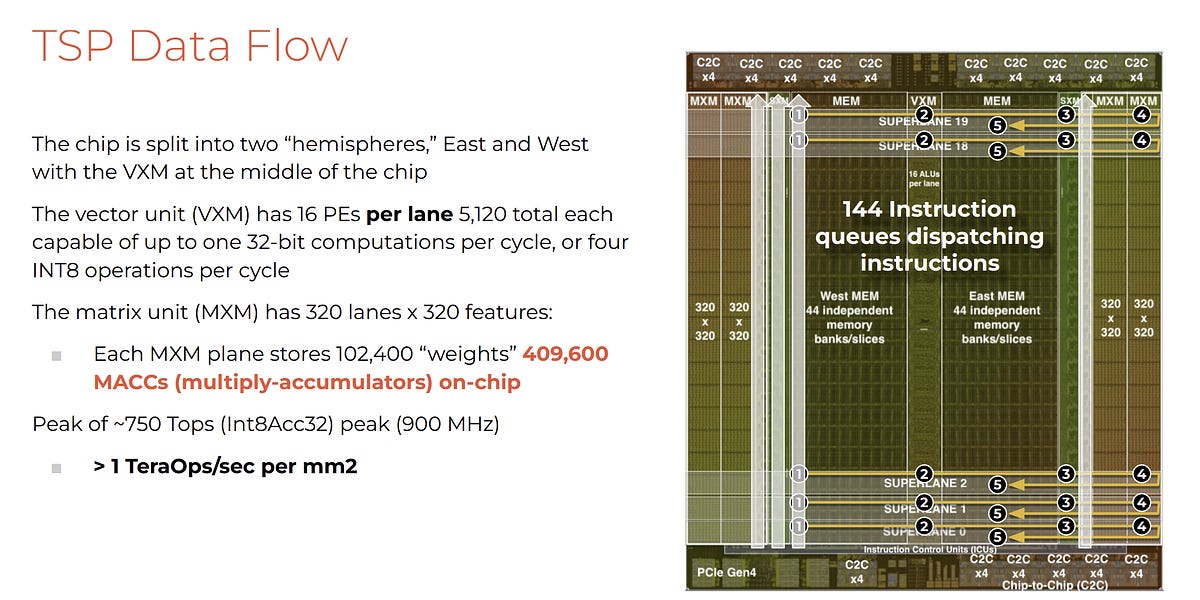
Faster than Nvidia? Dissecting the economics
2023-08-09 · downfall.page
Downfall attacks targets a critical weakness found in billions of modern processors used in personal and cloud computers.
2023-07-28 · spectrum.ieee.org

Atom-thin layers of oxygen in a chip’s silicon can make devices speedier and more reliable
2023-07-24 · gordicaleksa.medium.com
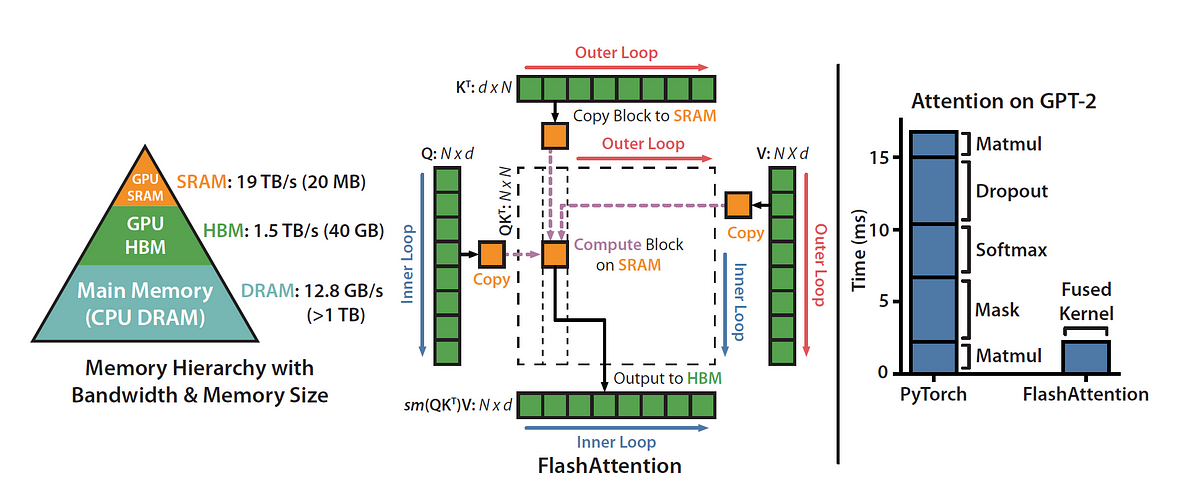
Step by step explanation of how one of the most important MLSys breakthroughs work — in gory detail.
2023-07-24 · semiengineering.com
A technical paper titled “Benchmarking and modeling of analog and digital SRAM in-memory computing architectures” was published by researchers at KU Leuven. Abstract: “In-memory-computing is emerging as an efficient hardware paradigm for deep neural network accelerators at the…
2023-07-23 · blog.gopenai.com
tldr; techniques to speed up training and inference of LLMs to use large context window up to 100K input tokens during training and…
2023-06-05 · chipsandcheese.com
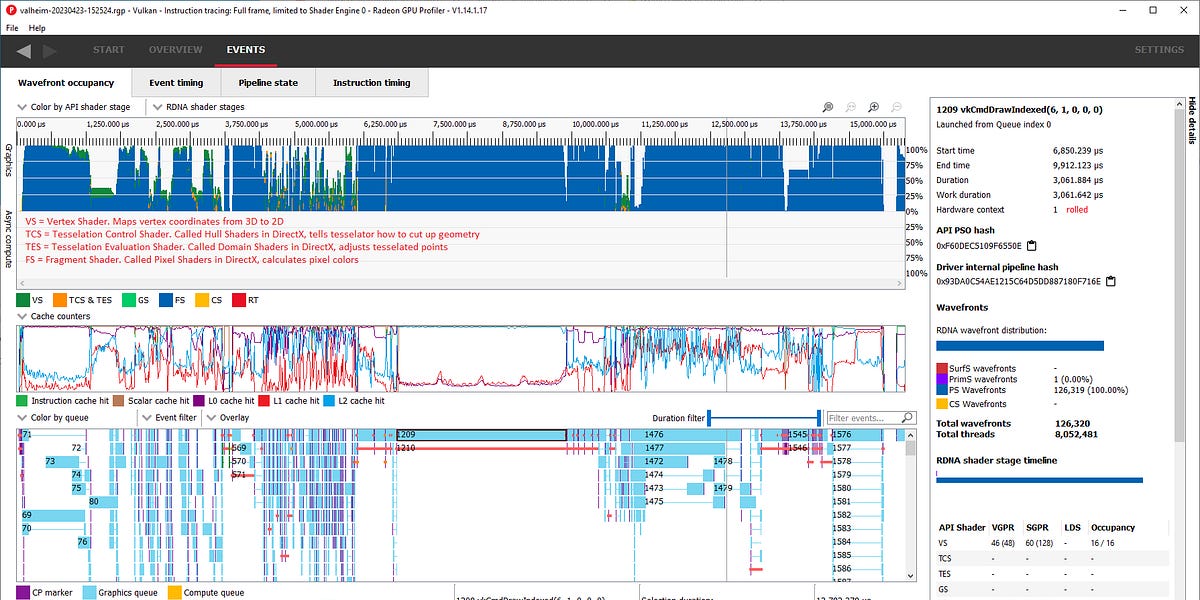
Editor’s Note (6/14/2023): We have a new article that reevaluates the cache latency of Navi 31, so please refer to that article for some new latency data.
2023-06-02 · anysilicon.com
Floorplanning plays a crucial role in the physical design of an SoC and lays the foundation for an efficient and high-performance ASIC layout. In this article, we will discuss ten essential floorplanning commandments that physical design engineers can follow to ensure a…
2023-04-27 · anandtech.com
2023-04-25 · allaboutcircuits.com

New memory technologies have emerged to push the boundaries of conventional computer storage.
2023-04-05 · bits-chips.nl
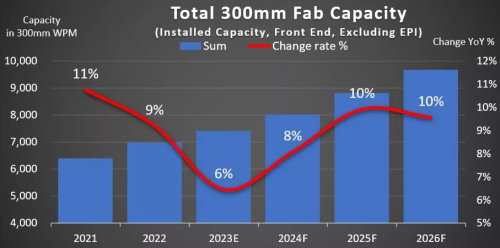
After dipping this year, the growth of 300mm semiconductor manufacturing capacity is set to gain momentum.
2023-04-05 · nextplatform.com
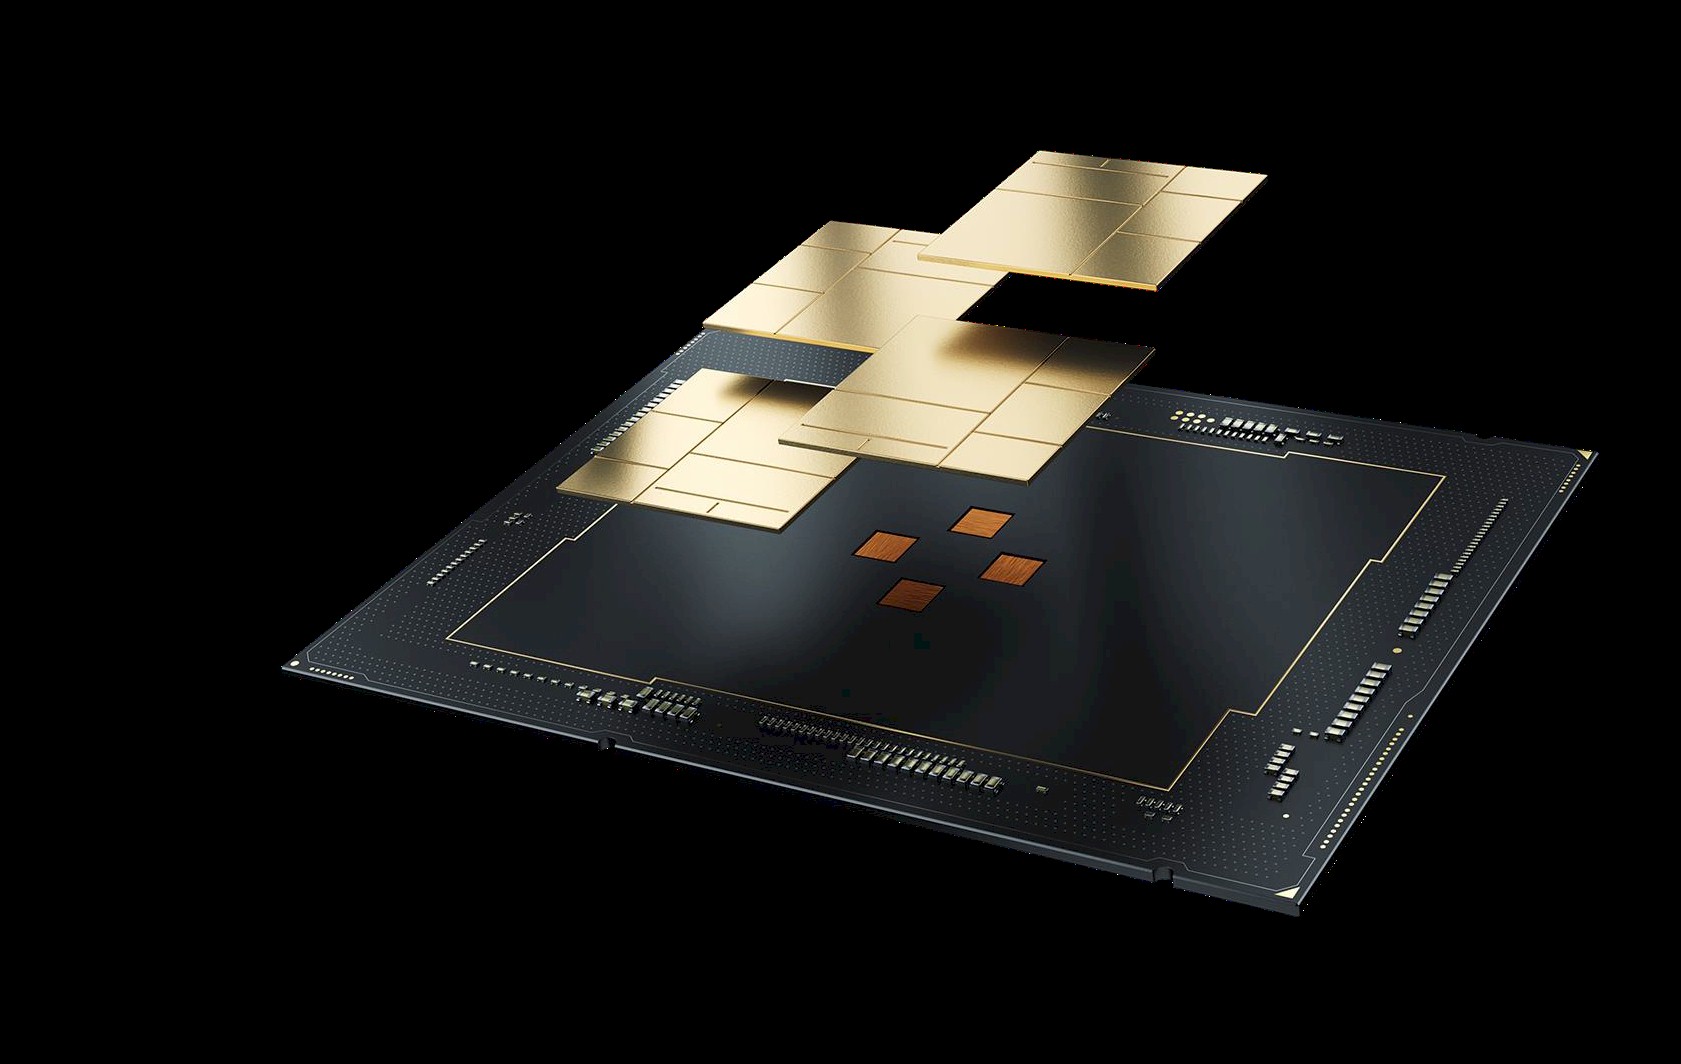
Sponsored Feature: Training an AI model takes an enormous amount of compute capacity coupled with high bandwidth memory. Because the model training can be
2023-03-16 · blocksandfiles.com
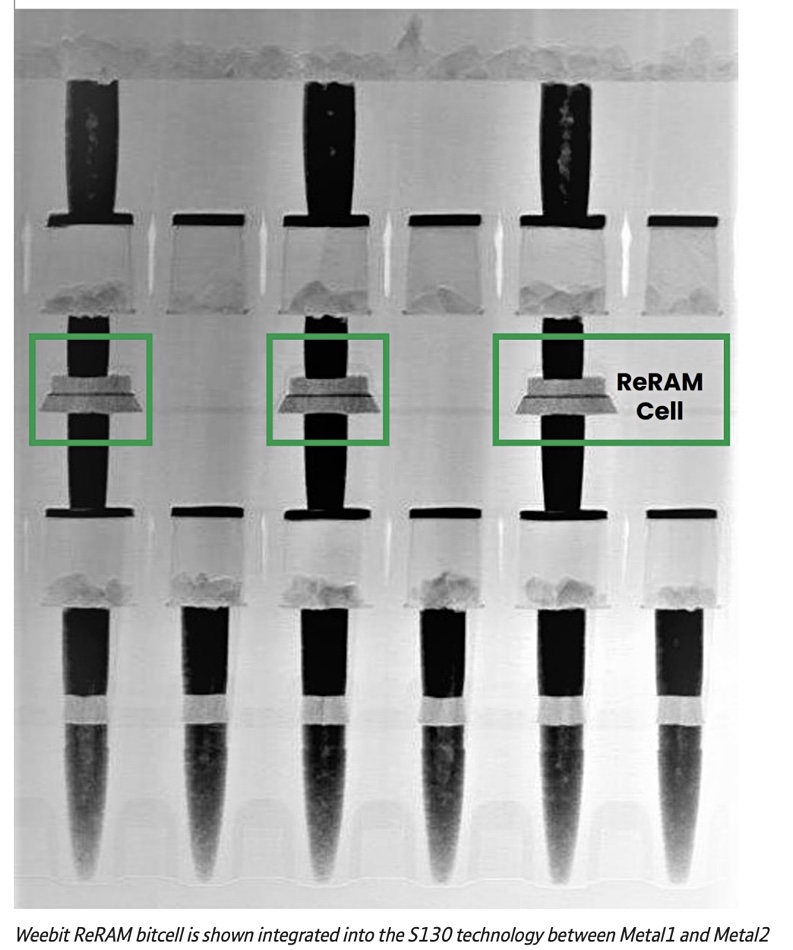
ReRAM startup Intrinsic Semiconductor Technologies has raised $9.73 million to expand its engineering team and bring its product to market.
2023-01-22 · anysilicon.com
Security IP cores are blocks that provide security features for integrated circuits (ICs) and systems-on-chips (SoCs). It includes encryption, decryption, authentication, and key management functions that protect against unauthorized access or hacking. The IP core can be…
2023-01-14 · tomshardware.com
Industry sources say TSMC is considering lowering 3nm prices to stimulate interest from chip designers