arxiv
71 bookmarks · page 1 of 2
2026-09-26 · arxiv.org

Complementary FETs (CFETs) extend nanosheet FET (NSFET) scaling by vertically stacking n- and p-type gate-all-around (GAA) devices, thereby shrinking standard-cell area. The performance gain, however, cannot be assessed from device metrics alone, as CFET layouts also introduce…
Note: Summary: This arXiv paper compares two next-generation chip technologies — A7 CFET and A10 NSFET — using a physics-based evaluation flow spanning from cell parasitics up to full-chip reliability. Approach: CFETs stack n- and p-type devices vertically to shrink cell area, but add extra cell-level resistance and capacitance. The authors built a flow linking calibrated device models, standard-cell…
2026-08-04 · arxiv.org
Large language models (LLMs) have become the default tool for a remarkable range of tasks, yet they have had conspicuously little success at one of the most common machine learning workloads: predictive analytics over tabular data. This gap is the founding premise of the…
2026-08-01 · arxiv.org
DRAM read disturbance, like RowHammer and RowPress, is a critical robustness issue where accessing DRAM can cause unintended bitflips in other unaccessed DRAM locations. DRAM read disturbance bitflips significantly impact the safe, secure, and reliable operation of DRAM-based…
2026-06-23 · arxiv.org
We expose a surprising failure of generalization in auto-regressive large language models (LLMs). If a model is trained on a sentence of the form "A is B", it will not automatically generalize to the reverse direction "B is A". This is the Reversal Curse. For instance, if a…
2026-06-08 · magazine.sebastianraschka.com
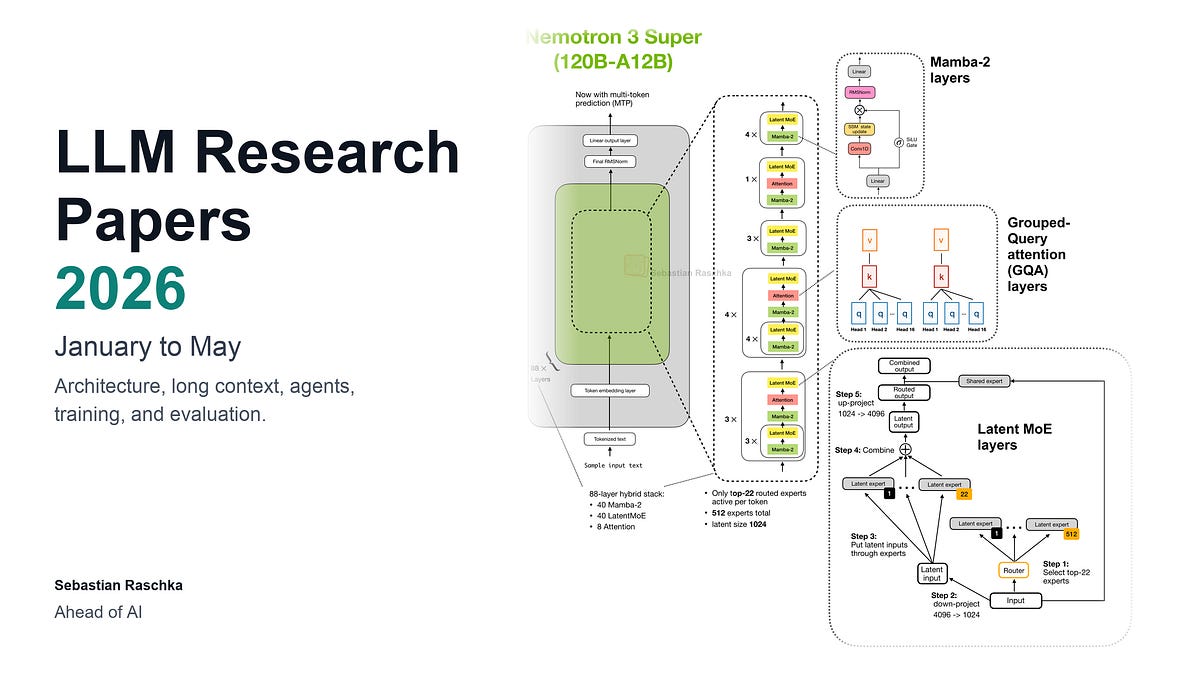
A January-May 2026 list of notable LLM research papers, covering new models, training methods, agents, reasoning, and efficiency improvements.
2026-04-27 · eli.voxos.ai

Paste any research paper and understand it at your level. From picture-book simple to college-level analysis, every section adapts to you.
2026-04-27 · marktechpost.com
2026-01-02 · magazine.sebastianraschka.com
In June, I shared a bonus article with my curated and bookmarked research paper lists to the paid subscribers who make this Substack possible.
2025-12-31 · sebastianraschka.com

A curated list of LLM research papers from July–December 2025, organized by reasoning models, inference-time scaling, architectures, training efficiency, and...
Reasoning
Reinforcement Learning
2025-10-16 · arxiv.org
Multisets are sets that allow repetition of elements. As such, multisets pave the way to a number of interesting possibilities of theoretical and applied nature. In the present work, after revising the main aspects of traditional sets, we introduce some of the main concepts and…
Multisets are sets that allow repetition of elements.
generalization to take into account vectors and matrices
2025-10-04 · arxiv.org
Compute-in-SRAM architectures offer a promising approach to achieving higher performance and energy efficiency across a range of data-intensive applications. However, prior evaluations have largely relied on simulators or small prototypes, limiting the understanding of their…
2025-09-08 · arxiv.org
The last decade has witnessed an experimental revolution in data science and machine learning, epitomised by deep learning methods. Indeed, many high-dimensional learning tasks previously thought to be beyond reach -- such as computer vision, playing Go, or protein folding…
2025-09-05 · arxiv.org
Memory latency, bandwidth, capacity, and energy increasingly limit performance. In this paper, we reconsider proposed system architectures that consist of huge (many-terabyte to petabyte scale) memories shared among large numbers of CPUs. We argue two practical engineering…
2025-08-11 · arxiv.org
A100
67.77 million GPU device-hours across 10,693 GPUs.
2025-07-28 · arxiv.org
Reasoning, the process of devising and executing complex goal-oriented action sequences, remains a critical challenge in AI. Current large language models (LLMs) primarily employ Chain-of-Thought (CoT) techniques, which suffer from brittle task decomposition, extensive data…
2025-07-19 · sebastianraschka.com

The latest in LLM research with a hand-curated, topic-organized list of over 200 research papers from 2025.
2025-04-17 · arxiv.org
2025-01-29 · freakonometrics.hypotheses.org

Our paper, Beyond Human Intervention: Algorithmic Collusion through Multi-Agent Learning Strategies, with Suzie Grondin and Philipp Ratz is now available online Collusion in market pricing is a concept associated with human actions to raise market prices through artificially…
2025-01-23 · sebastianraschka.com
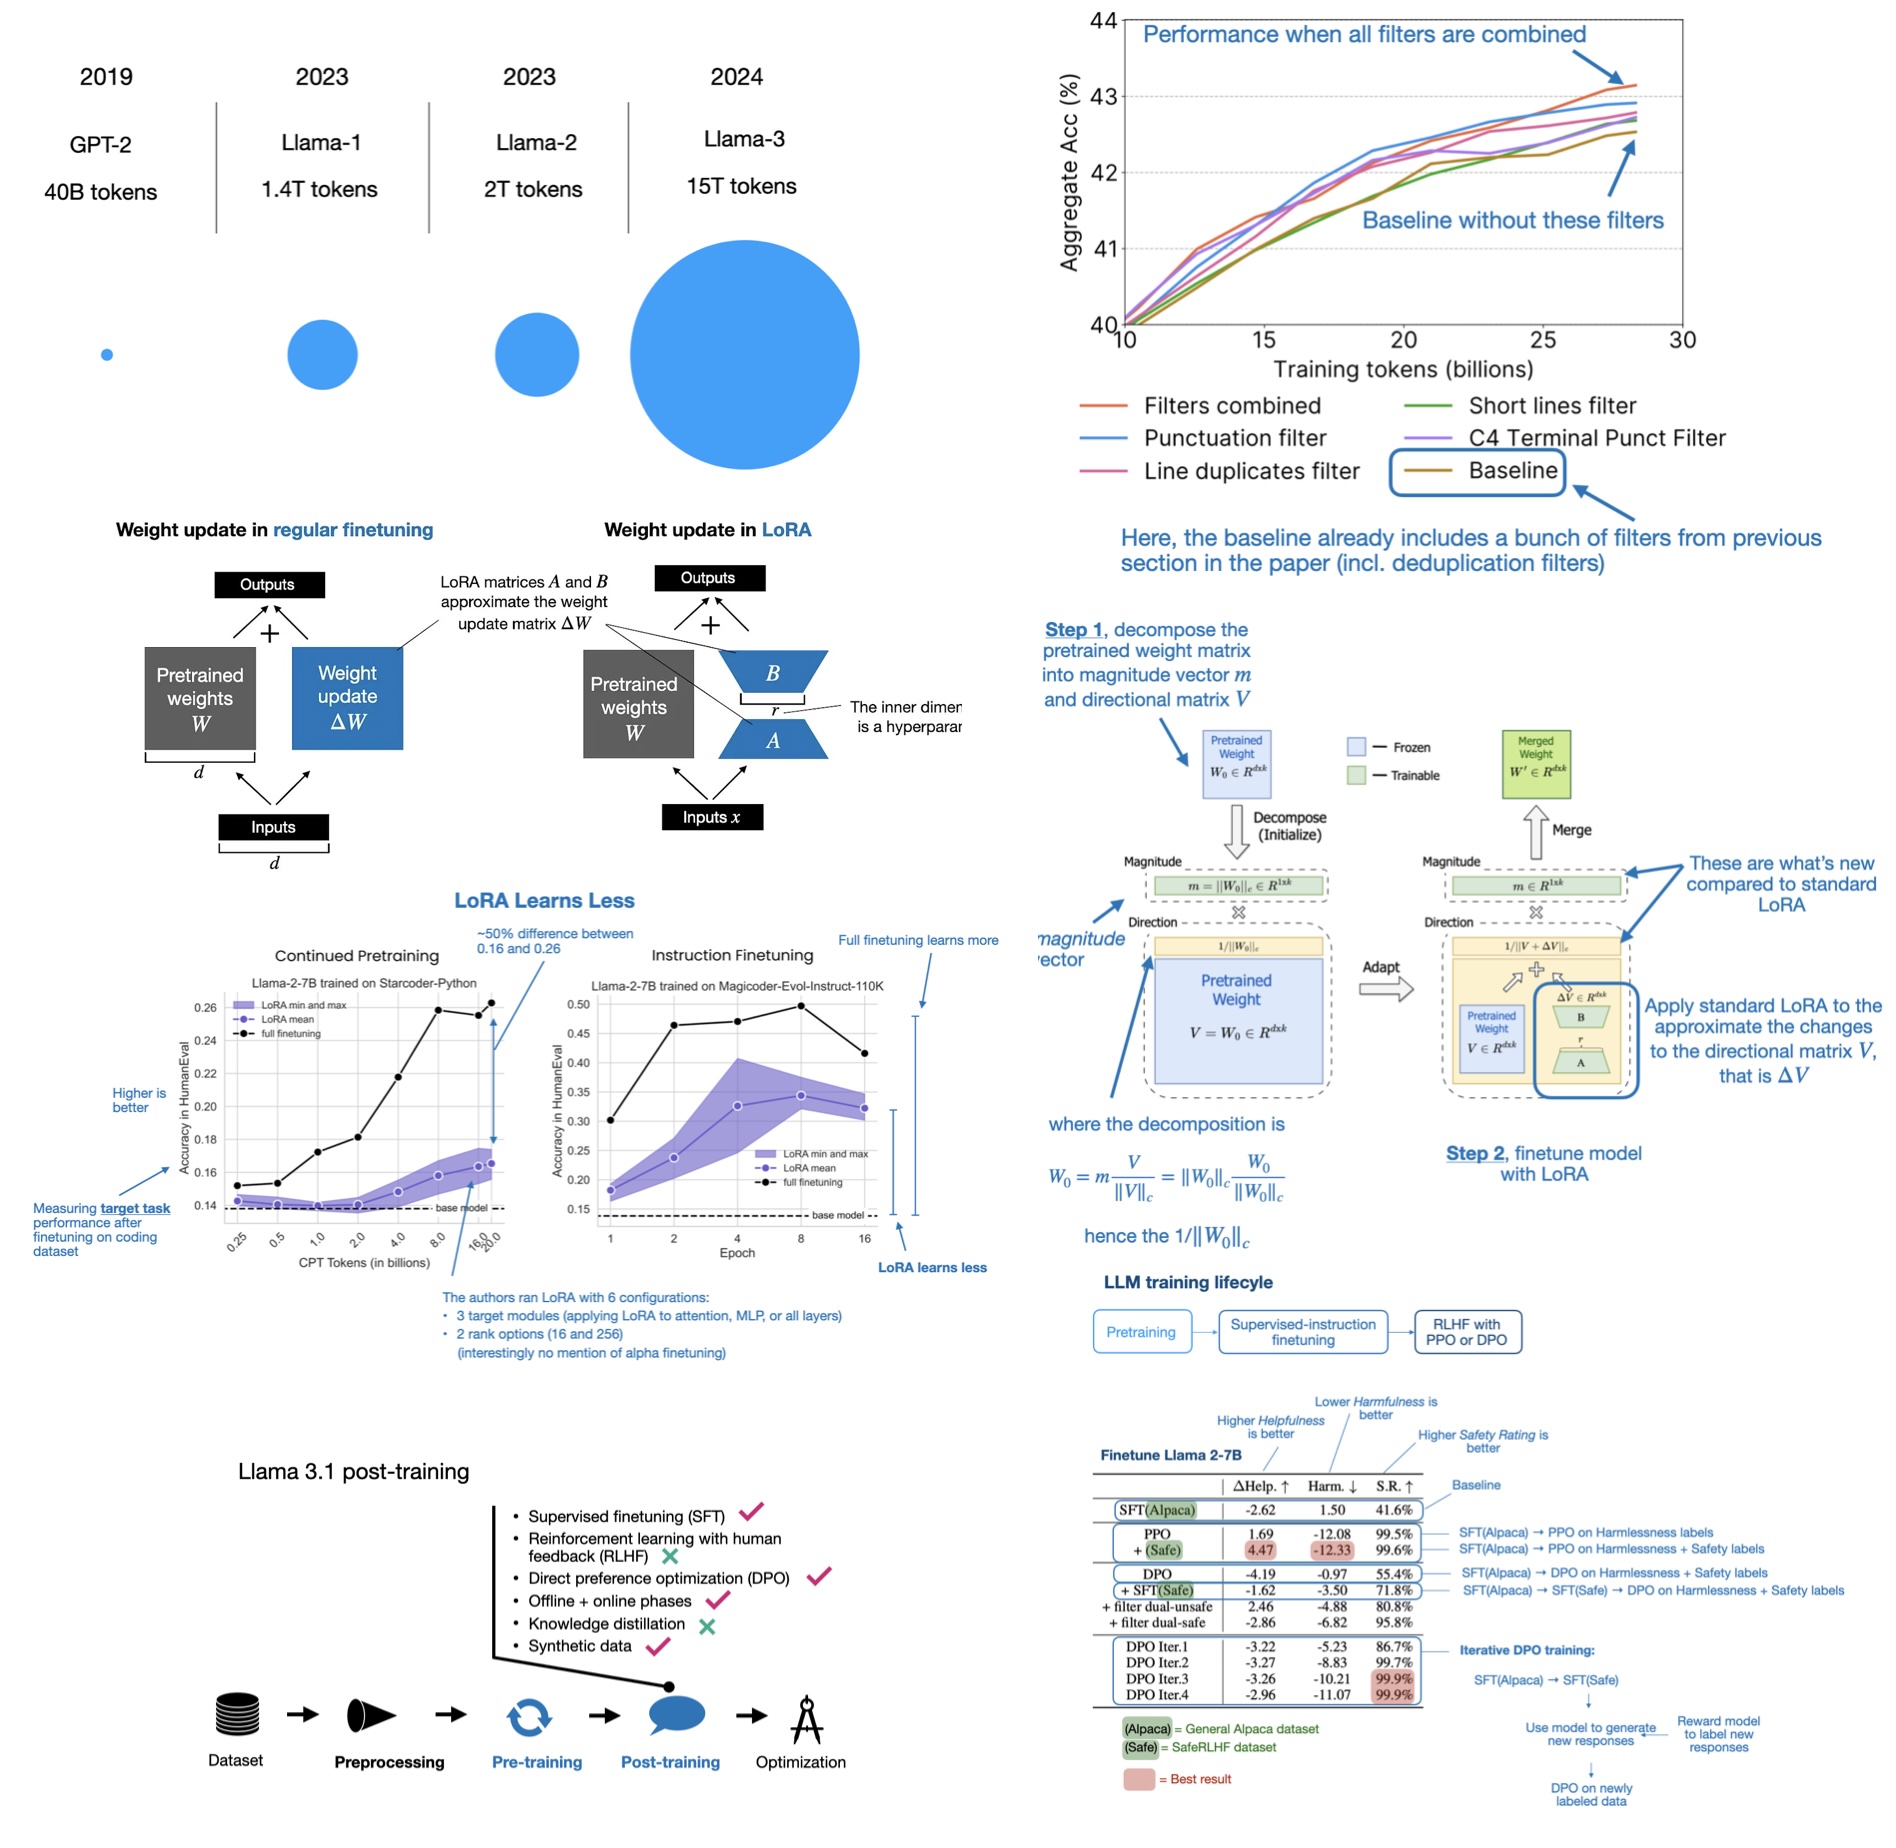
This article covers 12 influential AI research papers of 2024, ranging from mixture-of-experts models to new LLM scaling laws for precision..
★ 2025-01-14 · latent.space

We picked 50 paper/models/blogs across 10 fields in AI Eng: LLMs, Benchmarks, Prompting, RAG, Agents, CodeGen, Vision, Voice, Diffusion, Finetuning. If you're starting from scratch, start here.
Note: gist: https://gist.github.com/bjpcjp/117ecf144c062c3c933f2690e7ece5c2
2025-01-12 · open.substack.com
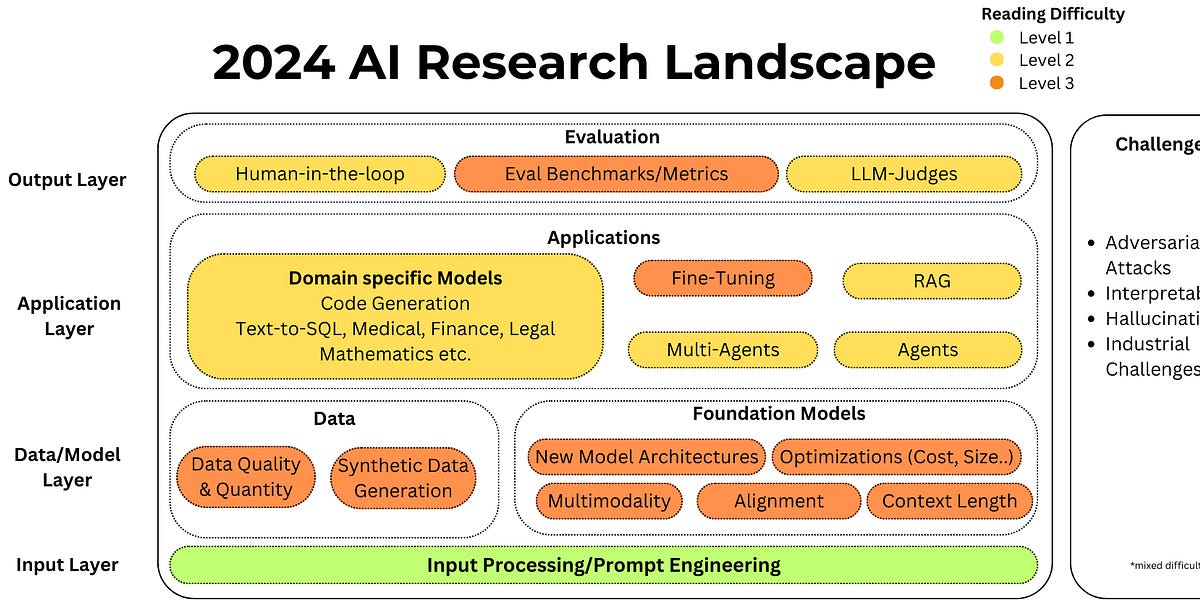
A comprehensive list of some of the most impactful generative papers from last year
2025-01-07 · apolloresearch.ai

A long reading list of evals papers with recommendations and comments by the evals team.
2024-12-22 · magazine.sebastianraschka.com

A curated list of interesting LLM-related research papers from 2024, shared for those looking for something to read over the holidays.
★ 2024-11-26 · github.com

Notes from the Latent Space paper club. Follow along or start your own! - eugeneyan/llm-paper-notes
2024-11-24 · open.substack.com
Your ultimate Paper Club Starter Kit, from your friends at the Latent Space Paper Club, where we have now read 100 papers. Also: Announcing Latent Space Paper Club LIVE! at Neurips 2024! Join us!
2024-11-11 · zeta-alpha.com
9 October 2024, Mathias Parisot, Jakub Zavrel.Even in the red hot global race for AI dominance, you publish and you perish, unless your peers pick up your work, build further on it, and you manage to drive real progress in the field. And of course, we are all very curious who is…
★ 2024-10-21 · aman.ai
Aman's AI Journal | Course notes and learning material for Artificial Intelligence and Deep Learning Stanford classes.
2024-10-19 · tensorlabbet.com
Note: CNNs (5 items) RNNs (10 items) Transformers (3 items) Info theory (5 items) Other (4 items)
2024-06-11 · arxiv.org
The linear representation hypothesis is the informal idea that semantic concepts are encoded as linear directions in the representation spaces of large language models (LLMs). Previous work has...
2024-05-11 · arxiv.org
We introduce a decoder-decoder architecture, YOCO, for large language models, which only caches key-value pairs once. It consists of two components, i.e., a cross-decoder stacked upon a...
2024-05-08 · arxiv.org
Large language models such as GPT and Llama are trained with a next-token prediction loss. In this work, we suggest that training language models to predict multiple future tokens at once results...
2024-04-30 · d.repec.org
2024-04-29 · d.repec.org
2024-04-29 · d.repec.org
2024-04-23 · d.repec.org
2024-04-23 · d.repec.org
2024-04-16 · arxiv.org
In-Memory Computing (IMC) introduces a new paradigm of computation that offers high efficiency in terms of latency and power consumption for AI accelerators. However, the non-idealities and...
2024-04-15 · magazine.sebastianraschka.com
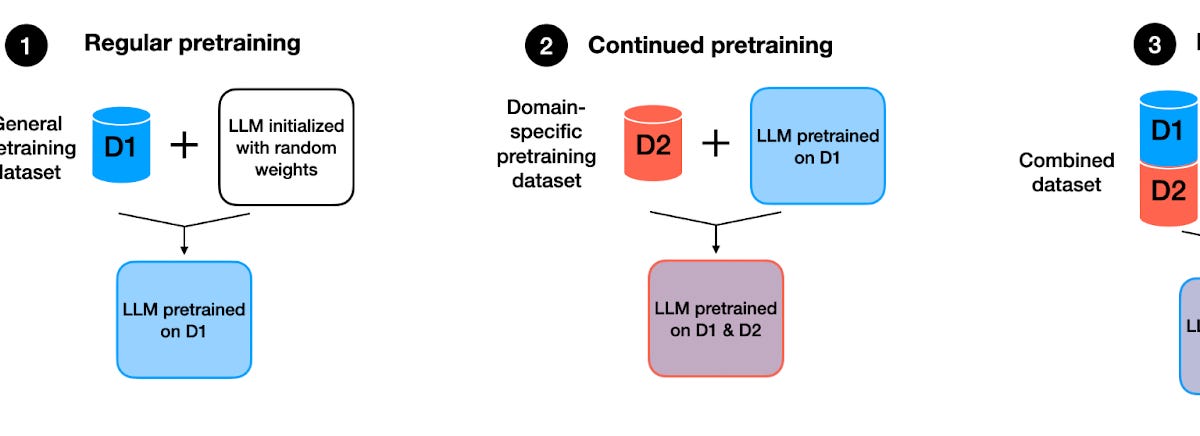
Discussing AI Research Papers in March 2024
2024-01-07 · magazine.sebastianraschka.com
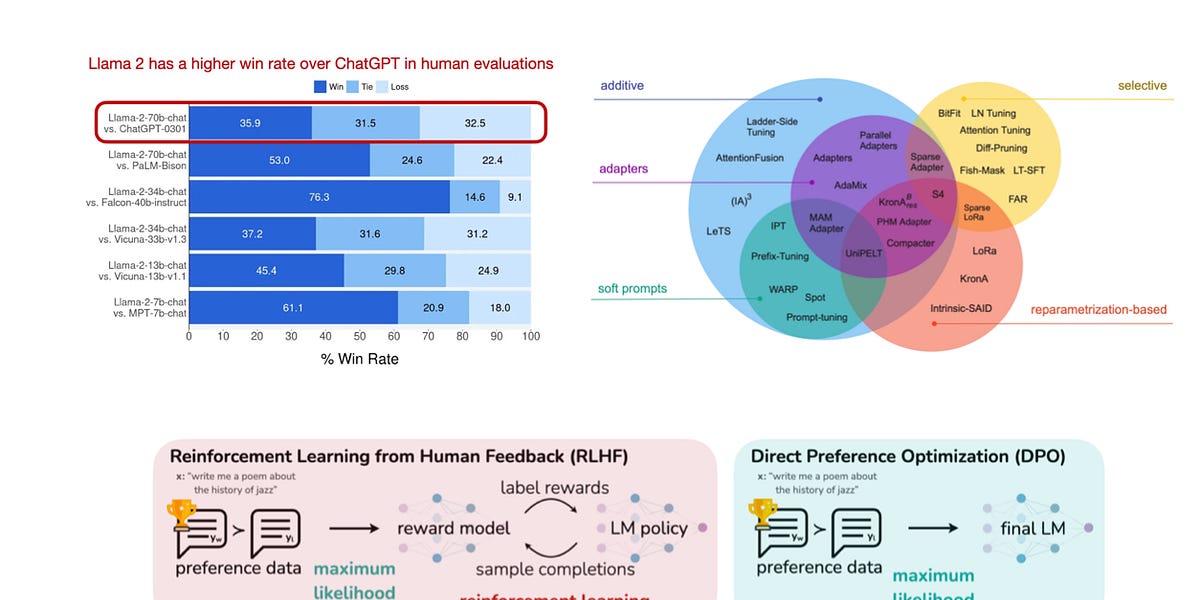
This year has felt distinctly different. I've been working in, on, and with machine learning and AI for over a decade, yet I can't recall a time when these fields were as popular and rapidly evolving as they have been this year. To conclude an eventful 2023 in machine learning…
2023-10-05 · arxiv.org
In the past few years we have seen the meteoric appearance of dozens of foundation models of the Transformer family, all of which have memorable and sometimes funny, but not self-explanatory,...
2023-10-03 · arxiv.org
2023-07-22 · d.repec.org
2023-05-05 · arxiv.org
Deploying large language models (LLMs) is challenging because they are memory inefficient and compute-intensive for practical applications. In reaction, researchers train smaller task-specific...
2023-05-05 · arxiv.org
We show for the first time that large-scale generative pretrained transformer (GPT) family models can be pruned to at least 50% sparsity in one-shot, without any retraining, at minimal loss of...
2023-04-25 · arxiv.org
Self-supervised learning, dubbed the dark matter of intelligence, is a promising path to advance machine learning. Yet, much like cooking, training SSL methods is a delicate art with a high...
2023-04-21 · arxiv.org
The widespread public deployment of large language models (LLMs) in recent months has prompted a wave of new attention and engagement from advocates, policymakers, and scholars from many fields....
2023-04-15 · arxiv.org
Chain-of-Thought (CoT) prompting can effectively elicit complex multi-step reasoning from Large Language Models~(LLMs). For example, by simply adding CoT instruction ``Let's think step-by-step''...
2023-04-14 · arxiv.org
Language is essentially a complex, intricate system of human expressions governed by grammatical rules. It poses a significant challenge to develop capable AI algorithms for comprehending and...
2023-03-31 · kdnuggets.com
These curated papers would step up your machine-learning knowledge.
2023-03-20 · zeta-alpha.com

Who Is publishing the most Impactful AI research right now? With the breakneck pace of innovation in AI, it is crucial to pick up some signal as soon as possible. No one has the time to read everything, but these 100 papers are sure to bend the road as to where our AI technology…