benchmarks
61 bookmarks · page 1 of 2
2026-09-26 · arxiv.org

Complementary FETs (CFETs) extend nanosheet FET (NSFET) scaling by vertically stacking n- and p-type gate-all-around (GAA) devices, thereby shrinking standard-cell area. The performance gain, however, cannot be assessed from device metrics alone, as CFET layouts also introduce…
Note: Summary: This arXiv paper compares two next-generation chip technologies — A7 CFET and A10 NSFET — using a physics-based evaluation flow spanning from cell parasitics up to full-chip reliability. Approach: CFETs stack n- and p-type devices vertically to shrink cell area, but add extra cell-level resistance and capacitance. The authors built a flow linking calibrated device models, standard-cell…
2026-09-23 · open.substack.com
In gory detail: reliability, performance, support, pricing—and, of course, security—in our most thorough analysis of GPU cloud providers globally.
2026-08-24 · github.com

A curriculum for learning about gpu performance engineering, from scratch to what the frontier AI labs do - wafer-ai/gpu-perf-engineering-resources
2026-08-22 · newsletter.semianalysis.com
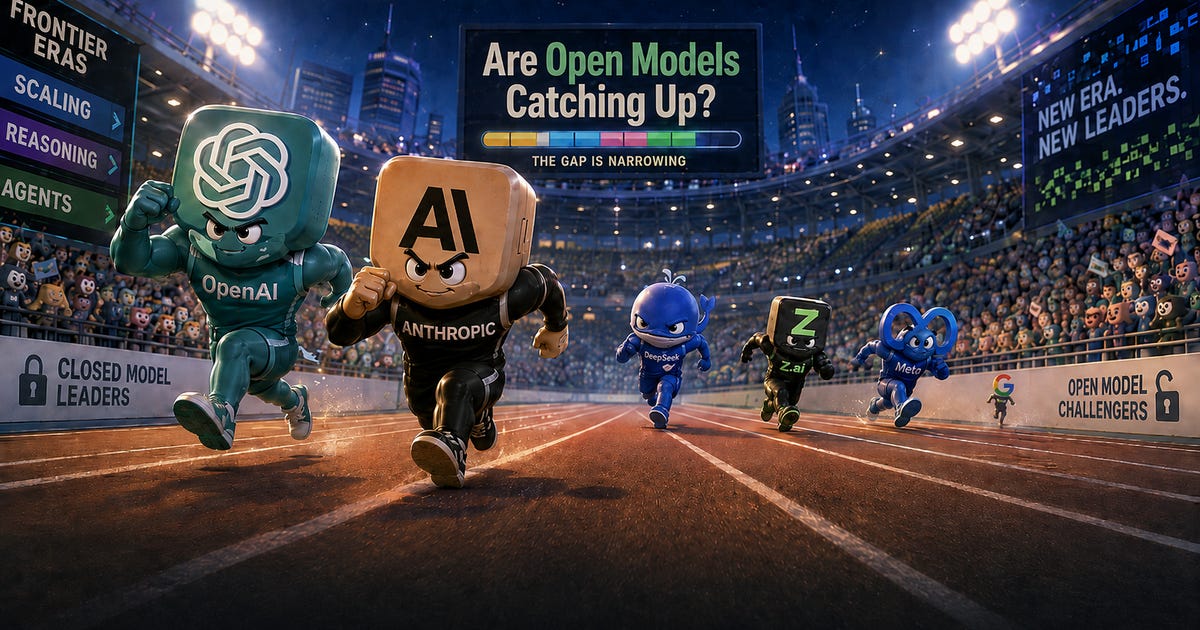
Comparing open vs. closed models across the eras of frontier models
2026-08-21 · catalystneuro.com
A given level of LLM intelligence costs about a thirtieth of what it did a year ago, and the rate of decline is accelerating. Using Artificial Analysis's measured cost per task, this post traces the falling price of each capability level, explains why cheaper intelligence leads…
A great deal of useful work does not require the smartest model available, but a model that is good enough, applied many thousands of times
At today’s prices a full pass over the corpus costs a little over a hundred dollars with a model whose capability was at the frontier in the spring. At the prices of this past March, the same pass with the same level of capability would have cost several thousand dollars, and a year ago that…
2026-08-19 · github.com

A 2.78-trillion-parameter Kimi K3 running inference on a single CPU in 8.24 GB of RAM. Portable C99: no BLAS, no framework, no GPU. - FareedKhan-dev/kimi-k3-in-c
2026-07-15 · lesswrong.com

How many AI safety papers are at the big ML conferences, what do they study, and who writes them? A comprehensive analysis. > Website: https://ai-saf…
2026-07-13 · systima.ai
We measured what Claude Code and OpenCode spend before reading your prompt, then added instruction files, MCP servers and subagents to the bill.
2026-06-09 · open.substack.com
2026-06-02 · the-decoder.com

According to benchmark platform Artificial Analysis, Nvidia's new Nemotron 3 Ultra is the most capable open AI model from the US to date.
2026-05-22 · link.mail.beehiiv.com
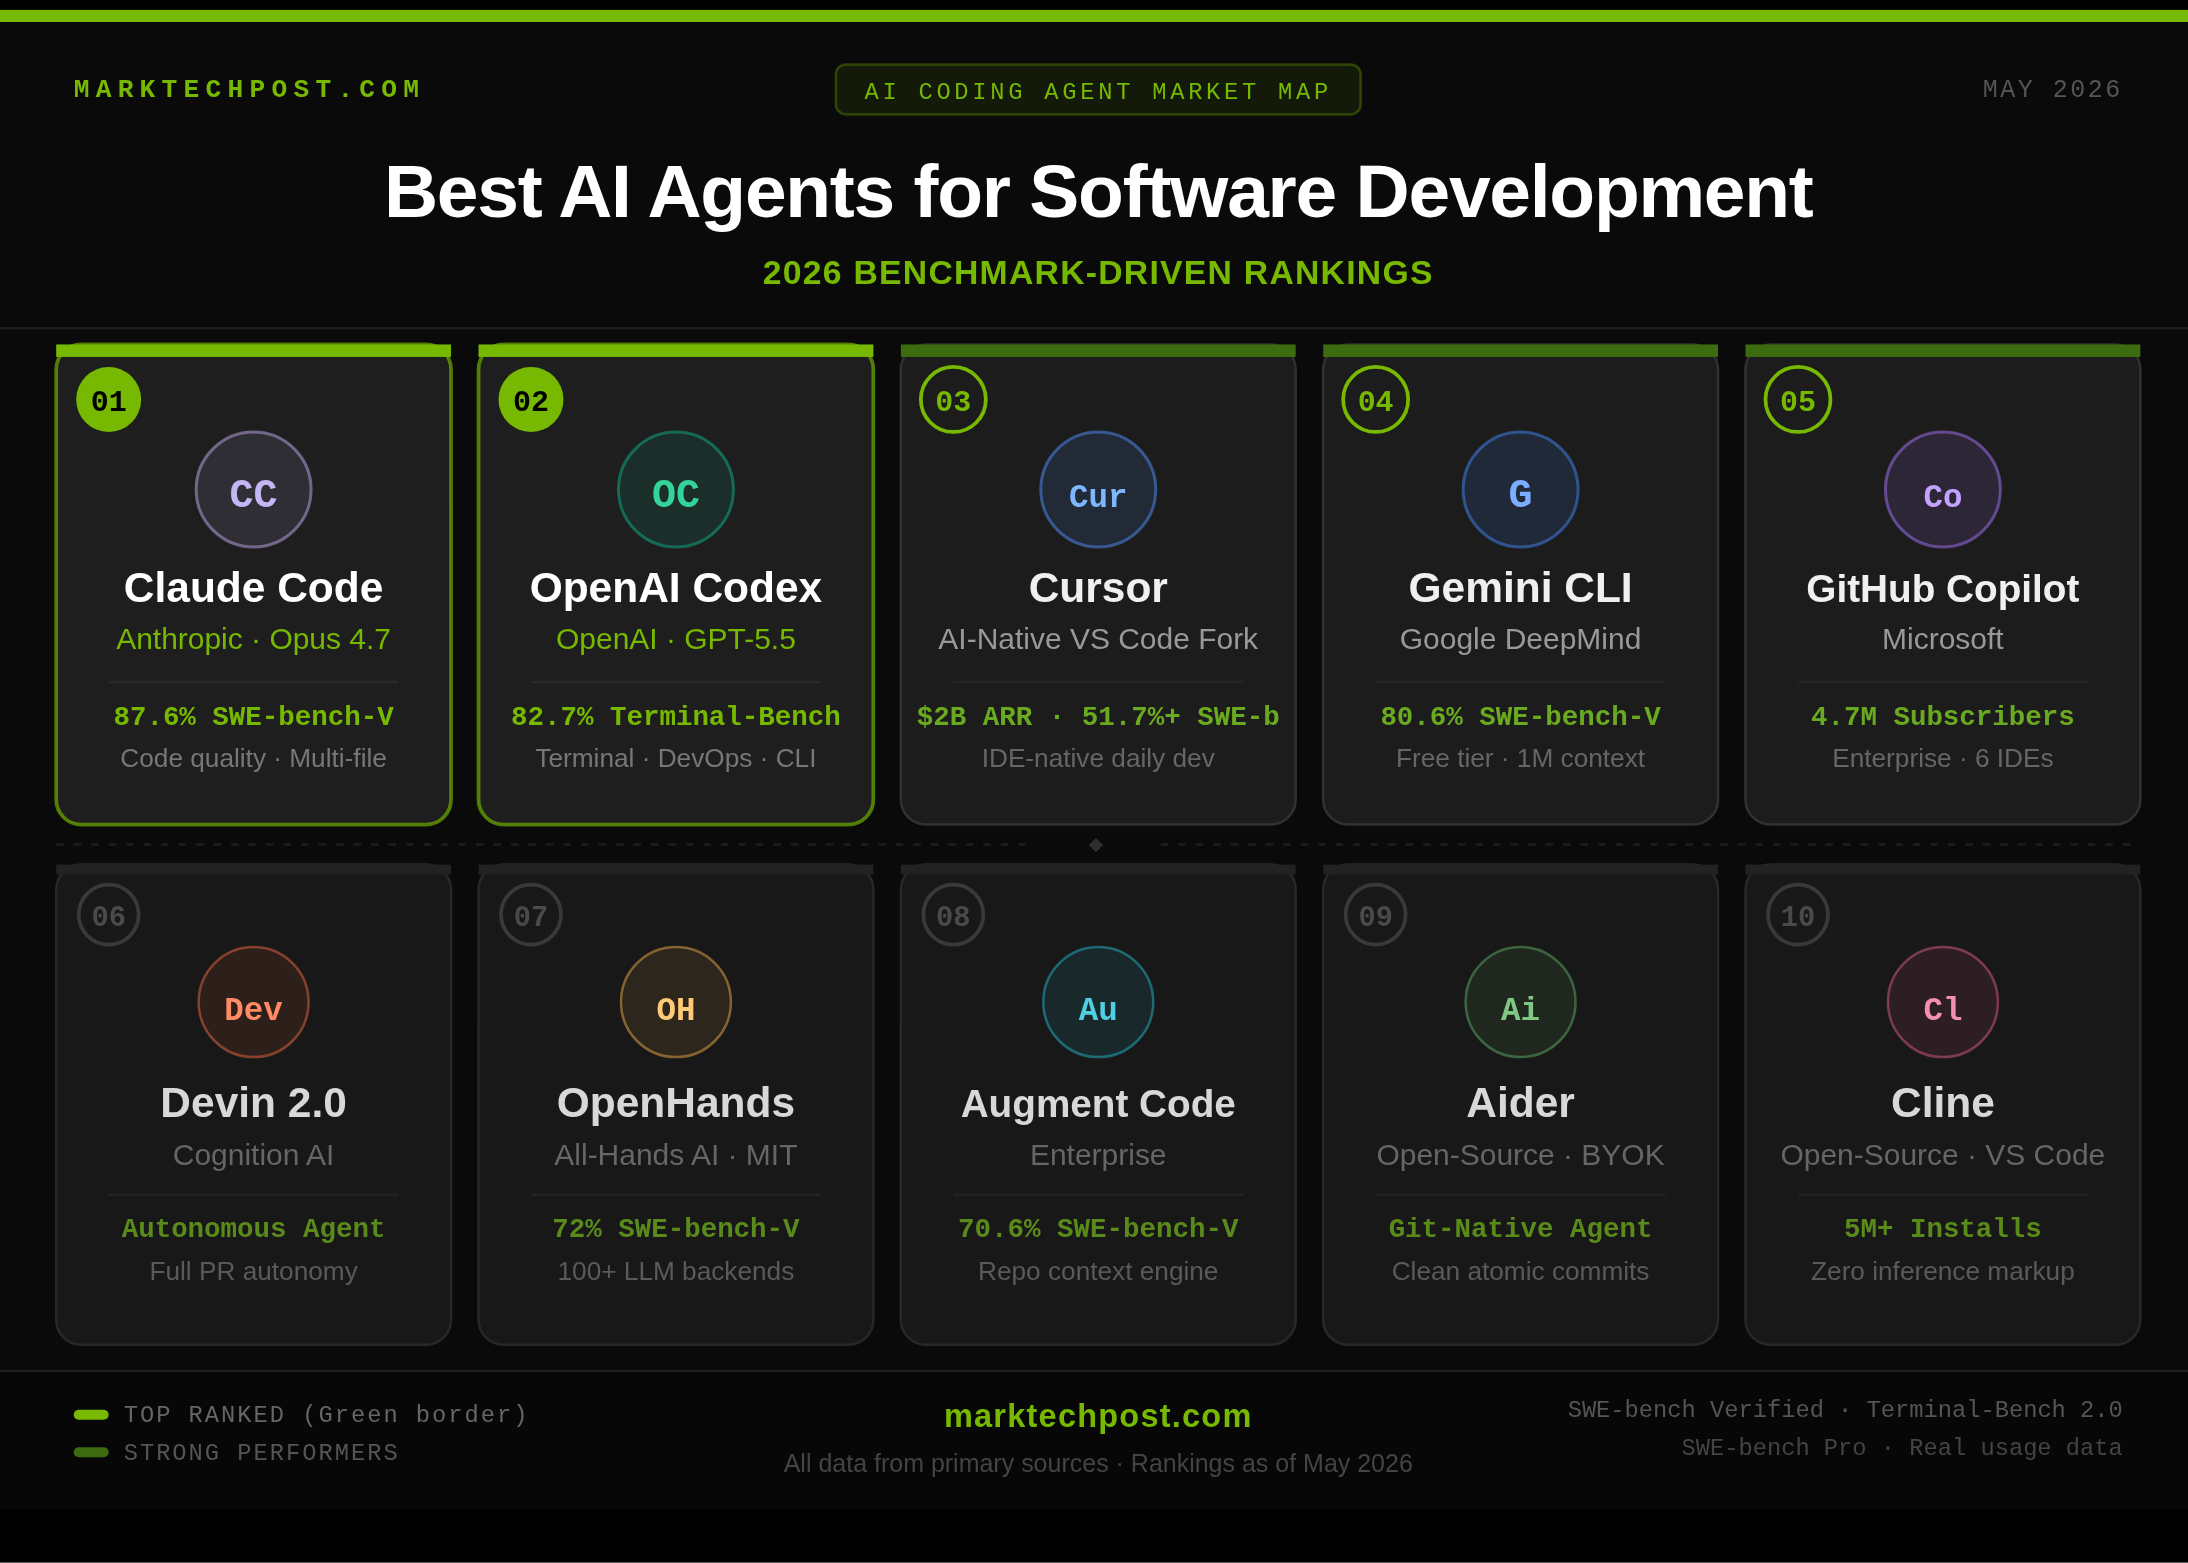
The AI coding agent field in 2026 is more capable, more fragmented, and harder to benchmark than it looks. Claude Code leads on code quality at 87.6% SWE-bench Verified. GPT-5.5 tops Terminal-Bench at 82.7%. But the benchmark OpenAI itself declared contaminated in February 2026…
SWE-bench
stopped reporting SWE-bench Verified
2026-05-22 · marktechpost.com

Alibaba's Qwen3.7-Max is a reasoning agent model with a 1M-token context window, scoring 56.6 on the Artificial Analysis Intelligence Index.
2026-05-20 · open.substack.com
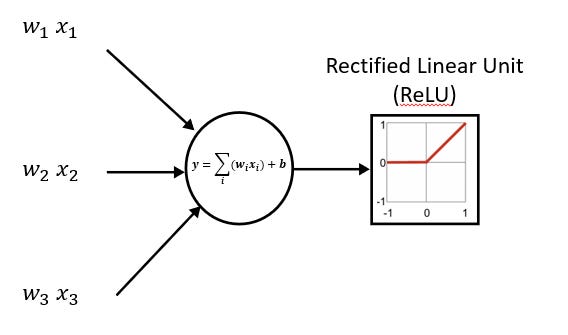
Learning from a classic AI accelerator - Eyeriss
2026-05-15 · marktechpost.com

Note: https://gist.github.com/bjpcjp/c85fa4214c1b59c3aa578a6e8e9d871c
2026-05-14 · venturebeat.com
AI IQ ranks frontier AI models like ChatGPT, Claude and Gemini on the human IQ scale, sparking debate over how artificial intelligence should be measured.
★ 2026-04-25 · newsletter.semianalysis.com
Hands On With GPT 5.5, Opus 4.7, DeepSeek V4, Why Benchmarks Are Bad, and Who’s Going To Win
GPT-5.5 is now materially better
GLM-5.1, Qwen3.6-Plus, Kimi K2.6, Composer 2, and Gemini 3.1 Pro
2026-03-15 · cemrehancavdar.com
Python loses every public benchmark by 21-875x. I took the exact problems people use to dunk on Python and climbed every rung of the optimization ladder -- from CPython version upgrades to Rust. Real numbers, real code, real effort costs.
2026-03-14 · canirun.ai

Detect your hardware and find out which AI models you can run locally. GPU, CPU, and RAM analysis in your browser.
2026-03-08 · devblog.ecuadors.net

2026-02-23 · linkedin.com
2026-02-16 · reuters.com

Alibaba on Monday unveiled a new artificial intelligence model Qwen 3.5 designed to execute complex tasks independently, with big improvements in performance and cost that the Chinese tech giant claims beat major U.S. rival models on several benchmarks.
2026-02-11 · semiengineering.com

A new technical paper titled “Advances in You Only Look Once (YOLO) algorithms for lane and object detection in autonomous vehicles” was published by RMIT University, Kyungpook National University, Deakin University and the RCA Robotics Laboratory, Royal College of Art. Abstract…
2026-02-11 · venturebeat.com
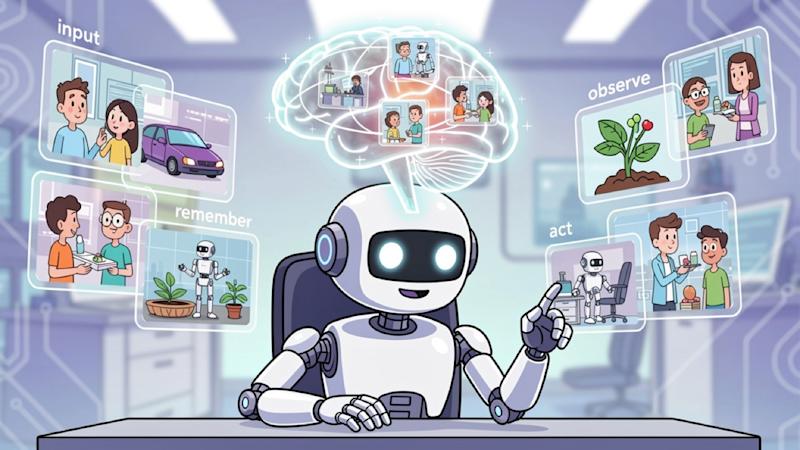
As AI agents move into production, teams are rethinking memory. Mastra’s open-source observational memory shows how stable context can outperform RAG while cutting token costs.
2026-01-02 · magazine.sebastianraschka.com
In June, I shared a bonus article with my curated and bookmarked research paper lists to the paid subscribers who make this Substack possible.
2025-12-31 · sebastianraschka.com

A curated list of LLM research papers from July–December 2025, organized by reasoning models, inference-time scaling, architectures, training efficiency, and...
Reasoning
Reinforcement Learning
2025-12-15 · johnjames.blog
A production-tested take on GraphQL in enterprise systems, why the honeymoon phase fades, and when its complexity outweighs the benefits.
2025-12-11 · venturebeat.com
2025-11-04 · marktechpost.com
Compare the top 7 large language models and systems for coding in 2025. Discover which ones excel for software engineering tasks.
OpenAI GPT-5 / GPT-5-Codex Anthropic Claude 3.5 Sonnet / Claude 4.x Sonnet with Claude Code Google Gemini 2.5 Pro Meta Llama 3.1 405B Instruct DeepSeek-V2.5-1210 (with DeepSeek-V3 as the successor) Alibaba Qwen2.5-Coder-32B-Instruct Mistral Codestral 25.01
Core coding quality: HumanEval, MBPP / MBPP EvalPlus, code generation and repair quality on standard Python tasks. Repo and bug-fix performance: SWE-bench Verified (real GitHub issues), Aider Polyglot (whole-file edits), RepoBench, LiveCodeBench. Context and long-context behavior: Documented…
2025-10-28 · open.substack.com
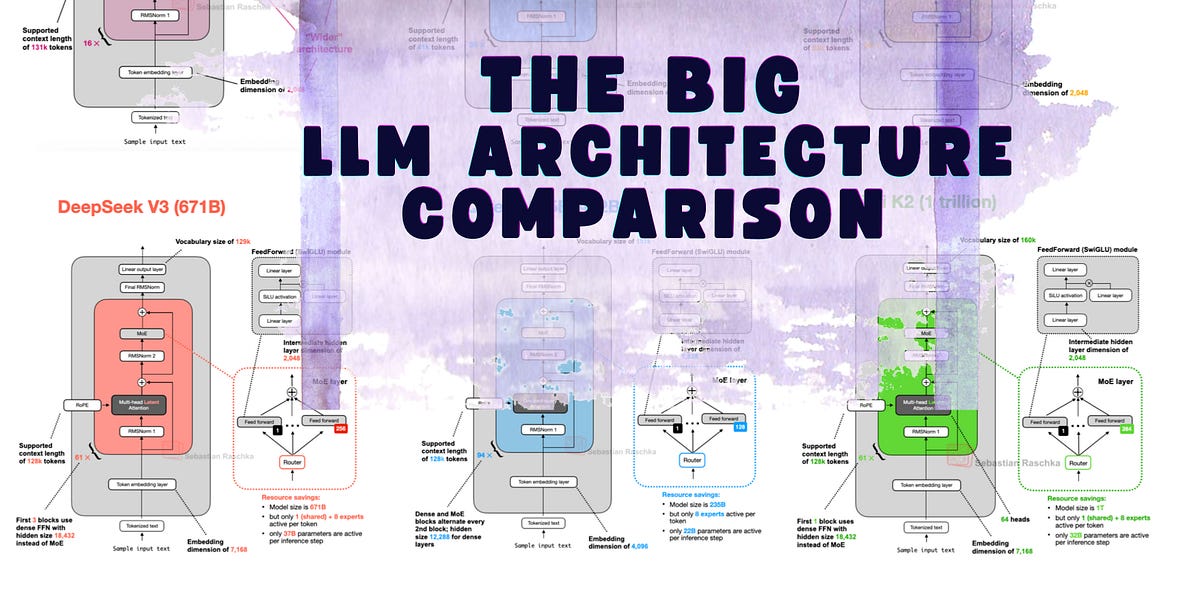
From DeepSeek-V3 to Kimi K2: A Look At Modern LLM Architecture Design
this section, I’ll focus on two key architectural techniques introduced in DeepSeek V3 that improved its computational efficiency and distinguish it from many other LLMs:
Multi-Head Latent Attention (MLA)
2025-10-05 · magazine.sebastianraschka.com
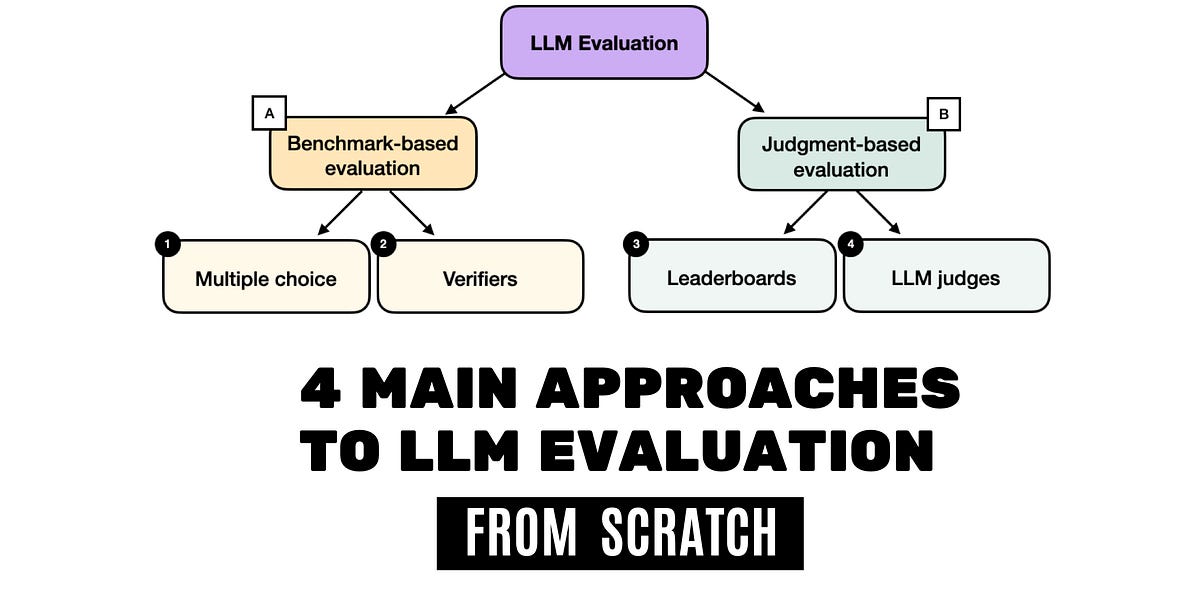
Multiple-Choice Benchmarks, Verifiers, Leaderboards, and LLM Judges with Code Examples
four common ways of evaluating trained LLMs in practice: multiple choice, verifiers, leaderboards, and LLM judges
training loss, perplexity, and rewards, but they are usually used internally during model development.)
2025-08-20 · baymard.com
See the ranked UX performance of the 319 leading ecommerce sites in the US and Europe. The chart summarizes 100,000+ UX performance ratings.
2025-08-14 · artificialanalysis.ai
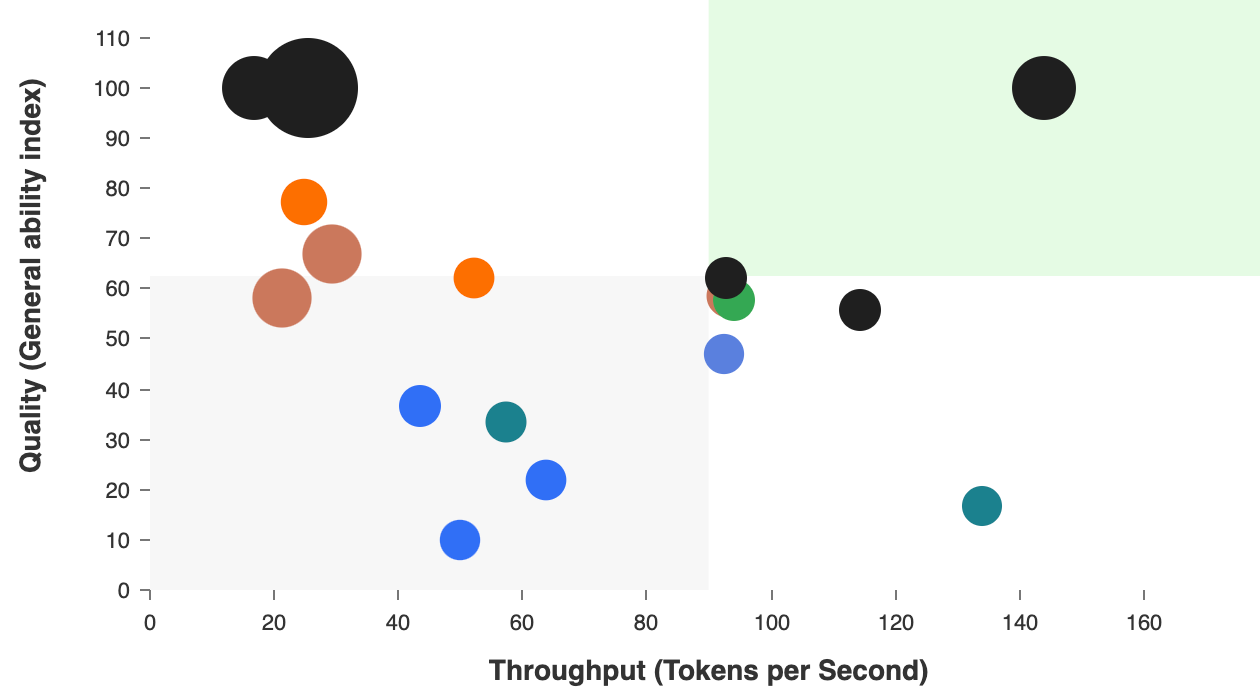
Comparison and analysis of AI models and API hosting providers. Independent benchmarks across key performance metrics including quality, price, output speed & latency.
2025-08-03 · marktechpost.com
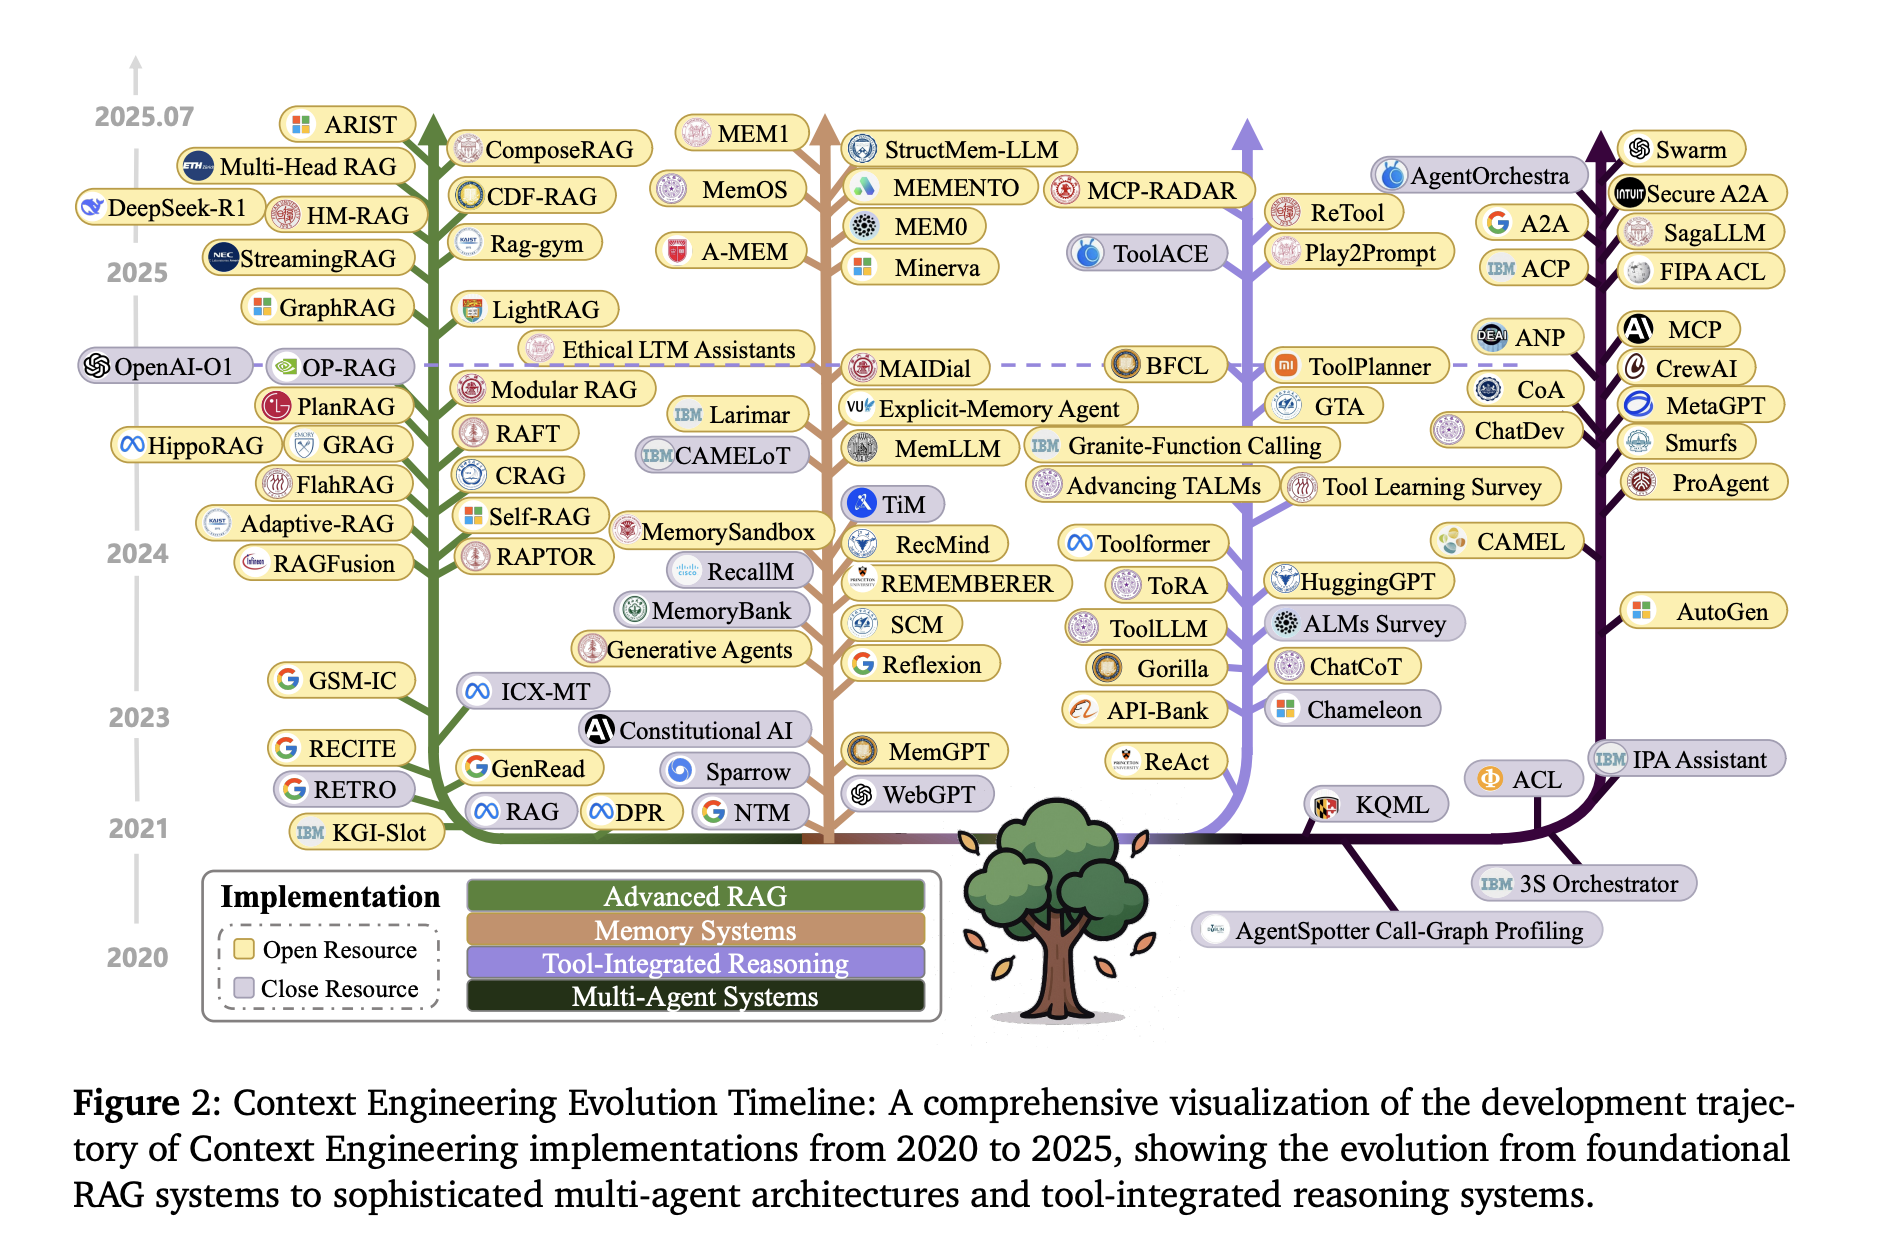
Context engineering for large language models—frameworks, architectures, and strategies to optimize AI reasoning, and scalability
Rather than viewing context as a static string (the premise of prompt engineering),
2025-04-30 · arxiv.org
Measuring progress is fundamental to the advancement of any scientific field. As benchmarks play an increasingly central role, they also grow more susceptible to distortion. Chatbot Arena has emerged as the go-to leaderboard for ranking the most capable AI systems. Yet, in this…
2025-04-26 · git.zib.de
This is the ZIB GitLab instance
2025-04-10 · theatlantic.com

François Chollet has constructed the ultimate test for the bots.
2025-04-07 · techmeme.com

By Matteo Wong / The Atlantic. View the full context on Techmeme.
2025-04-02 · developer.nvidia.com
The past few years have witnessed the rise in popularity of generative AI and large language models (LLMs), as part of a broad AI revolution.
2025-04-02 · dataconomy.com
METEOR Score is a metric used to evaluate the quality of machine translation based on precision, recall, word alignment, and linguistic flexibility.
2025-02-21 · artificialanalysis.ai
Comparison and ranking the performance of over 30 AI models (LLMs) across key metrics including quality, price, performance and speed (output speed - tokens per second & latency - TTFT), context window & others.
2025-02-01 · github.com

Aidan Bench attempts to measure in LLMs. - aidanmclaughlin/AidanBench
2024-07-03 · wccftech.com
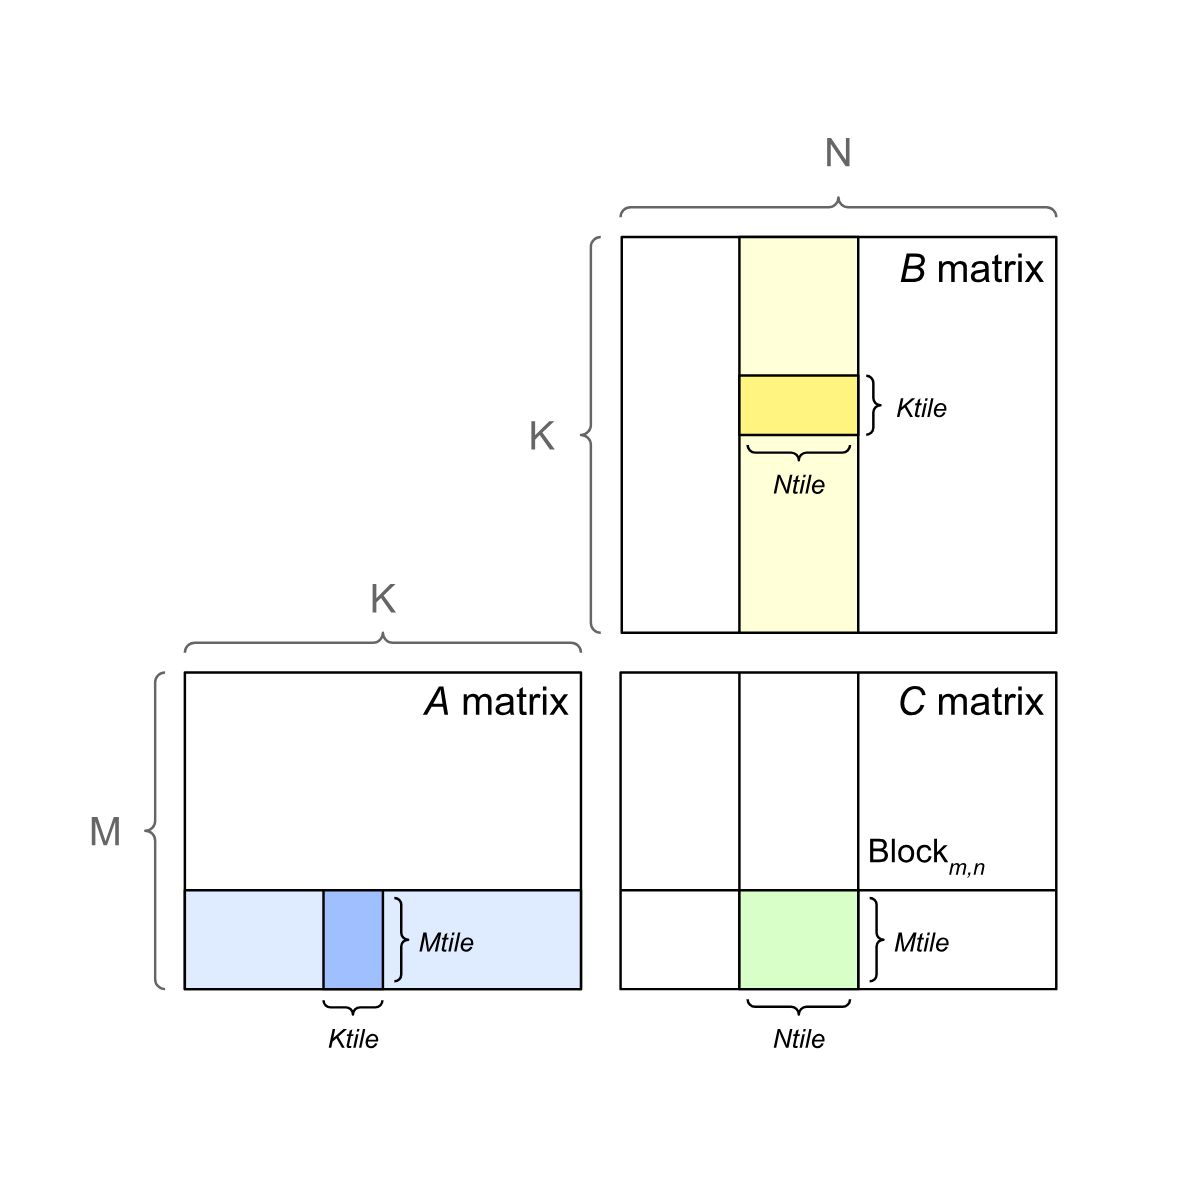
Nscale has tested AMD's flagship Instinct MI300X AI accelerator utilizing the GEMM tuning framework, achieving 7x faster performance.
2024-06-20 · marktechpost.com

Evaluating Large Language Models (LLMs) is a challenging problem in language modeling, as real-world problems are complex and variable. Conventional benchmarks frequently fail to fully represent LLMs' all-encompassing performance. A recent LinkedIn post has emphasized a number…
2024-06-13 · spectrum.ieee.org
GPU maker tops new MLPerf benchmarks on graph neural nets and LLM fine-tuning
2023-09-25 · huggingface.co
Track, rank and evaluate open LLMs and chatbots
2023-09-25 · benchmarks.llmonitor.com
Human-readable benchmarks of 60+ open-source and proprietary LLMs.
2023-07-28 · turingpost.com

Exploring the Development of the 3 Leading Open LLMs and Their Chatbot Derivatives
2023-07-24 · kdnuggets.com
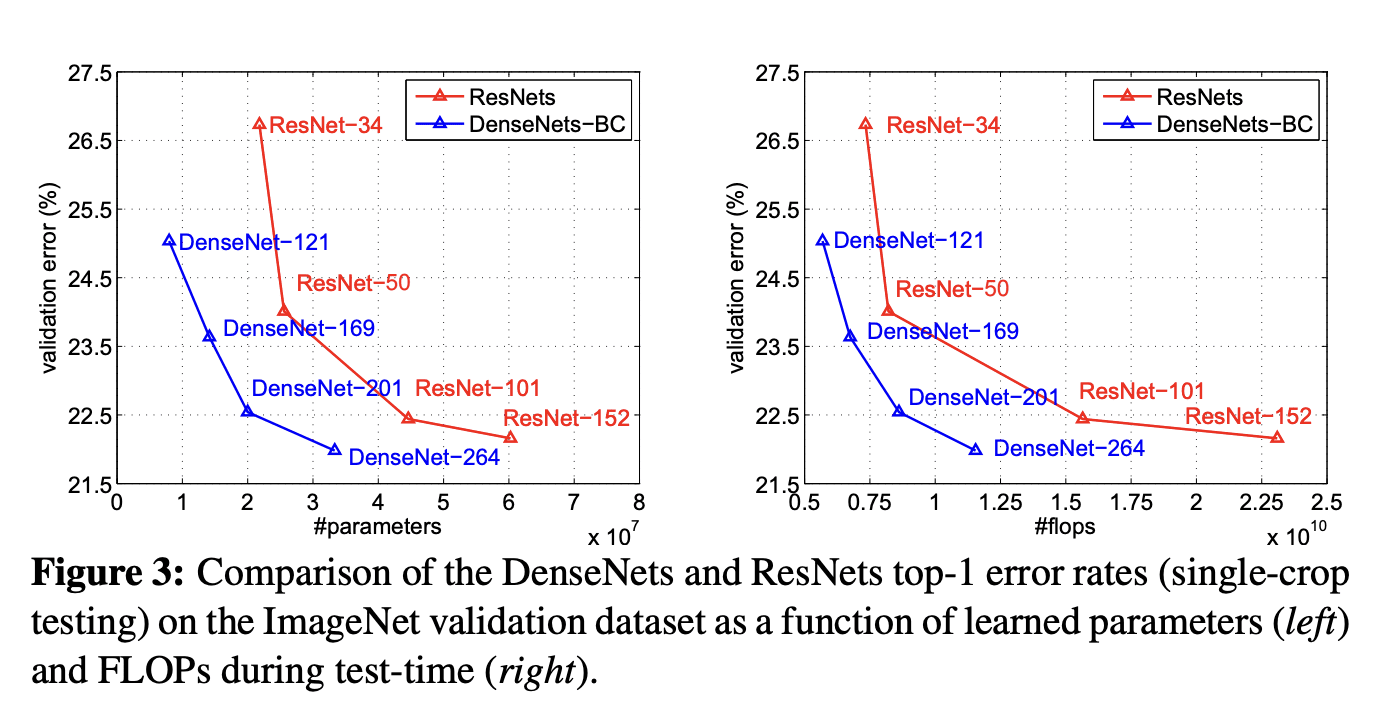
In this article we will learn about its definition, differences and how to calculate FLOPs and MACs using Python packages.
2023-03-19 · hgpu.org
As computing system become more complex, it is becoming harder for programmers to keep their codes optimized as the hardware gets updated. Autotuners try to alleviate this by hiding as many archite…
2022-11-23 · datasciencecentral.com