HiEQ·HOME
一个小小的个人网页
一个小小的个人网页

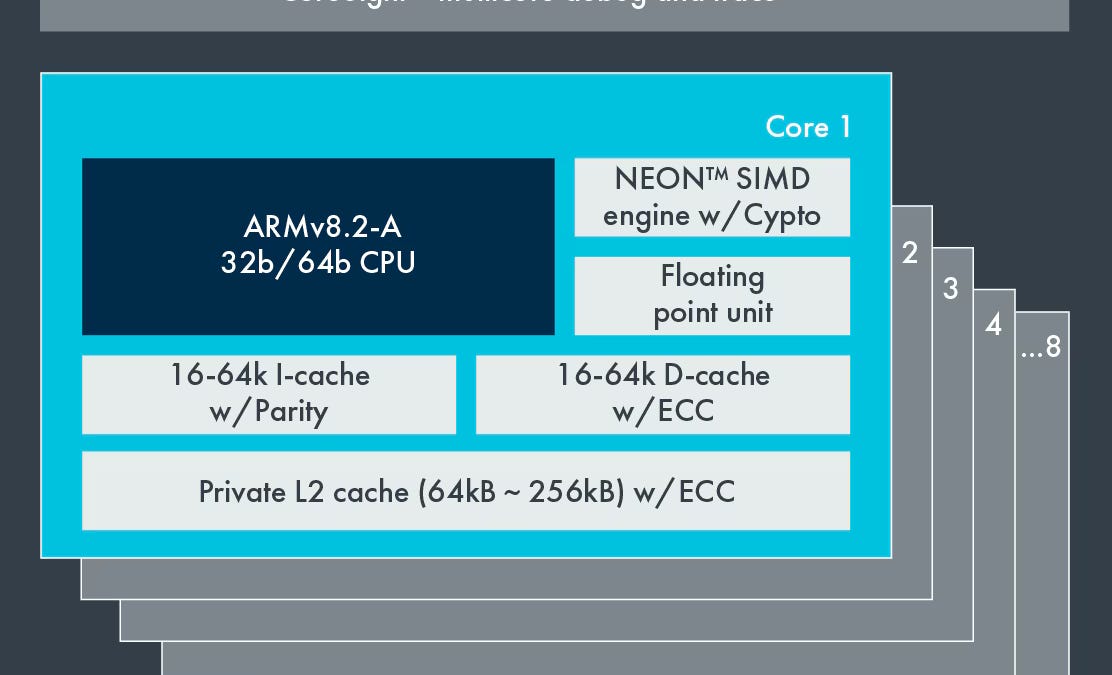
Arm’s 5-series cores are meant for tasks where performance barely matters, but power and area efficiency are top priorities.
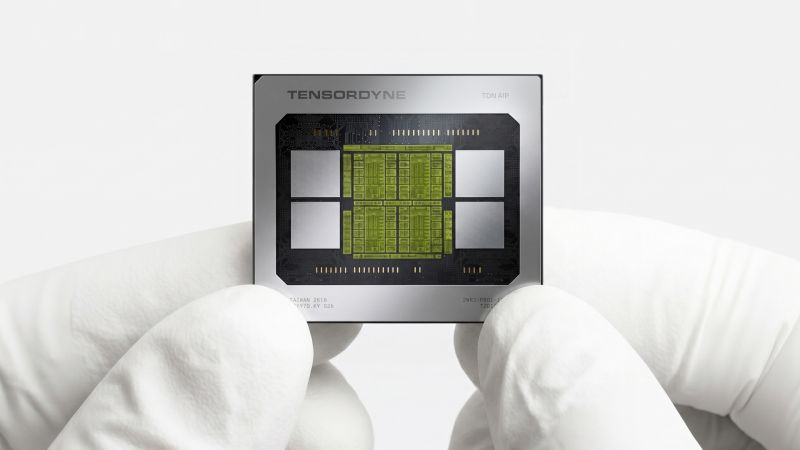
tensordyne just announced their chip specs. their trick is to turn every multiply into an add using logarithms, a trick from 1962 that everyone tried and gave up on. here's the breakdown: the idea is simple. log(a×b) = log(a) + log(b). store your numbers as logs and every…
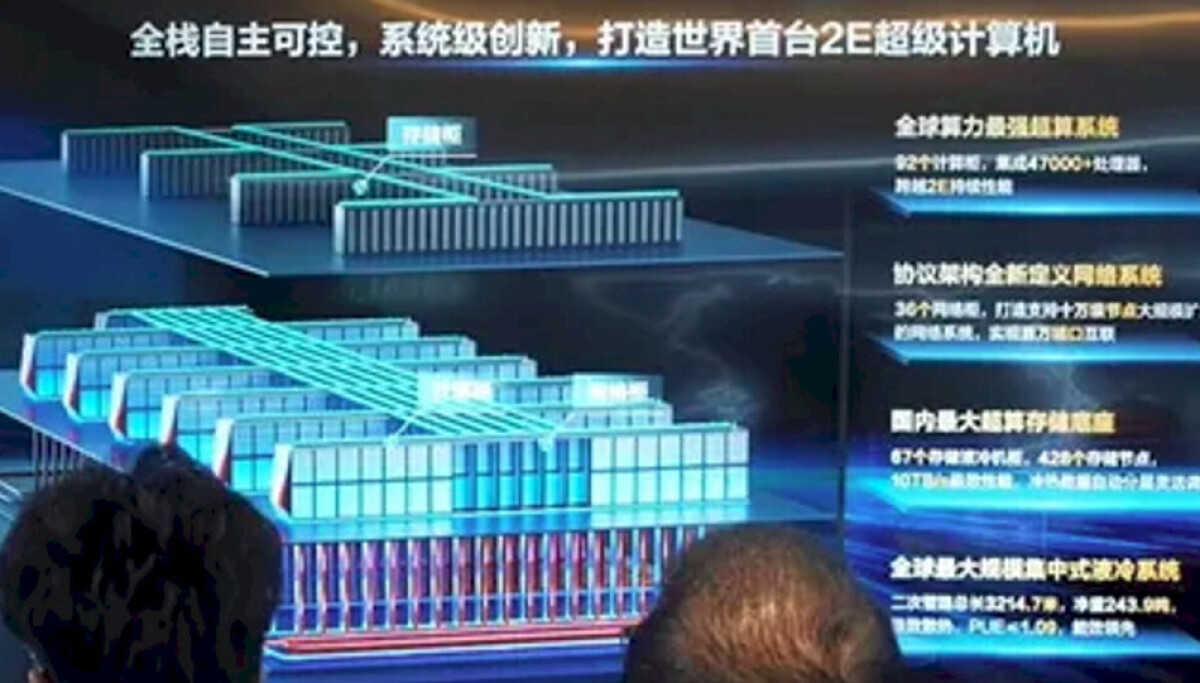
It has been nine years since a Chinese HPC supercomputer was at the top of the High Performance Linp ...
NASA's High Performance Spaceflight Computing project aims to significantly enhance the computational capabilities of spacecraft, enabling autonomous operations and faster
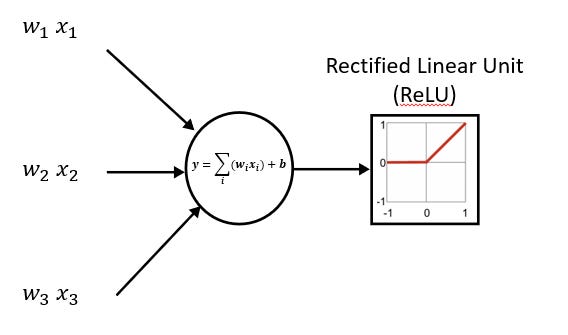
Learning from a classic AI accelerator - Eyeriss
I have never watched the AMC show Halt and Catch Fire, and for a long time I only knew the title, but nothing about the show. Something about it always reminded...

Startup Verkor.io’s agentic AI orchestrated the entire design process from a 219-word prompt

AMD's 3D V-Cache CPUs deliver a huge boost versus the Non-X3D part in AI benchmarks, showcasing why they are best suited for RAG pipelines.
But LLMs' limitations can be seen when it needs to generate responses on data it wasn't trained on.
That's where RAG or Retrieval-Augmented Generation) comes into play


I've been studying the standard cell circuitry in the Intel 386 processor recently. The 386, introduced in 1985, was Intel's most complex pr...
Hello you fine Internet folks!
The mechanism behind this is a time-resource matrix: A scheduling framework that orchestrates compute, memory and control resources across time. Much like a train timetable, scalar, vector and matrix operations move across a synchronized compute fabric without pipeline stalls or contention.
By predicting exactly when data will arrive — whether in 10 cycles or 200 — Deterministic Execution can slot dependent instructions into the right future cycle. This turns latency from a hazard into a schedulable event, keeping the execution units fully utilized and avoiding the massive thread and…
Motorola’s 68000 blended 32-bit power with a 16-bit bus, creating a balanced, orthogonal, and elegant architecture that powered everything from Macintosh to arcade machines.

I've been reverse-engineering the Intel 386 processor (from 1985), and I've come across some interesting circuits for the chip's input/outpu...


Most people think of machine instructions as the fundamental steps that a computer performs. However, many processors have another layer of ...
Hello you fine Internet folks,

In 1993, Intel released the high-performance Pentium processor, the start of the long-running Pentium line. I've been examining the Pentium'...
It is often said that companies – particularly large companies with enormous IT budgets – do not buy products, they buy roadmaps. No one wants to go to
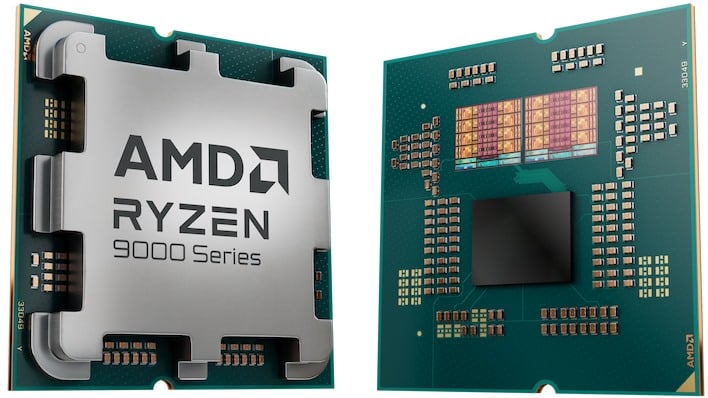
After persistent rumors refused to recede, AMD steps in with a clear explanation why dual-CCD V-Cache doesn't exist.
No, the actual reason AMD won't make a dual-V-Cache chip is much simpler: it would be pointless and a waste of money.
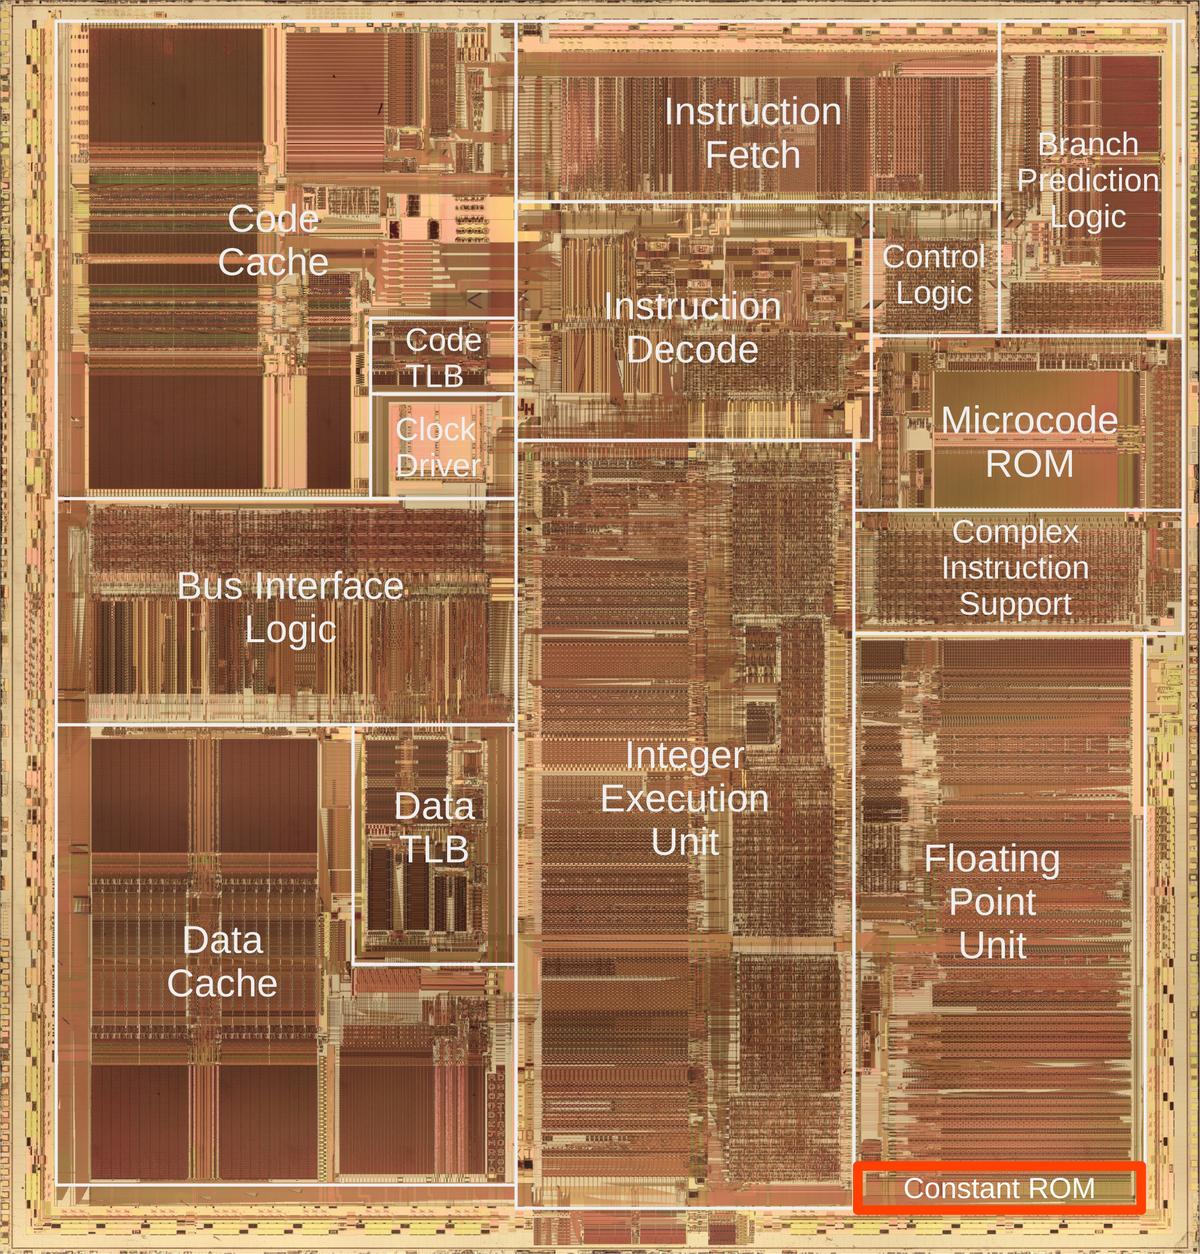
Intel released the powerful Pentium processor in 1993, establishing a long-running brand of high-performance processors. 1 The Pentium incl...
Note: Based on Ken Shirriff's article "[Pi in the Pentium: reverse-engineering the constants in its floating-point unit](https://www.righto.com/2025/01/pentium-floating-point-ROM.html)", here is an outline of each section with explanations of the findings: | Section | Findings | |---|---| | **Introduction** | The Pentium processor's floating-point unit (FPU) computes transcendental functions like sine…
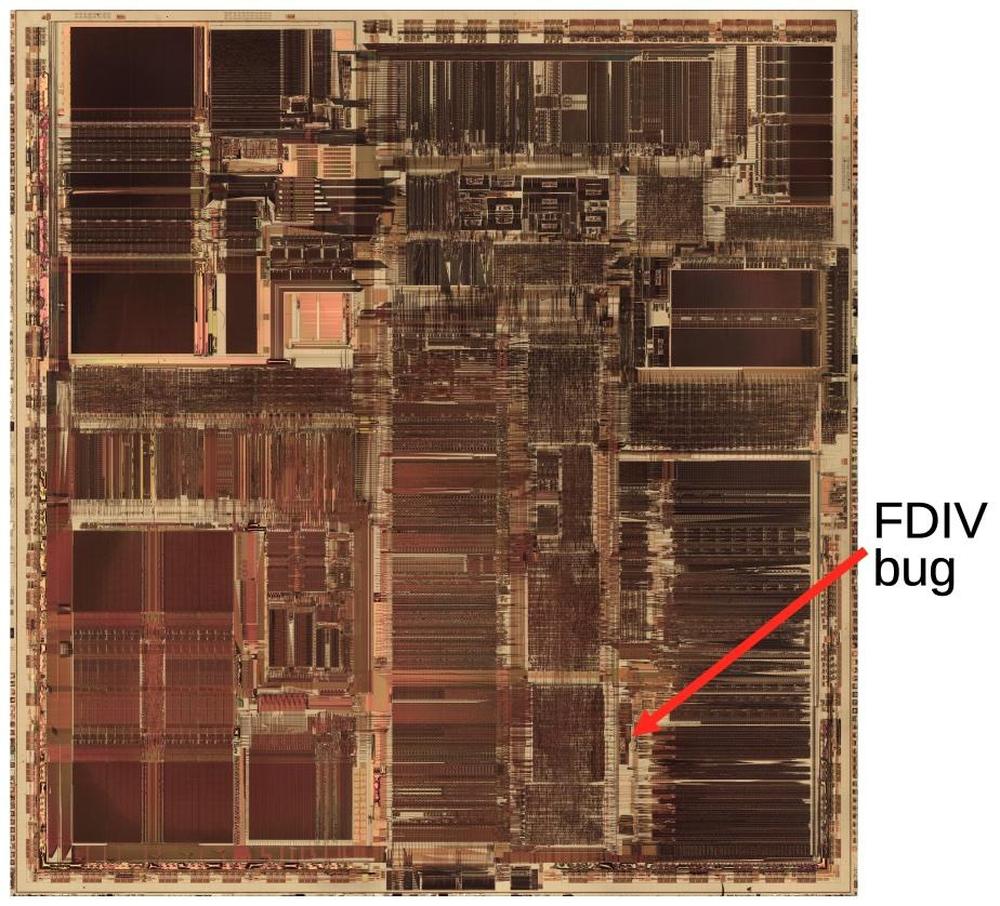
In 1993, Intel released the high-performance Pentium processor, the start of the long-running Pentium line. The Pentium had many improvement...

The CCD stack with 3D V-Cache on the AMD Ryzen 7 9800X3D is only 40-45µm in total, but the rest of the layers add up to a whopping 750µm.
stability
9800X3D brought the 3D chiplet underneath the CC

A loop buffer sits at a CPU's frontend, where it holds a small number of previously fetched instructions.
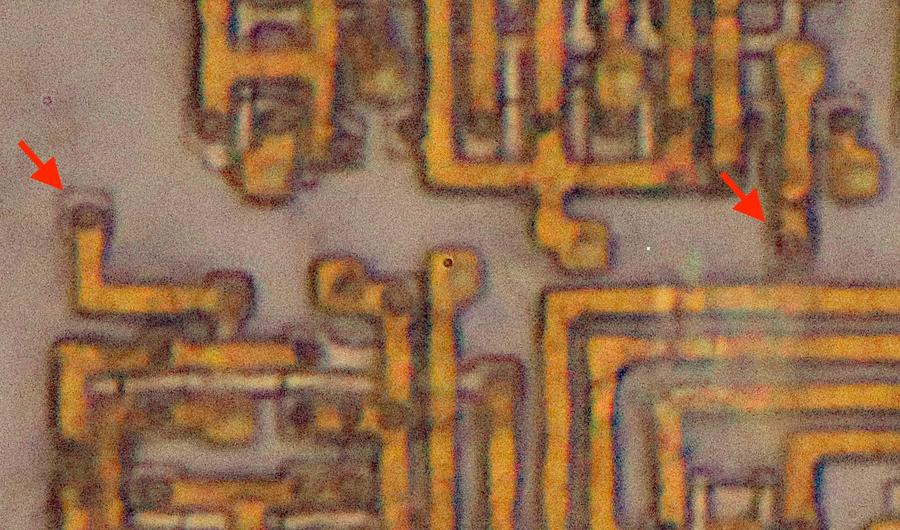
I was studying the silicon die of the Pentium processor and noticed some puzzling structures where signal lines were connected to the silico...
Intel was a dominant leader in the CPU market for the better part of a decade, but AMD has seen massive success in recent years thanks to its Ryzen chips.
Nitro, Graviton, EFA, Inferentia, Trainium, Nvidia Cloud, Microsoft Azure, Google Cloud, Oracle Cloud, Handicapping Infrastructure, AI As A Service, Enterprise Automation, Meta, Coreweave, TCO
No matter how elegant and clever the design is for a compute engine, the difficulty and cost of moving existing – and sometimes very old – code from the
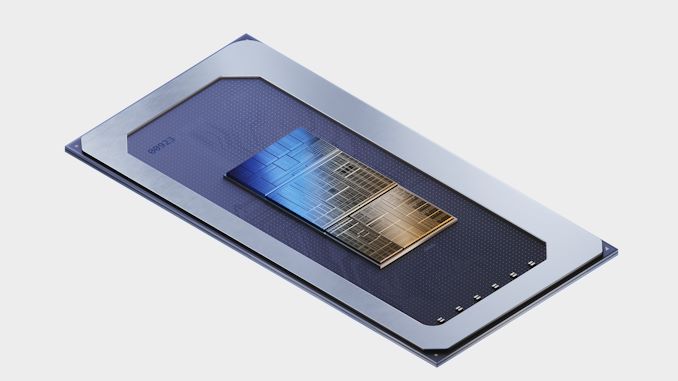

There are many chip partitioning and placement tradeoffs when comparing top-tier smartphone processor designs.
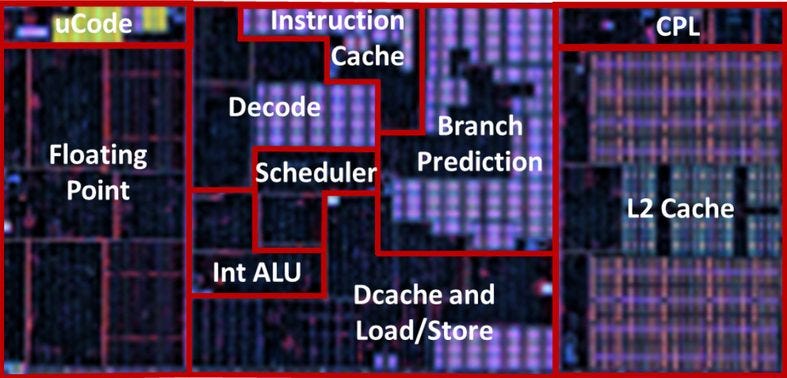
When I recently interviewed Mike Clark, he told me, “…you’ll see the actual foundational lift play out in the future on Zen 6, even though it was really Zen 5 that set the table for that.” And at that same Zen 5 architecture event, AMD’s Chief Technology Officer Mark Papermaster…
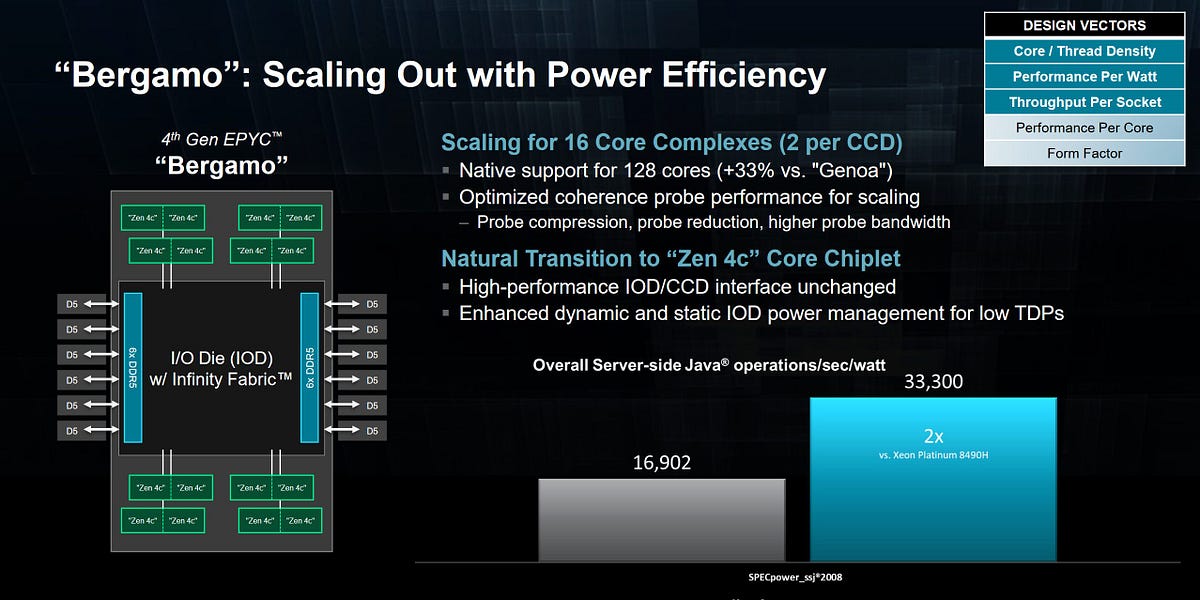
Server CPUs have pushed high core counts for a long time, though they way they got high core counts has varied.

A Finnish startup called Flow Computing is making one of the wildest claims ever heard in silicon engineering: by adding its proprietary companion chip,
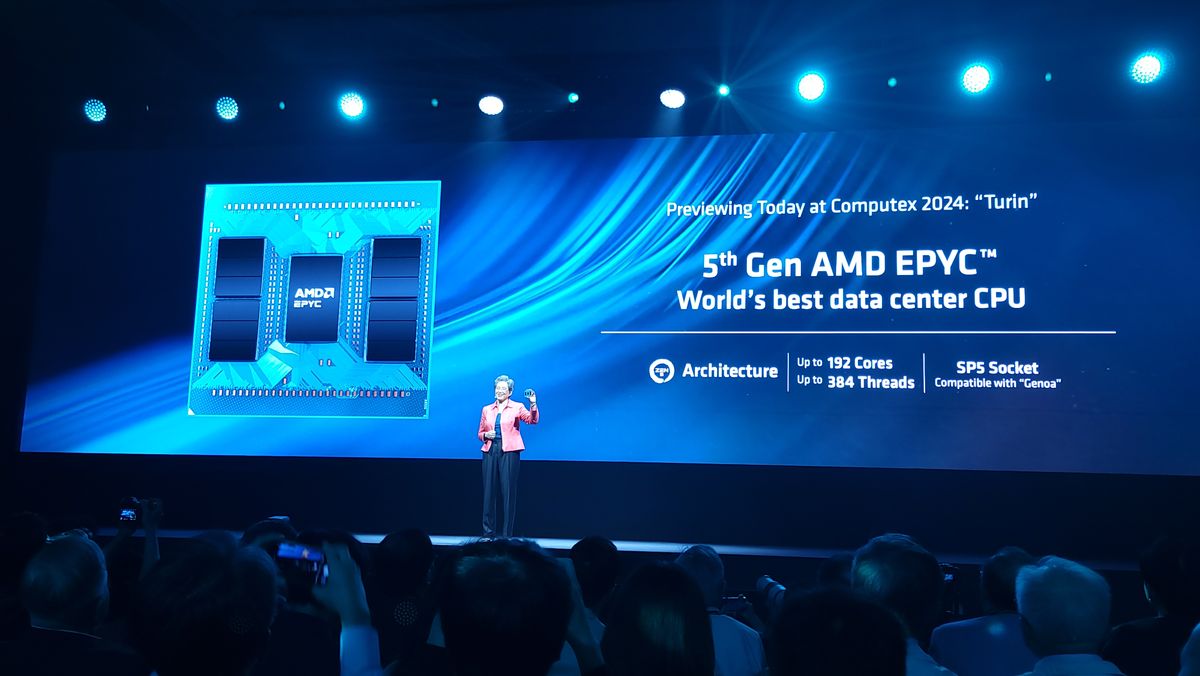
192 cores, 385 threads, socket compatibility. What's not to like?

Anton Shilov reports via Tom's Hardware: About half of the processors packaged in Russia are defective. This has prompted Baikal Electronics, a Russian processor developer, to expand the number of packaging partners in the country, according to a report in Vedomosti, a…
Researchers also disclosed a separate bug called “Inception” for newer AMD CPUs.
Downfall attacks targets a critical weakness found in billions of modern processors used in personal and cloud computers.
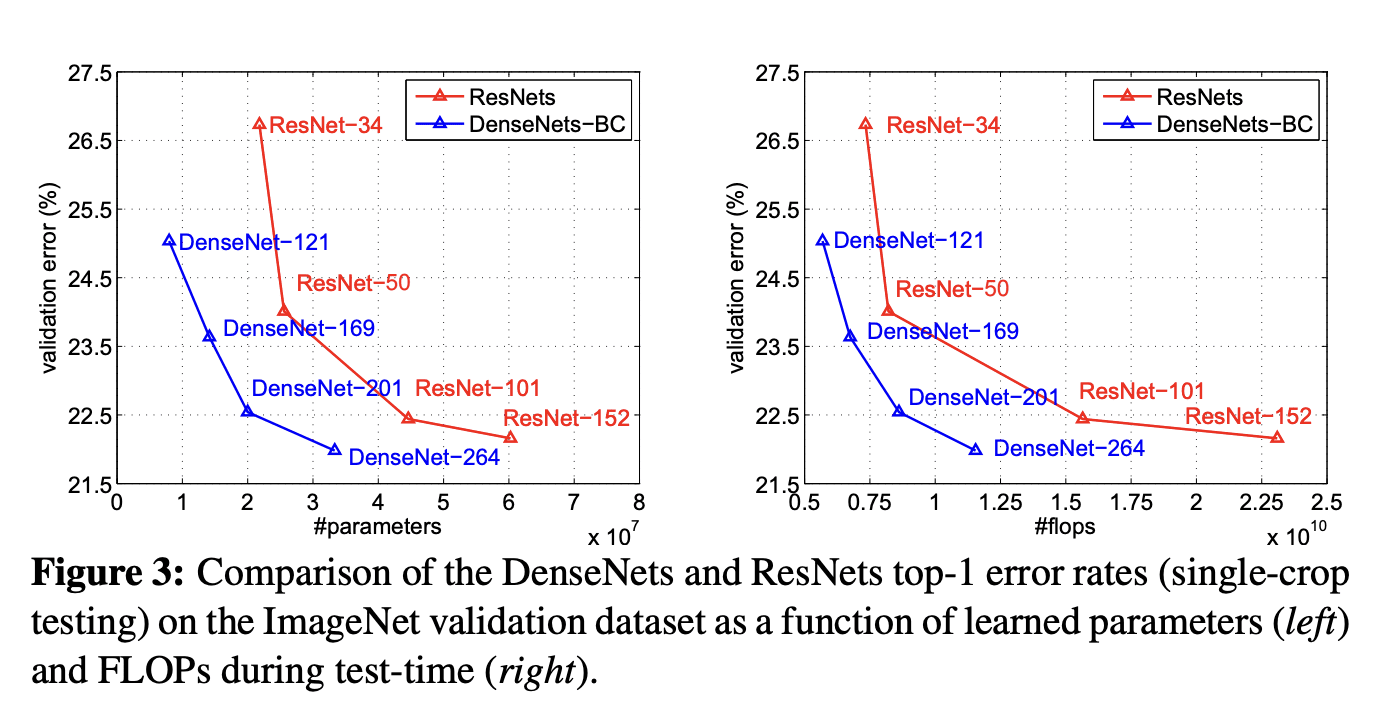
In this article we will learn about its definition, differences and how to calculate FLOPs and MACs using Python packages.
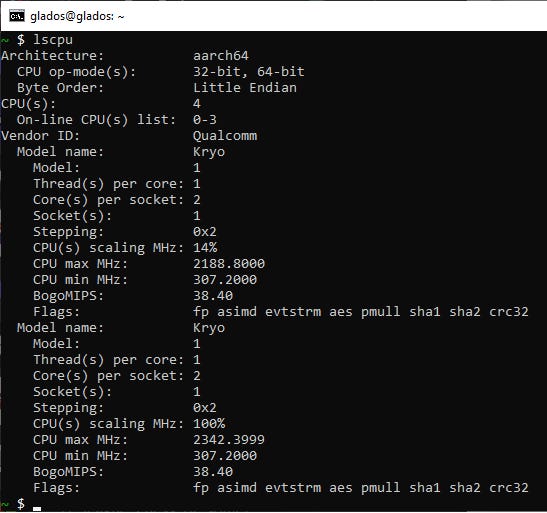
CPU design is hard.
Micron $MU looks very weak in AI
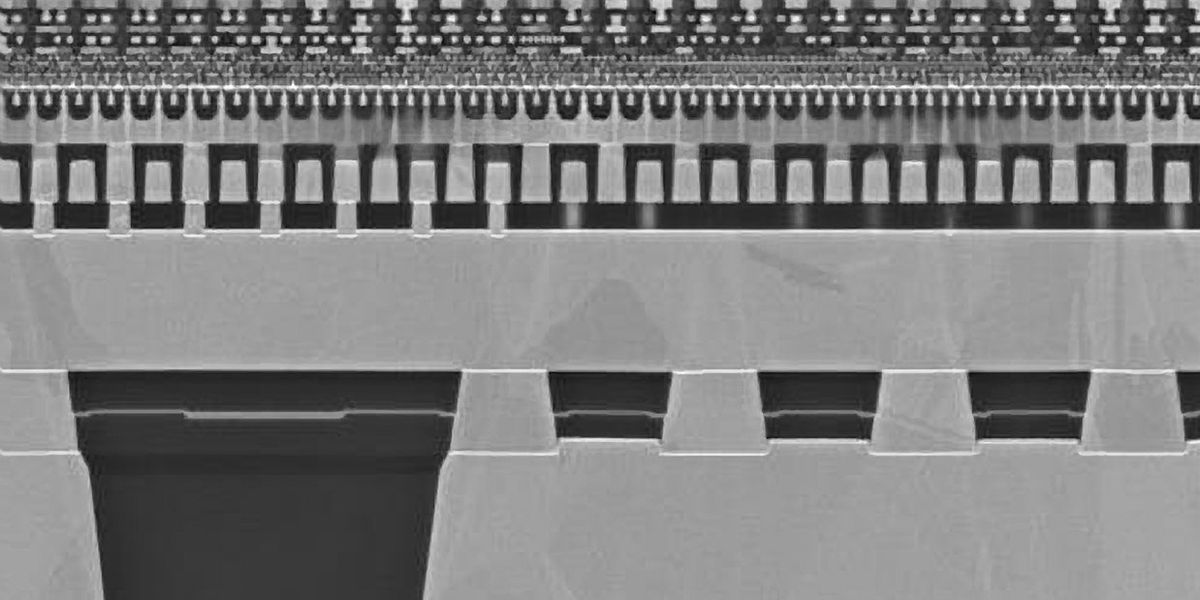
The company’s PowerVia interconnect tech demonstrated a 6 percent performance gain

GPUs may dominate, but CPUs could be perfect for smaller AI models