Yes, Transformers Are a Problem...
But So Are Converters, Inverters, and MMCs!
But So Are Converters, Inverters, and MMCs!
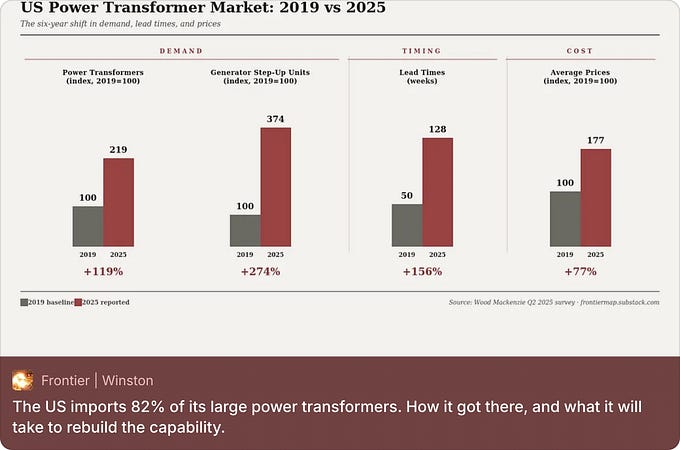
The steel almost nobody can make. Grain-oriented electrical steel, or GOES, is the material at the heart of every large transformer core. It is a silicon-iron alloy at roughly 3% silicon, rolled into sheets 0.18 to 0.35 millimeters thick, with the crystalline grains forced into…
This tutorial covers three NLP tasks: text classification, zero-shot labelling, and question answering using Transformers.js's pipeline() API.

LLMs are evolving. The next generation of the world’s hottest technology will be cheaper, more efficient, and able to solve bigger problems without going off the rails.
You've likely used ChatGPT, Gemini, or Grok, which demonstrate how large language models can exhibit human-like intelligence. While creating a clone of these large language models at home is unrealistic and unnecessary, understanding how they work helps demystify their…
Making developers awesome at machine learning.
We insist that large language models repeatedly translate their mathematical processes into words. There may be a better way.
This reliance on filtering concepts through the sieve of language can also result in a loss of information
deep neural networks that allow language models to continue thinking in mathematical spaces before producing any text.
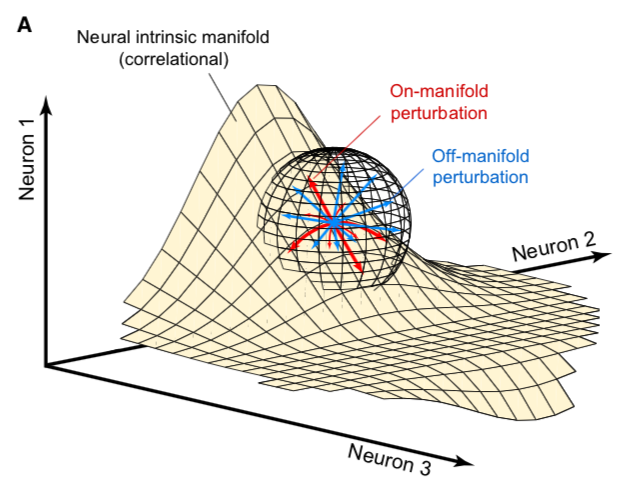

Large language models (LLMs) can understand and generate human-like text by encoding vast knowledge repositories within their parameters. This capacity enables them to perform complex reasoning tasks, adapt to various applications, and interact effectively with humans. However…
Speed up your LLM inference

Natural Language Processing (NLP) has rapidly evolved in the last few years, with transformers emerging as a game-changing innovation. Yet, there are still notable challenges when using NLP tools to develop applications for tasks like semantic search, question answering, or…
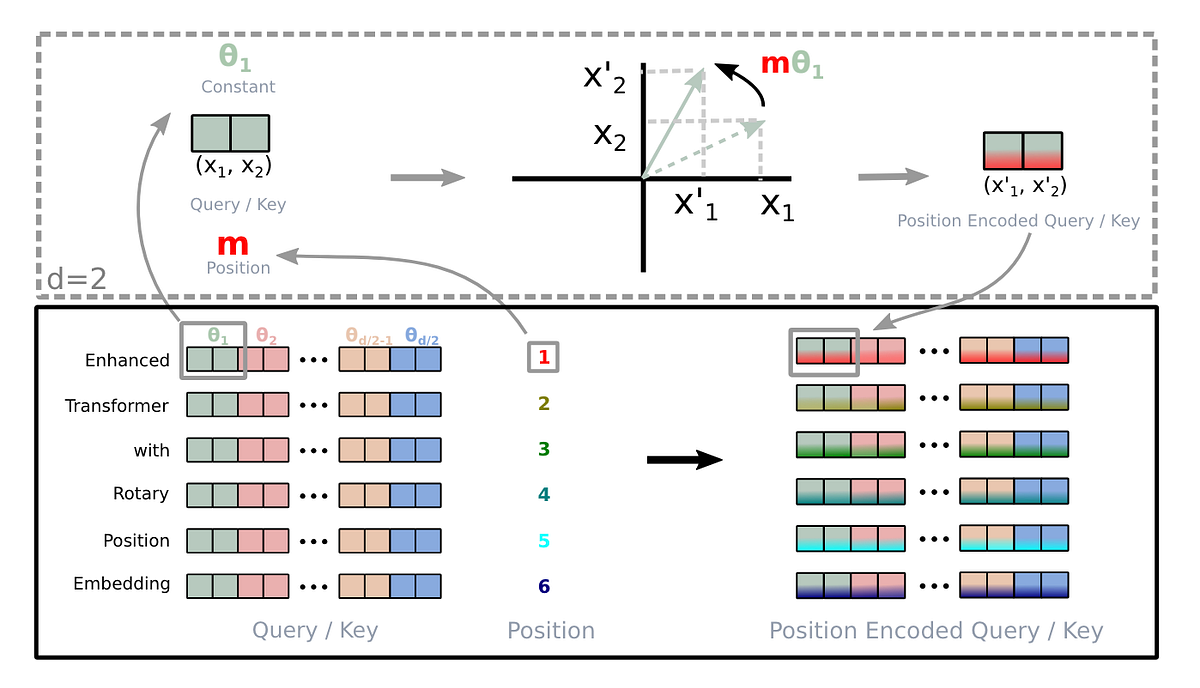
A deep dive into absolute, relative, and rotary positional embeddings with code examples

The Sohu AI chip by Etched is a thundering breakthrough, boasting the title of the fastest AI chip to date. Its design is a testament to cutting-edge innovation, aiming to redefine the possibilities within AI computations and applications. At the center of Sohu's exceptional…
This is a visual guide (scroll story) to Vision Transformers (ViTs), a class of deep learning models that have achieved state-of-the-art performance on image classification tasks.
Is Attention all you need? Mamba, a novel AI model based on State Space Models (SSMs), emerges as a formidable alternative to the widely used Transformer models, addressing their inefficiency in processing long sequences.
The Math and the Code Behind Position Embeddings in Vision Transformers
The Math and the Code Behind Attention Layers in Computer Vision
A Full Walk-Through of Vision Transformers in PyTorch

In the past few years we have seen the meteoric appearance of dozens of foundation models of the Transformer family, all of which have memorable and sometimes funny, but not self-explanatory,...
Welcome to this beginner-friendly tutorial on sentiment analysis using Hugging Face's transformers...
A quick-start guide to using open-source LLMs
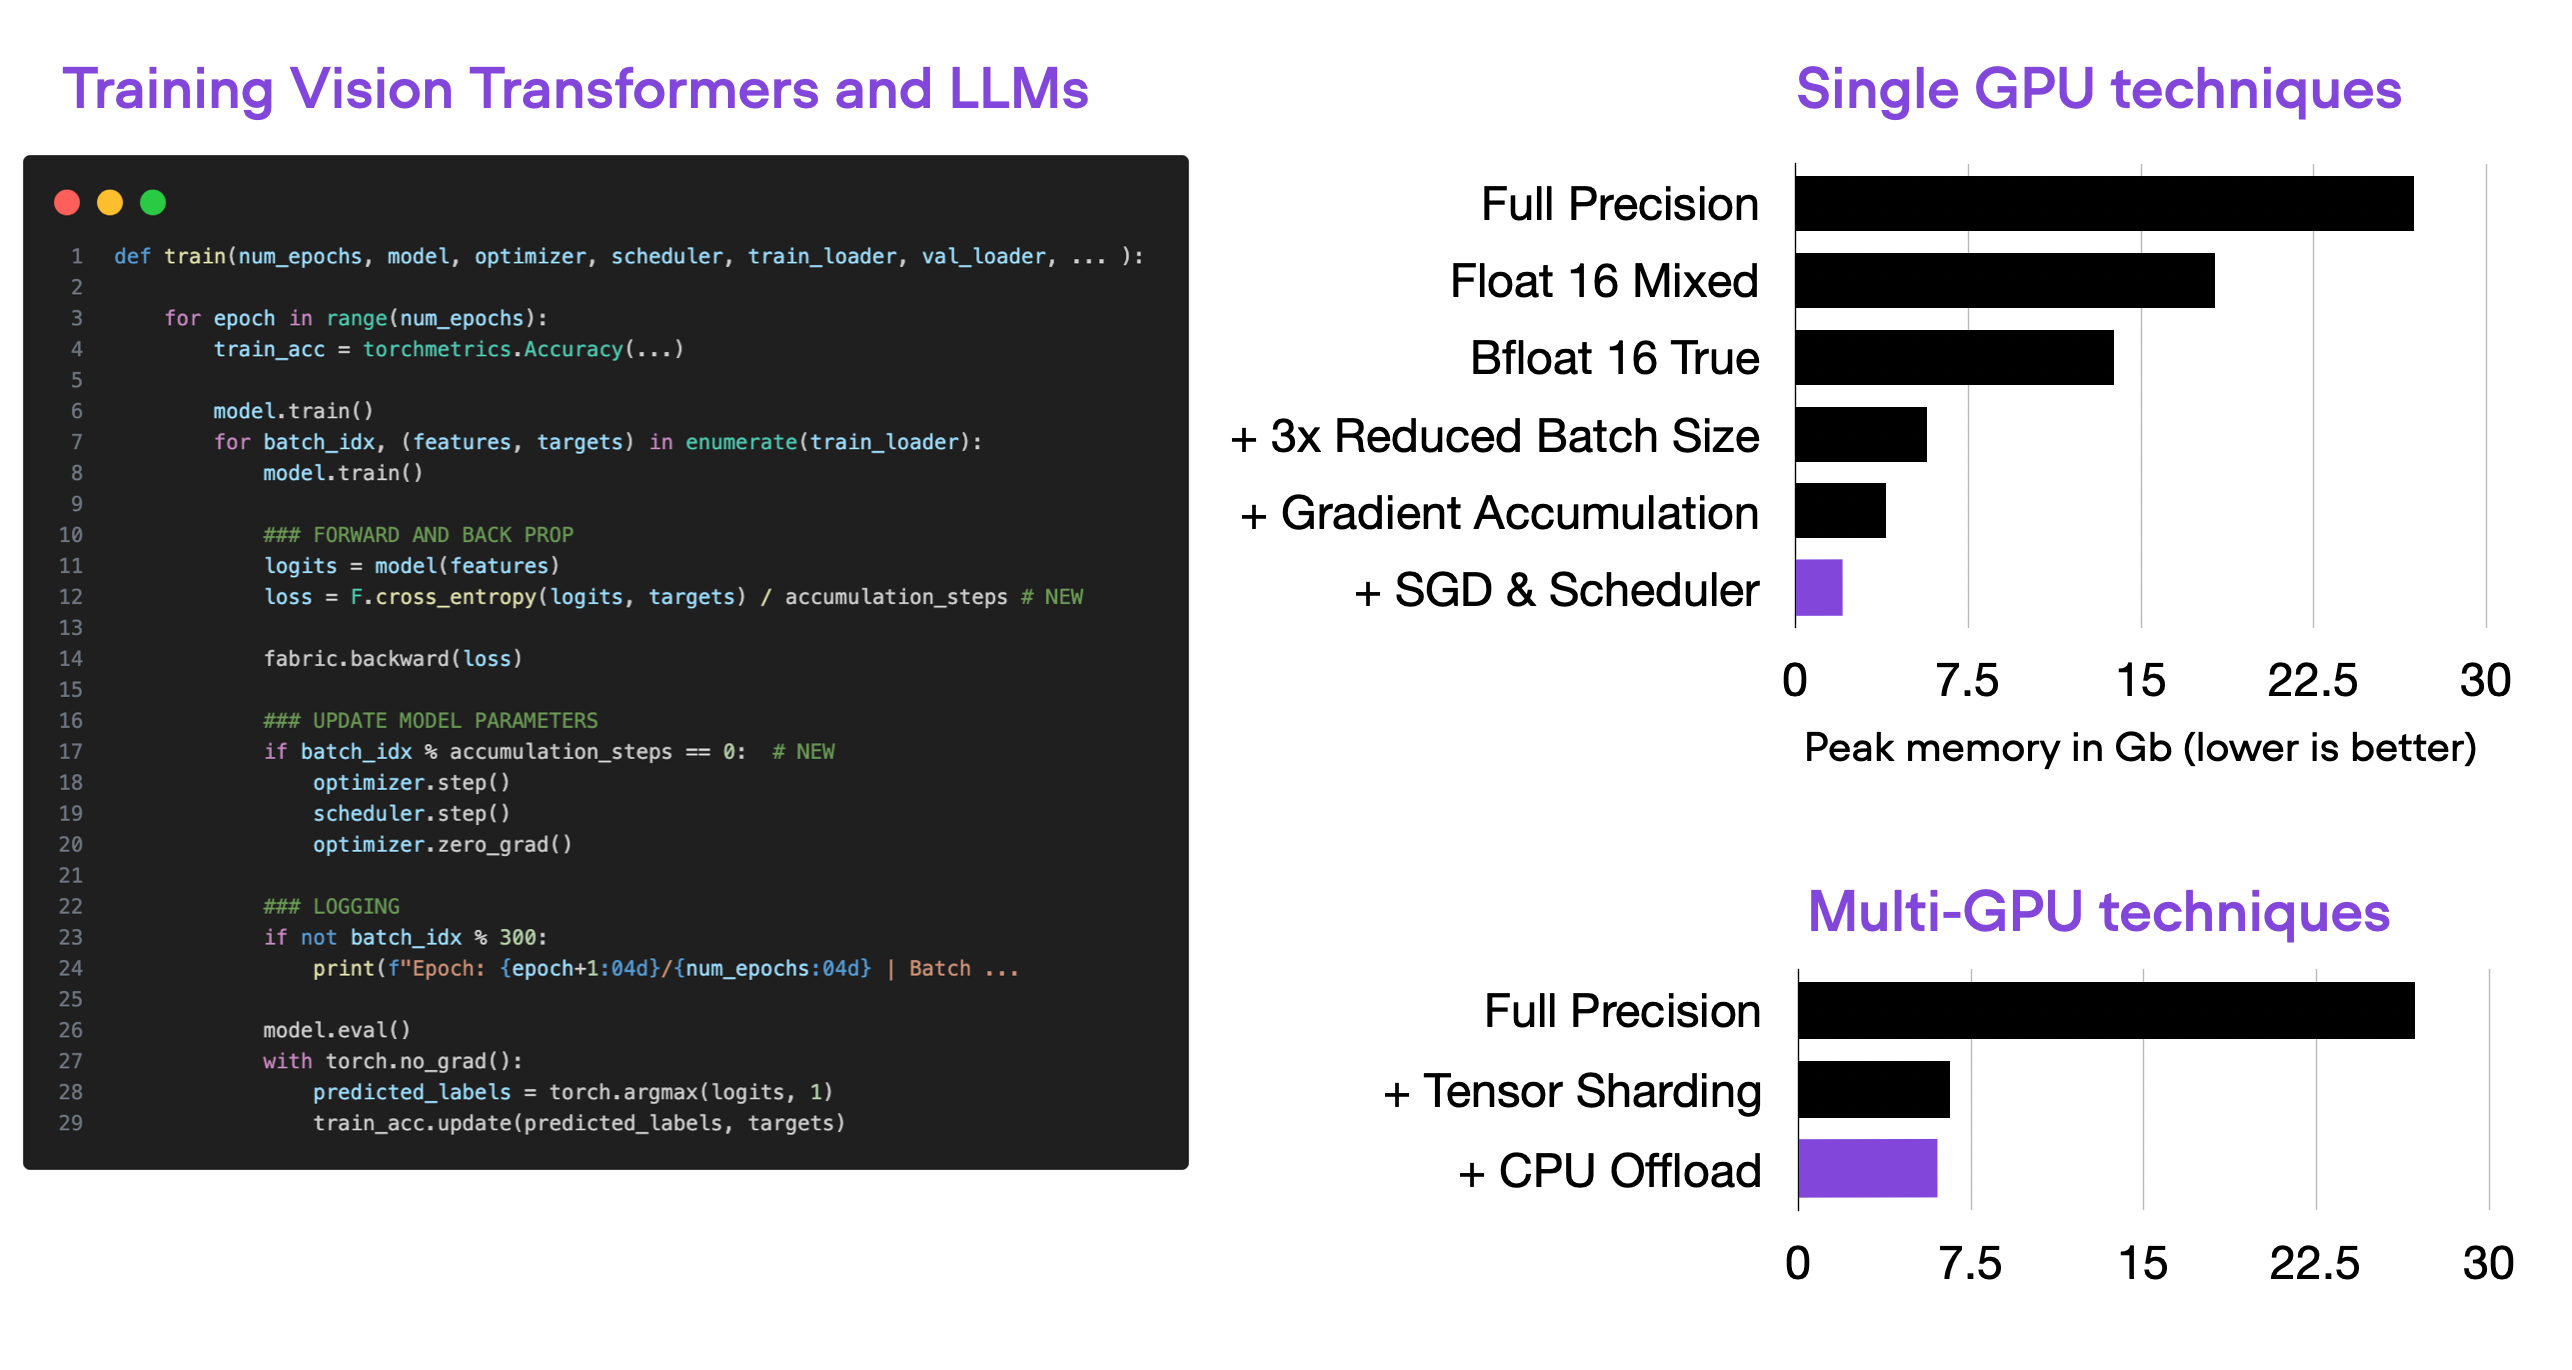
This article provides a series of techniques that can lower memory consumption in PyTorch (when training vision transformers and LLMs) by approximately 20x without sacrificing modeling performance and prediction accuracy.
1) Reinforcement Learning with Human Feedback(RLHF) 2) The RLHF paper, 3) The transformer reinforcement learning framework.
Facebook’s parent company is inviting researchers to pore over and pick apart the flaws in its version of GPT-3
Transformer models are one of the most exciting new developments in machine learning. They were introduced in the paper Attention is All You Need. Transformers can be used to write stories, essays, poems, answer questions, translate between languages, chat with humans, and they…
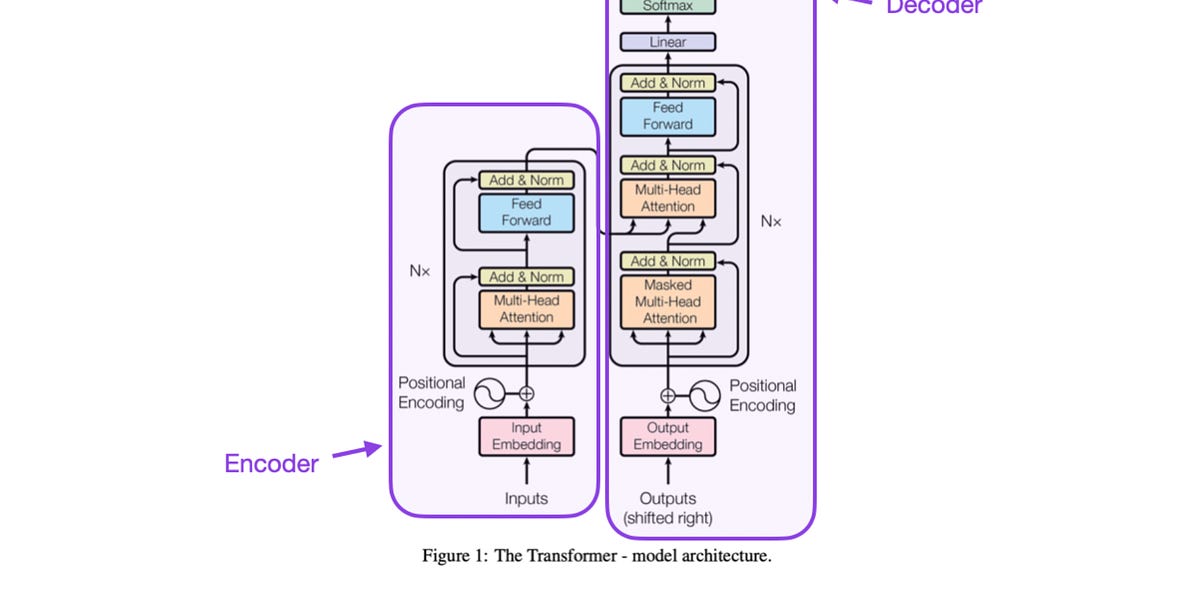
A Cross-Section of the Most Relevant Literature To Get Up to Speed
I explain what is so unique about the RWKV language model.
The rapidly increasing size of deep-learning models has caused renewed and growing interest in alternatives to digital computers to dramatically reduce the energy cost of running state-of-the-art...
Many new Transformer architecture improvements have been proposed since my last post on “The Transformer Family” about three years ago. Here I did a big refactoring and enrichment of that 2020 post — restructure the hierarchy of sections and improve many sections with more…
Implementation of Vision Transformer, a simple way to achieve SOTA in vision classification with only a single transformer encoder, in Pytorch - lucidrains/vit-pytorch
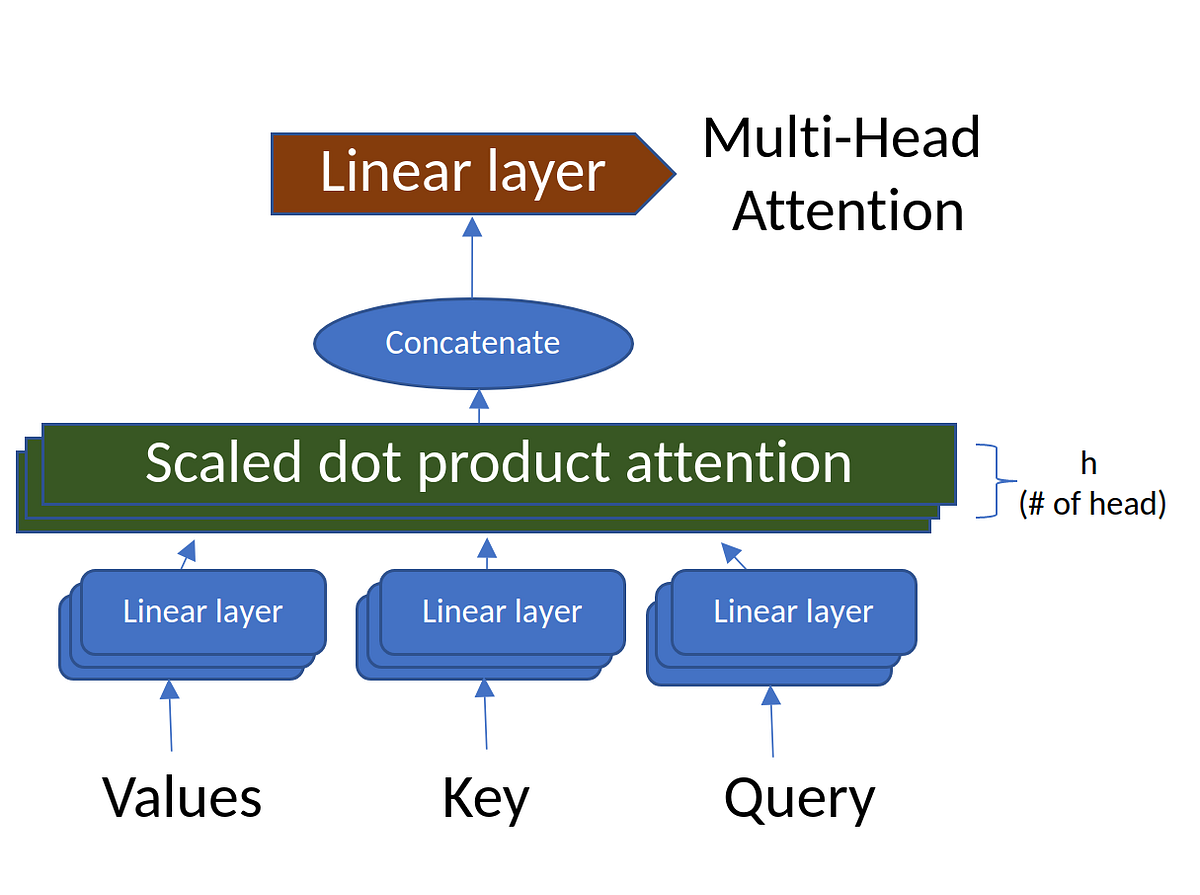
Attention, Self-Attention, Multi-head Attention, Masked Multi-head Attention, Transformers, BERT, and GPT
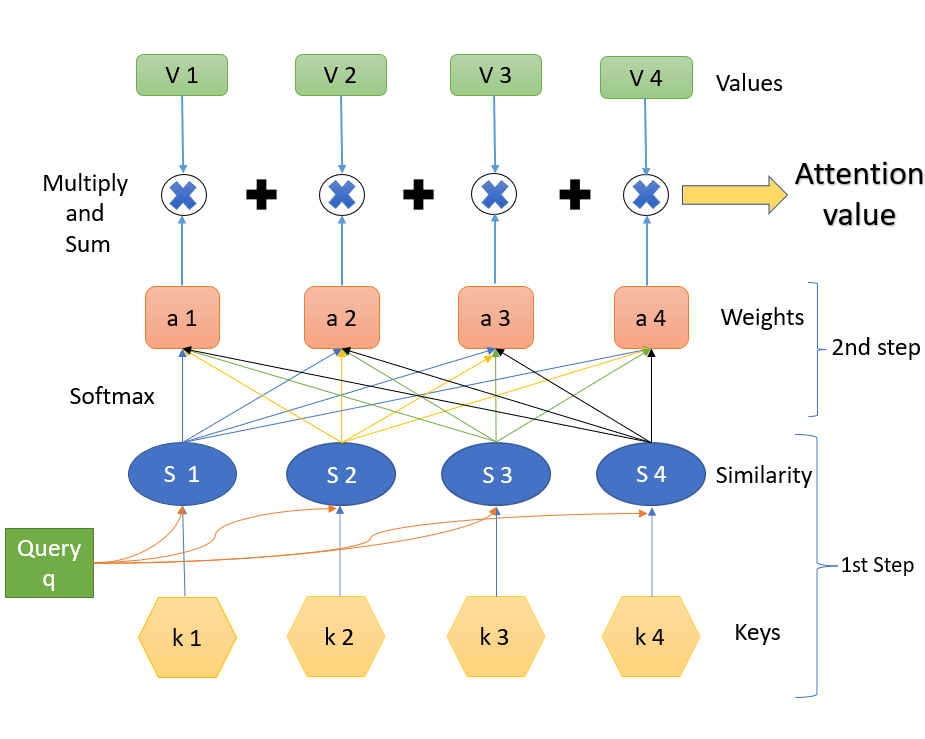
Attention, Self-Attention, Multi-head Attention, and Transformers
State-of-the-art transformers for Ruby.

Summary: We have released GPT-J-6B, 6B JAX-based (Mesh) Transformer LM (Github).GPT-J-6B performs nearly on par with 6.7B GPT-3 (or Curie) on various zero-shot down-streaming tasks.You can try out …
This repository contains demos I made with the Transformers library by HuggingFace. - NielsRogge/Transformers-Tutorials
Discussions: Hacker News (65 points, 4 comments), Reddit r/MachineLearning (29 points, 3 comments) Translations: Arabic, Chinese (Simplified) 1, Chinese (Simplified) 2, French 1, French 2, Italian, Japanese, Korean, Persian, Russian, Spanish 1, Spanish 2, Vietnamese Watch: MIT’s…

How this novel neural network architecture changes the way we analyze complex data types, and powers revolutionary models like GPT-3 and BERT.
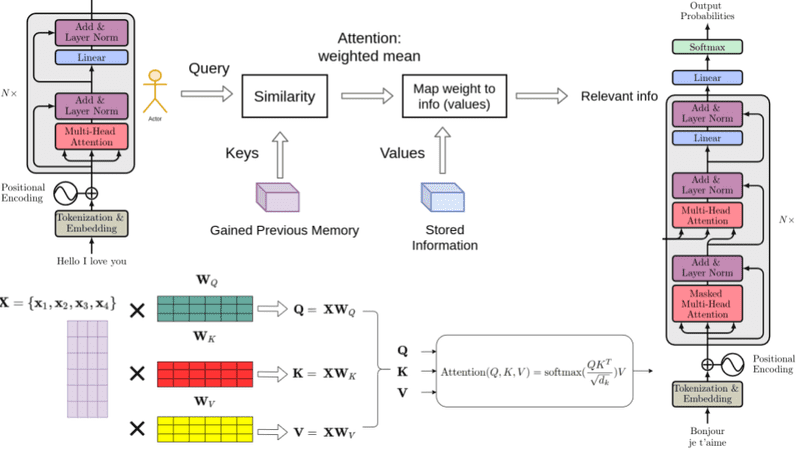
An intuitive understanding on Transformers and how they are used in Machine Translation. After analyzing all subcomponents one by one such as self-attention and positional encodings , we explain the principles behind the Encoder and Decoder and why Transformers work so well