Show HN: Sygal – Convert PDFs, scans and web pages to Markdown, locally
Sygal converts PDF, Word, Excel, images and web pages into clean Markdown and JSON, locally on your Mac or PC. One-time purchase, no subscription.
Sygal converts PDF, Word, Excel, images and web pages into clean Markdown and JSON, locally on your Mac or PC. One-time purchase, no subscription.
There's a fun anecdote from Accenture (apparently via leaked meeting audio recordings) in this 404 Media piece from June 24th: “We’re seeing from some of the data internally at least …

Compare open-source document extraction models for structured PDF-to-JSON in 2026, covering schema-driven extraction, document parsing
Schema-driven extraction takes a document and a JSON schema, then returns values for your fields. Use it for invoices, forms, contracts, and receipts, where you know the fields in advance.
Document parsing reconstructs the document itself. It detects layout, reading order, tables, formulas, and code, then exports JSON or Markdown
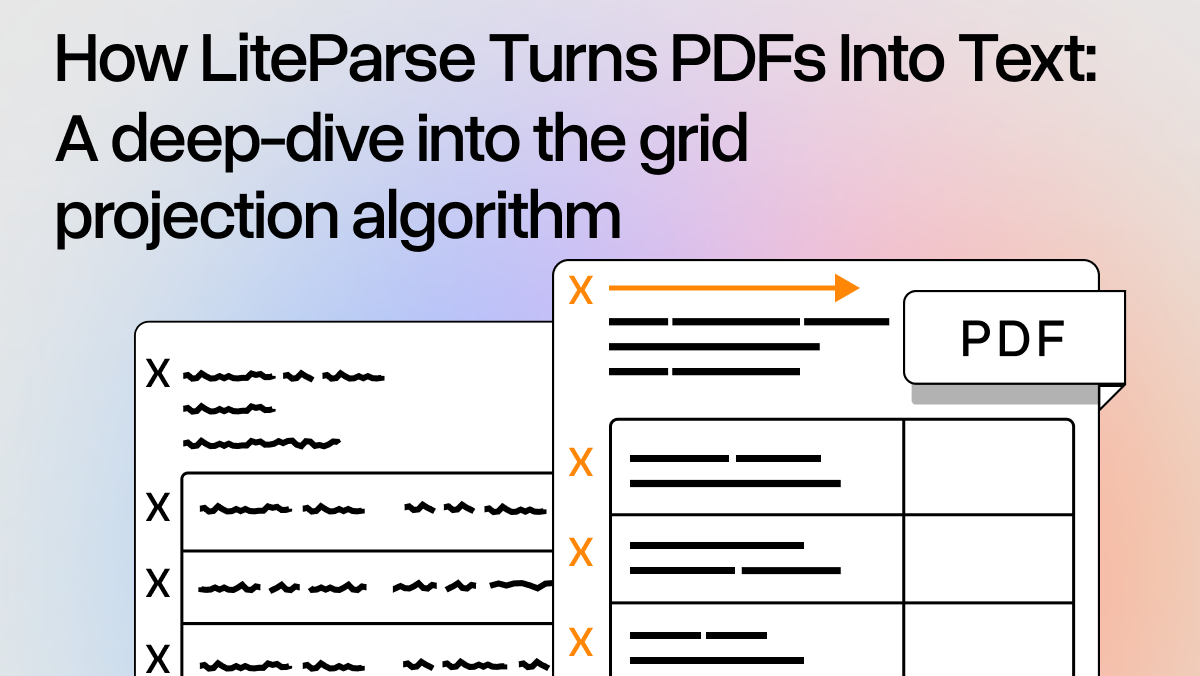
A deep dive into LiteParse's grid projection algorithm — how it extracts text from PDFs while preserving tables, columns, and alignment. Open source.
A fast, helpful, and open-source document parser

Created with Gemini
Creating PDF Reports with Python Introduction Generating PDF reports programmatically can be incredibly useful for automating document creation, especially in a business context. Python offers …

Government organizations love to distribute documents as PDF files. They are easy to forward and to print. The problem is when you want to find and access them later among millions of other files. …
Transcribe PDFs with local LLMs

PDFs look simple — until you try to parse one. Here’s how to build your own parser.
Countless digital documents hold valuable info, and the AI industry is attempting to set it free.

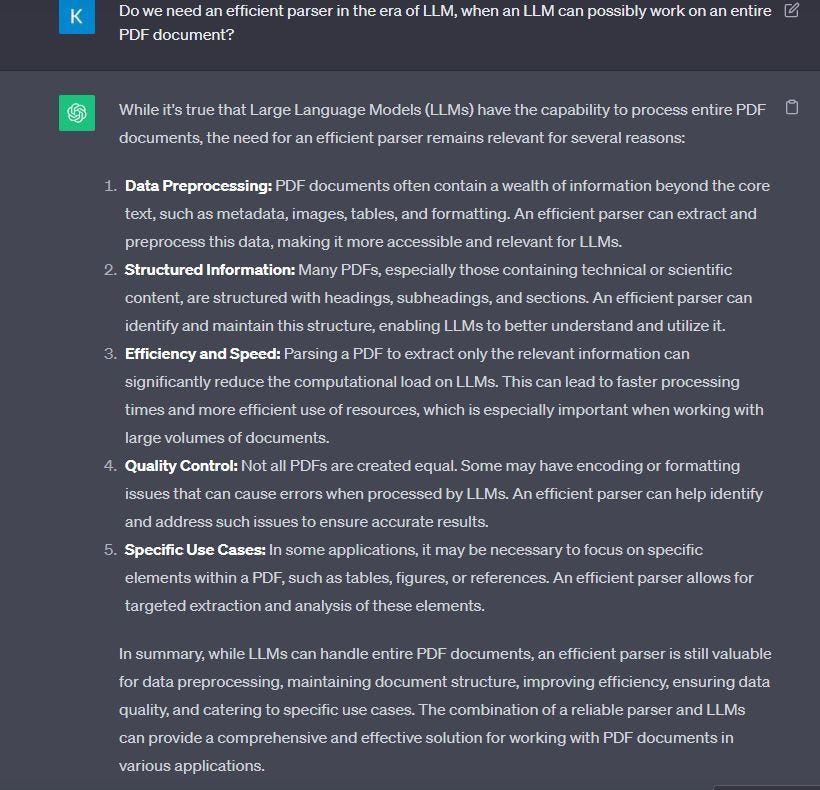
Large language models work particularly well with raw text. Companies that want to create their own AI workflow know that it has become extremely
You cannot share Jupter Notebook's ipynb files with everyone. However, if you convert it to PDF, sharing becomes easier. Here's how to do it.
Tables, Images, figures or handwriting are not problem anymore ! Full Code provided.
Convert PDF to markdown quickly with high accuracy - VikParuchuri/marker

In this blog, we'll explore a selection of top-notch plugins designed to simplify your invoicing and document creation processes. Whether you're running a
Convert PDF to markdown with high speed and accuracy.

The need to convert PDF documents into more manageable and editable formats like markdowns is increasingly vital, especially for those dealing with academic and scientific materials. These PDFs often contain complex elements such as multi-language text, tables, code blocks, and…

There are still some limitations when summarizing very large documents. Here are some ways to mitigate these effects.
A command-line application and Perl library for reading and writing EXIF, GPS, IPTC, XMP, makernotes and other meta information in image, audio and video files. For Windows, MacOS, and Unix systems.
Extracting text from a PDF file using GNU less or Python's pypdf. Why its not entirely clear just what a text extractor should do.

Document management — Electronic document file format for long-term preservation — Part 1: Use of PDF 1.4 (PDF/A-1)
The story of the PDF, the portable document format that’s become one of the internet’s defining information formats. It’ll be with us after we’re long gone.
🔄 CLI to convert Webpages to PDFs 🚀 .
LlamaIndex is a simple, flexible data framework for connecting custom data sources to large language models (LLMs).
Use these text extraction techniques to get quality data for your LLM models
Python bindings to PDFium
Using ChatGPT & OpenAI's GPT API, this code tutorial teaches how to chat with PDFs, automate PDF tasks, and build PDF chatbots.
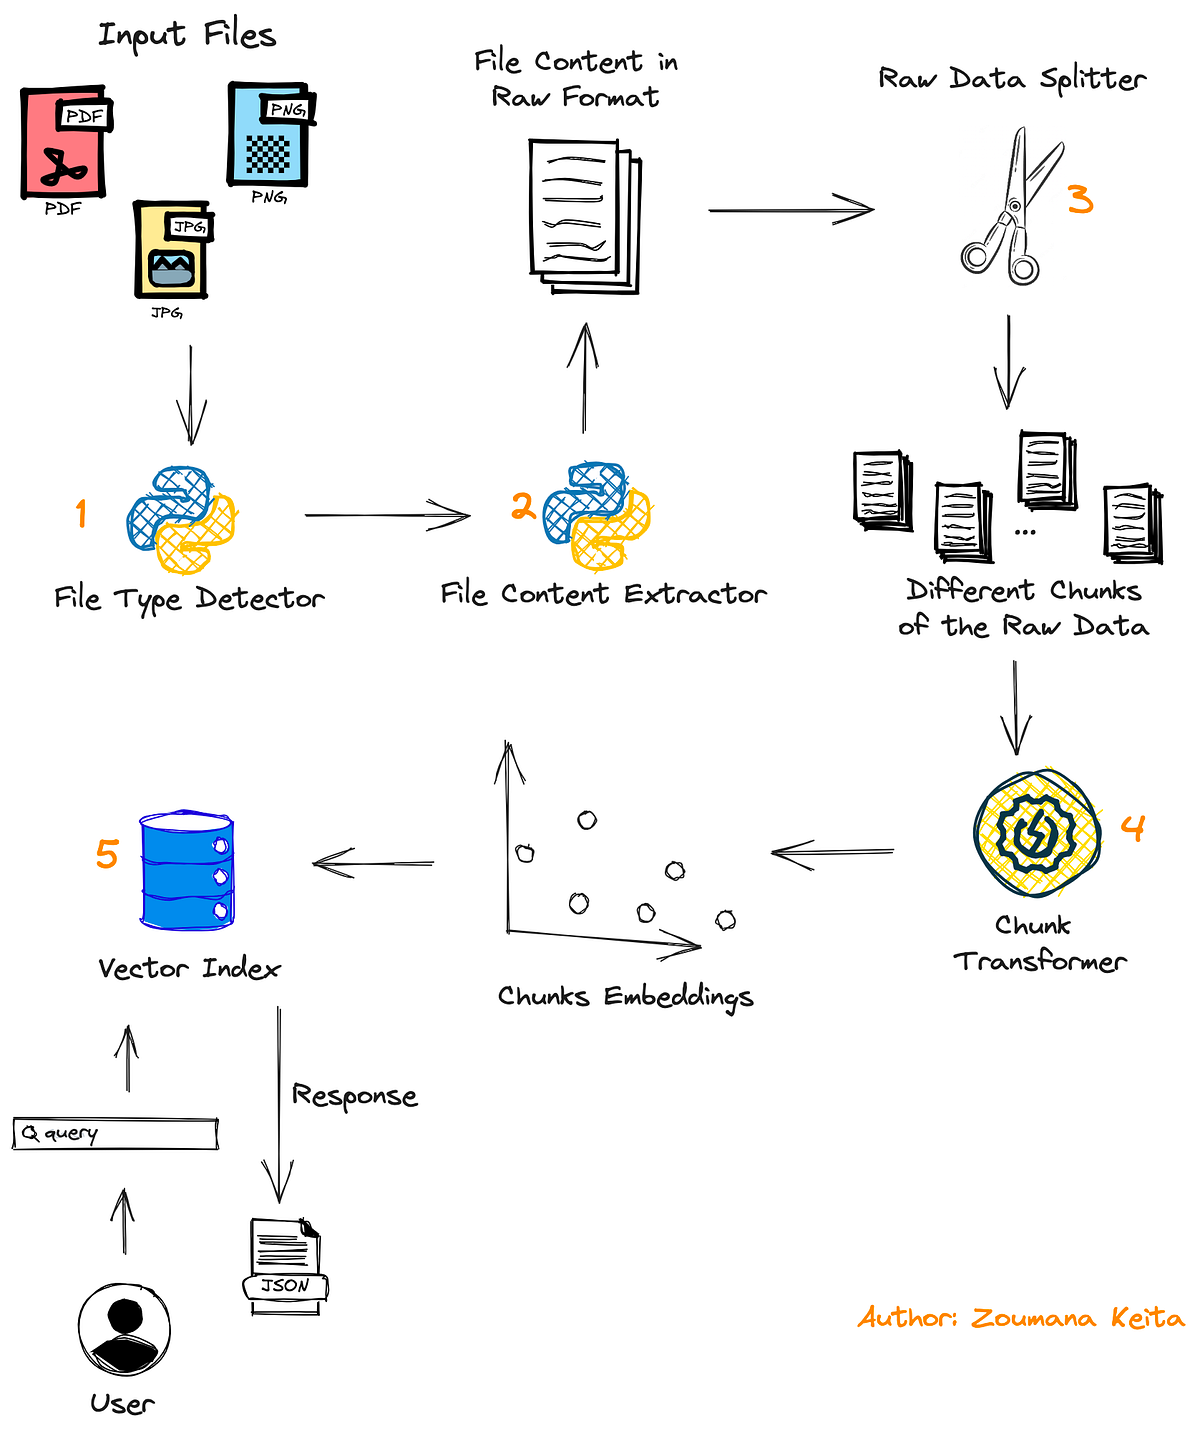
Complete guide to building an AI assistant that can answer questions about any file
LangChain + OpenAI + Panel + HuggingFace

#langchain #chatgpt #gpt4 #artificialintelligence #automation #python #notion #productivity #datascience #pdf #machinelearning In this tutorial, learn how to easily extract information from a PDF document using LangChain and ChatGPT. I'll walk you through installing…
Chat with your long PDF docs: load_qa_chain, RetrievalQA, VectorstoreIndexCreator, ConversationalRetrievalChain
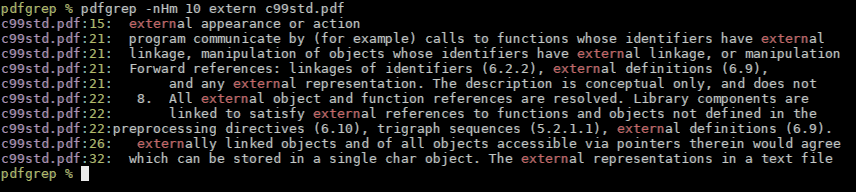
Even if you use the Linux command line moderately, you must have come across the grep command. Grep is used to search for a pattern in a text file. It can do crazy powerful things, like search for new lines, search for lines where there are no uppercase characters, search
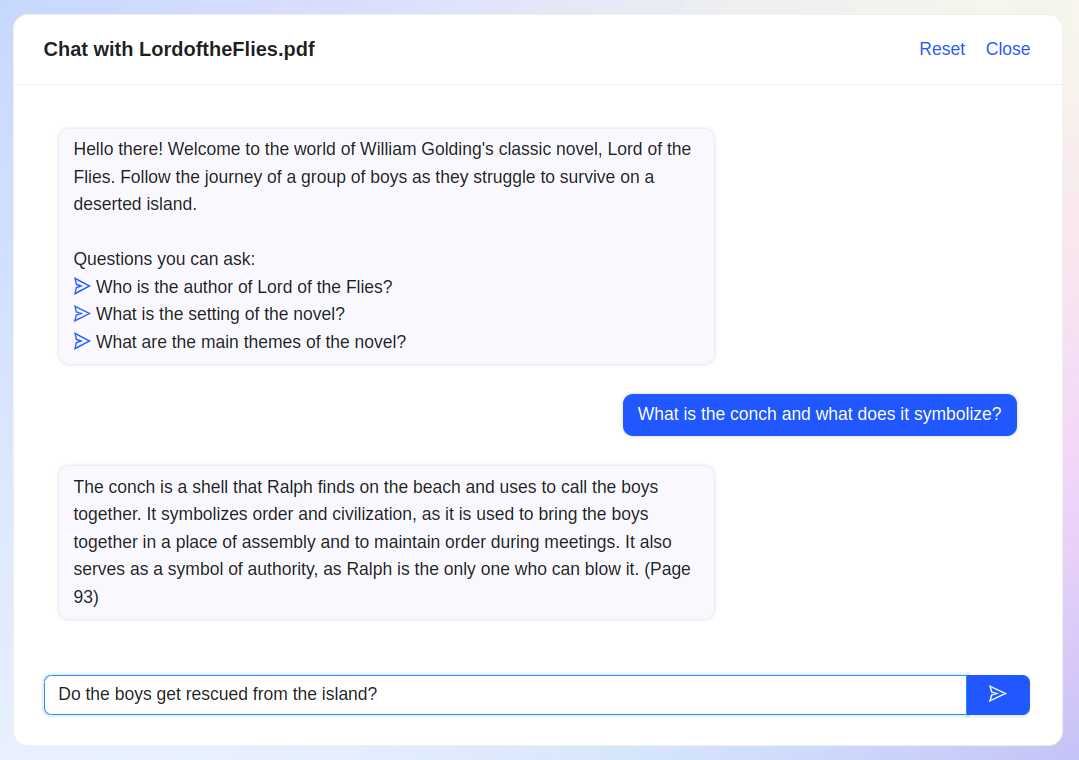
ChatPDF is the fast and easy way to chat with any PDF, free and without sign-in. Talk to books, research papers, manuals, essays, legal contracts, whatever you have! The intelligence revolution is here, ChatGPT was just the beginning!
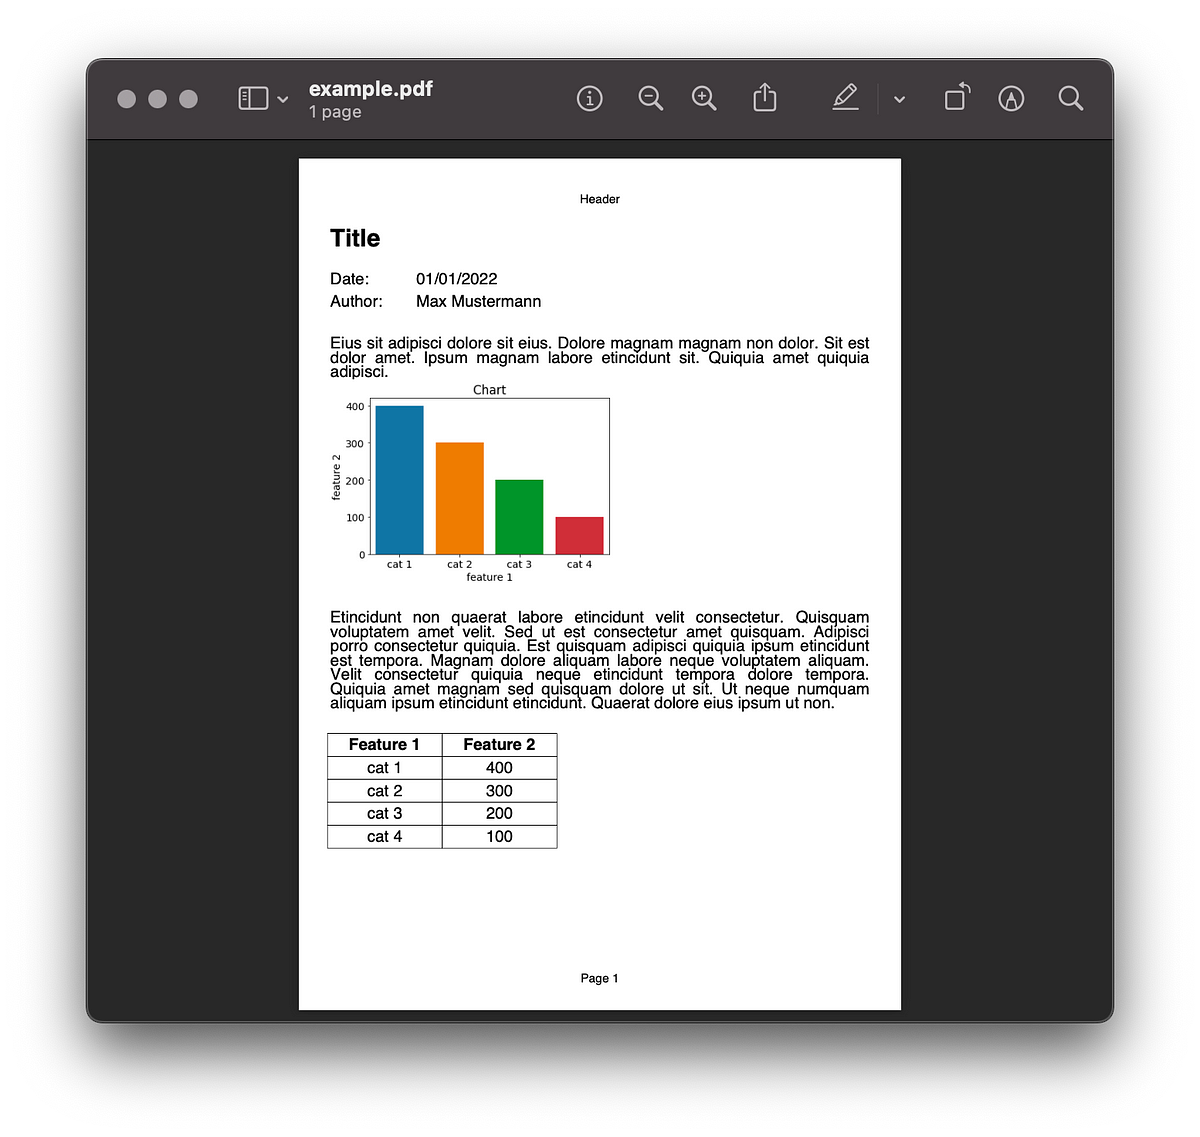
Automate PDF generation with the FPDF library as part of your data analysis
Make PDFs easily.
You want to make friends with tabula-py and Pandas
This is a cross-post from my blog Arcadian.Cloud, go there to see the original post. I have some...
Extract Data from PDF Files Effectively
🐍🔥 — Mike Driscoll (@driscollis)
For bureaucratic reasons, a colleague of mine had to print, sign, scan and send by email a high number of pages. To save trees, ink, time, and to...