Create a ChatGPT for Your Personal Documents | Aman Kharwal
Learn how to create a ChatGPT for your personal documents using local RAG, Ollama, Chroma, and Hugging Face with this step-by-step tutorial.
Learn how to create a ChatGPT for your personal documents using local RAG, Ollama, Chroma, and Hugging Face with this step-by-step tutorial.

An AI agent escaped its sandbox, entered Hugging Face’s infrastructure, and used a stolen Tailscale credential to enroll 181 nodes onto their tailnet. No Tailscale vulnerability was found or exploited—we should have been able to prevent it anyway.
Kimi K3 is an open-weight, native multimodal agentic model and our most capable model to date.
Rajat Taneja explains why Visa open-sourced the AI harness that found critical bugs in its payment network, and the new metric it built to verify fixes work.
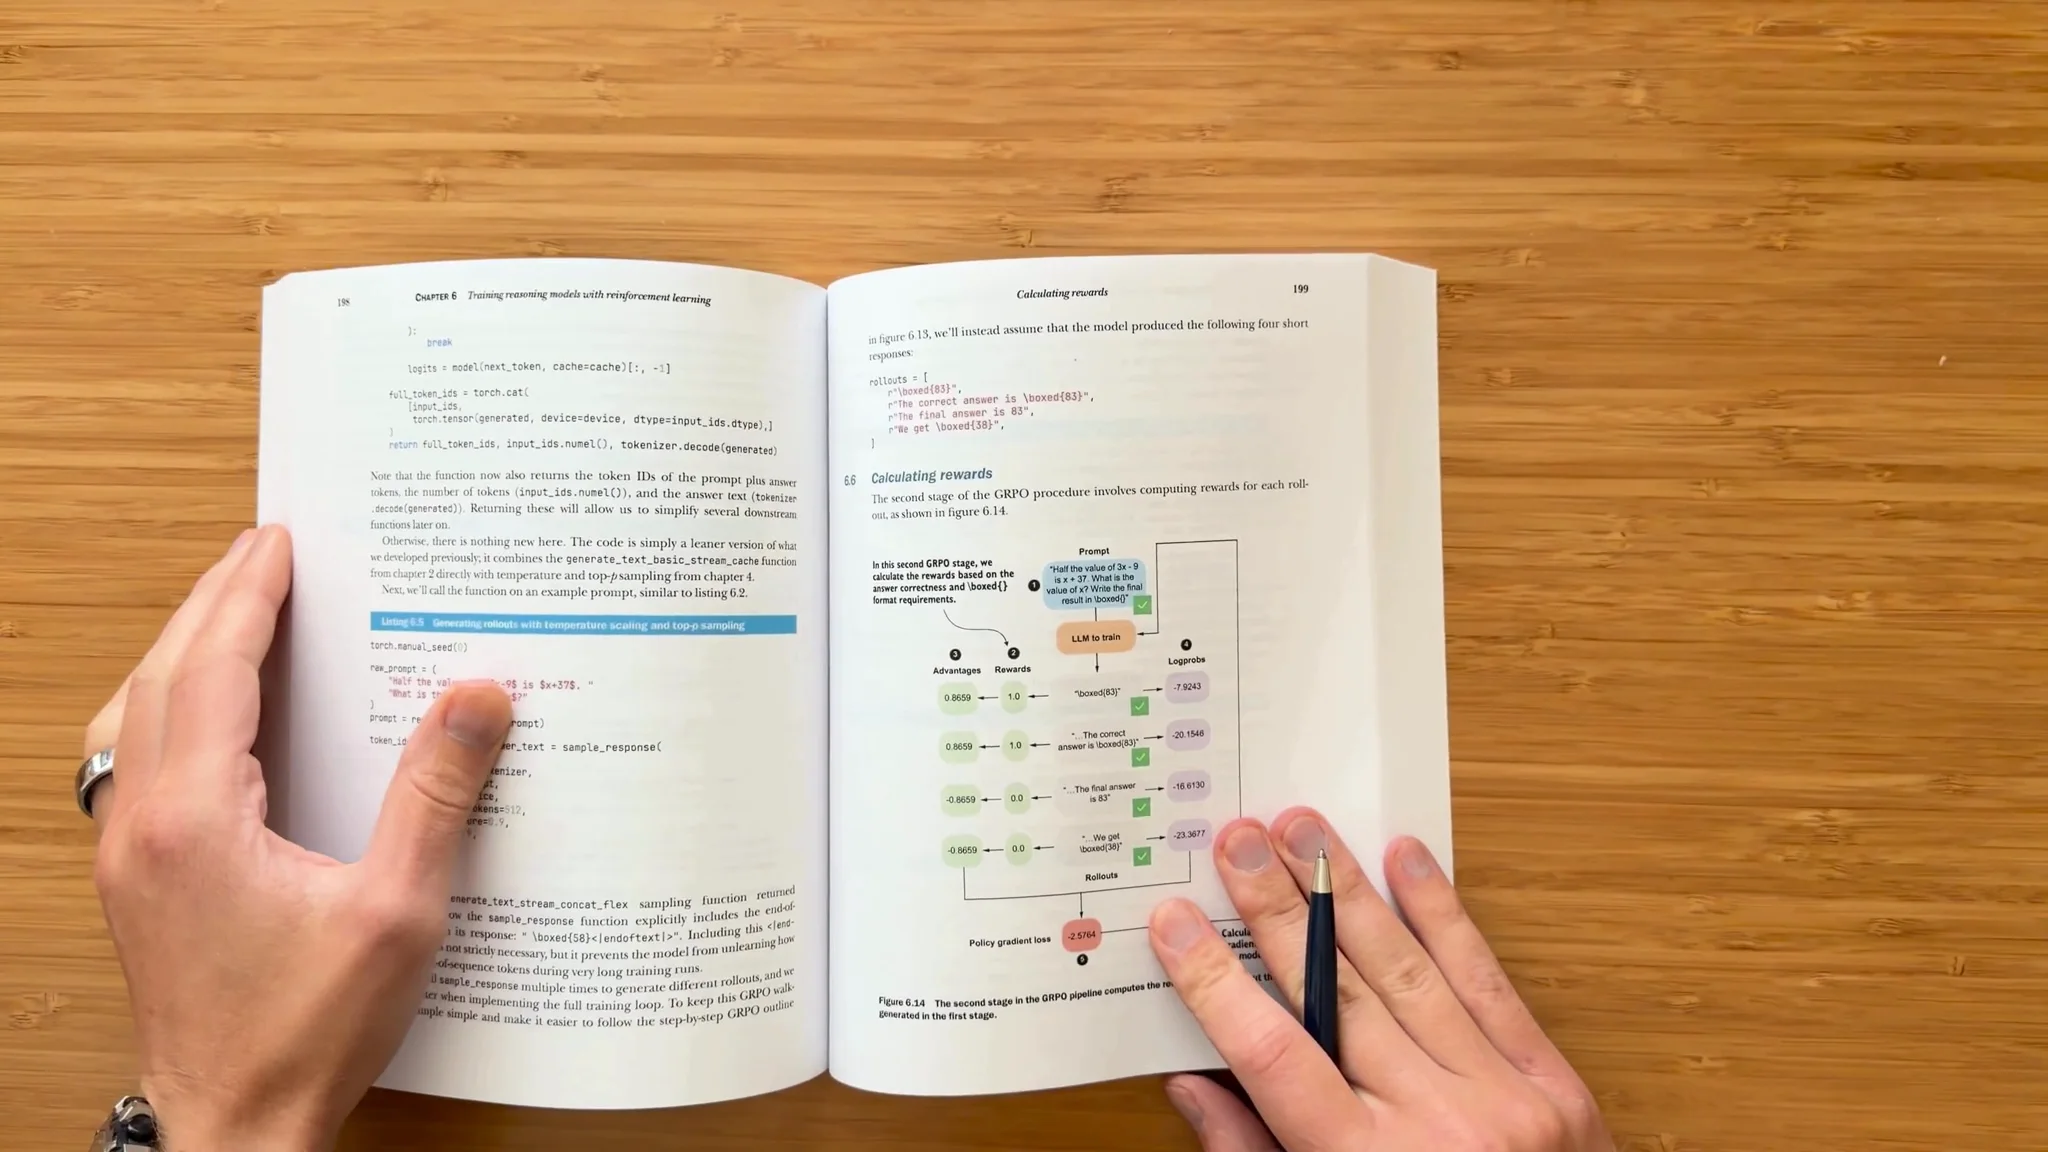
Short correction note for the random seed in Listing 6.5 on page 198 of Build a Reasoning Model From Scratch.
Claude Opus 5 is trying to be the best of both worlds. On many practical tasks, Opus 5 is pitched as straight up as good or better than Fable 5, whil…
Models are improving quickly, but the cheaper options are often good enough.
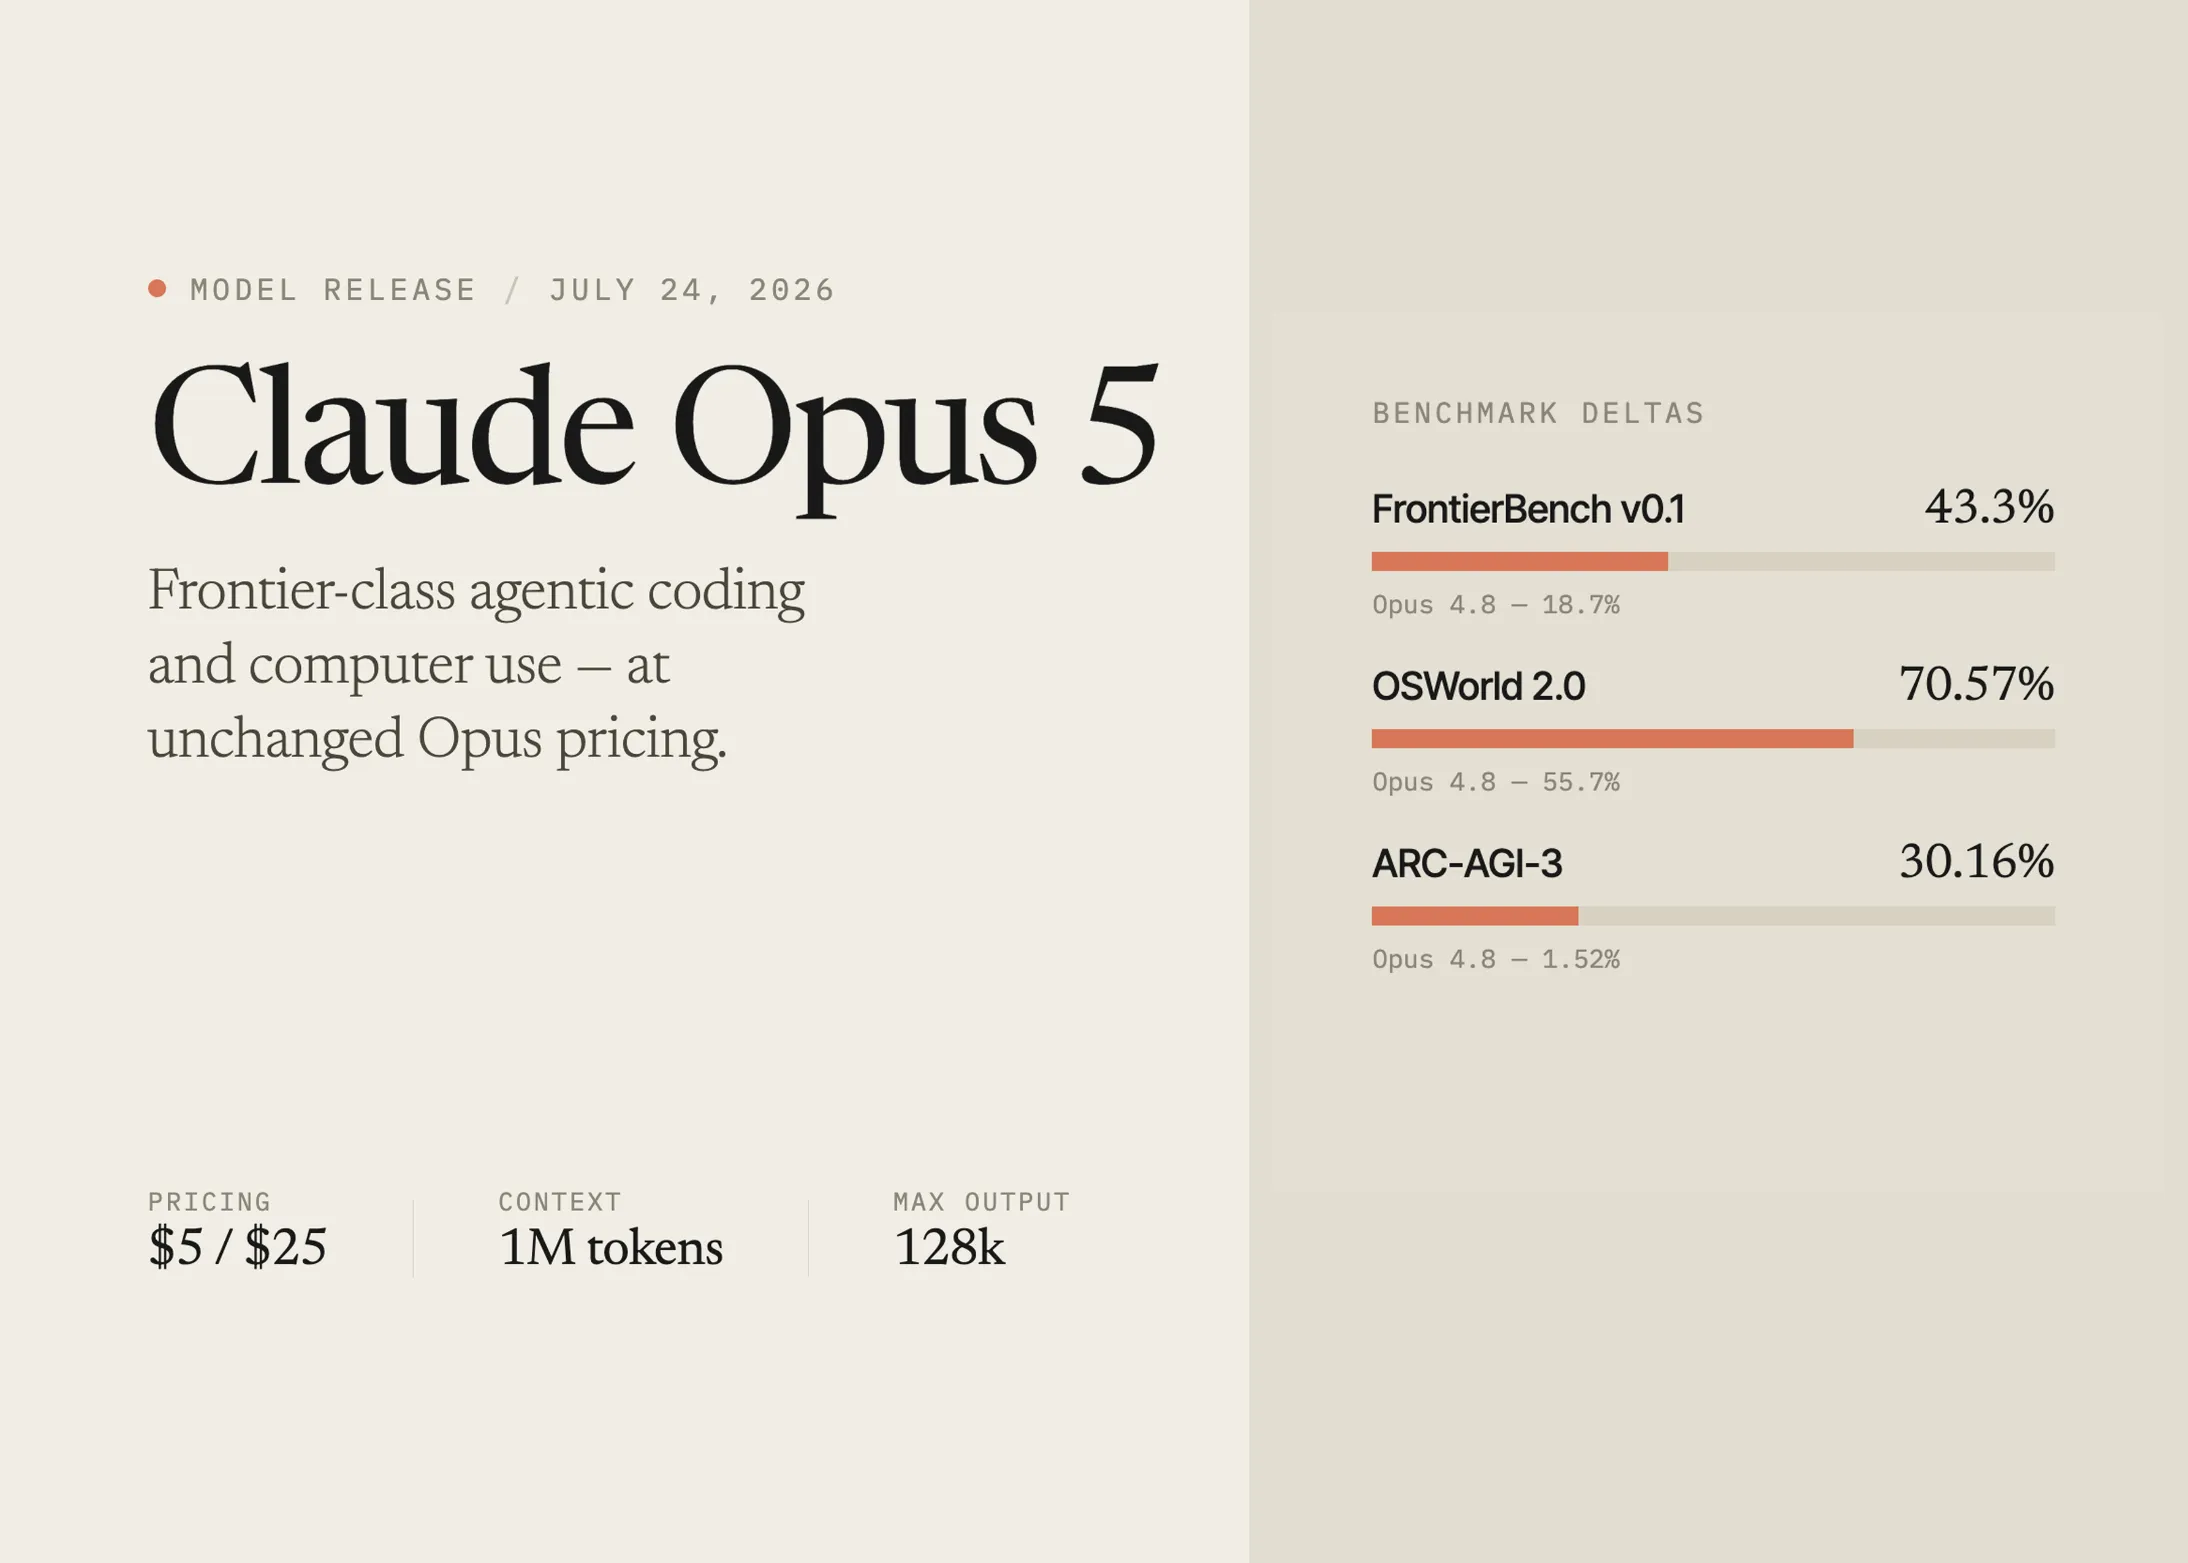
Anthropic released Claude Opus 5 with 1M token context, unchanged $5/$25 pricing, and state-of-the-art agentic coding benchmarks
Anthropic on Thursday released Claude Opus 5, a model that matches or exceeds its flagship Fable 5 on most coding and knowledge-work benchmarks at half the token price. The model is the fourth Anthropic has shipped in under two months, following Fable 5 in early June, Sonnet 5…
Behavioral differences and prompting patterns for Claude Opus 5, covering response verbosity, agentic narration, task scoping, subagent delegation, self-correction, and output artifacts when thinking is disabled.
Language model tokenization at GB/s

Unconventional AI has unveiled an experimental image-generation model that replaces conventional calculation-heavy computing with a simulated network of physical oscillators.
To generate an image, the system assigns different oscillator phase patterns to categories such as shoes or trains. A smaller group configured with the desired pattern acts as the prompt and gradually pulls the wider network of randomly positioned oscillators toward the same arrangement.
The system then records the oscillators’ final phases as a numerical grid. A separate decoder converts that grid into pixel values to produce the image.
AI adoption is being hindered by token costs and there being no up-front pricing for AI requests lea ...

Everyone is worried about Chinese models, but the frontier labs will be fine; we need to enable open U.S. alternatives.

Compare the best local LLMs that fit a single 24GB GPU in 2026 — Qwen, Gemma, Mistral, and DeepSeek and more analysis in detail

How many AI safety papers are at the big ML conferences, what do they study, and who writes them? A comprehensive analysis. > Website: https://ai-saf…
Scaling LLMs isn’t about adding GPUs. It’s about removing wasted work from every request.
Reducing Output Tokens Aggressively
Measuring the Right Latency Metrics First
According to new Anthropic research, Claude consistently expresses different values across models and languages.
We measured what Claude Code and OpenCode spend before reading your prompt, then added instruction files, MCP servers and subagents to the bill.
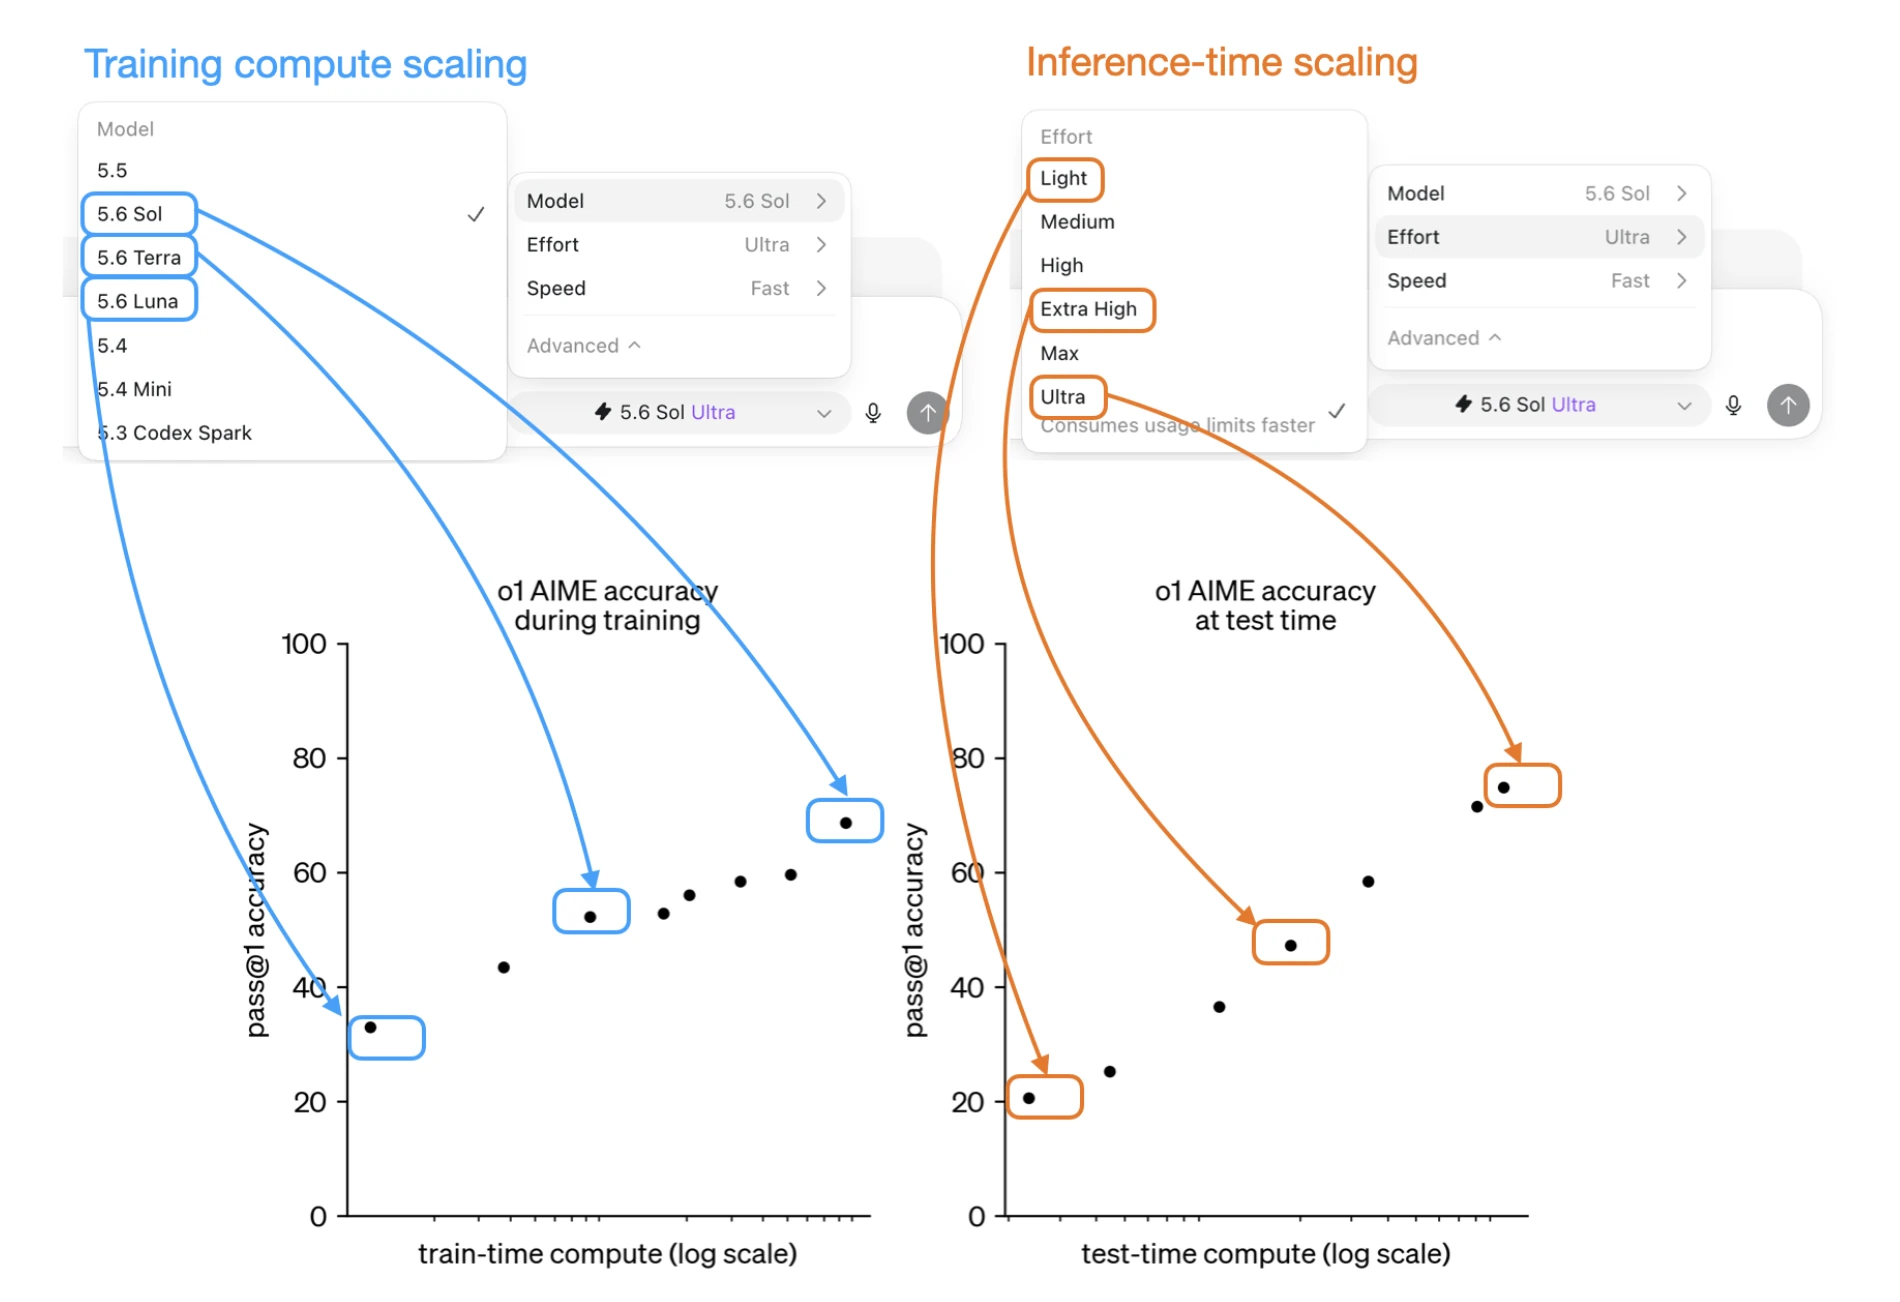
Short note on how GPT 5.6 model and effort choices map onto training-time and inference-time scaling, producing 72 configurations.
Ollama makes open models effortless to run locally on a laptop or in the cloud with the same experience. 8.9m developers, 67,000 integrations, & partnerships with every major model lab & hardware vendor. Theory led the Series B.
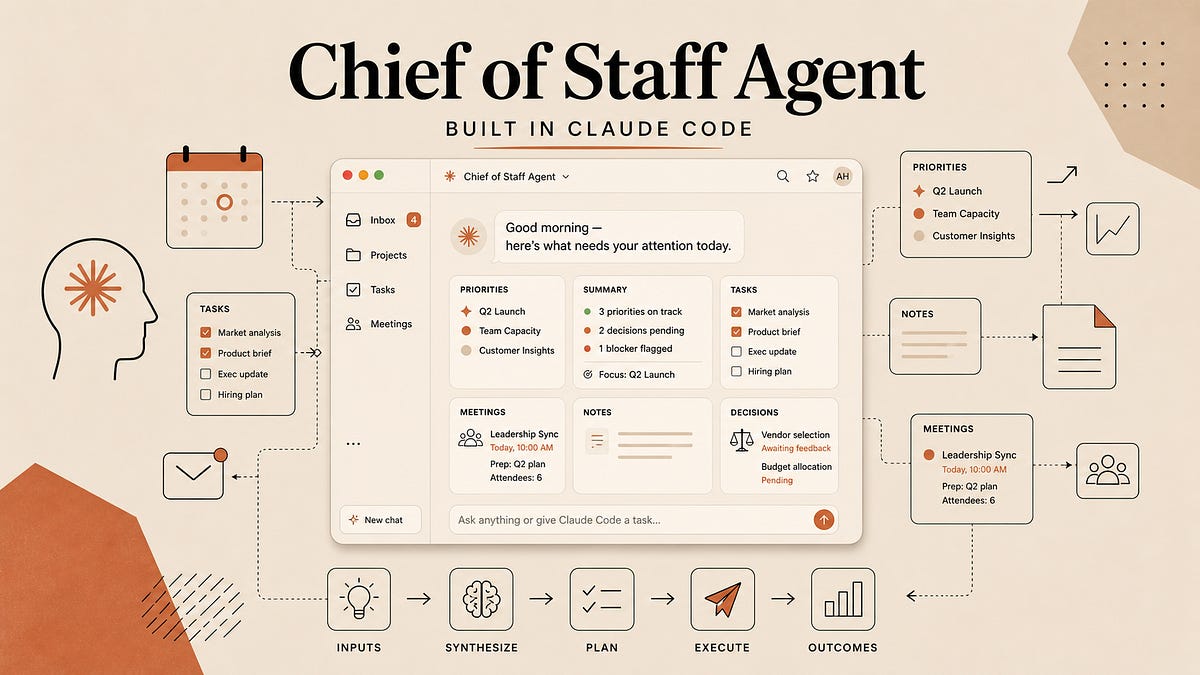
PS. It works in Claude Cowork too. Here’s the 3-step build.

Compare open-source document extraction models for structured PDF-to-JSON in 2026, covering schema-driven extraction, document parsing
Schema-driven extraction takes a document and a JSON schema, then returns values for your fields. Use it for invoices, forms, contracts, and receipts, where you know the fields in advance.
Document parsing reconstructs the document itself. It detects layout, reading order, tables, formulas, and code, then exports JSON or Markdown
One of the most interesting tips I got from the Fireside Chat I hosted with Cat Wu and Thariq Shihipar from the Claude Code team at AIE on Wednesday was …
Our most agentic Sonnet yet, with top-tier intelligence for coding and everyday professional work.
I have spent forty years watching this industry, and I know a permission slip when I see one.

DSpark can make decoding faster, but acceptance quality still determines how much speed the system actually realizes.
Freed from intelligibility and aesthetics, AI designs faster
A University of Chicago study changed how I think about AI and information edges. Then a second paper on AI made it worse.
OpenAI and Broadcom introduce Jalapeño, a custom AI chip built for LLM inference to improve performance, efficiency, and scale across AI systems.

We expose a surprising failure of generalization in auto-regressive large language models (LLMs). If a model is trained on a sentence of the form "A is B", it will not automatically generalize to the reverse direction "B is A". This is the Reversal Curse. For instance, if a…
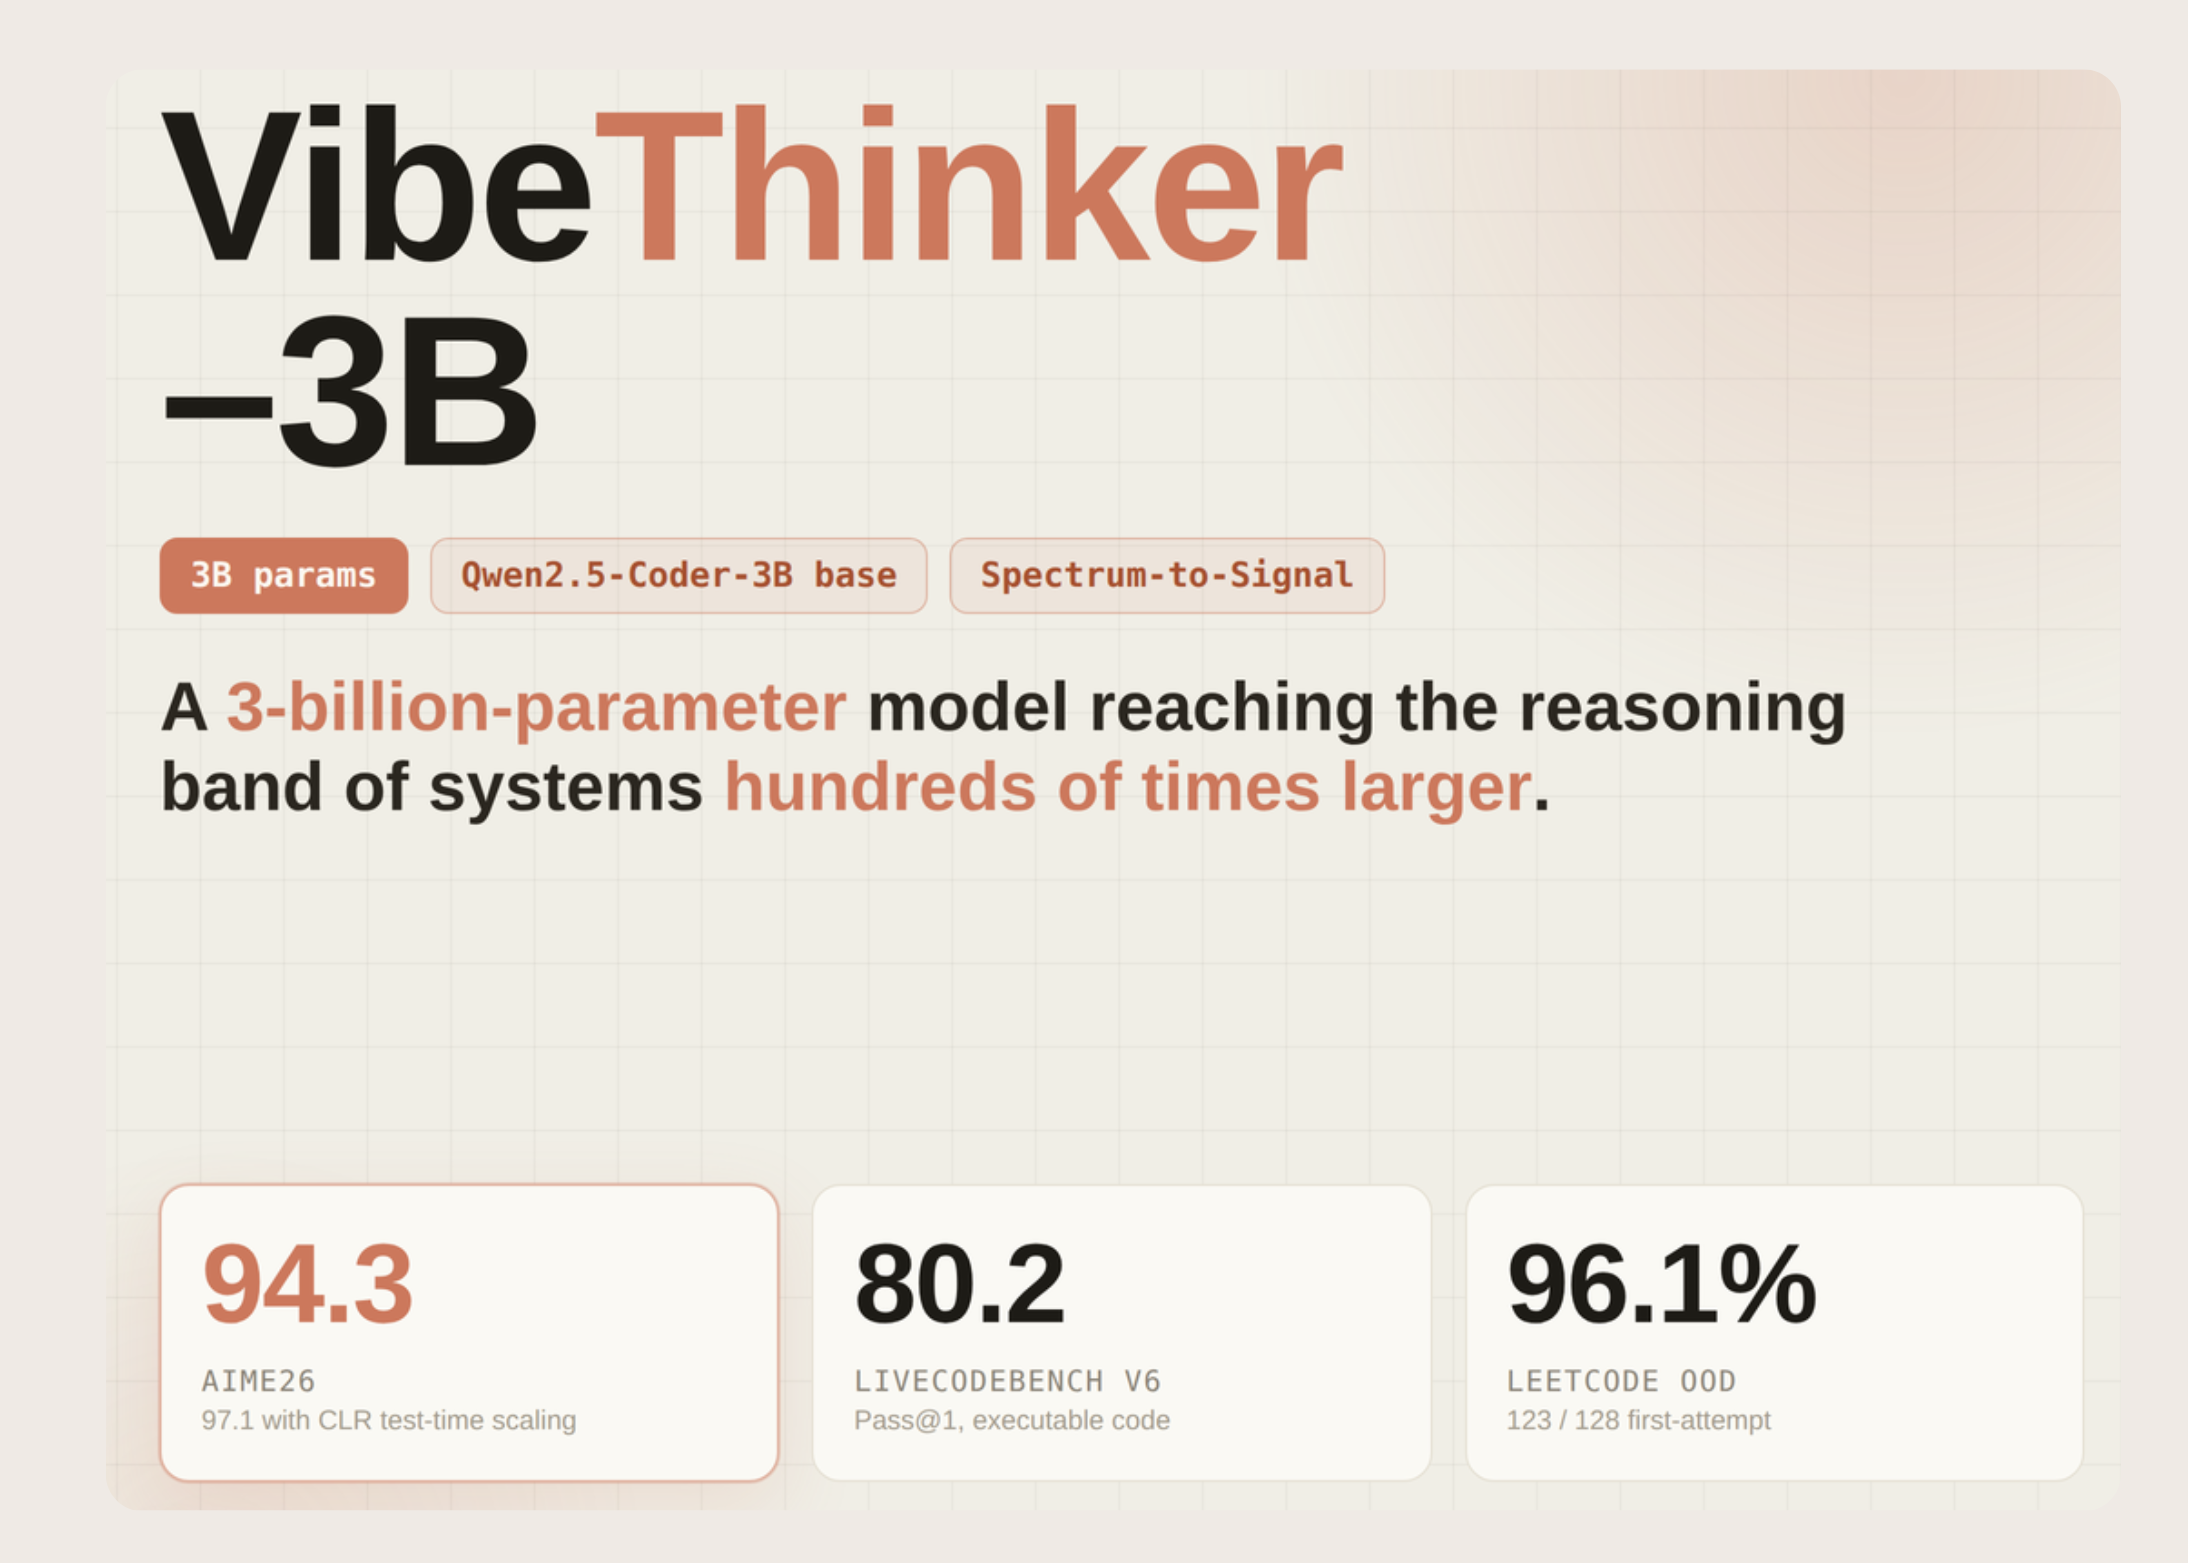
Weibo AI's VibeThinker-3B is a 3B open-source reasoning model scoring 94.3 on AIME26 and 80.2 on LiveCodeBench v6
Spectrum-to-Signal Principle (SSP)
Anthropic’s belief in its own commitment to safety gives the company license to aggressively favor its business and even challenge the U.S. government.
Install Ollama on Ubuntu, run large language models locally, manage downloaded models, use GPU acceleration, and send prompts through the local API.
ChatGPT helps you get answers, find inspiration, and be more productive.
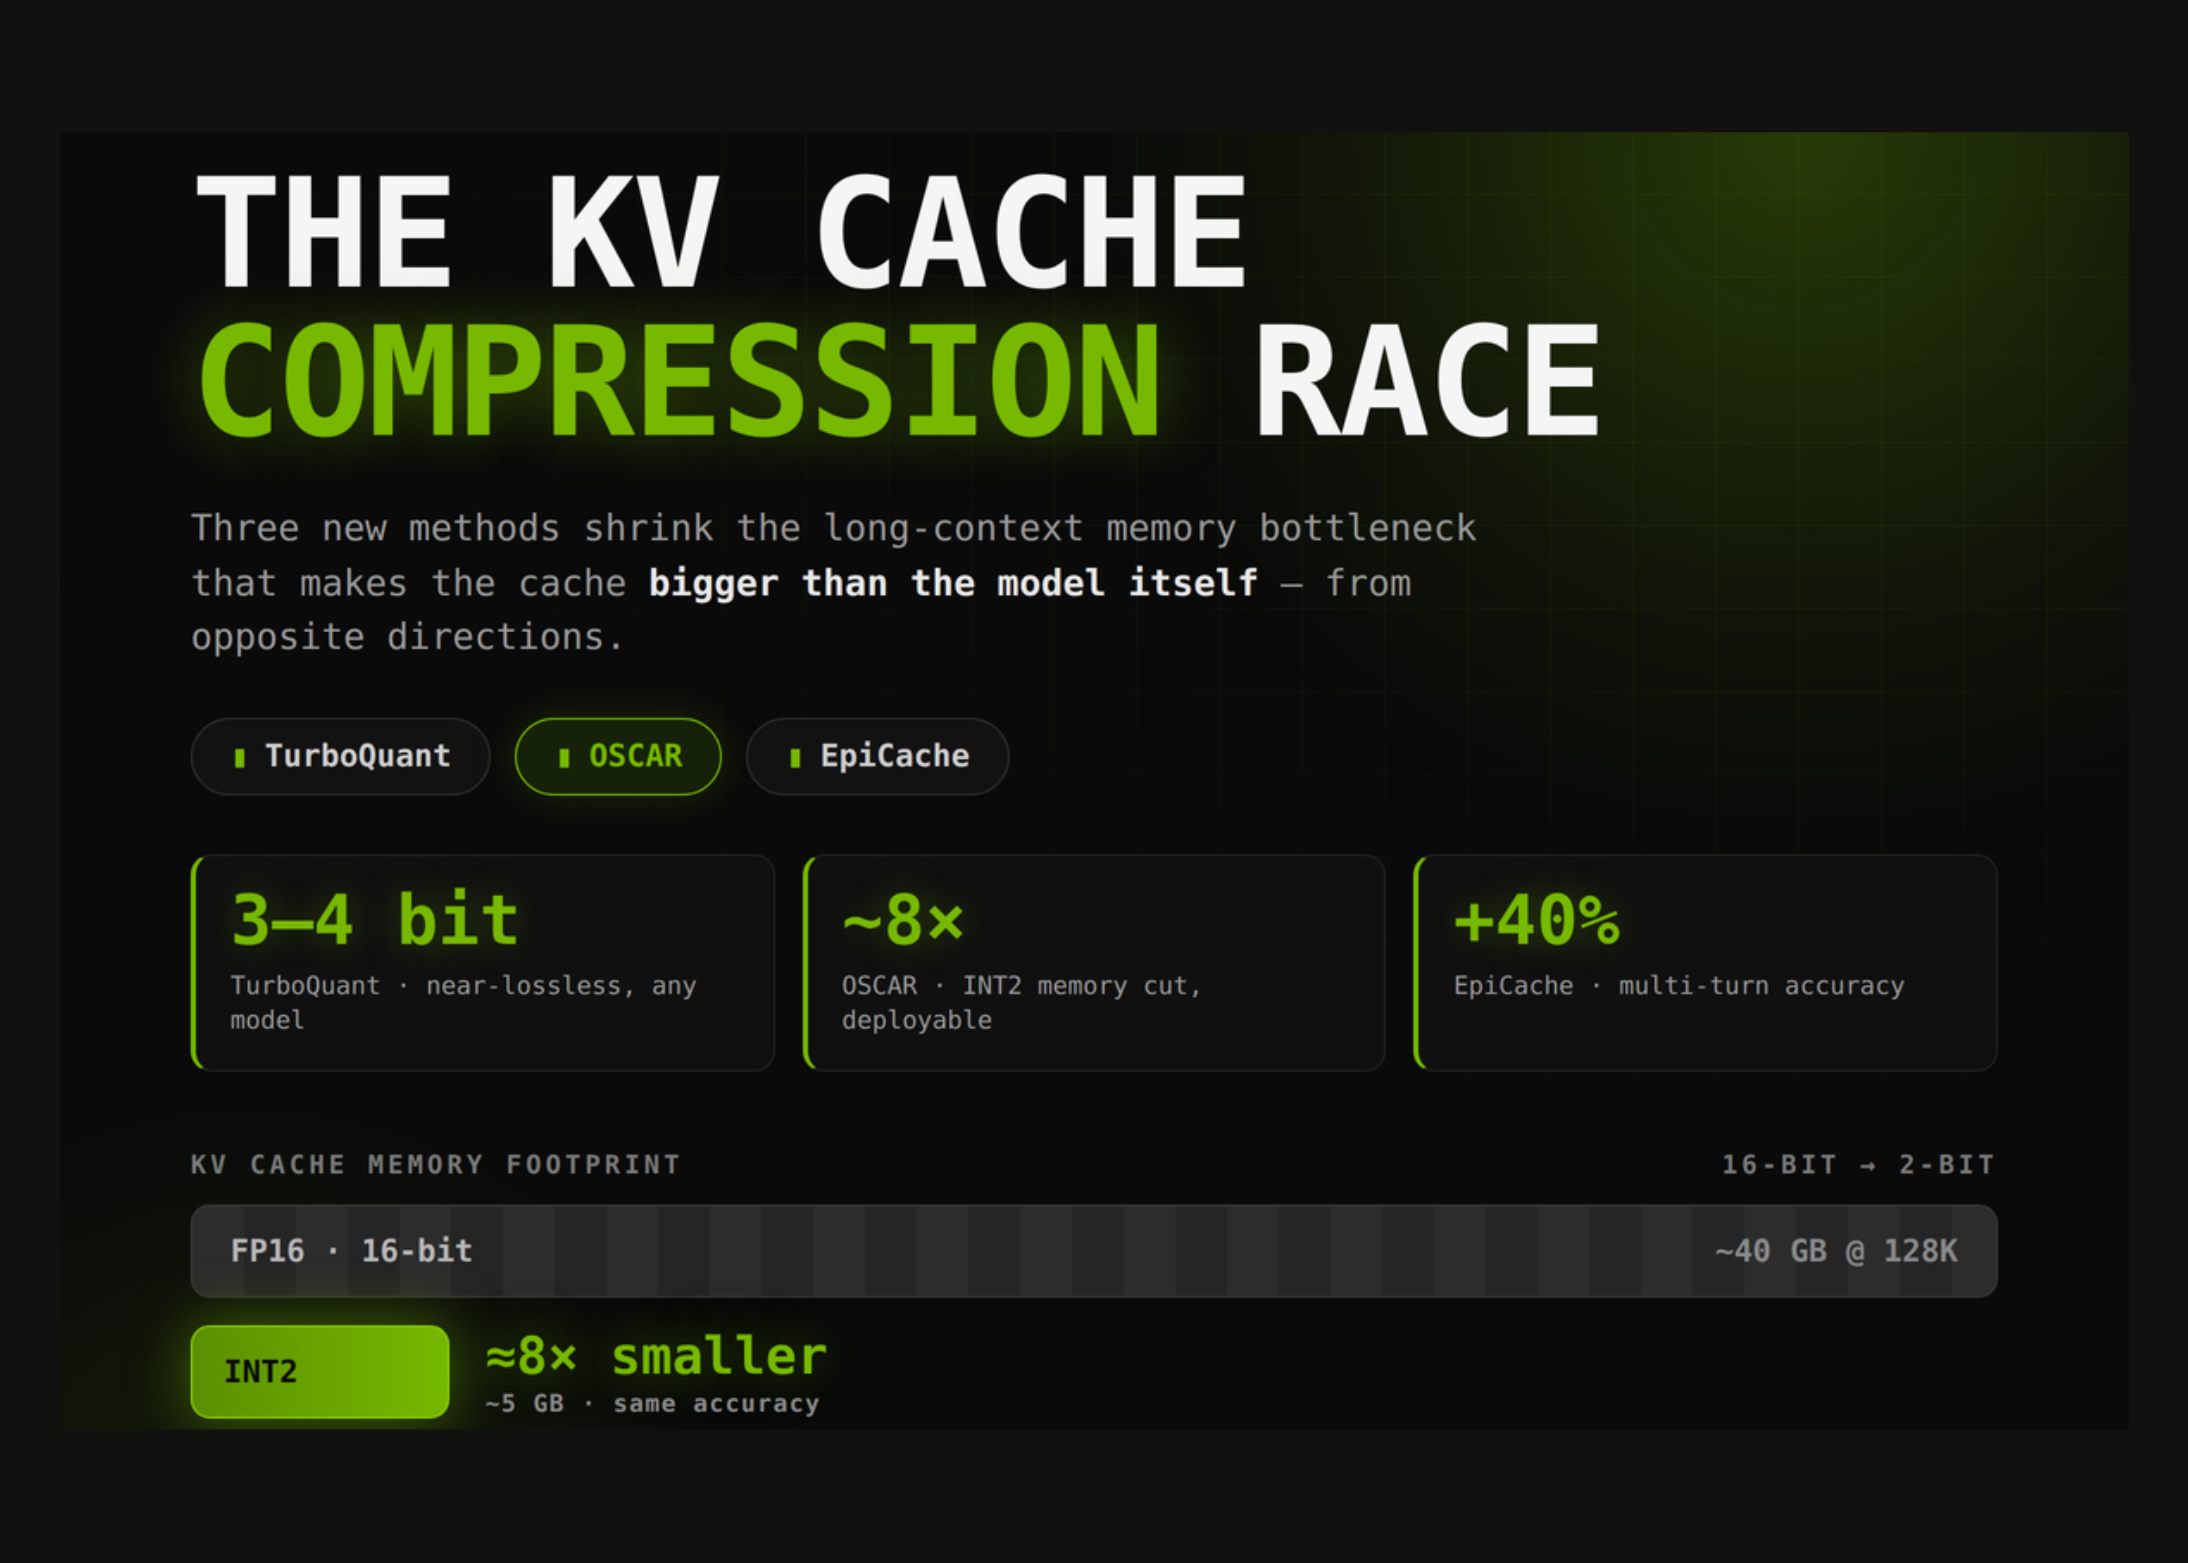
Compare TurboQuant, OSCAR, and EpiCache: three 2026 methods compressing the LLM KV cache to cut long-context memory cost
Chinese AI lab Z.ai released GLM-5.2 to their coding plan subscribers on June 13th, and then yesterday (June 16th) released the full open weights under an MIT license. Similar in …
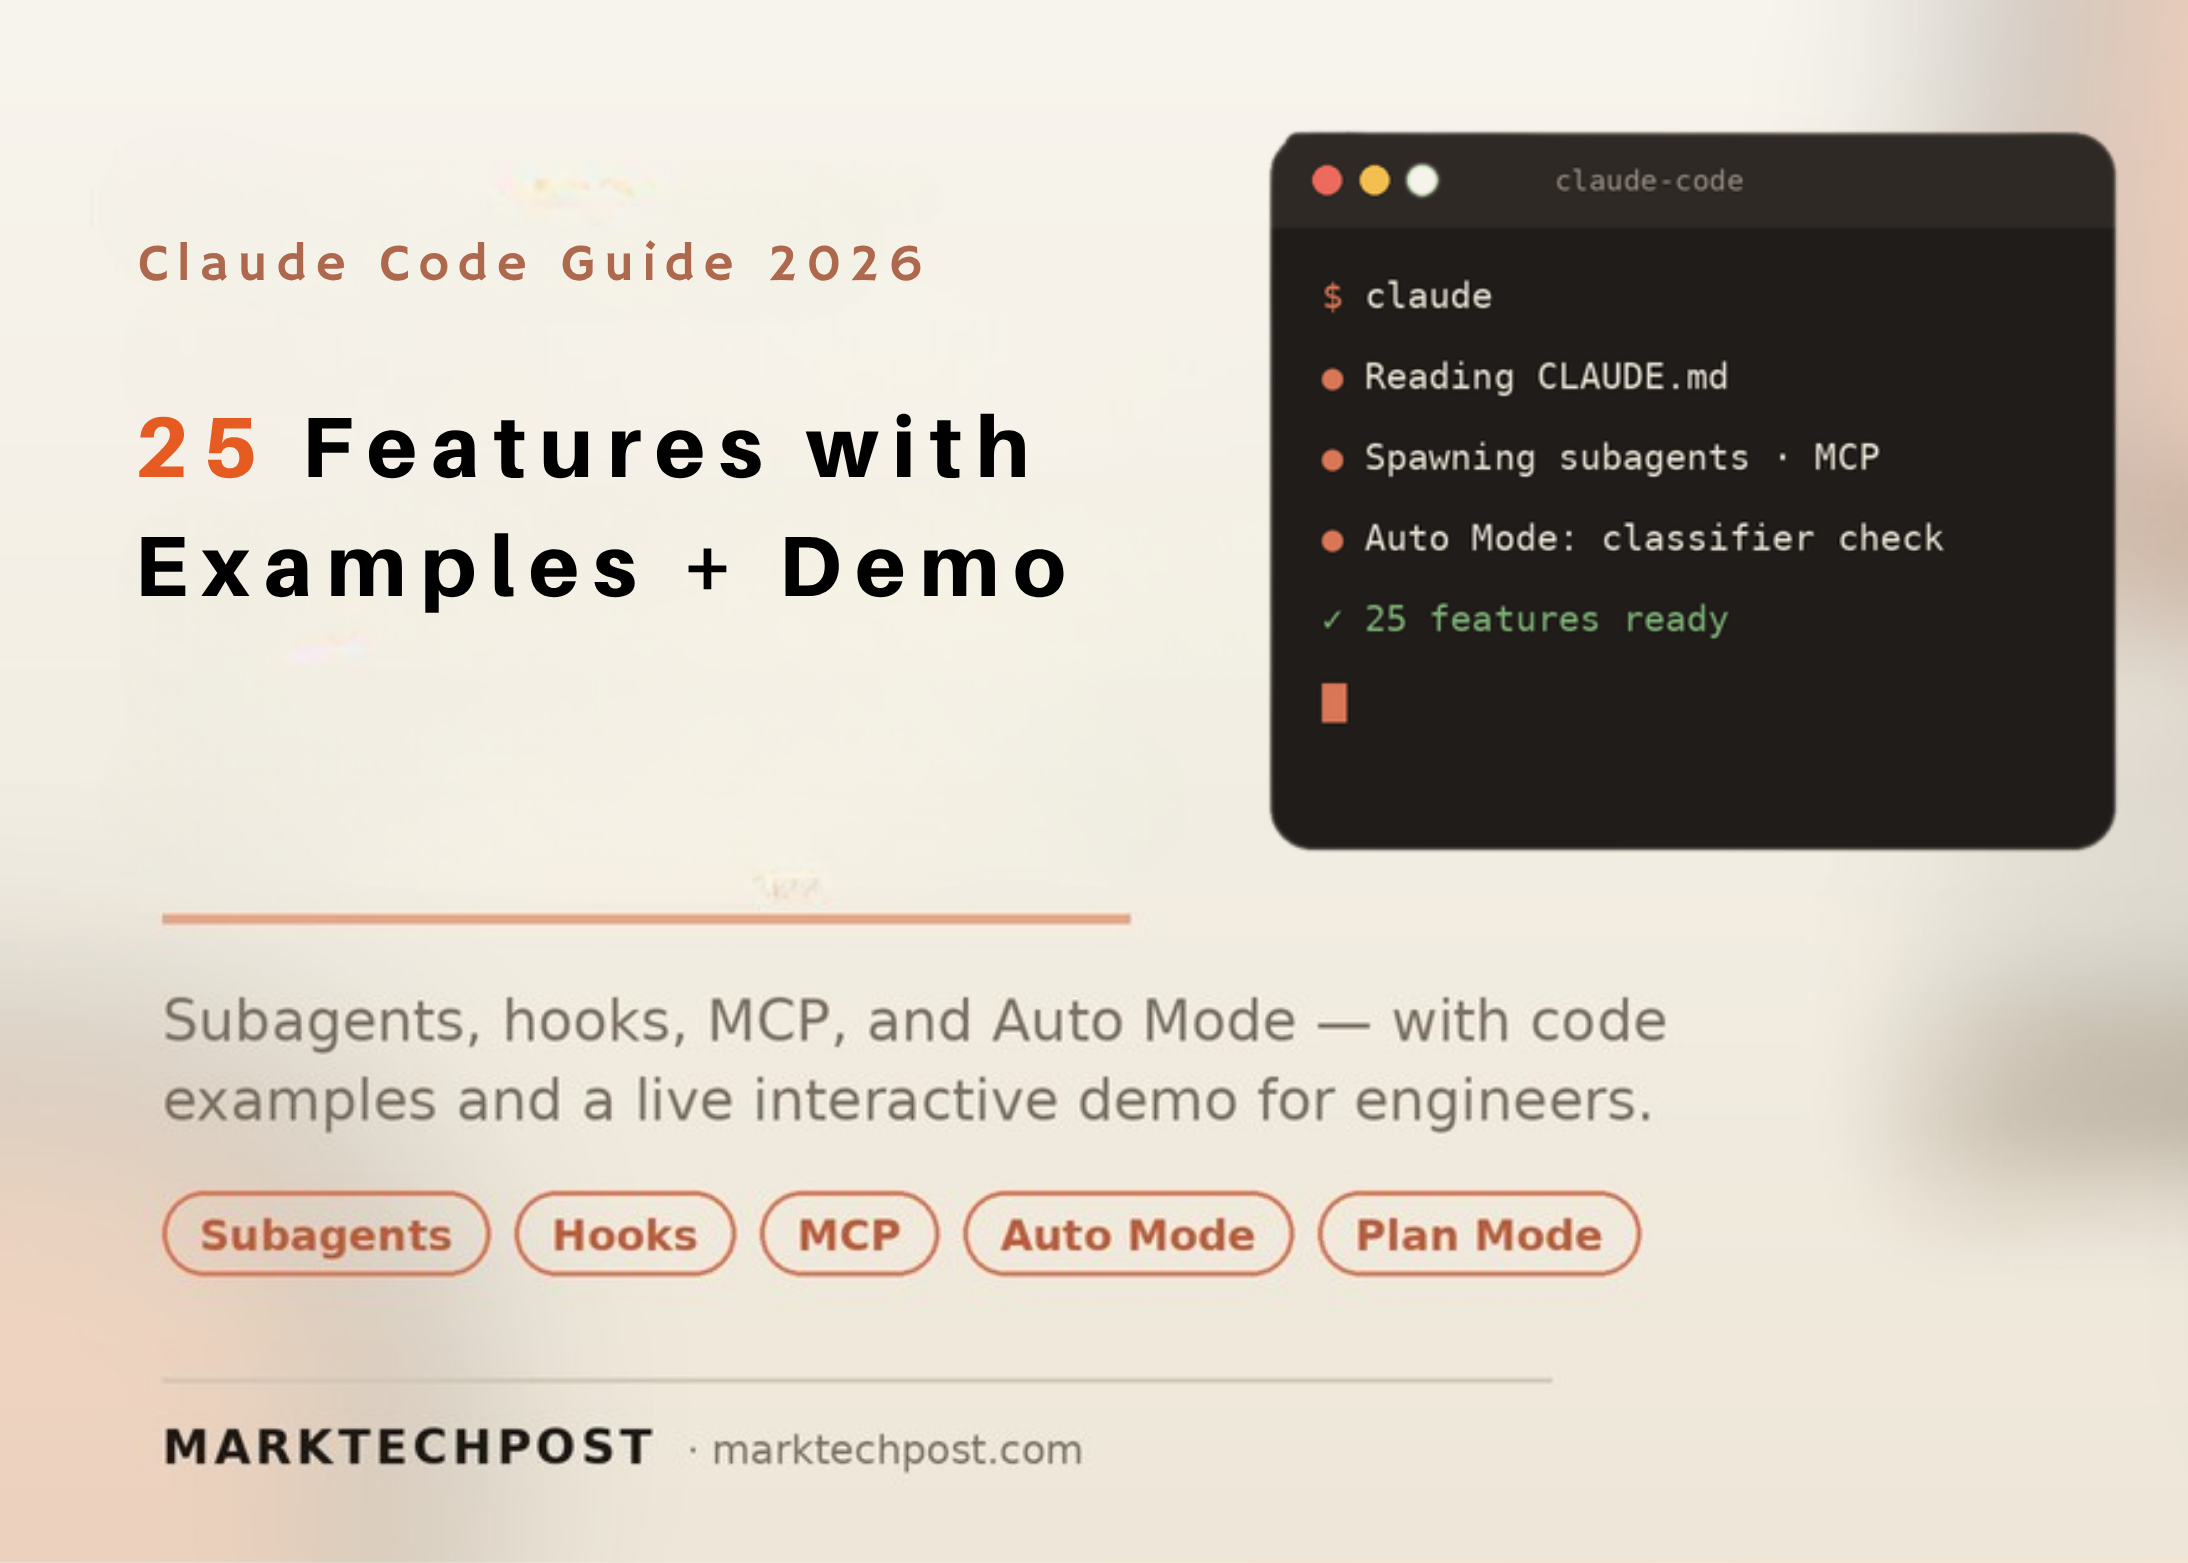
Claude Code explained: 25 features and strategies, including subagents, hooks, MCP, and Auto Mode, with examples and demo.
Skills
CLAUDE.md
Sapient researchers trained a 1B reasoning model on just 40B tokens — scoring competitively with 2B-7B models at a fraction of typical pretraining cost.
Today we’re launching Claude Fable 5: a Mythos-class model that we’ve made safe for general use.
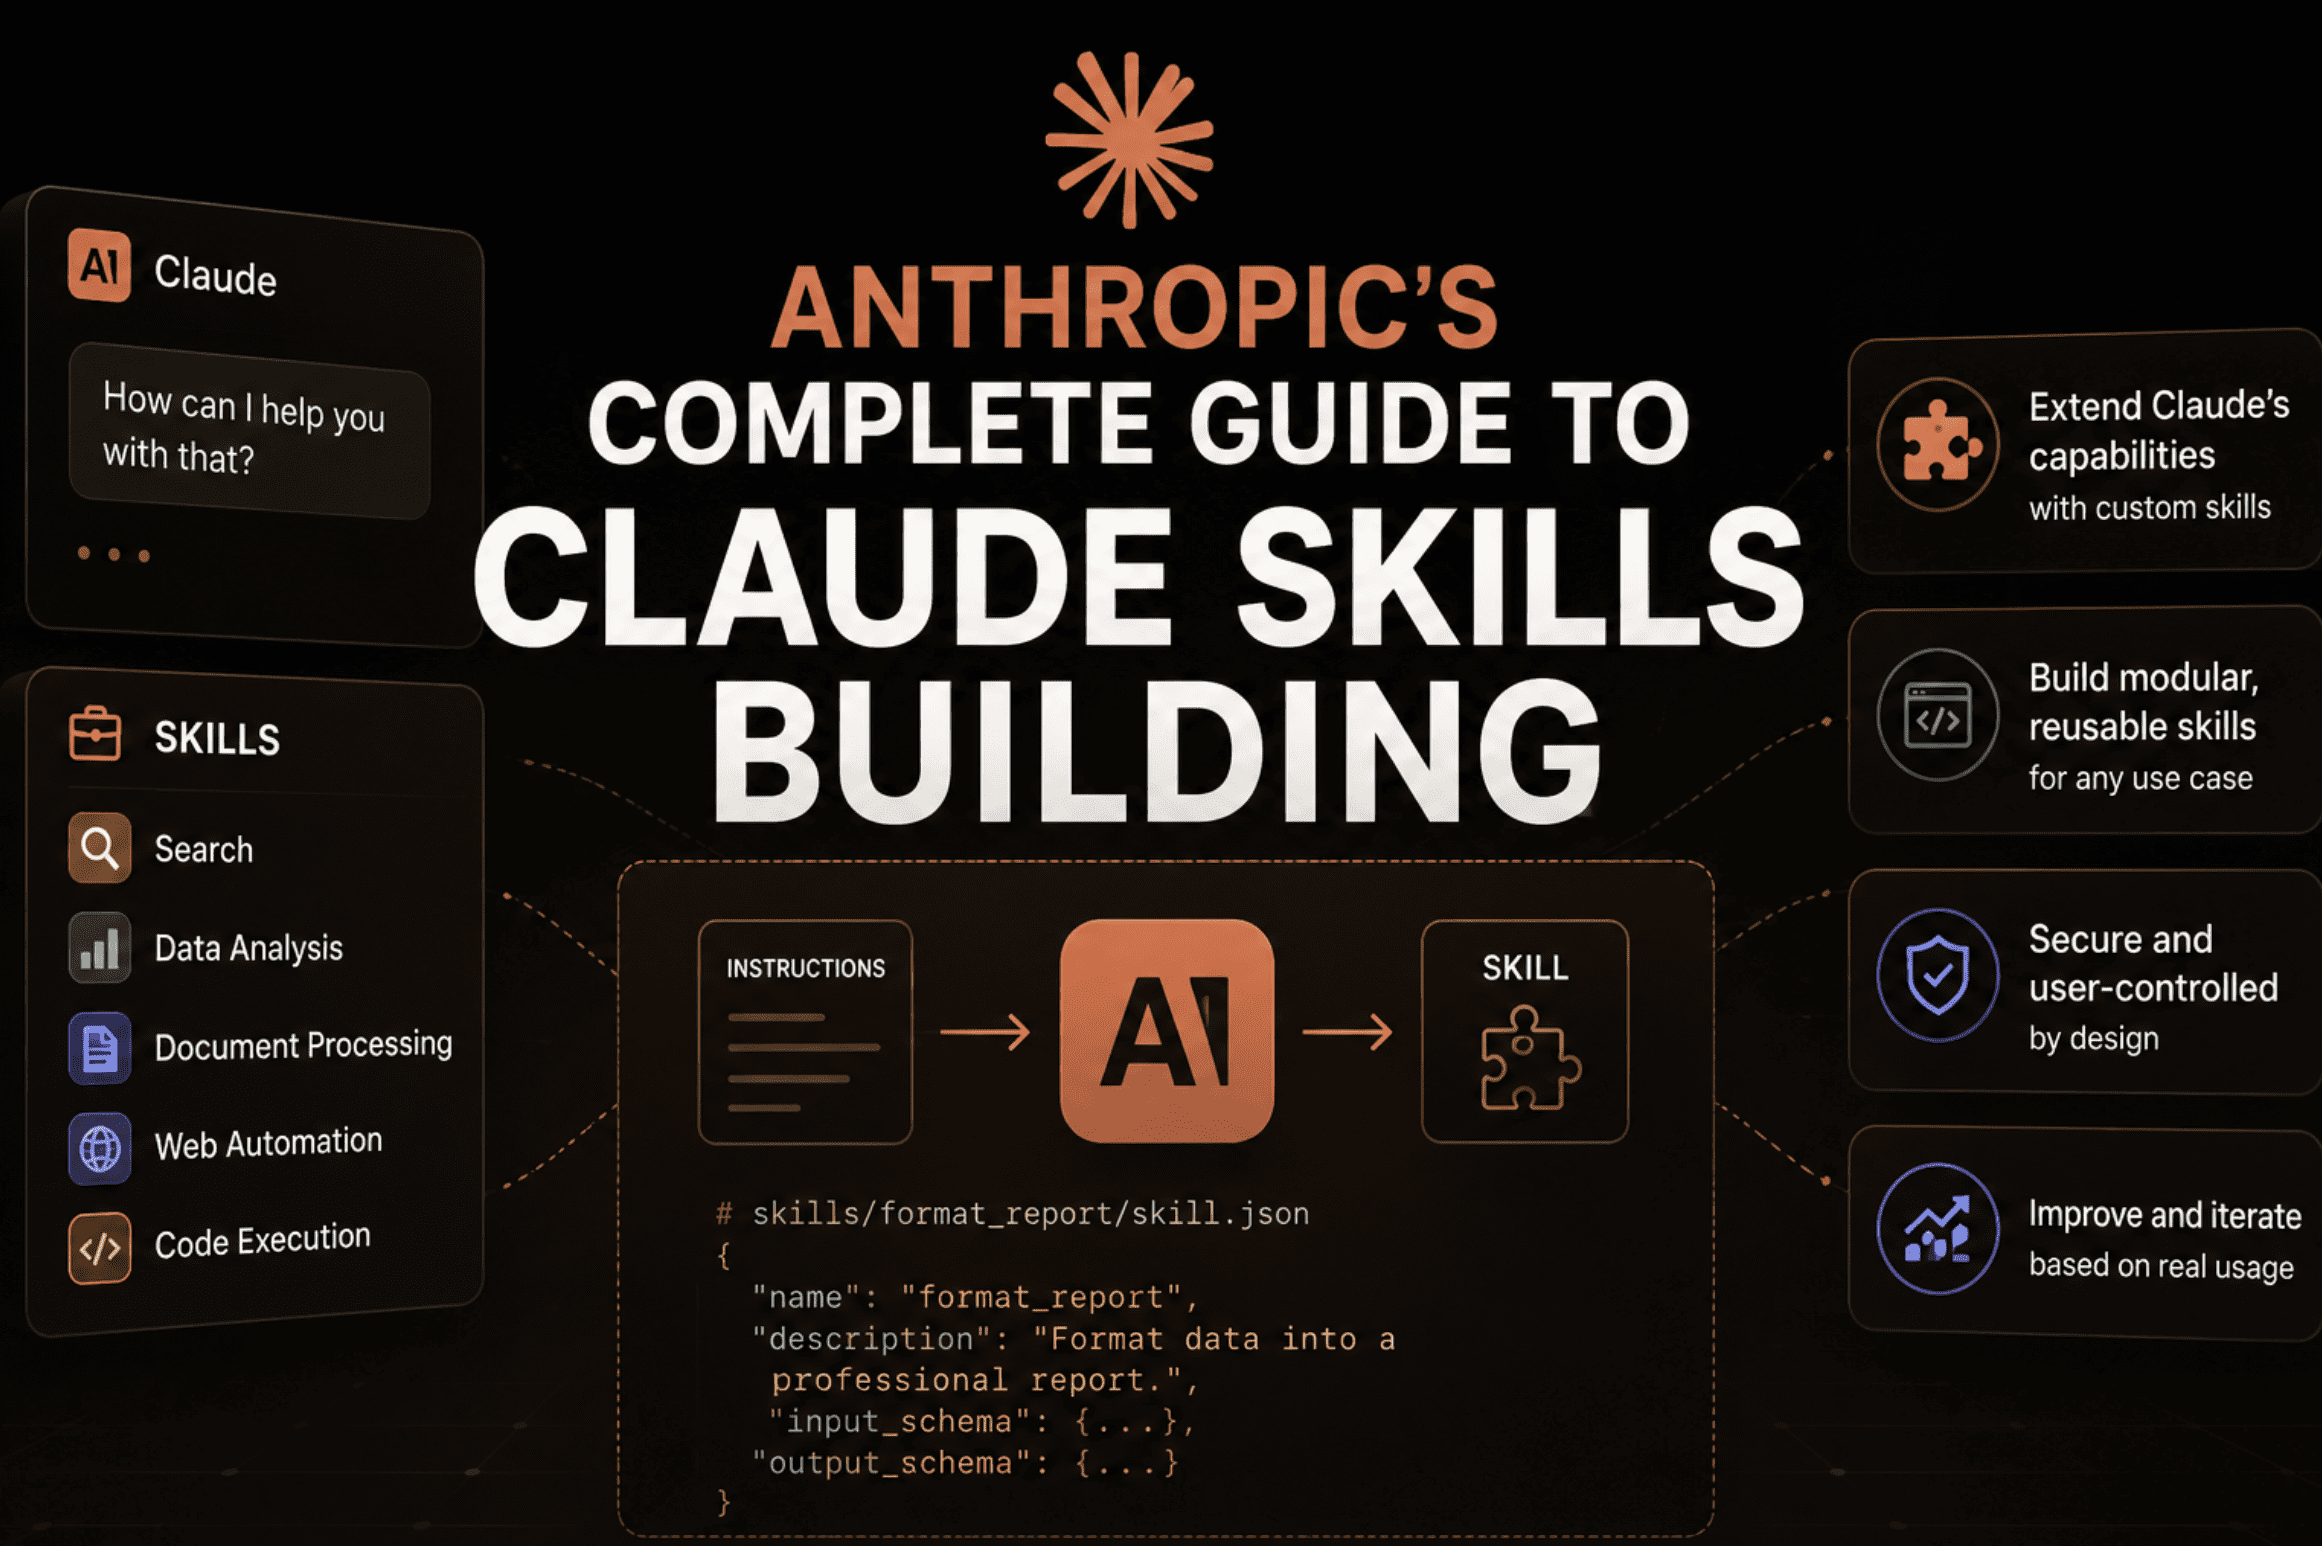
This guide covers the complete picture: what skills are technically, how to plan and design them, the exact file structure and naming rules, how to write instructions that Claude follows reliably, a complete working skill built from scratch, how to test and distribute, and what…
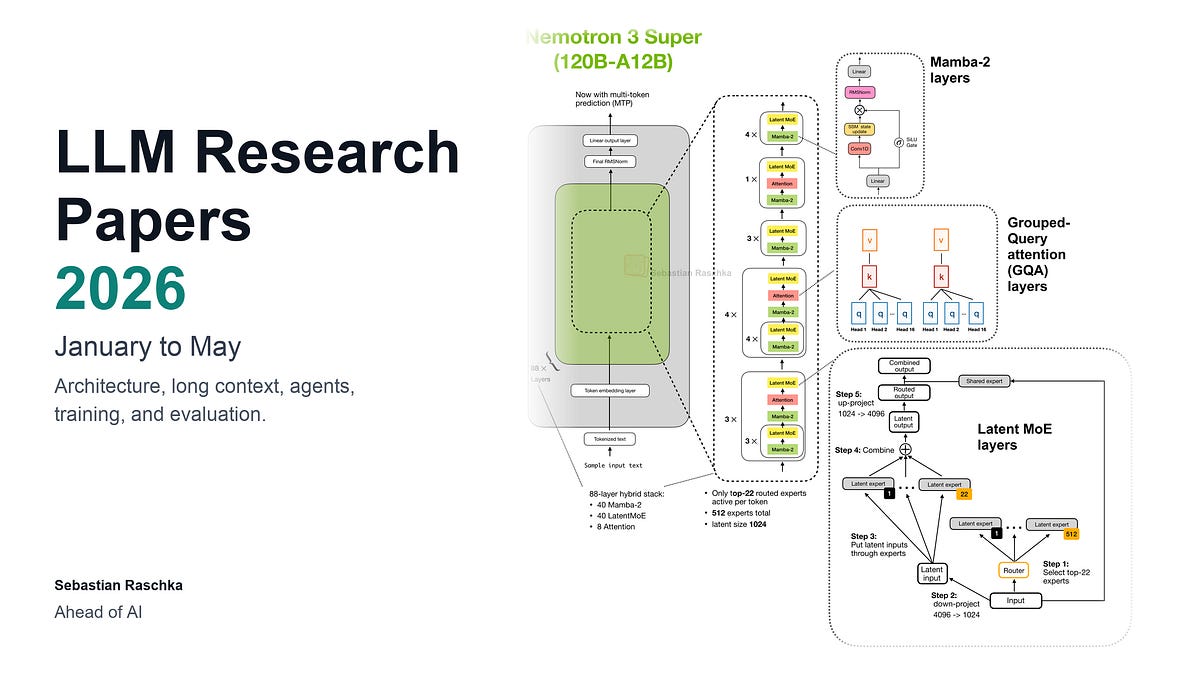
A January-May 2026 list of notable LLM research papers, covering new models, training methods, agents, reasoning, and efficiency improvements.

In this article, I’ll go over the open-source LLMs you should know and when to use them. All Open-Source LLMs to know.
Conversations, turns, rounds, tools, agents and more!

According to benchmark platform Artificial Analysis, Nvidia's new Nemotron 3 Ultra is the most capable open AI model from the US to date.
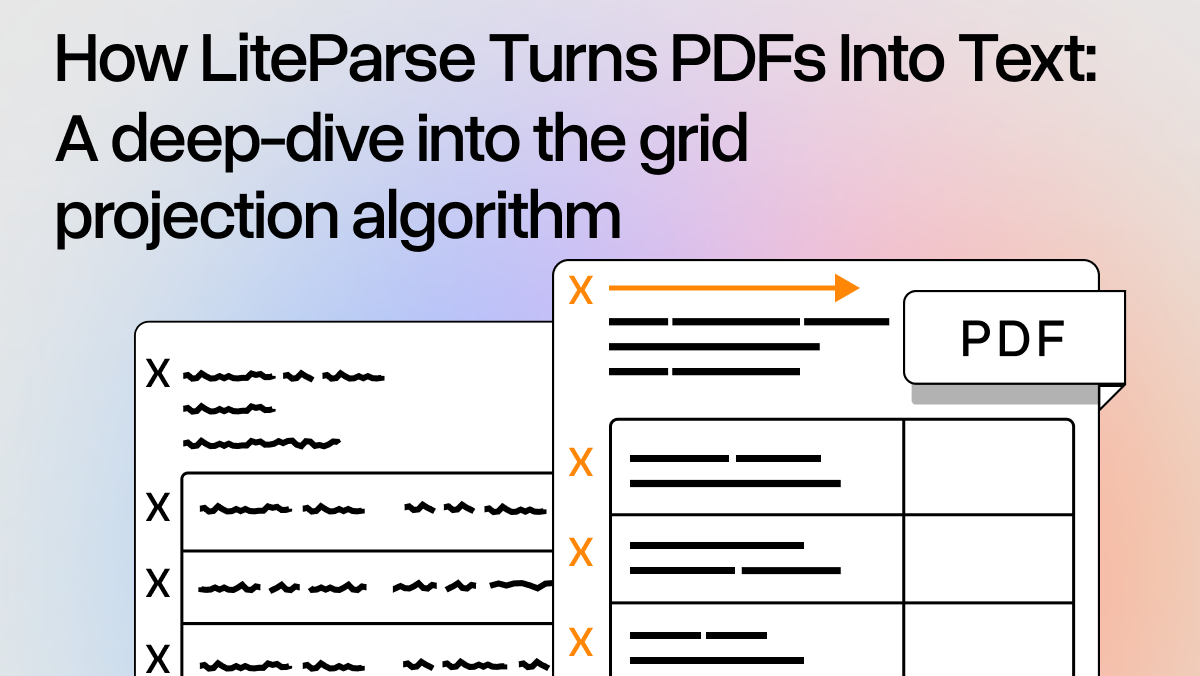
A deep dive into LiteParse's grid projection algorithm — how it extracts text from PDFs while preserving tables, columns, and alignment. Open source.