llms
903 bookmarks · page 3 of 19
2026-05-27 · arps18.github.io
A deep dive into Claude Code for daily users. Covers the .claude directory, CLAUDE.md the way Boris writes it, CLAUDE.local.md, Skills with real examples, custom subagents, plugins, underused commands like /goal and /insights, MCPs, and the workflow patterns the Anthropic team…
The daily driver uses it like a programmable agent with memory, custom commands, parallel sessions, and a project setup that compounds over time
give Claude a way to verify its own work
2026-05-26 · nolanlawson.com

A lot of people seem convinced that the point of AI coding is to write low-quality code as fast as possible. Spew out barely-passable slop, open massive PRs, and merge them unvetted. Ship it! But t…
2026-05-26 · github.com
A curated list of 100+ libraries and frameworks for AI engineers building with LLMs - Sumanth077/ai-engineering-toolkit
2026-05-25 · github.com

A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls. - multica-ai/andrej-karpathy-skills
2026-05-24 · medium.com
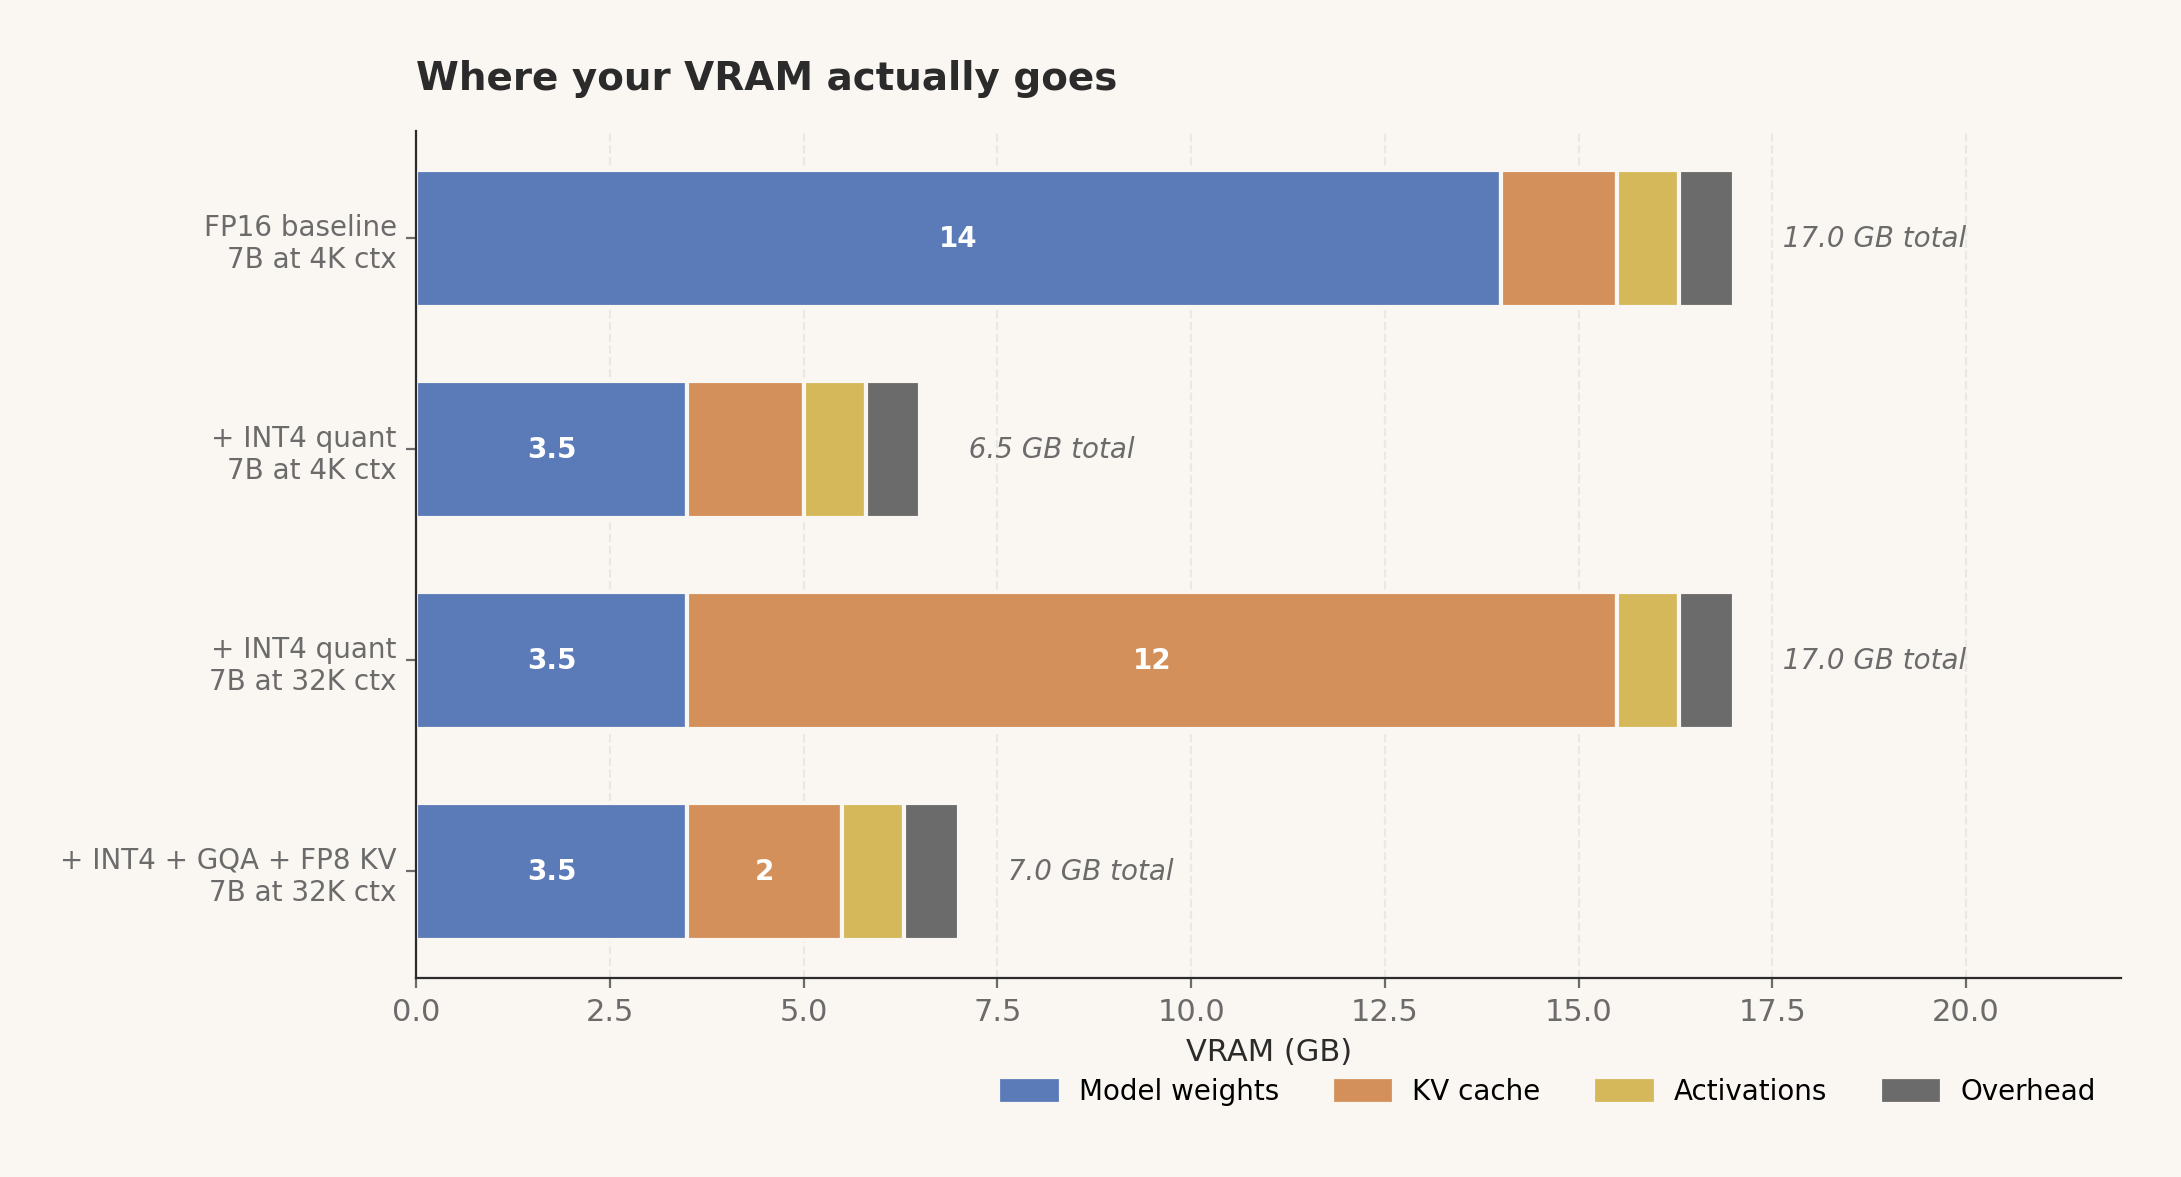
The Practical Guide to LLM Inference on Consumer Hardware A practical walk through quantization, KV caches, Flash Attention, Mamba, MoE, and the runtimes that tie it all together — without the …
2026-05-22 · link.mail.beehiiv.com
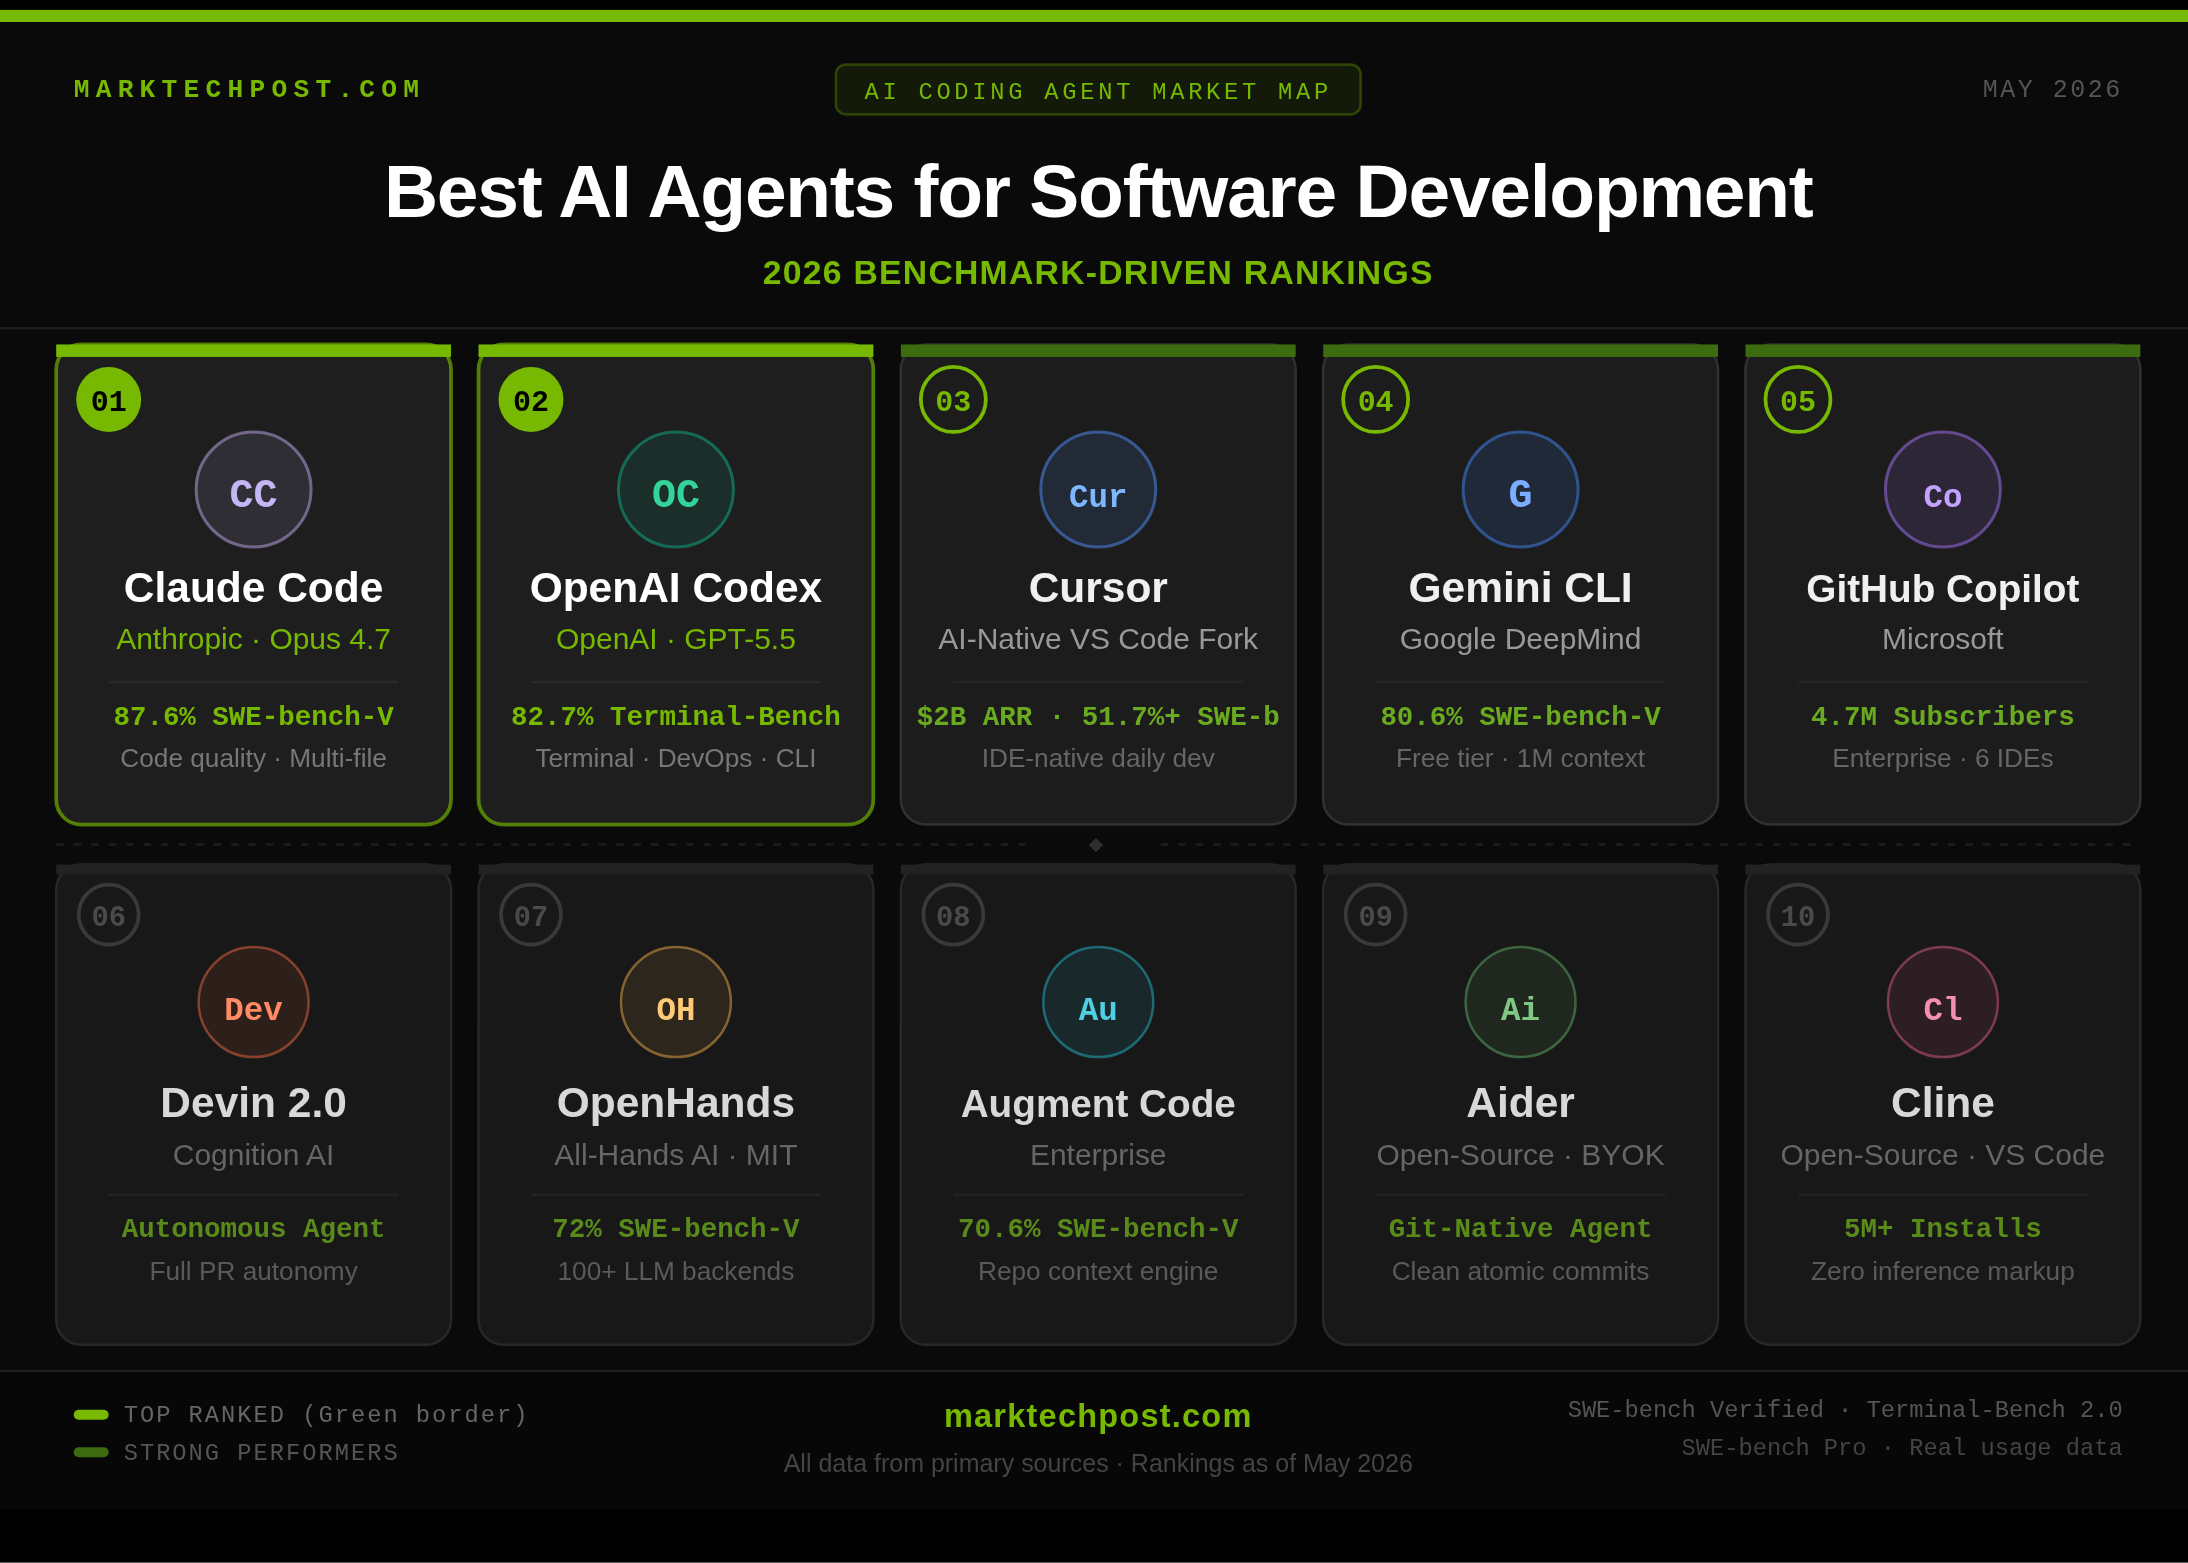
The AI coding agent field in 2026 is more capable, more fragmented, and harder to benchmark than it looks. Claude Code leads on code quality at 87.6% SWE-bench Verified. GPT-5.5 tops Terminal-Bench at 82.7%. But the benchmark OpenAI itself declared contaminated in February 2026…
SWE-bench
stopped reporting SWE-bench Verified
2026-05-22 · marktechpost.com

Alibaba's Qwen3.7-Max is a reasoning agent model with a 1M-token context window, scoring 56.6 on the Artificial Analysis Intelligence Index.
2026-05-21 · substack.com
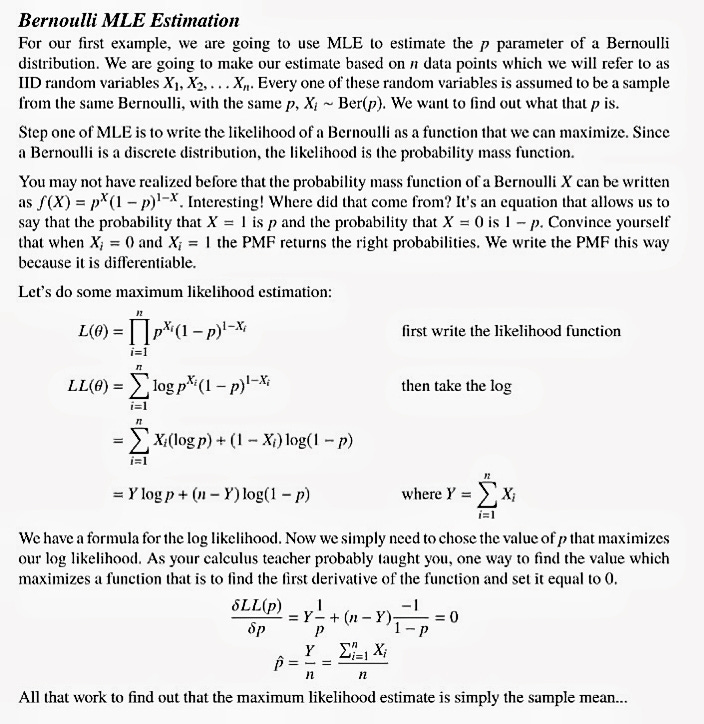
Maximum Likelihood Estimation is the quiet engine underneath almost everything in ML, DL, and RL. Most people learn it once in a stats class and move on. They shouldn't. It's not just a parameter-fitting trick — it's the philosophical foundation of why our models work at all…
2026-05-21 · statology.org

Estimate the Average Treatment Effect in Python using DoWhy with regression and propensity score matching on real data.
2026-05-20 · gist.github.com
llm-wiki. GitHub Gist: instantly share code, notes, and snippets.
2026-05-19 · statology.org

Learn how to build and test causal inference models in Python using the DoWhy library.
2026-05-19 · decrypt.co
Vitalik Buterin said mathematically verified software may help protect cryptographic infrastructures as AI improves both code generation and vulnerability discovery.
2026-05-18 · open.substack.com
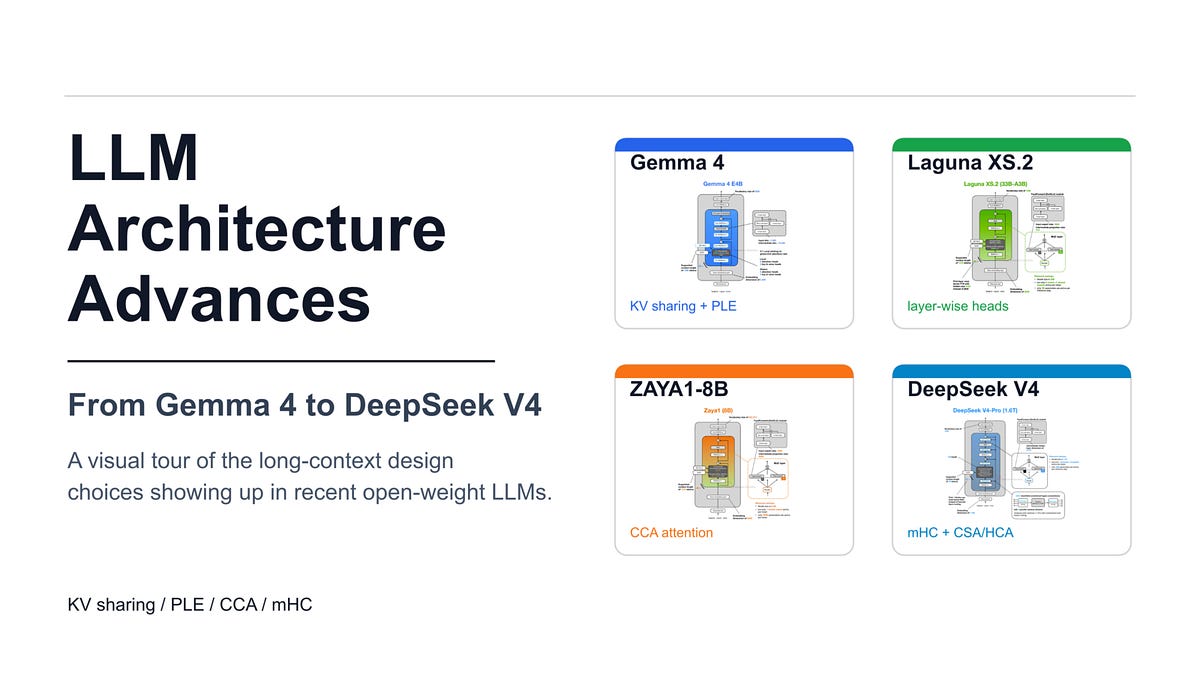
From Gemma 4 to DeepSeek V4, How New Open-Weight LLMs Are Reducing Long-Context Costs
2026-05-18 · blog.cloudflare.com

In recent weeks, we pointed Mythos and other security-focused LLMs at live code across critical parts of our infrastructure. We share what we observed, the models’ strengths and weaknesses, and what the work around them needs to look like before any of it can scale.
2026-05-16 · linkedin.com
6 Open-Source Libraries to FineTune LLMs 1. Unsloth GitHub: https://lnkd.in/gQvPWVFb → Fastest way to fine-tune LLMs locally → Optimized for low VRAM (even laptops) → Plug-and-play with Hugging Face models 2. Axolotl GitHub: https://lnkd.in/g34kuExT → Flexible LLM fine-tuning…
2026-05-16 · magazine.sebastianraschka.com
From Gemma 4 to DeepSeek V4, How New Open-Weight LLMs Are Reducing Long-Context Costs
2026-05-15 · open.substack.com
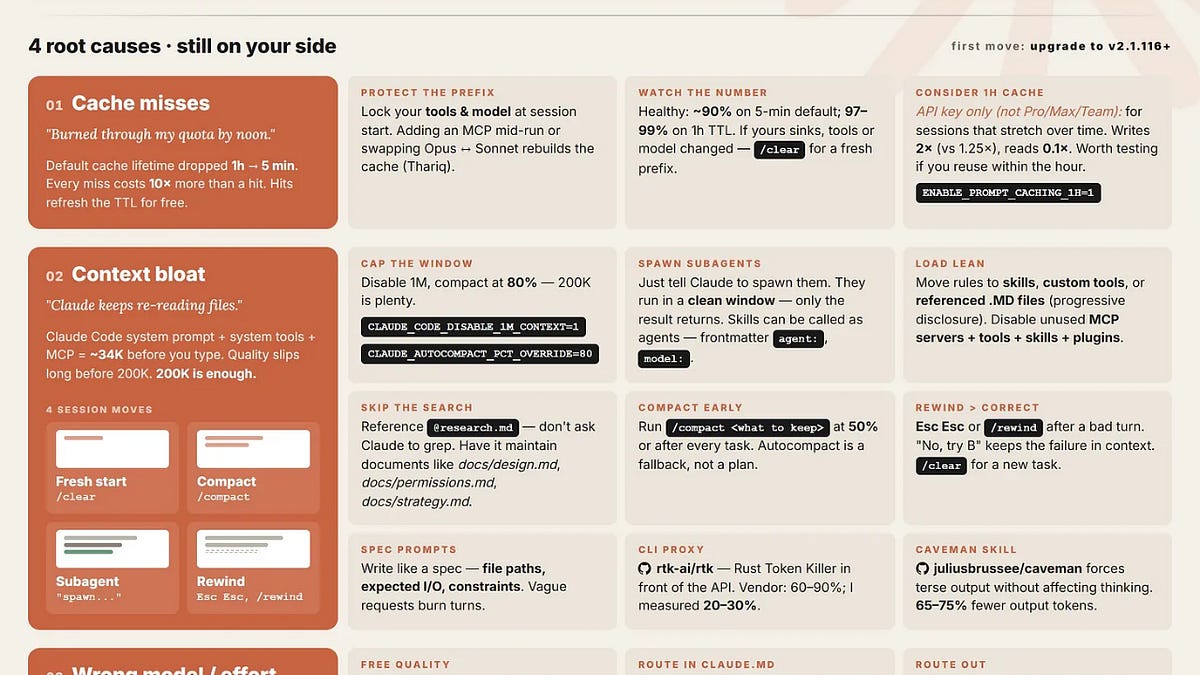
From $1,389/mo to $200/mo on the same workflow. Anthropic fixed 3 bugs. The 4 root causes still on your side — with copy-paste templates.
2026-05-15 · manning.com
Learn how to put Large Language Model-based applications into production safely and efficiently.
2026-05-14 · manning.com
By default, general purpose LLMs are not optimized for specific domains and business goals. Using techniques like specialized fine-tuning, pruning unnecessary neural components, and knowledge distillation, you can rearchitect your models to cost less, run faster, and deliver…
2026-05-14 · venturebeat.com
AI IQ ranks frontier AI models like ChatGPT, Claude and Gemini on the human IQ scale, sparking debate over how artificial intelligence should be measured.
2026-05-13 · marktechpost.com

2026-05-11 · marktechpost.com

Learn how understanding LLM distillation techniques improves model training through innovative teacher-student approaches.
n this article, we will explore three major approaches used for training one LLM using another:
2026-05-11 · reddit.com

Explore this post and more from the ClaudeAI community
2026-05-09 · thenewstack.io

Subquadratic has launched a new AI architecture featuring a 12-million-token context window that outperforms GPT-5.5 on retrieval benchmarks.
2026-05-08 · amanxai.com

In this guide, I’ll show you how to build a Text-to-SQL app that takes your questions and uses AI to translate them.
2026-05-08 · amanxai.com
In this article, I’ll show you how to turn any CSV file into an AI chatbot using Python. Turn Any CSV into an AI Chatbot with Python.
2026-05-08 · venturebeat.com
Anthropic has launched “dreaming” for AI agents, giving Claude new self-improving tools designed to boost enterprise automation, reliability, and scale.
2026-05-06 · venturebeat.com
Miami startup Subquadratic says its SubQ model could make AI 1,000 times more efficient and handle 12 million tokens, but researchers remain divided over whether the breakthrough is real.
2026-05-05 · amanxai.com

Learning to use LlamaIndex for RAG apps isn’t just about memorizing APIs. It’s about understanding how data moves through the system.
2026-05-03 · marktechpost.com
Analyzing Tokenization Drift: Using Token Overlap Metrics to Identify Out-of-Distribution Risks and Optimizing Prompts
2026-05-01 · linkedin.com
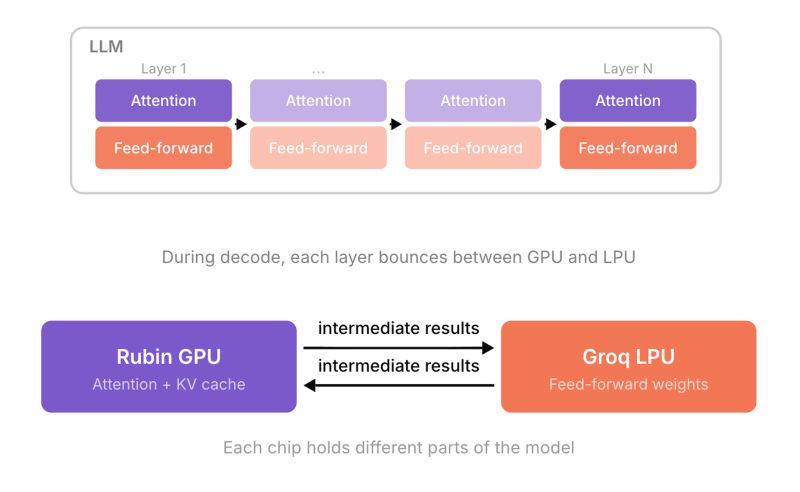
why did NVIDIA cancel the Rubin CPX and replace it with a Groq LPU? LLM inference has two phases. prefill processes the whole prompt at once and is compute-bound. decode generates one token at a time and is memory-bound, reading the full model weights and KV cache for every…
2026-05-01 · venturebeat.com
LlamaIndex CEO Jerry Liu argues the framework era is over: agent loops are now capable enough that context quality is the real competitive edge.
LlamaIndex
RAG
2026-04-30 · open.substack.com
Two Open-Weight Models. Eight Chip Families. One Frontier Co-Engineered for Non-Nvidia Silicon. The Stack Was the Moat. Now It Has a Fork.
2026-04-29 · amcompute.com
Disaggregated inference started as a software technique for splitting prefill and decode onto separate GPU pools. NVIDIA, Groq, Cerebras, and AWS are now taking it further with chips purpose-built for each phase.
prefill-decode disaggregation
production LLM serving
2026-04-27 · kdnuggets.com
Learn the top Python frameworks for LLM apps covering fine-tuning, model loading, serving, RAG pipelines, multi-agent systems, and evaluation.
2026-04-27 · api-docs.deepseek.com
🚀 DeepSeek-V4 Preview is officially live & open-sourced! Welcome to the era of cost-effective 1M context length.
2026-04-27 · marktechpost.com
2026-04-27 · thenextweb.com
The promotional discount runs until 5 May 2026. Even at full price, V4-Pro already undercuts GPT-5.5, Claude Opus 4.7, and Gemini 3.1 Pro on per-token costs. The move is a direct challenge to the pricing strategy of US AI providers at a moment when the Trump administration has…
2026-04-27 · arkaung.github.io
2026-04-26 · open.substack.com
An important primitive for the new "AI agent era"
2026-04-25 · spectrum.ieee.org

Startup Verkor.io’s agentic AI orchestrated the entire design process from a 219-word prompt
2026-04-25 · github.com

A fast, helpful, and open-source document parser
2026-04-25 · theargumentmag.com
AI only needs 150 words to identify me. What does that mean for you?
2026-04-25 · magazine.sebastianraschka.com
KV caches are one of the most critical techniques for efficient inference in LLMs in production.
★ 2026-04-25 · newsletter.semianalysis.com
Hands On With GPT 5.5, Opus 4.7, DeepSeek V4, Why Benchmarks Are Bad, and Who’s Going To Win
GPT-5.5 is now materially better
GLM-5.1, Qwen3.6-Plus, Kimi K2.6, Composer 2, and Gemini 3.1 Pro
2026-04-25 · simonwillison.net
Now that GPT-5.5 is available in the API, OpenAI have released a wealth of useful tips on how best to prompt the new model. Here's a neat trick they recommend …
2026-04-24 · scmp.com
The company says its cost-efficient new V4 model is competitive with top closed-source models from OpenAI and Google DeepMind.
2026-04-24 · simonwillison.net
Chinese AI lab DeepSeek’s last model release was V3.2 (and V3.2 Speciale) last December. They just dropped the first of their hotly anticipated V4 series in the shape of two …
2026-04-24 · github.com

Ruby's most capable AI runtime
2026-04-23 · openai.com
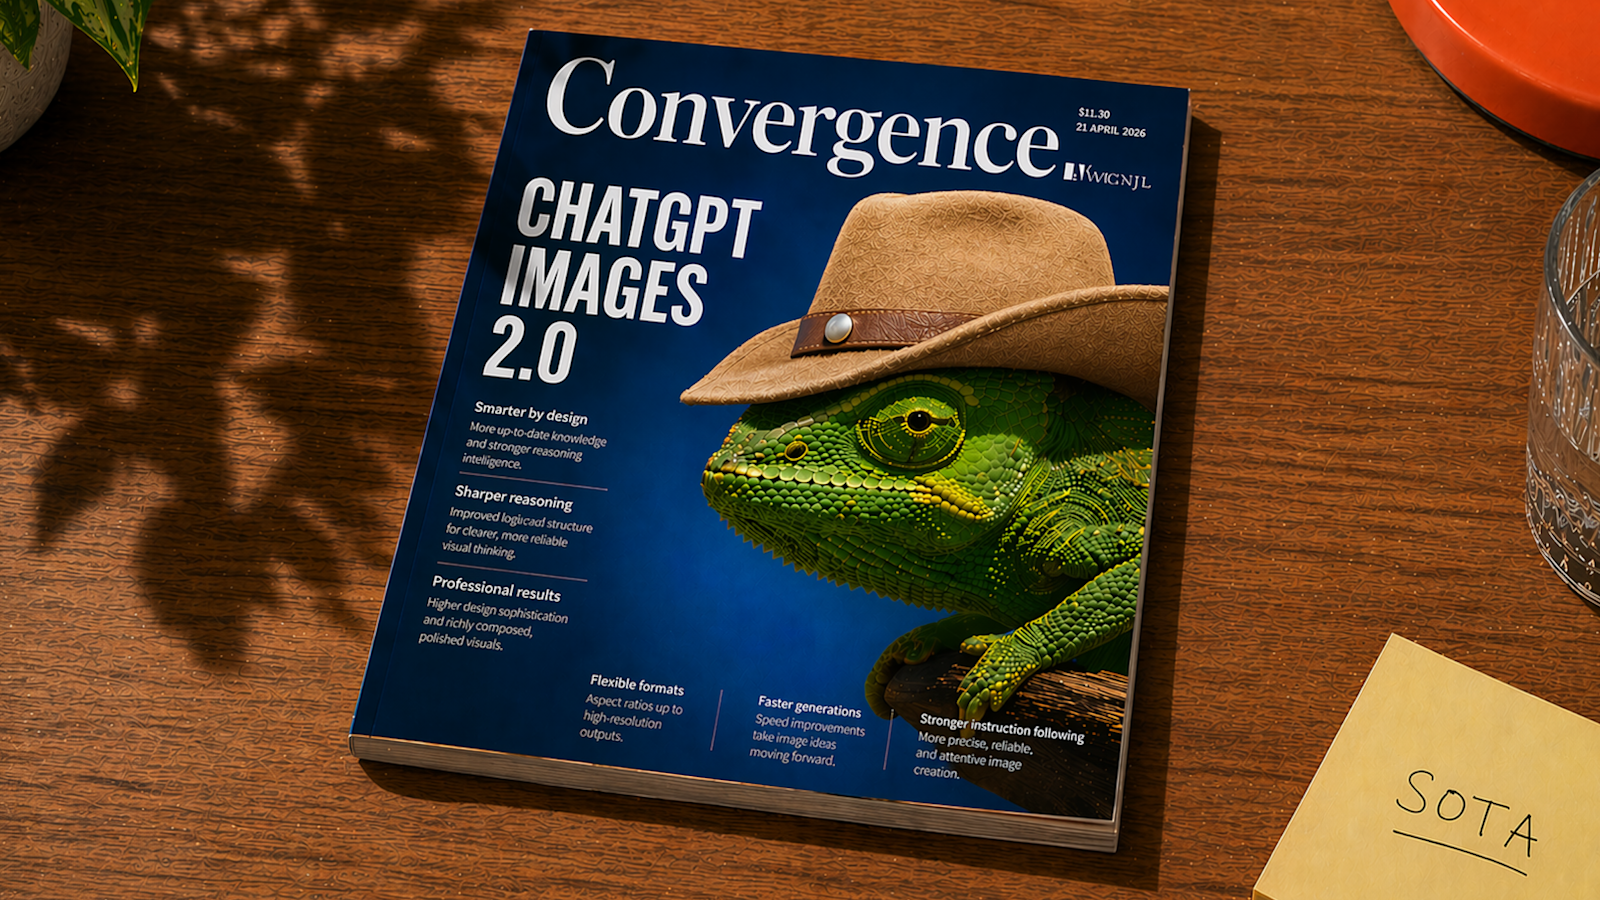
ChatGPT Images 2.0 introduces a state-of-the-art image generation model with improved text rendering, multilingual support, and advanced visual reasoning.