DeepSeek V4—almost on the frontier, a fraction of the price
Chinese AI lab DeepSeek’s last model release was V3.2 (and V3.2 Speciale) last December. They just dropped the first of their hotly anticipated V4 series in the shape of two …
Chinese AI lab DeepSeek’s last model release was V3.2 (and V3.2 Speciale) last December. They just dropped the first of their hotly anticipated V4 series in the shape of two …
Ruby's most capable AI runtime
ChatGPT Images 2.0 introduces a state-of-the-art image generation model with improved text rendering, multilingual support, and advanced visual reasoning.
Learn faster, build smarter, and unlock the full power of Claude Code through real examples, reusable templates, prompts, workflows, subagents, and system design.

LLMs are evolving. The next generation of the world’s hottest technology will be cheaper, more efficient, and able to solve bigger problems without going off the rails.

Qwen Studio offers comprehensive functionality spanning chatbot, image and video understanding, image generation, document processing, web search integration, tool utilization, and artifacts.

AMD's 3D V-Cache CPUs deliver a huge boost versus the Non-X3D part in AI benchmarks, showcasing why they are best suited for RAG pipelines.
But LLMs' limitations can be seen when it needs to generate responses on data it wasn't trained on.
That's where RAG or Retrieval-Augmented Generation) comes into play
Learn to build with Claude through Anthropic's comprehensive courses and training programs.
The updated Codex app for macOS and Windows adds computer use, in-app browsing, image generation, memory, and plugins to accelerate developer workflows.
Claude is a family of state-of-the-art large language models developed by Anthropic. This guide introduces the available models and compares their performance.
The .claude folder is created by tools that integrate with Claude to store local state. It keeps track of how the model behaves inside your project and that includes configuration, cached data, task definitions, and sometimes context that helps the system stay consistent across…
Tested, ranked, and ready to use

New interviews and closely guarded documents shed light on the persistent doubts about the head of OpenAI, Ronan Farrow and Andrew Marantz write.
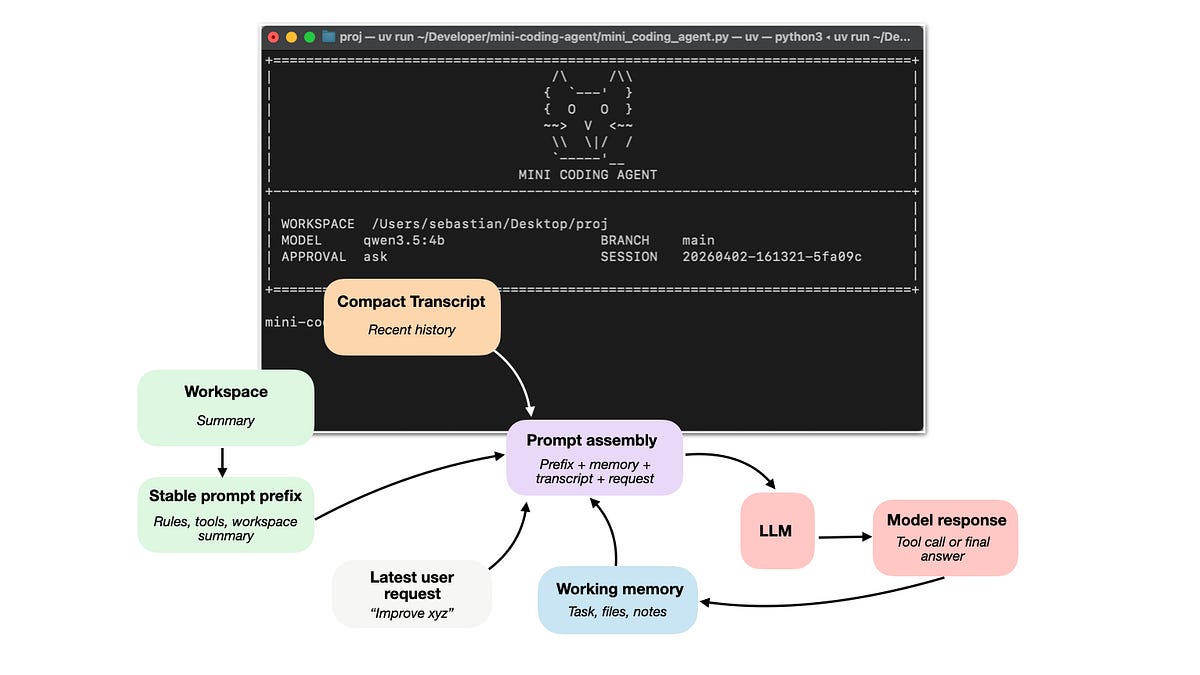
How coding agents use tools, memory, and repo context to make LLMs work better in practice
six of the main building blocks
application layer, a so-called agentic harness
Anthropic's interpretability team published research revealing that its Claude Sonnet 4.5 model contains 171 internal representations that function analogously to
Qwen Chat offers comprehensive functionality spanning chatbot, image and video understanding, image generation, document processing, web search integration, tool utilization, and artifacts.

Our most intelligent open models, built from Gemini 3 research.

What actually happens when you type a message into Claude Code? The agent loop, 50+ tools, multi-agent orchestration, and unreleased features, mapped from source.
This technique can be used out-of-the-box, requiring no model training or special packaging. It is code-execution free, which means you do not need to add additional tools to your LLM environment.
One major bottleneck: the need to set up dynamic execution sandboxes for every repository,
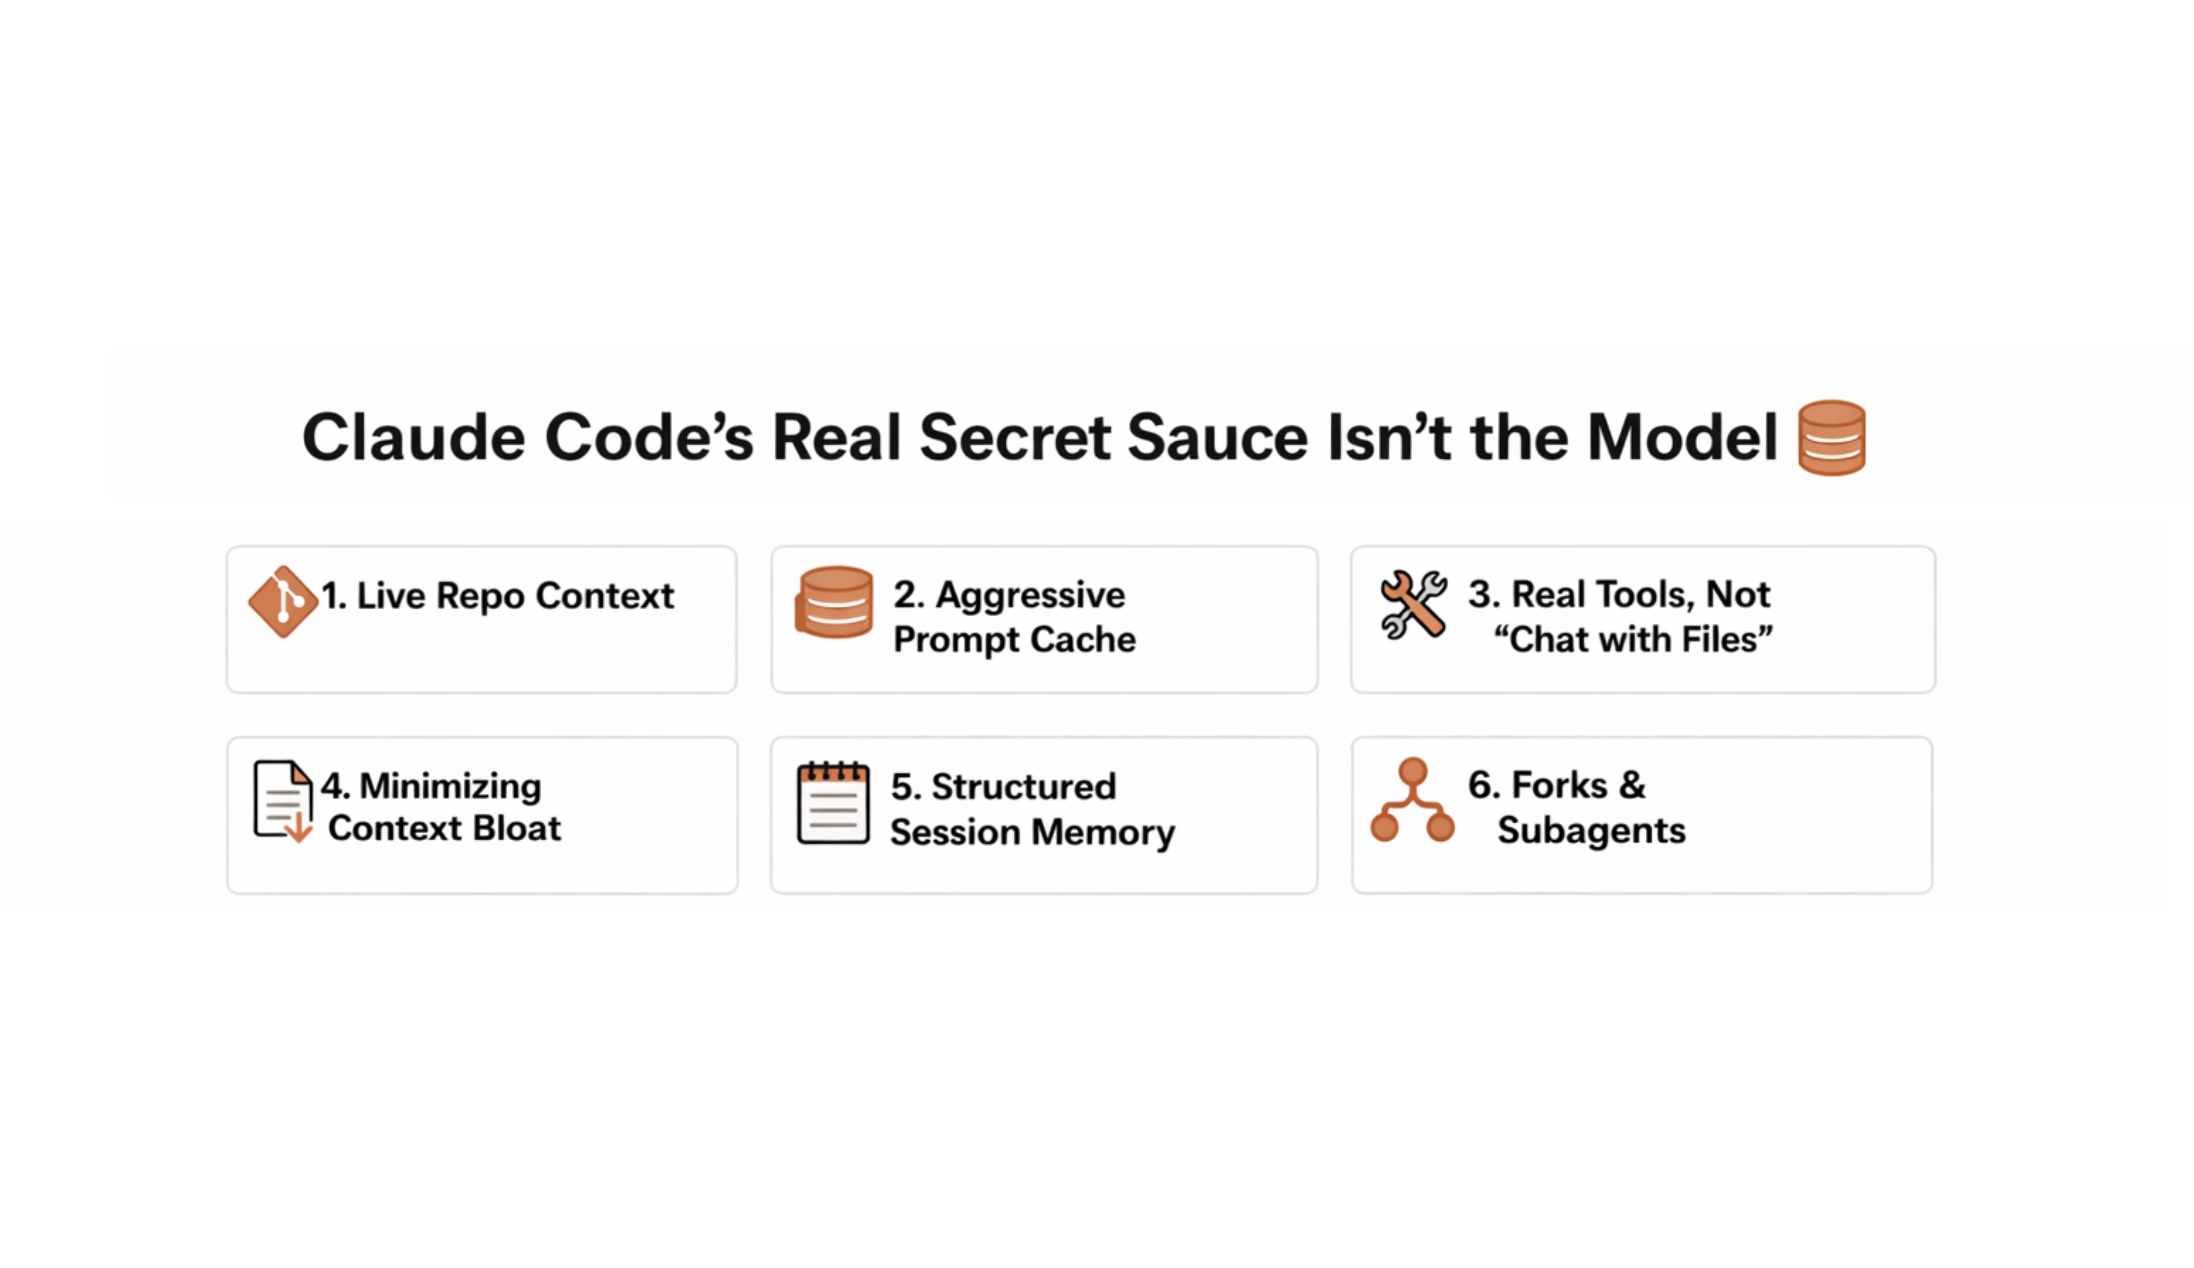
Skimming the leaked Claude Code TypeScript snapshots suggests that much of its coding performance comes from the surrounding software harness, including repo context, tooling, caching, memory, and subagents.
Universal CLAUDE.md - cut Claude output tokens by 63%. Drop-in. No code changes. - drona23/claude-token-efficient
Build an AI weather agent in 40 lines of Python using Hugging Face's smolagents library. Learn to create tools, connect LLMs, and run autonomous tasks.
An agent is essentially an LLM equipped with tools
approach to reasoning
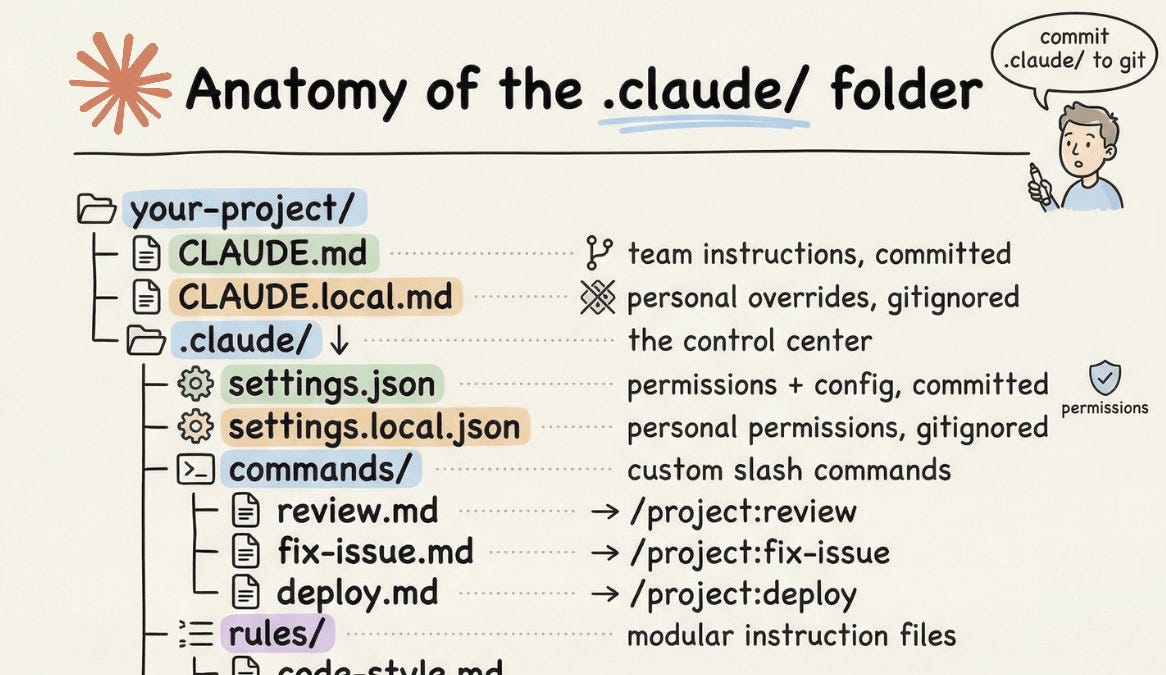
A complete guide to CLAUDE.md, custom commands, skills, agents, and permissions, and how to set them up properly.
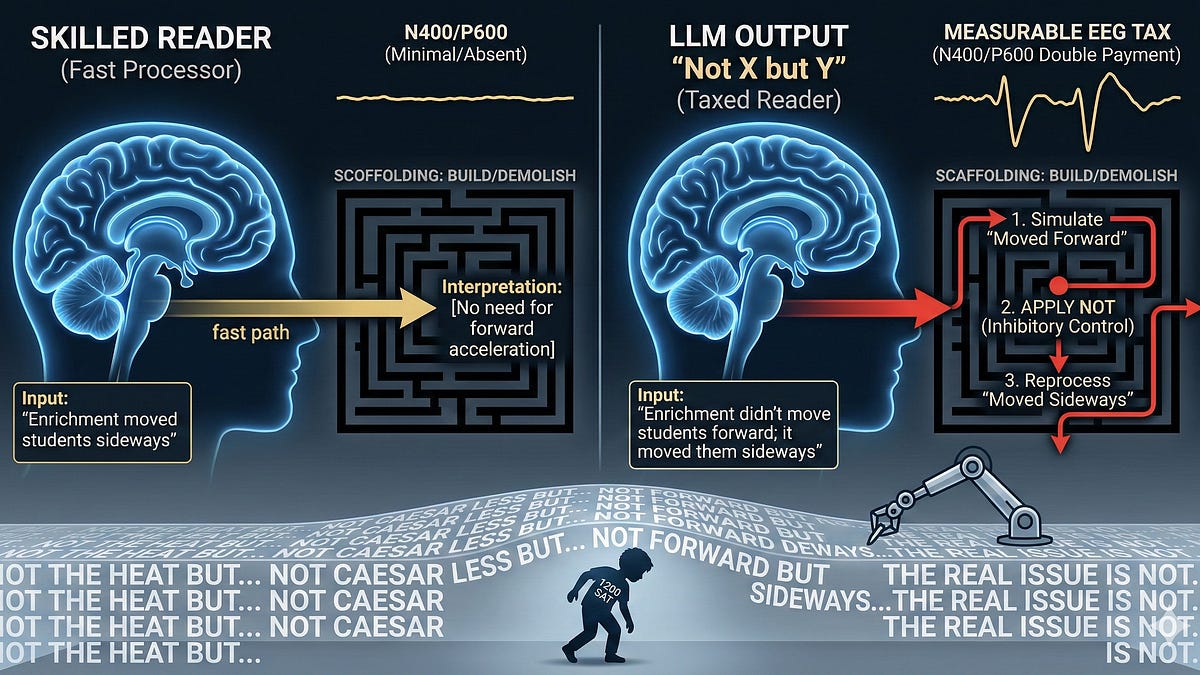
Your brain on "not X but Y"
This happens in seconds. A student with high verbal aptitude processes this almost instantaneously.
Psychometricians have called antonyms the most efficient measure of verbal intelligence in the toolkit: high g-loading, high discrimination at the top of the ability range, no contextual scaffolding.
Researchers at Tsinghua University and Z.ai built IndexCache to eliminate redundant computation in sparse attention models like DeepSeek and GLM. The training-free technique cuts 75% of indexer operations, delivering up to 1.82x faster time-to-first-token at 200K context lengths…
Google published a research blog post on Tuesday about a new compression algorithm for AI models. Within hours, memory stocks were falling. Micron dropped 3 per cent, Western Digital ...
Learn how to set up Nanobot, connect it to WhatsApp, and power it with OpenAI GPT-5.3-Codex for a practical, always-on AI agent.
When you type a query into a search engine, something has to decide which documents are actually relevant — and how to rank them. BM25 (Best Matching 25), the algorithm powering search engines like Elasticsearch and Lucene, has been the dominant answer to that question for…
The clever part is that BM25 doesn’t reward keyword stuffing
saturation
Access large language models from the command-line
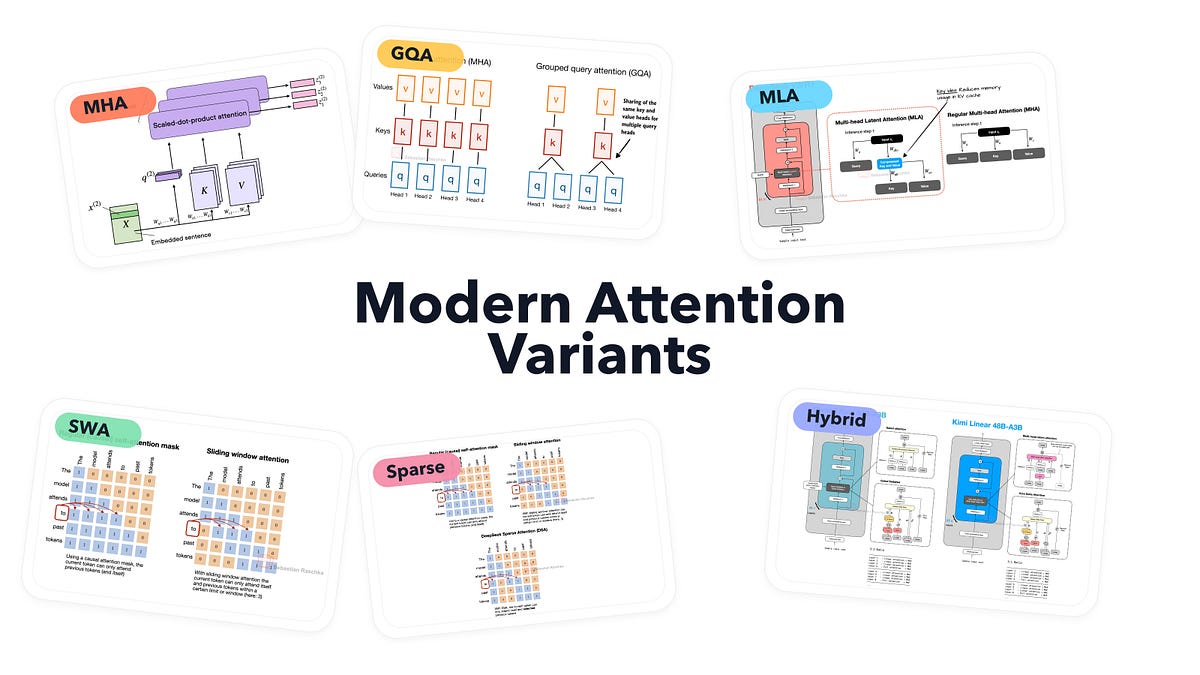
From MHA and GQA to MLA, sparse attention, and hybrid architectures

Shortly after Amazon announced its $50 billion investment in OpenAI, AWS invited me on a private tour of the chip lab at the heart of the deal.
Note: Based on the article **[An exclusive tour of Amazon’s Trainium lab, the chip that’s won over Anthropic, OpenAI, even Apple](#rid:1653401870)**, here are the key points: ### Strategic Impact & Partnerships * **Major Adoption:** Amazon’s custom chips have secured massive commitments from leading AI labs. **Anthropic** runs Claude on over 1 million Trainium2 chips, and **OpenAI** recently signed a…
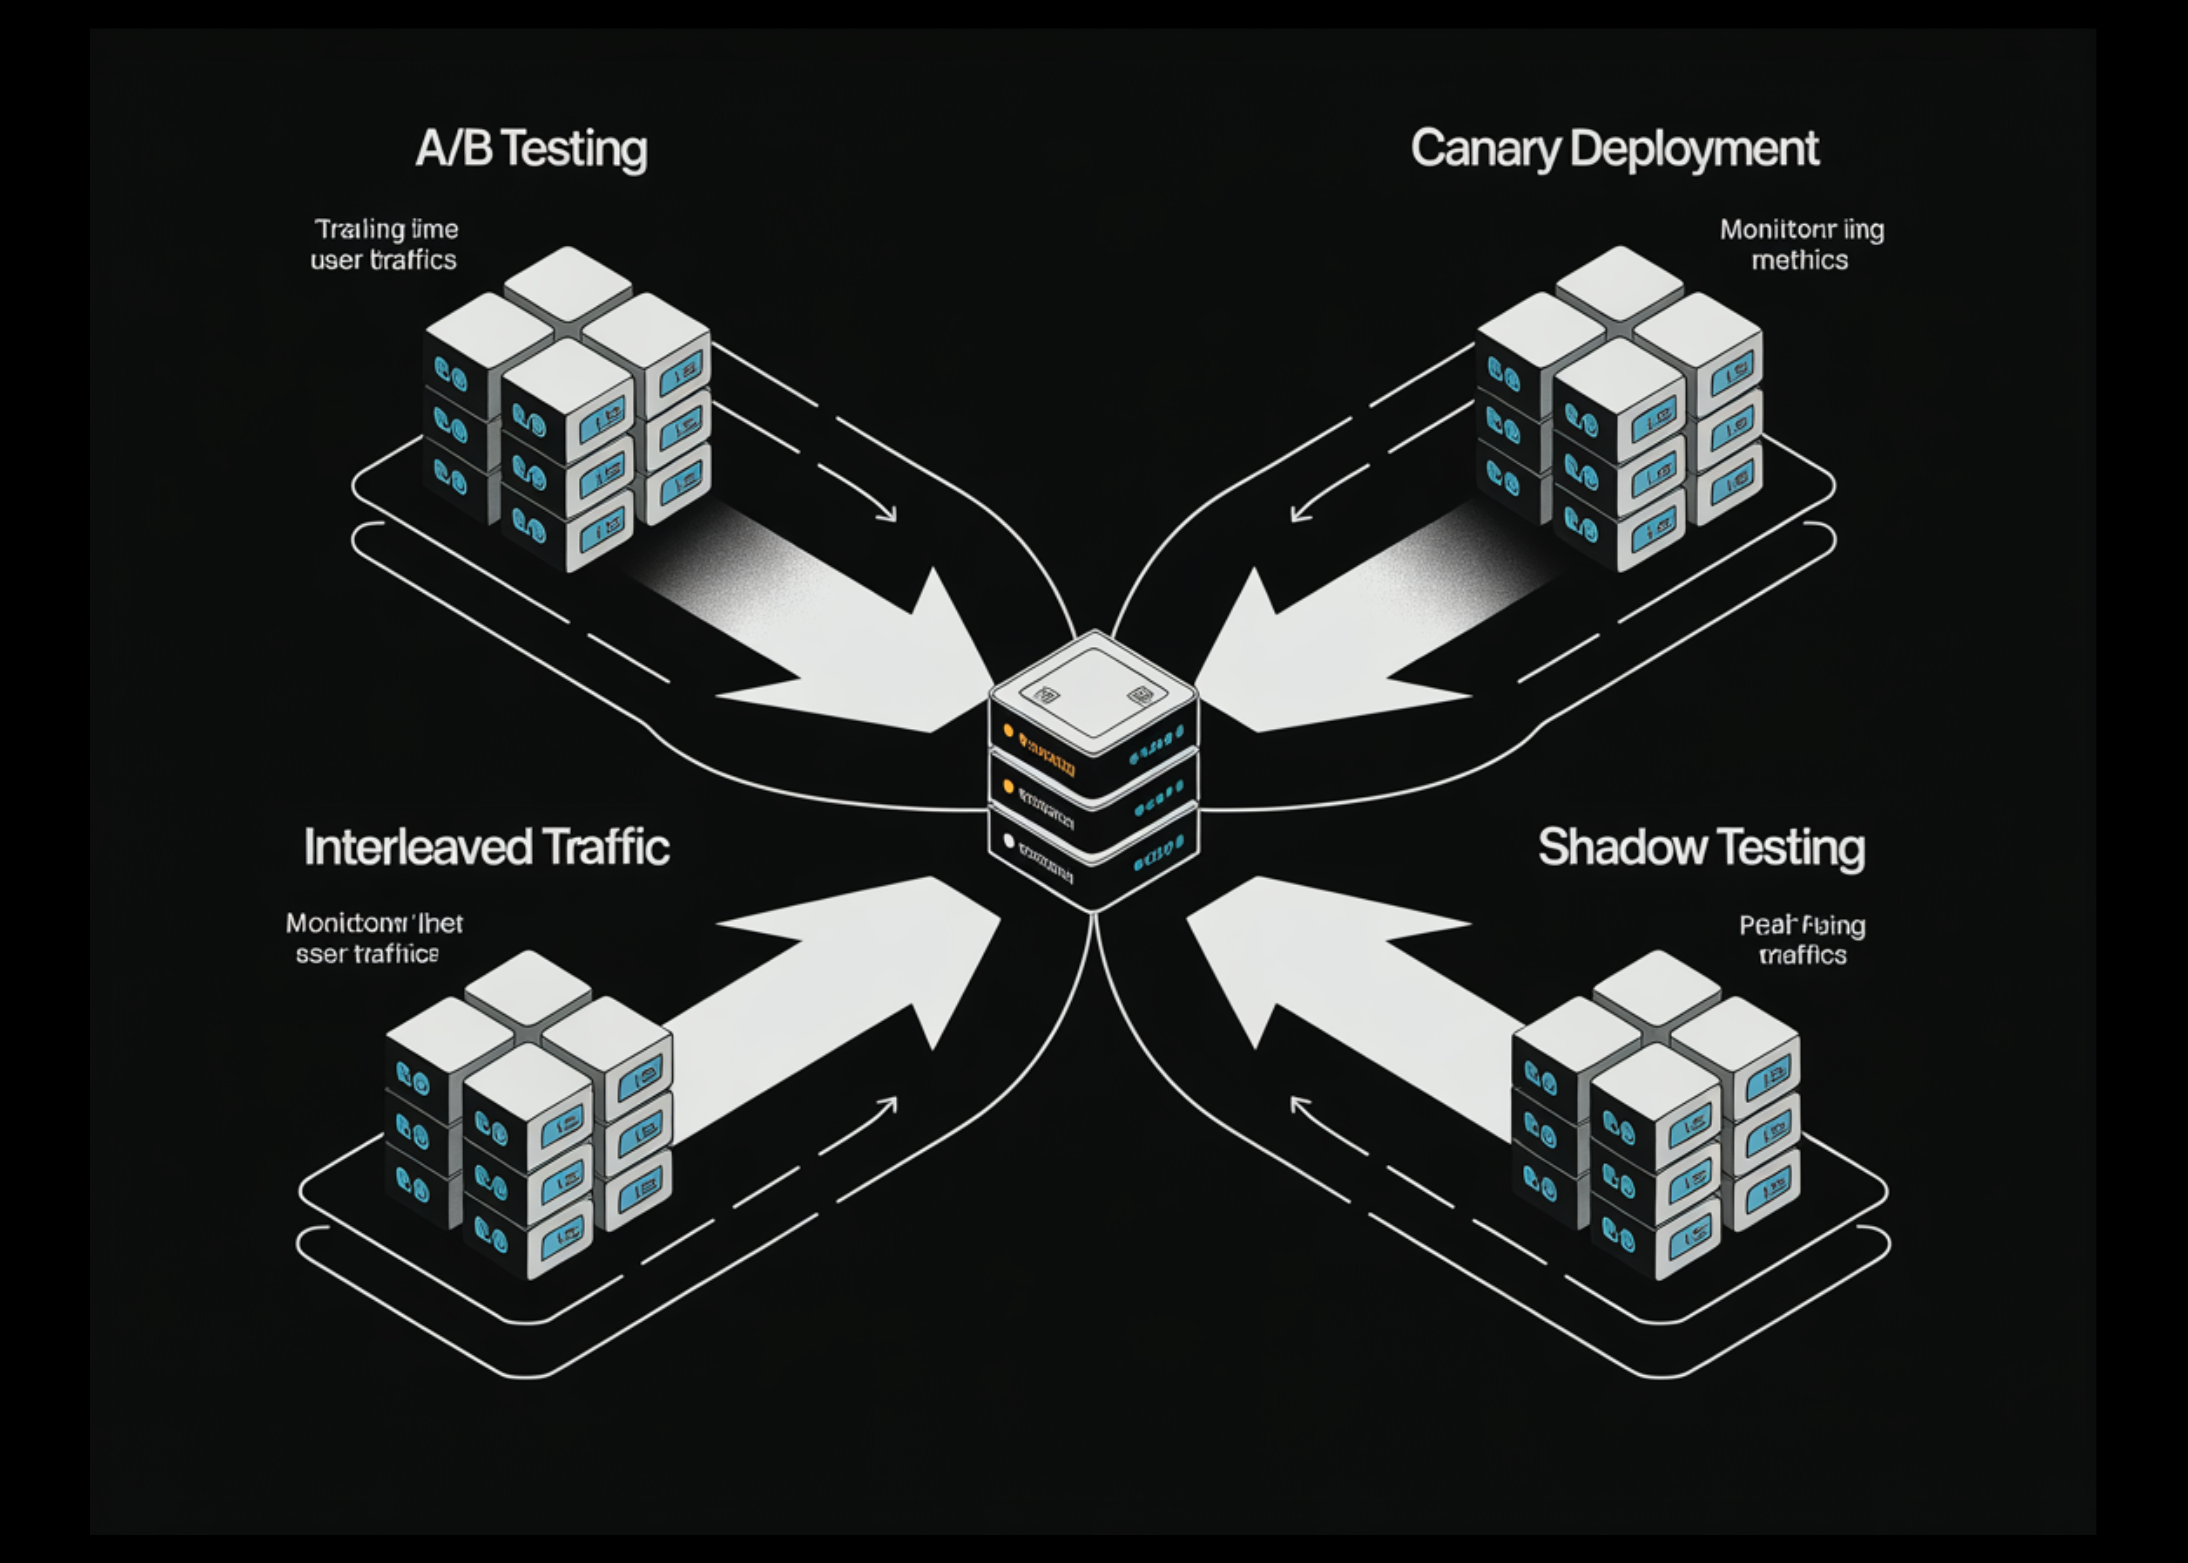
Safely Deploying Machine Learning Models to Production: Four Controlled Strategies (A/B, Canary, Interleaved, Shadow Testing)
Note: This bookmark, **[Safely Deploying ML Models to Production: Four Controlled Strategies](#rid:1652757915)**, is an article from MarkTechPost that outlines how to release machine learning models into production while minimizing risk. The article details four key deployment strategies: * **A/B Testing**: Randomly splits a small percentage of total traffic to the new model while the rest stays on the…

A gallery that collects architecture figures from The Big LLM Architecture Comparison and related articles, with fact sheets and links back to the original sections.

Mistral's Small 4 combines reasoning, multimodal analysis and agentic coding in a single open-source model with configurable inference effort, offering enterprises a lower-cost alternative to running separate models for each task.
LLM calls are black boxes in production. Learn how to add structured observability to your RubyLLM-powered app with OpenTelemetry.
Nvidia's KV Cache Transform Coding (KVTC) compresses LLM key-value cache by 20x without model changes, cutting GPU memory costs and time-to-first-token by up to 8x for multi-turn AI applications.

Train your own model with Unsloth, an open-source framework for LLM fine-tuning and reinforcement learning.
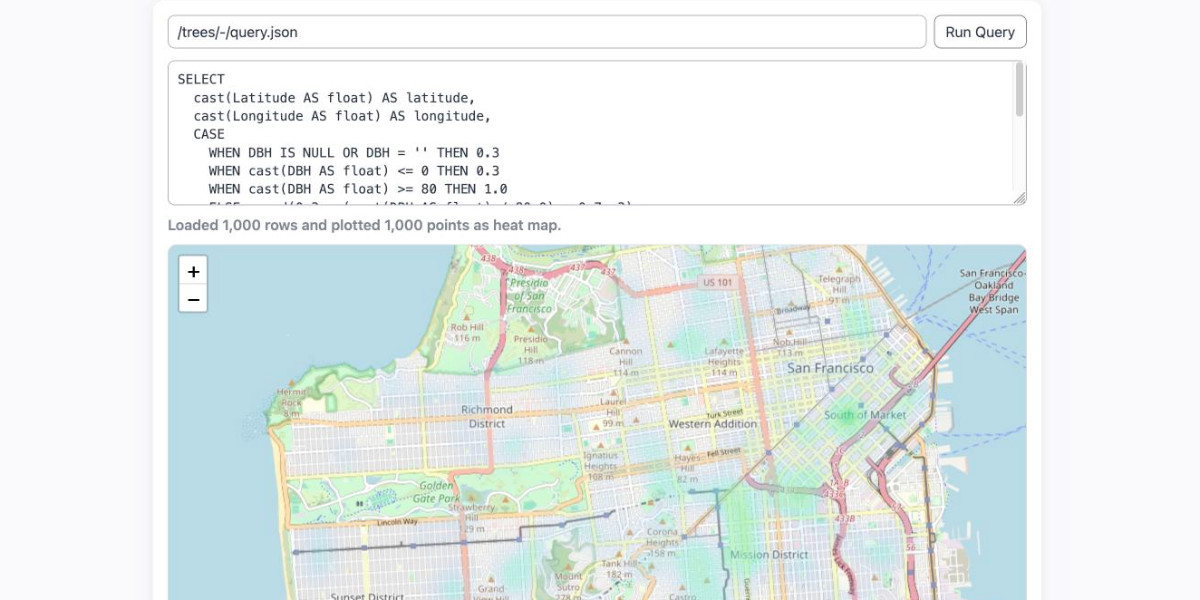
Here's the handout I prepared for my NICAR 2026 workshop "Coding agents for data analysis" - a three hour session aimed at data journalists demonstrating ways that tools like Claude …
I put together a new LLM Architecture Gallery that collects the architecture figures from my recent comparison articles in one place, together with compact fact sheets and links.

Detect your hardware and find out which AI models you can run locally. GPU, CPU, and RAM analysis in your browser.
We assumed good theories are small. But the minimum viable compression of a complex system might be billions of parameters large.
Chomsky showed that all human languages share deep recursive structure.
Elegant equations might not exist for complex systems.
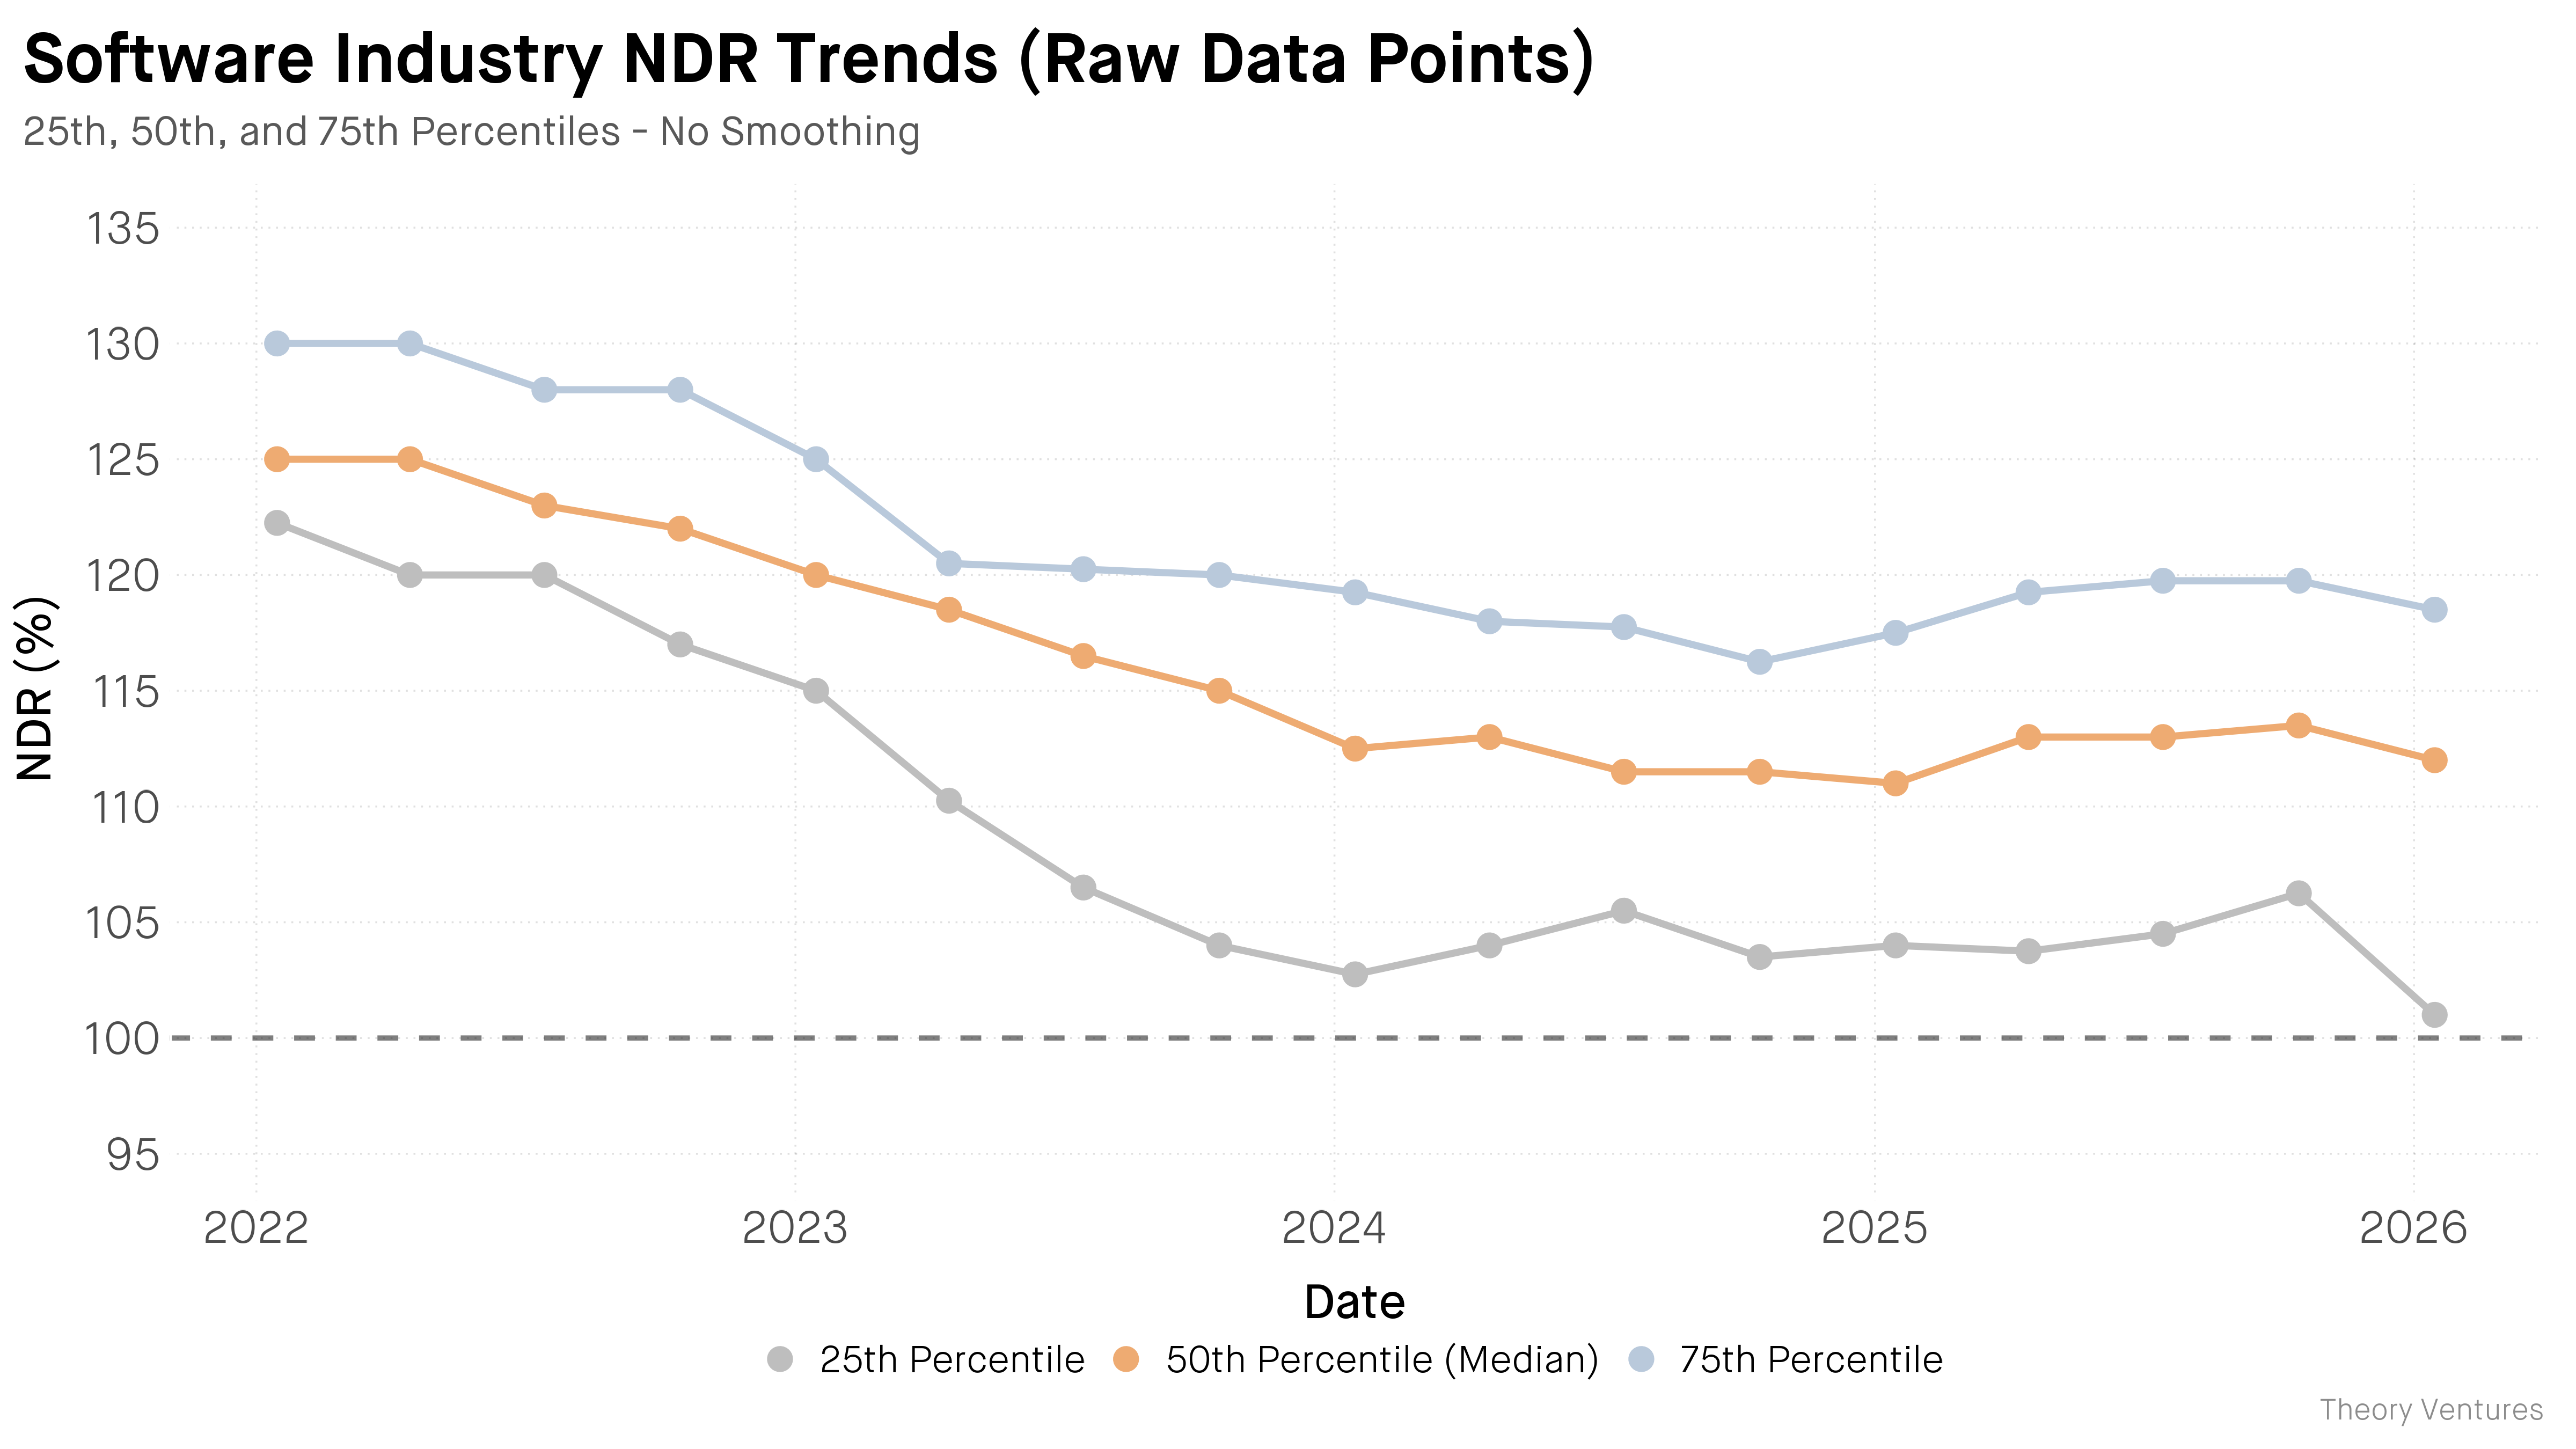
"GitHub Copilot had 20 million users. First to market. Then Claude Code arrived and installs peaked within six months. If the sword can cut the leader, no one is safe."
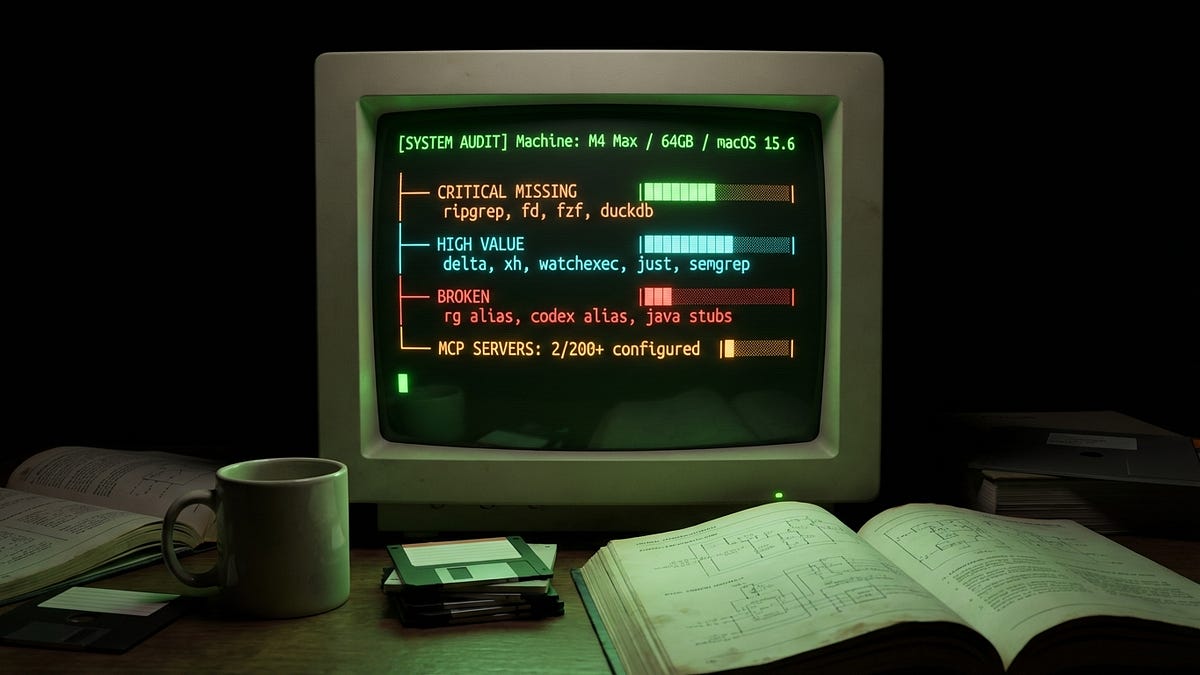
My Claude was craving for better tooling.
Learn these five Python decorators based on diverse libraries, that take particular significance when used in the context of LLM-based applications.
OpenAI has indicated that a new version of its large language model, GPT-5.4, is in development following a post on