prob-stats
124 bookmarks · page 1 of 3
★ 2026-10-06 · statology.org

Statsmodels answers the questions sklearn was never built to answer: is this coefficient real or noise, does this added complexity earn its keep, can I trust these p-values in the first place, and which specific data points are quietly running the whole show.
Note: Run a regression in scikit-learn, and you get exactly two things back: a set of coefficients and a .predict() method. Ask it for a p-value on any of those coefficients, and there’s no built-in way to get one. This isn’t a missing feature scikit-learn’s maintainers overlooked; it’s a deliberate design choice they’ve stated directly: scikit-learn is built for prediction, not statistical inference…
2026-09-16 · gegell.github.io
This post details how Factorio's random number generation works, how it can be reversed and how I used that knowledge to predict and manipulate the RNG with pure in‑game mechanics.
How is it possible for a deterministic game like Factorio to have a random mechanic?
PRNG
2026-09-07 · johndcook.com
An example illustrating the large amount of error in Ngram data.
2026-09-06 · methodologymatters.substack.com
Exactly what the title says.
2026-08-14 · rubydoc.info

Documenting RubyGems, Stdlib, and GitHub Projects
2026-07-14 · statology.org

Explore how Pareto, log-normal, and Cauchy distributions differ from normal and why confusing them is costly.
Note: pareto, log-normal, cauchy
2026-07-02 · statology.org

Learn how starting hand frequencies and table position shape every pre-flop decision in Texas Hold 'Em.
2026-07-01 · asteriskmag.com
Everyone knows RCTs are the gold standard of evidence. ….Right?
It is a rare randomized trial (studying a particular intervention with a sufficiently large and well-distributed sample population) that can detect an 0.3% difference in a binary random variable — but Laplace could, more than 200 years ago.
You can be relatively sure that a p-value in one clinical trial conveys the same information as it does in another clinical trial, at least as far as the mathematical model is concerned.
2026-06-24 · fastly.com
Discover how Fastly uses the Gini coefficient, a metric usually reserved for economics, to model edge traffic inequality, improve cache efficiency, and plan capacity.
Major events change the shape of the traffic we serve.
traffic inequality -> cache behavior -> CPU utilization -> headroom
2026-06-18 · quantamagazine.org
A decades-old proof showed that seven shuffles are enough to mix up a deck of cards. But it requires you to cut the deck with the precision of a professional magician. A new proof gets around that obstacle.
2026-05-21 · substack.com
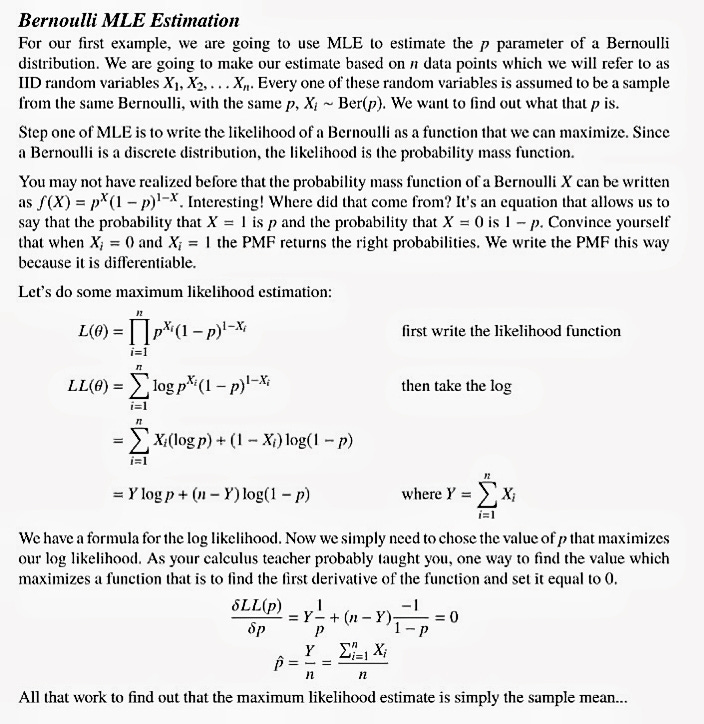
Maximum Likelihood Estimation is the quiet engine underneath almost everything in ML, DL, and RL. Most people learn it once in a stats class and move on. They shouldn't. It's not just a parameter-fitting trick — it's the philosophical foundation of why our models work at all…
2026-05-21 · statology.org

Estimate the Average Treatment Effect in Python using DoWhy with regression and propensity score matching on real data.
2026-05-19 · statology.org

Learn how to build and test causal inference models in Python using the DoWhy library.
2026-05-14 · statology.org

Learn how probability, outs, and card removal drive every decision in Texas Hold 'Em.
2026-05-07 · kdnuggets.com
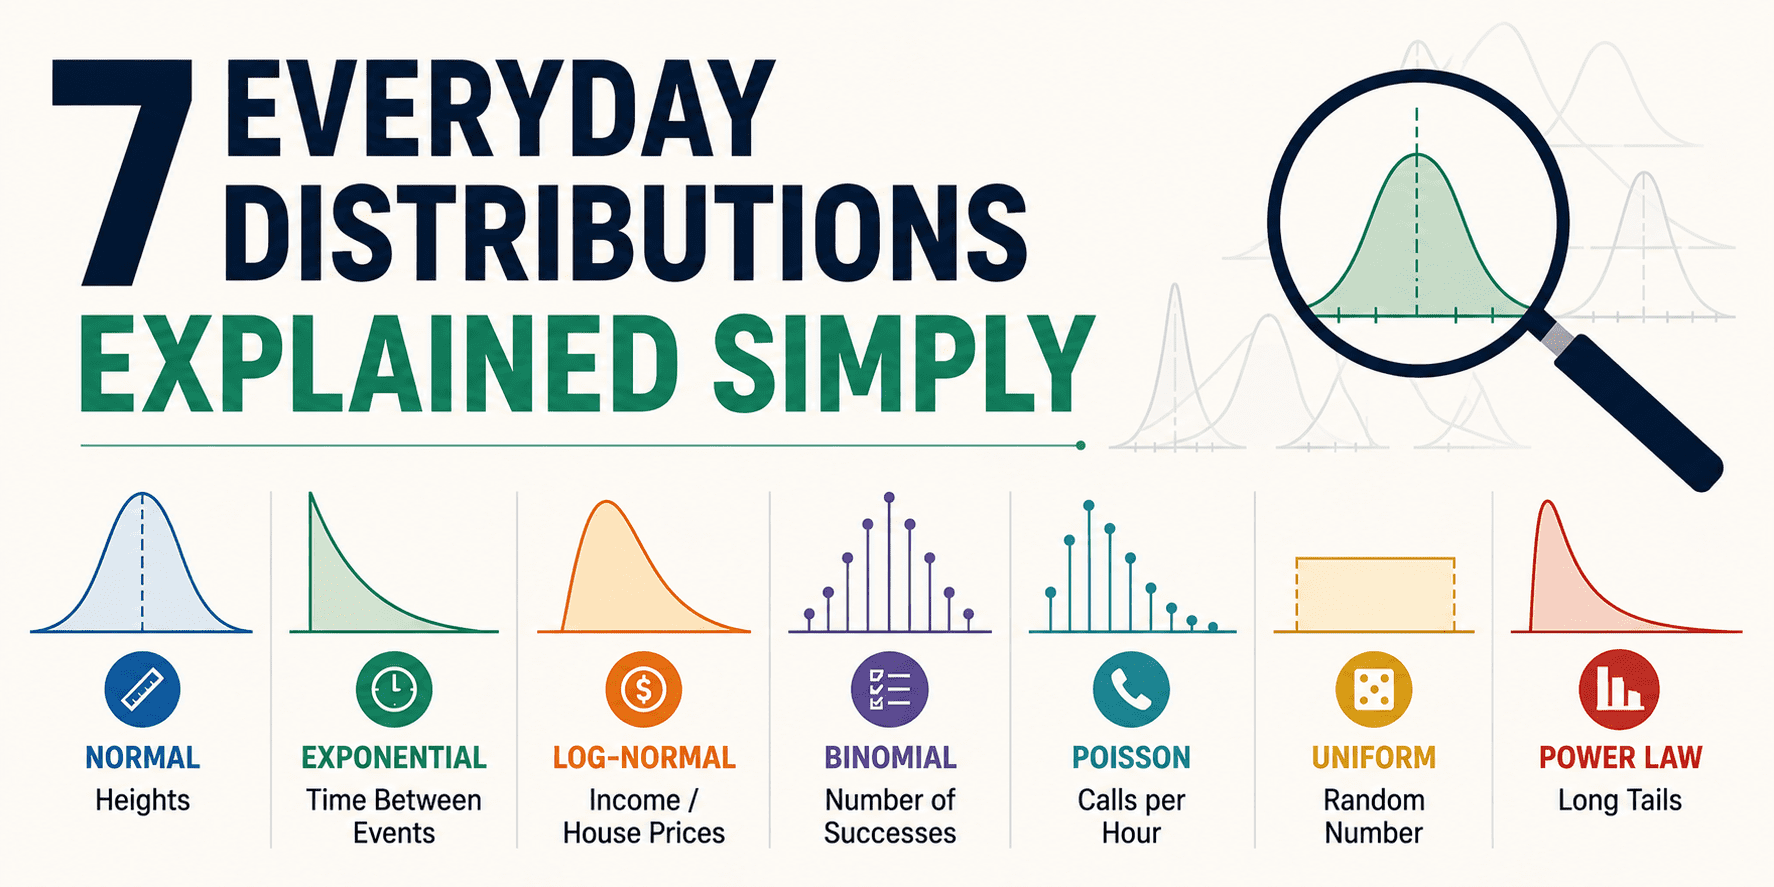
This article is a quick, everyday tour of seven distributions you'll actually recognize once you know what to look for. No heavy math. No gatekeeping.
The "Everything's Equally Likely" Pattern
The "How Many Successes?" Counter
2026-04-30 · outsourcedpharma.com
The industry has begun the movement to science-, risk-, and statistics-based approaches to cleaning process development and validation. Process capability has become an important measure for demonstrating acceptable cleaning processe performance. Explore process…
2026-04-03 · statology.org

Understand the law of large numbers and why larger datasets produce results closer to theoretical truth.
he more times an experiment is repeated, the closer the average of its results will be to the expected theoretical result.
2026-03-17 · scientificamerican.com
Here’s how a mathematical paradox distorts our view of news, safety and statistics
Welsh police learned this lesson the hard way during the 2017 Union of European Football Associations Champions League final. They deployed cameras throughout Cardiff, where the soccer event was held, and used automated facial-recognition software to analyze the footage. The software scanned the…
2026-01-22 · statology.org

Understand the key differences between standard deviation and standard error with clear examples and practical applications.
The standard deviation measures the spread of individual data points in a sample from a population.
The standard error measures how well a sample mean represents the actual population mean—in other words, how uncertain we are about the sample mean.
2026-01-13 · scientificamerican.com
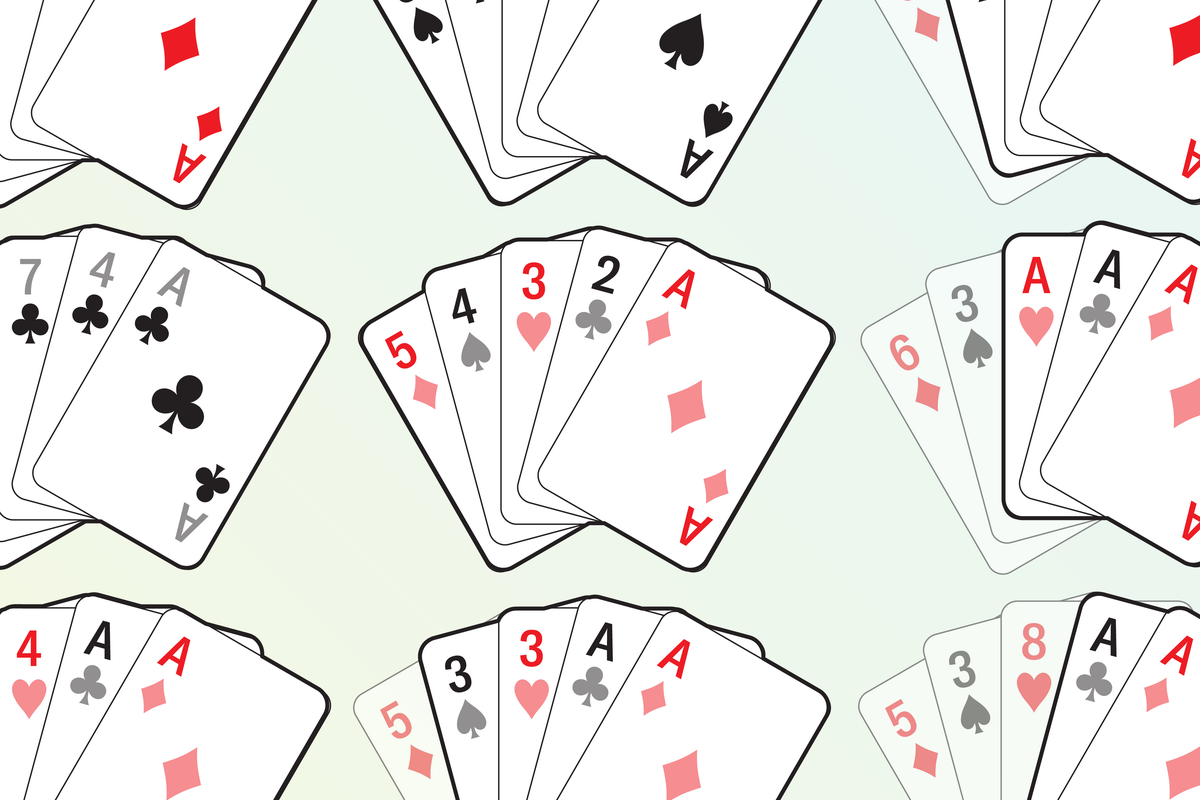
A traditional card deck happens to dodge a tricky poker paradox. Other poker variants aren’t so lucky
2026-01-07 · marktechpost.com

Learn about implementing Softmax from scratch and discover how to avoid the numerical stability trap in deep learning projects.
This function implements the Softmax activation in its most straightforward form.
numerically unstable—large positive logits can cause overflow, and large negative logits can underflow to zero. As a result, this version should be avoided in real training pipelines
2025-11-14 · statology.org
2025-10-27 · statology.org

Learn to calculate and interpret five essential effect size measures with Python examples and clear guidance.
Cohen’s d — the standardized difference between two group means r (correlation coefficient) — the strength of a relationship between variables Odds ratio — how much more likely an outcome is in one group than another η² (eta squared) — how much of the total variance your variable explains Cliff’s…
2025-10-09 · statology.org

Gibrat's Law explains why proportional growth processes create lognormal distributions across economics, biology, and social systems.
2025-09-24 · statology.org

Learn how softmax converts raw scores into probability distributions that power AI decision-making.
2025-09-17 · statology.org

In this article, we will explore how to calculate and interpret the covariance matrix using NumPy.
2025-09-04 · statology.org

In this article, we'll explore what p-values really mean, what they do not mean, and how to interpret them correctly.
2025-08-26 · statology.org

Learn why simpler statistical models often outperform complex alternatives and when to apply this principle.
Information criteria like Akaike Information Criterion (AIC) and Bayesian Information Criterion (BIC) formalize this trade-off using specific formulas:
2025-07-07 · statology.org

Image by Editor | ChatGPT The Poisson distribution might sound like one of those things you only deal with in a stats class, but it actually shows up in
2025-06-12 · statology.org
In this article, you will learn how to visualize skewness and kurtosis using Python.
2025-05-20 · statology.org
In this article, we'll explore 10 Python one-liners that showcase the progression from basic statistical tests to sophisticated analyses.
2025-05-08 · statology.org
Let’s break down seven statistical concepts that even seasoned machine learning engineers often trip over — and why getting them right matters more than you think.
2025-04-18 · statology.org
So, if you’ve ever asked, “How long until X happens?” and wanted to back that up with solid data, you’re in the right place.
2025-04-14 · statology.org
This article explains its features, installation, and how to use it with examples.
2025-04-08 · statology.org

Let's clarify this important statistical pattern and understand its significance in analysis.
2025-04-01 · statology.org

The Poisson distribution is a discrete probability distribution that expresses the likelihood of a specific number of events occurring within a fixed time or space interval.
2025-03-25 · statology.org

This article is your ultimate guide to understanding them gently and illustratively.
2025-03-13 · evanmiller.org
2025-03-12 · dataconomy.com
Hellinger Distance is a statistical measure that quantifies the similarity between two probability distributions, useful in data analysis and machine learning applications.
2025-03-09 · theactuary.com

The Kaplan-Meier survival curve estimator is one of the most cited ideas in science
2025-03-03 · statology.org

Leverage helps us identify observations that could significantly influence our regression results, even in ways that aren't immediately obvious.
2025-02-17 · statology.org

Heteroscedasticity might seem like just the opposite of homoscedasticity, but understanding it in its own right is crucial for any data analyst.
2025-02-13 · statology.org

Homoscedasticity stands as one of those statistical terms that can seem unnecessarily complex at first glance.
2025-02-07 · statology.org

Still, the exact application, challenges and shortcuts related to this technique are relatively unknown, and that’s what this article seeks to change.
2025-02-06 · statology.org

Statistical power might be the most frequently misunderstood concept in research design. While many researchers know they "need" it, few truly understand
2025-01-09 · statology.org

Degrees of freedom (df) represent the number of independent values in a dataset that are free to vary while still satisfying the statistical constraints imposed on the data.
2024-12-31 · statology.org

Have a look at Statology's most popular articles of the year!
Note: Here are some of the most popular articles from Statology in 2024, along with brief summaries: 1. **5 of the Most Cited Statistical Papers of All Time** This article highlights five landmark statistical papers that have significantly influenced the field, including works by Kaplan and Meier, Cox, Bland and Altman, Duncan, and Marquardt. 2. **10 Essential Statistical Tests Explained in One…
2024-12-15 · marktechpost.com

Masked diffusion has emerged as a promising alternative to autoregressive models for the generative modeling of discrete data. Despite its potential, existing research has been constrained by overly complex model formulations and ambiguous relationships between different…
2024-12-01 · leancrew.com

A brief numerical and graphical check on a 3Blue1Brown video.
2024-11-30 · statology.org

The calculators in this guide follow a natural progression, starting with basic probabilities and z-scores, moving through hypothesis testing tools, and concluding with specialized distributions.