3 Seaborn Plots That Reveal Hidden Statistical Relationships
Exploratory data analysis (EDA) on complex datasets requires tools that reveal deep, hidden patterns, including overlapping distributions and outliers.
Exploratory data analysis (EDA) on complex datasets requires tools that reveal deep, hidden patterns, including overlapping distributions and outliers.
This post details how Factorio's random number generation works, how it can be reversed and how I used that knowledge to predict and manipulate the RNG with pure in‑game mechanics.
How is it possible for a deterministic game like Factorio to have a random mechanic?
PRNG
Biological phenomena are often studied by examining how a numerical variable, usually called the response (e.g., the weight or height of an organism), is affected by another variable, usually called the predictor (e.g., time or fertiliser applic...

Explore how Pareto, log-normal, and Cauchy distributions differ from normal and why confusing them is costly.
Note: pareto, log-normal, cauchy

Learn how starting hand frequencies and table position shape every pre-flop decision in Texas Hold 'Em.
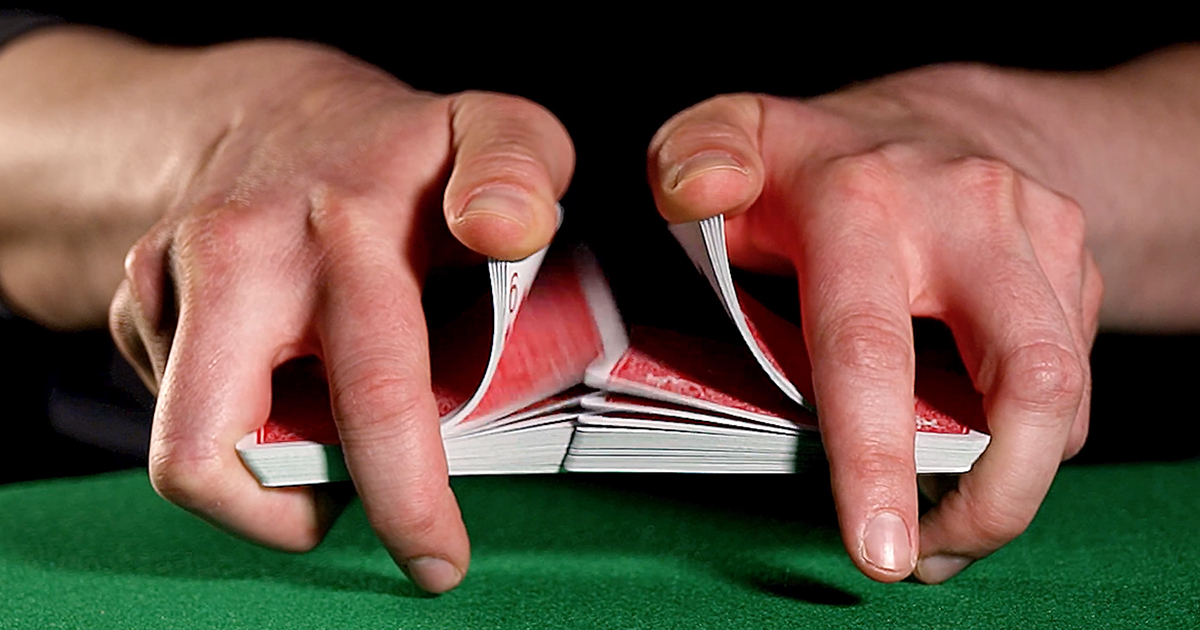
A decades-old proof showed that seven shuffles are enough to mix up a deck of cards. But it requires you to cut the deck with the precision of a professional magician. A new proof gets around that obstacle.
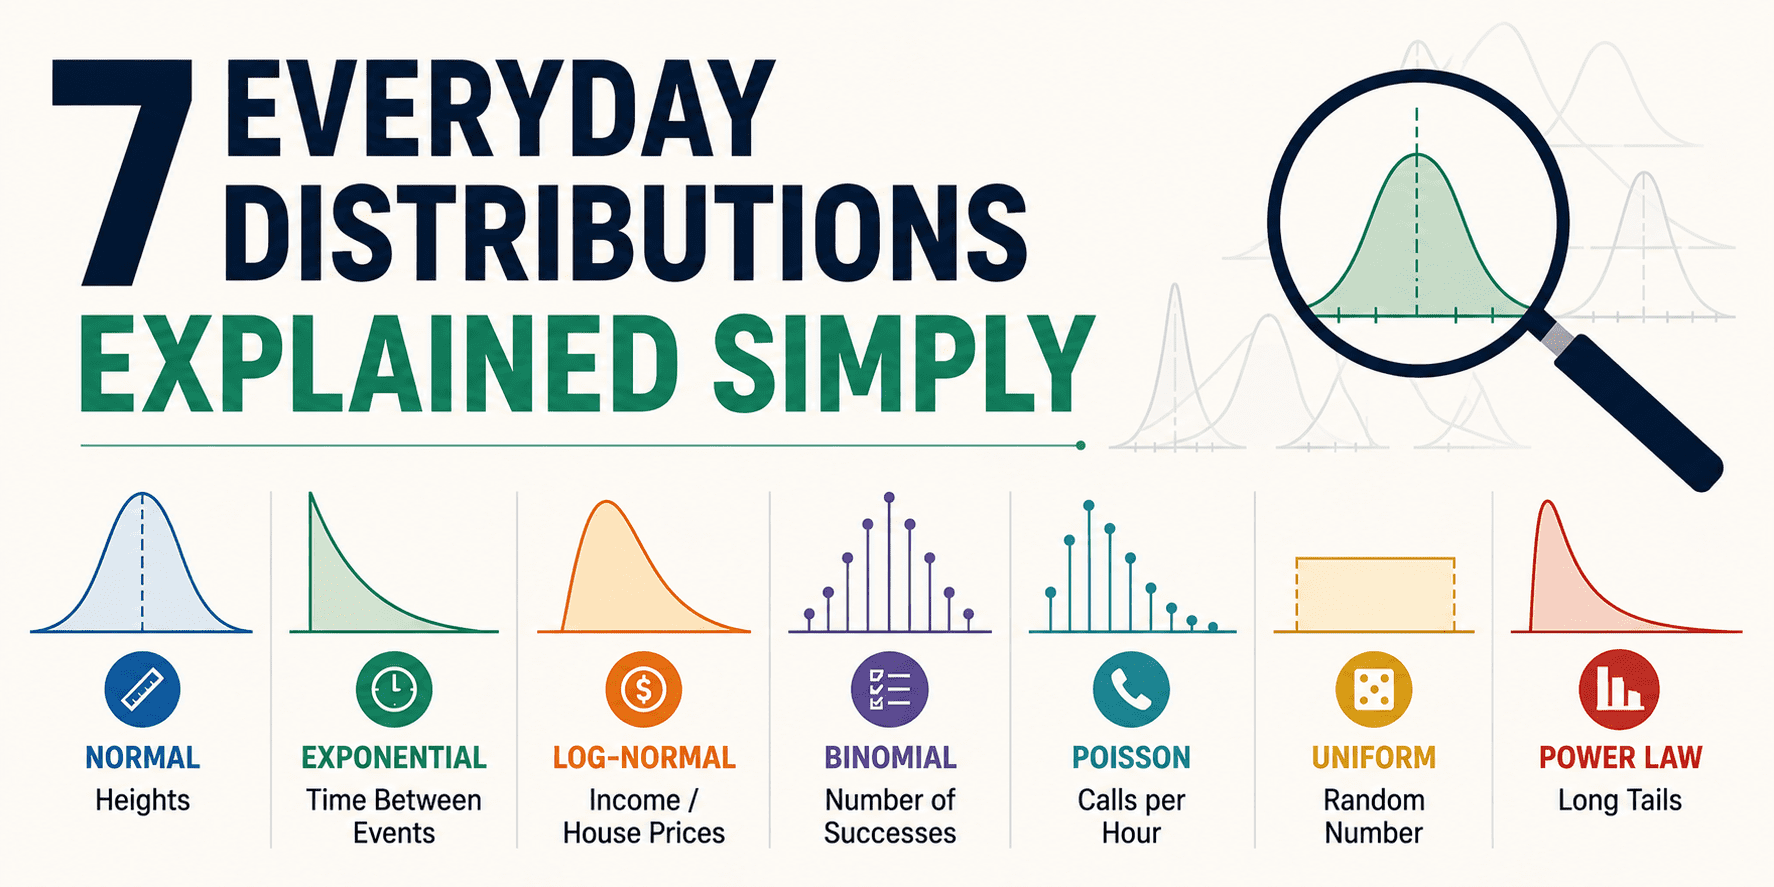
This article is a quick, everyday tour of seven distributions you'll actually recognize once you know what to look for. No heavy math. No gatekeeping.
The "Everything's Equally Likely" Pattern
The "How Many Successes?" Counter

Gibrat's Law explains why proportional growth processes create lognormal distributions across economics, biology, and social systems.

Let's clarify this important statistical pattern and understand its significance in analysis.

This article is your ultimate guide to understanding them gently and illustratively.

Understanding probability distributions in data science is crucial. They provide a mathematical framework for modeling and analyzing data.
Discover the origins, theory and uses behind the famous t-distribution
Breaking down one of the less well-known distributions in data science
While Fisher’s exact test is a convenient tool for A/B testing, the idea and results of the test are often hard to grasp and difficult to…
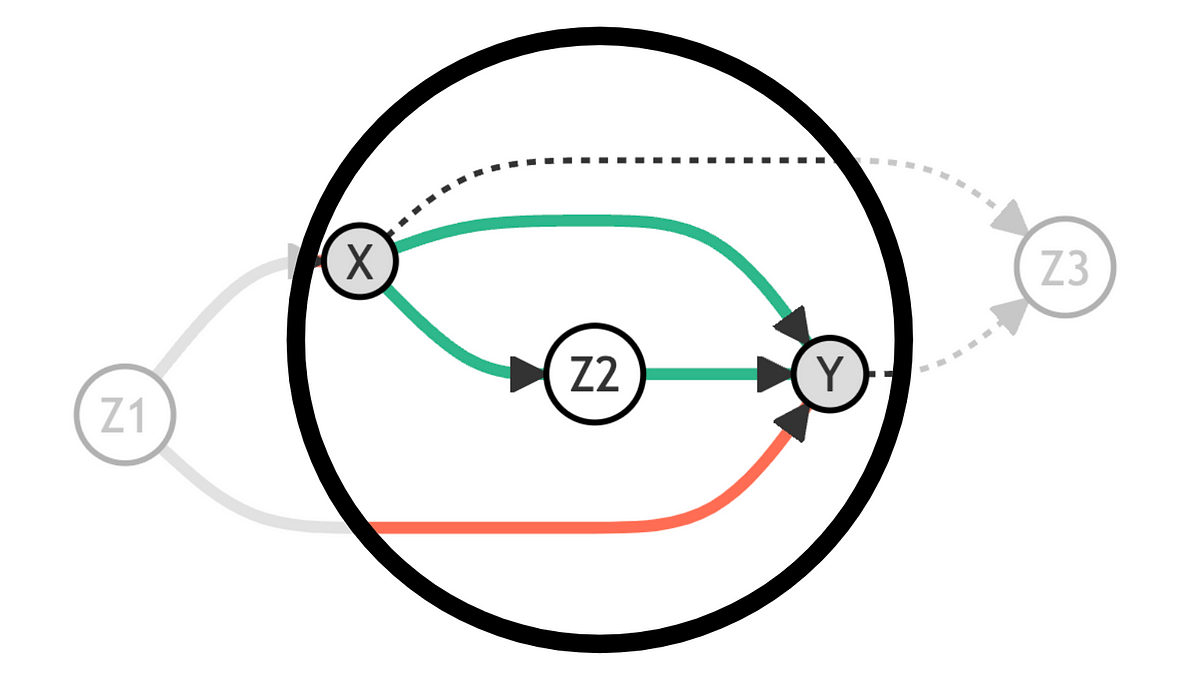
How to select control variables for causal inference using Directed Acyclic Graphs
An introduction to the Student’s t-distribution and the Student’s t-test
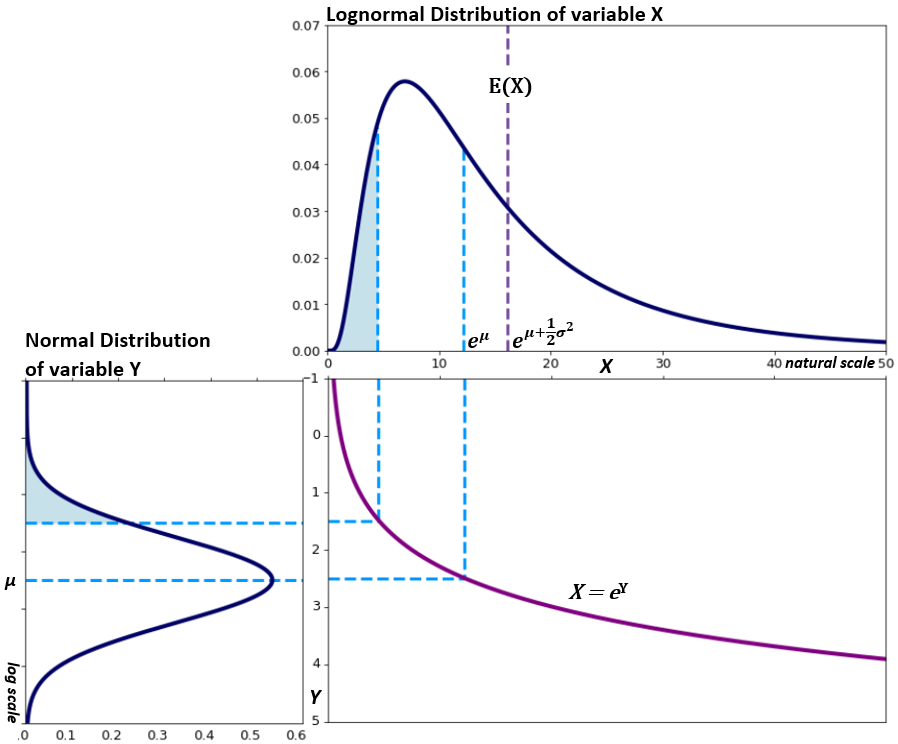
How to calculate μ & σ, the mode, mean, median & variance

Most human activities as well as many disciplines — from physics and biology to linguistics, finance, and computer science — follow a Pareto distribution instead of a “normal” Gaussian curve. In Pareto distributions, a small change in one variable is associated with a large…
How to Model random Processes with Distributions and Fit them to Observational Data
This post explains how those numbers were derived in the hope that they can be more interpretable for your future endeavors.
Standard Deviation is one of the most underrated statistical tools out there. It’s an extremely useful metric that most people know how to calculate but very few know how to use effectively.