Understanding Probability And Statistics: Chi-Squared, Student-T, And F Dis

A Must Know Topic For Data Scientists Who Work With Data And Statistical Inference
A Must Know Topic For Data Scientists Who Work With Data And Statistical Inference

I got a customer ticket the other day that said they weren’t worried about response time because “New Relic is showing our average response time to be sub 20...

One of the most important concepts for Data Scientists

When to use Beta distribution

By Winnifred Louis, Associate Professor, Social Psychology, The University of Queensland, and Cassandra Chapman,PhD Candidate in Social Psychology, The University of Queensland. Here are the 7 sins: Assuming small differences are meaningful Equating statistical significance with…

In economics, the Gini coefficient, also known as the Gini index or Gini ratio, is a measure of statistical dispersion intended to represent the income inequality, the wealth inequality, or the consumption inequality within a nation or a social group. It was developed by Italian…
Data Science, Machine Learning, AI & Analytics
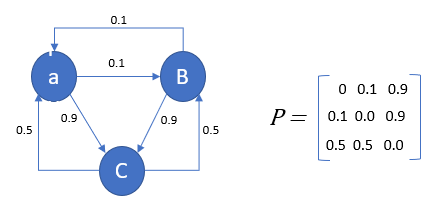
Solving real-world problems with probabilities
This post is about various evaluation metrics and how and when to use them.

This resource is part of a series on specific topics related to data science: regression, clustering, neural networks, deep learning, decision trees, ensembles, correlation, Python, R, Tensorflow, SVM, data reduction, feature selection, experimental design, cross-validation…
Quick-reference guide to the 17 statistical hypothesis tests that you need in applied machine learning, with sample code in Python. Although there are hundreds of statistical hypothesis tests that you could use, there is only a small subset that you may need to use in a machine…
This post explains how those numbers were derived in the hope that they can be more interpretable for your future endeavors.
During my years as a Consultant Data Scientist I have received many requests from my clients to provide frequency distribution
Kurtosis and Skewness are very close relatives of the “data normalized statistical moment” family – Kurtosis being the fourth and Skewness the third moment, and yet they are often used to detect very different phenomena in data. At the same time, it is typically recommendable to…
I recently ran across this bloom filter post by Michael Schmatz and it inspired me to write about a neat variation on the bloom filter that…
Standard Deviation is one of the most underrated statistical tools out there. It’s an extremely useful metric that most people know how to calculate but very few know how to use effectively.
This article was written by Sunil Ray. Sunil is a Business Analytics and Intelligence professional with deep experience. Introduction – the difference in mindset I started my career as a MIS professional and then made my way into Business Intelligence (BI) followed by Business…
The author presents 10 statistical techniques which a data scientist needs to master. Build up your toolbox of data science tools by having a look at this great overview post.

In statistics, Fisher's method, also known as Fisher's combined probability test, is a technique for data fusion or "meta-analysis" (analysis of analyses). It was developed by and named for Ronald Fisher. In its basic form, it is used to combine the results from several…

Nina Zumel prepared an excellent article on the consequences of working with relative error distributed quantities (such as wealth, income, sales, and many more) called “Living in A Lognormal…
Important concepts in information theory, machine learning, and statistics