Label Leakage: The Bug That Makes Churn Models Look Brilliant - Dataconomy

The model scores 0.94 AUC on held-out data. The notebook is clean, the cross-validation is stratified, nobody touched the test
The model scores 0.94 AUC on held-out data. The notebook is clean, the cross-validation is stratified, nobody touched the test
Build the five components every feature store needs, then see where AI changes the design.
Meet TARS — a simple, repeatable, and meaningful UX metric designed specifically to track the performance of product features. Upcoming part of the Measure UX & Design Impact (use the code 🎟 IMPACT to save 20% off today).

Learn what Shapley values are and how SHAP tools help explain machine learning predictions.

In this article, we'll walk through the process of aggregating claims data to create meaningful provider features, visualize patterns using Yellowbrick's Parallel Coordinates, and explore other visualization tools available for feature analysis.

Dataset distillation is an innovative approach that addresses the challenges posed by the ever-growing size of datasets in machine learning. This technique focuses on creating a compact, synthetic dataset that encapsulates the essential information of a larger dataset, enabling…

Analytics, management, and business intelligence (BI) procedures, such as data cleansing, transformation, and decision-making, rely on data profiling. Content and quality reviews are becoming more important as data sets grow in size and variety of sources. In addition…

Types of Functions > Basis functions (called derived features in machine learning) are building blocks for creating more complex functions. In other
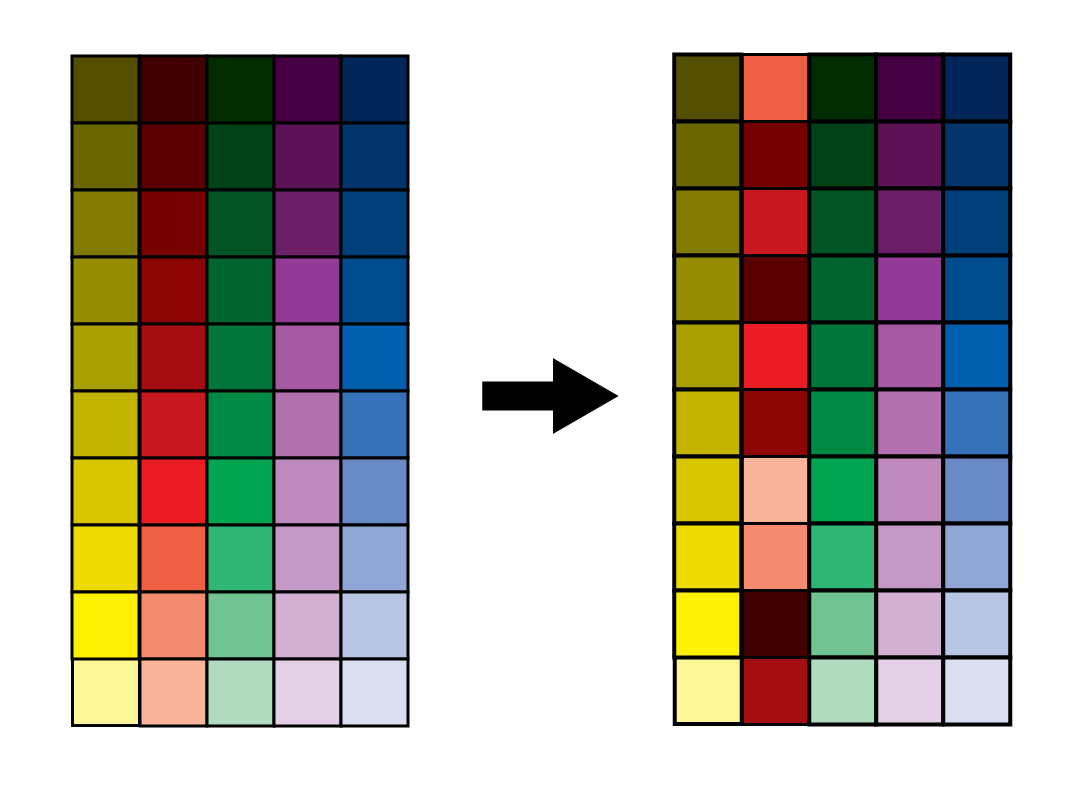
Understanding the importance of permutations in the field of explainable AI
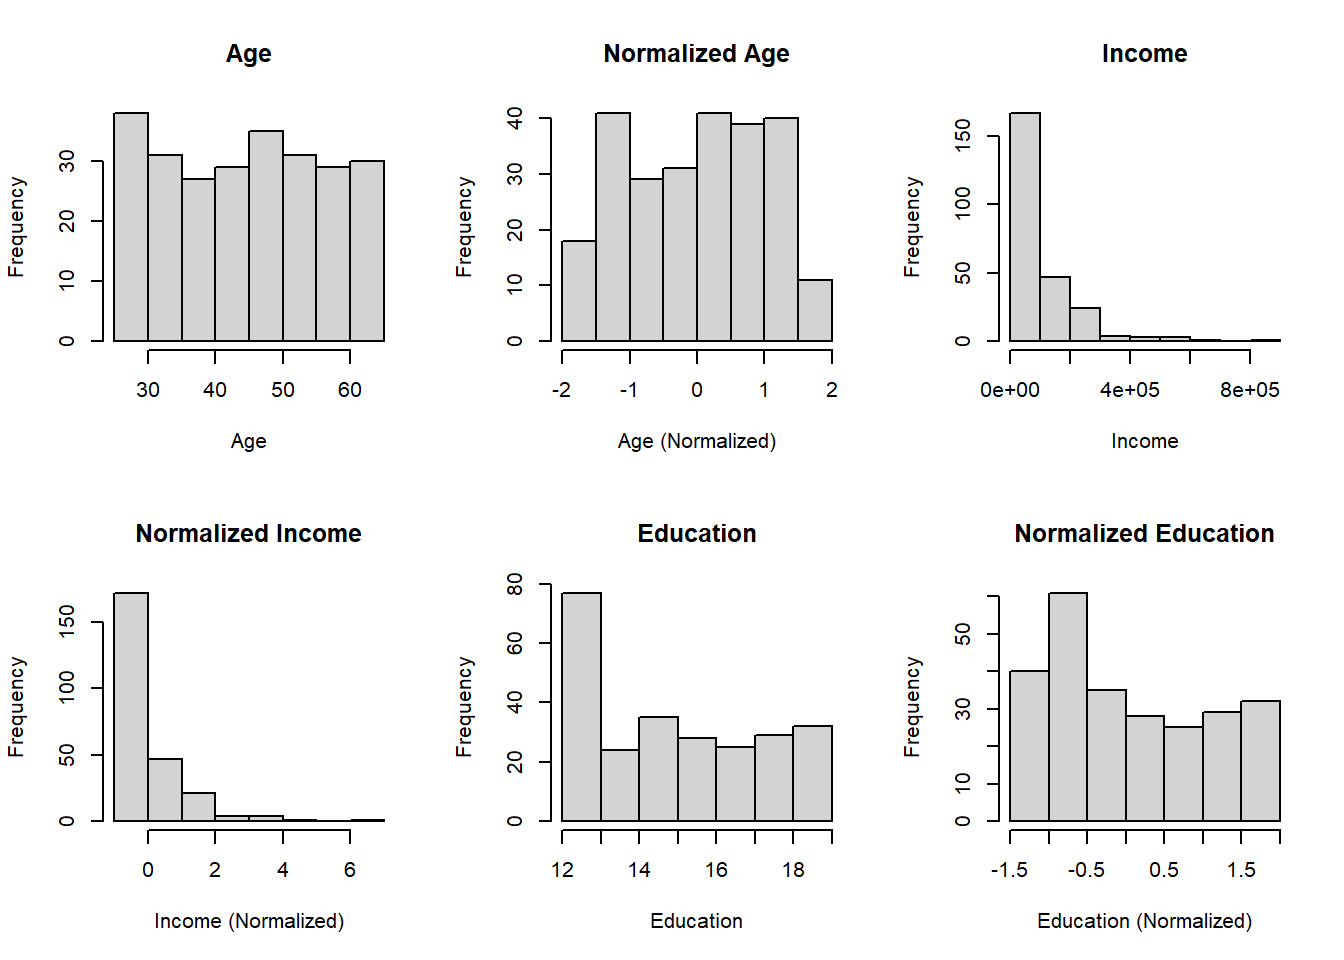
Introduction Data normalization is a crucial preprocessing step in data analysis and machine learning workflows. It helps in standardizing the scale of numeric features, ensuring fair treatment to all variables regardless of their magnitude. In ...
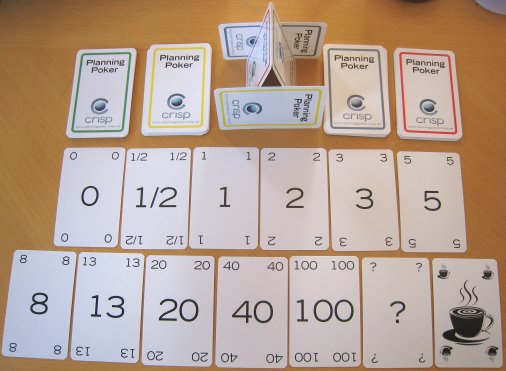
Planning poker, also called Scrum poker, is a consensus-based, gamified technique for estimating, mostly used for timeboxing in Agile principles. In planning poker, members of the group make estimates by playing numbered cards face-down to the table, instead of speaking them…
Standardization, Normalization, Robust Scaling, Mean Normalization, Maximum Absolute Scaling and Vector Unit Length Scaling
A gentle dive into this unusual feature selection technique
Python Feature Engineering Cookbook Second Edition, published by Packt - PacktPublishing/Python-Feature-Engineering-Cookbook-Second-Edition
Sourced from O'Reilly ebook of the same name.
Updates in progress. Jupyter workbooks will be added as time allows. - bjpcjp/scikit-learn
Bonus: What makes a good footballer great?
A simple technique for boosting accuracy on ANY model you use

The ability of the Generative Adversarial Networks (GANs) framework to learn generative models mapping from simple latent distributions to arbitrarily complex data distributions has been...
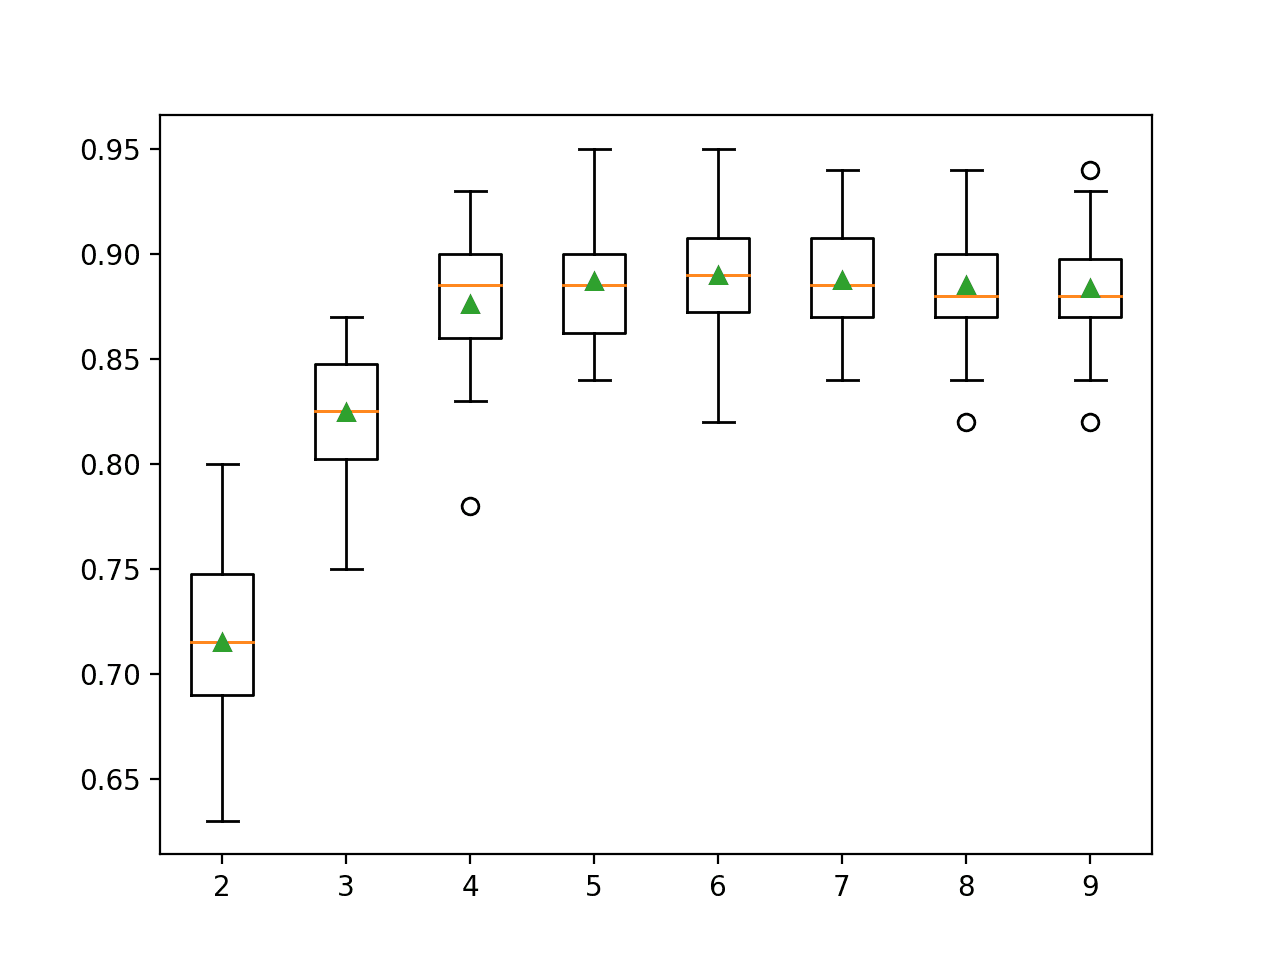
Recursive Feature Elimination, or RFE for short, is a popular feature selection algorithm. RFE is popular because it is easy to configure and use and because it is effective at selecting those features (columns) in a training dataset that are more or most relevant in predicting…
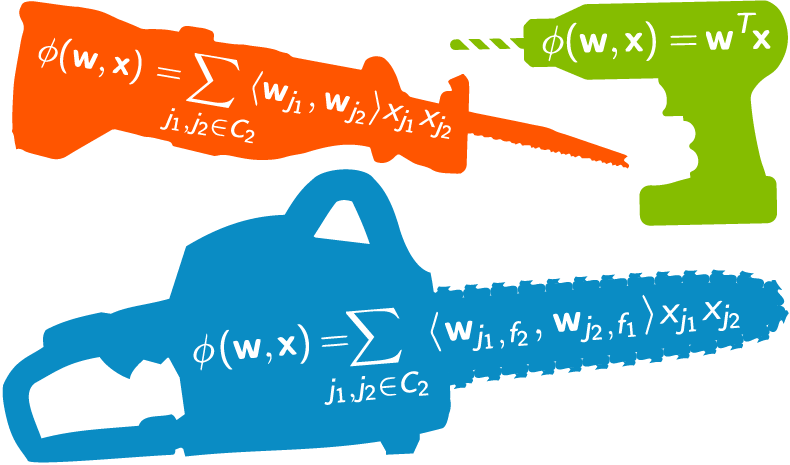
originally posted by the author on Linkedin : Link It is very tempting for data science practitioners to opt for the best known algorithms for a given problem.However It’s not the algorithm alone , which can provide the best solution ; Model built on carefully engineered and…
This article will introduce the different type of data sets, data object and attributes.
Permutation Importance as a feature selection method

The O’Reilly Data Show Podcast: Alex Ratner on how to build and manage training data with Snorkel.
This post is about some of the most common feature selection techniques one can use while working with data.
168 votes, 13 comments. 2.2M subscribers in the datascience community. A space for data science professionals to engage in discussions and debates on…
Using the FeatureSelector for efficient machine learning workflows

Stay up-to-date on the latest data science and AI news in the worlds of artificial intelligence, machine learning, deep learning, implementation, and more.

Unsure how to perform feature engineering? Here are 20 best practices and heuristics that will help you engineer great features for machine learning.
Traditional strategies for taming unstructured, textual data
Strategies for working with discrete, categorical data
Strategies for working with continuous, numerical data
Data Engineering: The Close Cousin of Data Science
2.9M subscribers in the MachineLearning community. Beginners -> /r/mlquestions , AGI -> /r/singularity, career advices -> /r/cscareerquestions…