DMA® Regions | Nielsen
DMA (Designated Market Area) regions are the geographic areas and zip codes in the U.S. in which local television viewing is measured by Nielsen.
DMA (Designated Market Area) regions are the geographic areas and zip codes in the U.S. in which local television viewing is measured by Nielsen.

Use our plastics properties table to sort and compare plastic materials. Review typical, physical, thermal, optical, electrical properties. Ask an Expert or Get a Quote.
Solar is in the process of shearing off the base of the entire global industrial stack – energy – and the tech sector still lacks a unified thesis for how to best enable, accelerate, an…
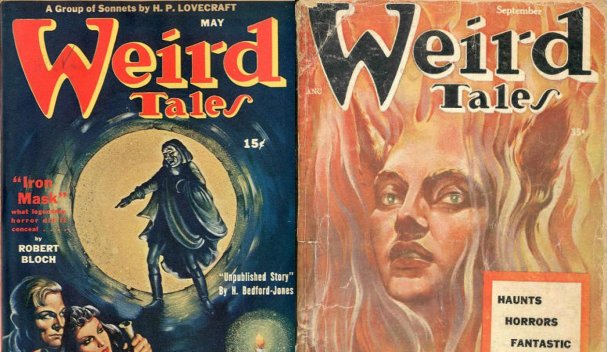
We live in an era of genre. Browse through TV shows of the last decade to see what I mean: Horror, sci-fi, fantasy, superheroes, futuristic dystopias…. Take a casual glance at the burgeoning global film franchises or merchandising empires.

Dataset distillation is an innovative approach that addresses the challenges posed by the ever-growing size of datasets in machine learning. This technique focuses on creating a compact, synthetic dataset that encapsulates the essential information of a larger dataset, enabling…

Analytics, management, and business intelligence (BI) procedures, such as data cleansing, transformation, and decision-making, rely on data profiling. Content and quality reviews are becoming more important as data sets grow in size and variety of sources. In addition…

Computer vision has advanced significantly in recent decades, thanks in large part to comprehensive benchmark datasets like COCO. However, nearly a decade after its introduction, COCO's suitability as a benchmark for modern AI models is being questioned. Its annotations may…
A Fun Tutorial using Python, JSON, and Spotify API! You might find it more comfortable...
Stats about all US cities - real estate, relocation info, crime, house prices, schools, races, income, photos, sex offenders, maps, education, weather, home value estimator, recent sales, etc.

A proactive, coordinated effort can reduce the chances that manipulations will impact model performance and protect algorithmic integrity.

Beautiful, free images and photos that you can download and use for any project. Better than any royalty free or stock photos.
Open Library is an open, editable library catalog, building towards a web page for every book ever published. Read, borrow, and discover more than 3M books for free.

The Pile is a 825 GiB diverse, open source language modelling data set that consists of 22 smaller, high-quality datasets combined together.
College Football Play-By-Play Data

Developing large-scale datasets has been critical in computer vision and natural language processing. These datasets, rich in visual and textual information, are fundamental to developing algorithms capable of understanding and interpreting images. They serve as the backbone for…

Nitasha Tiku / Washington Post: Analysis of 1,800 AI datasets: ~70% didn't state what license should be used or had been mislabeled with more permissive guidelines than their creators intended

Human motion capture has emerged as a key tool in various industries, including sports, medical, and character animation for the entertainment sector. Motion capture is utilized in sports for multiple purposes, including injury prevention, injury analysis, video game industry…
Europe at the end of the nineteenth century and beginning of the twentieth: what a time and place to be alive.
Read For Free, Anywhere, Anytime. An online library of over 1000 classic short stories. H. G. Wells, Edgar Allan Poe, H. P. Lovecraft, Anton Chekhov, Beatrix Potter.
BookCorpus has helped train at least thirty influential language models (including Google’s BERT, OpenAI’s GPT, and Amazon’s Bort), according to HuggingFace. This is the research question that…

Large-scale pre-trained Vision and language models have demonstrated remarkable performance in numerous applications, allowing for the replacement of a fixed set of supported classes with zero-shot open vocabulary reasoning over (nearly arbitrary) natural language queries…

An analysis of a chatbot data set by The Washington Post reveals the proprietary, personal, and often offensive websites that go into an AI’s training data.
A ready-to-run code which identifies and anonymises places, based on the GeoNames database
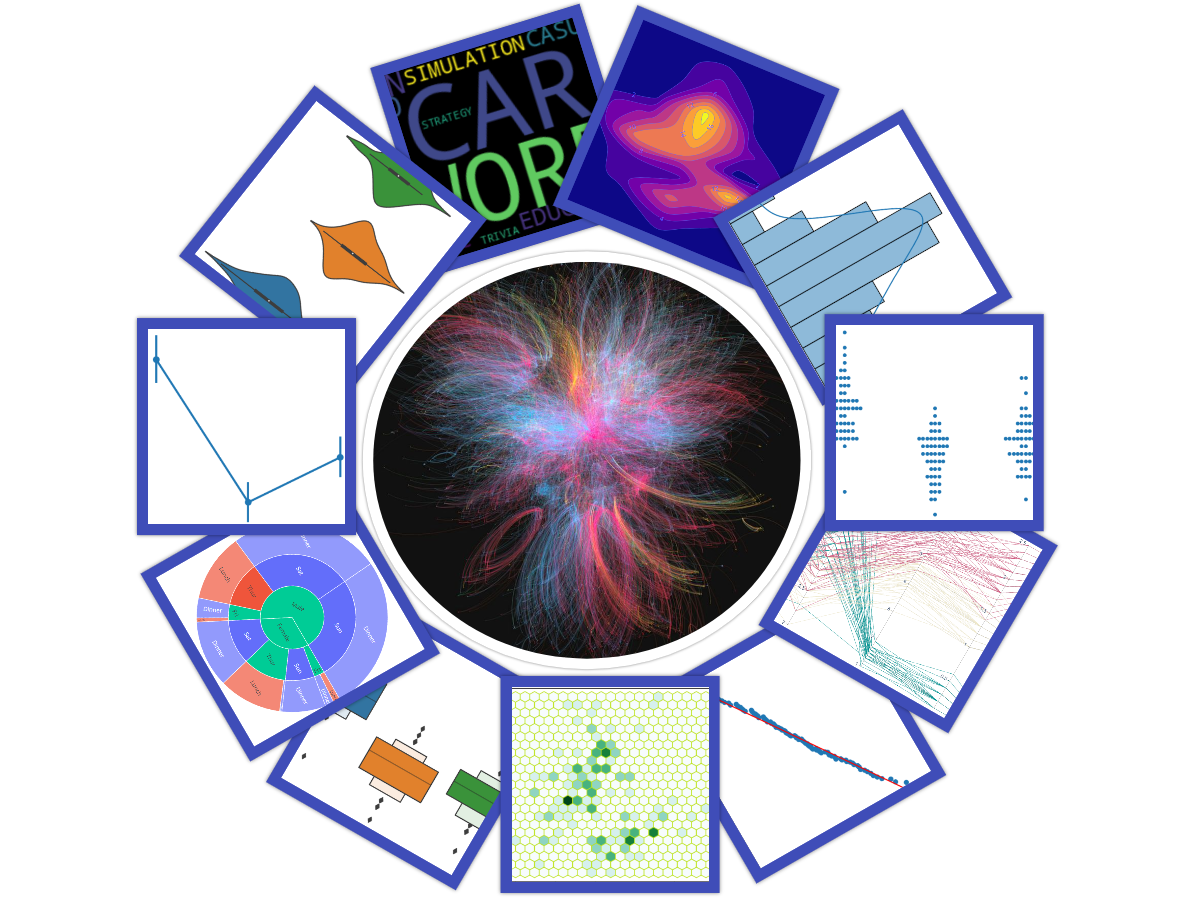
Some Unique Data Visualization Techniques for Getting High-Level Insight into the Data
Posted by Mahima Pushkarna, Senior Interaction Designer, and Andrew Zaldivar, Senior Developer Relations Engineer, Google Research As machine learn...
Build geo specific subset of LAION-5B
The Allen Institute’s release includes recordings from a whopping 300,000 mouse neurons. Now the challenge is figuring out what to do with all that data.
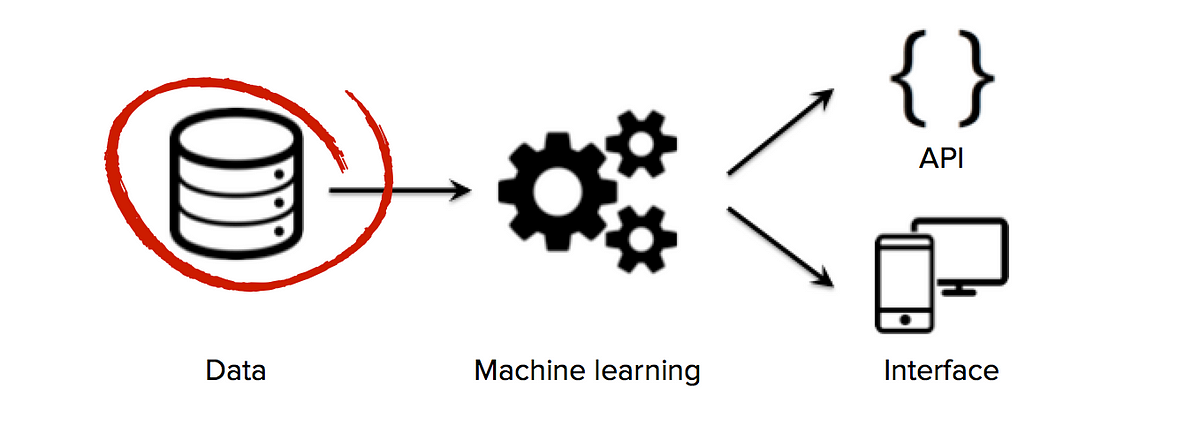
The “unreasonable effectiveness” of data for machine-learning applications has been widely debated over the years (see here, here and…

We introduce ArtBench-10, the first class-balanced, high-quality, cleanly annotated, and standardized dataset for benchmarking artwork generation. It comprises 60,000 images of artwork from 10...
Posted by Sara Beery, Student Researcher, and Jonathan Huang, Research Scientist, Google Research, Perception Team Over four billion people live in...
When AllMusic launched 25 years ago, it wasn't an obvious big data play. But it became one. Hidden in its millions of entries is music's collective history.
To understand what's happening, but also what's coming if synthetic data does get more broadly adopted, we talked to various CEOs and VCs over the last few months.
How you can pull one of a few dozen example political, sporting, education, and other frames on-the-fly.
Our zip code database is a unified view of public datasets like the Census, American Community Survey, Bureau of Labor Statistics and the CDC, spanning 800+ data points, also offering a free zip code database.
You can either Collect Data or Create your Own Data
Best-practices to follow when building datasets from large pools of image and video data and tools that make it straightforward.
MedMNIST v2 is a large-scale MNIST-like collection of standardized biomedical images, including 12 datasets for 2D and 6 datasets for 3D. All images are pre-processed into 28 x 28 (2D) or 28 x 28 x 28 (3D) with the corresponding classification labels, so that no background…

The release of the FC-AMF-OCR Dataset by LightOn marks a significant milestone in optical character recognition (OCR) and machine learning. This dataset is a technical achievement and a cornerstone for future research in artificial intelligence (AI) and computer vision…