llms
905 bookmarks · page 13 of 19
2024-04-14 · kenkantzer.com
My startup Truss (gettruss.io) released a few LLM-heavy features in the last six months, and the narrative around LLMs that I read on Hacker News is now starting to diverge from my reality, so I thought I’d share some of the more “surprising” lessons after churning through just…
2024-04-13 · kdnuggets.com
Run large language models on your local PC for customized AI capabilities with more control, privacy, and personalization.
2024-04-13 · arstechnica.com
Gemini 1.5 Pro launch, new version of GPT-4 Turbo, new Mistral model, and more.
2024-04-12 · dev.to
2024-04-11 · marktechpost.com

Claude and ChatGPT are two compelling options in AI chatbots, each with unique features and capabilities. To discern their strengths and suitability for various applications, let's compare these two AI chatbots comprehensively. What is Claude? Claude is an AI chatbot developed…
2024-04-10 · linkedin.com
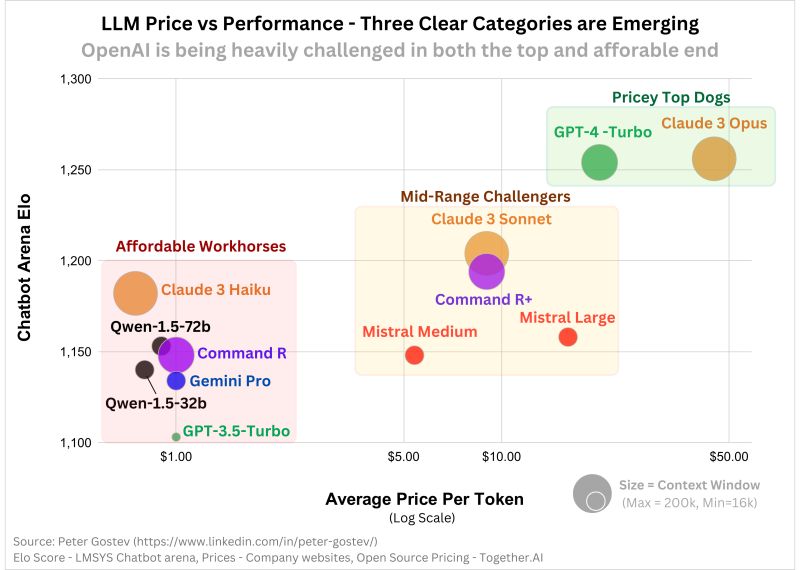
We are seeing some clear categories emerge in the world of LLMs - 1) affordable (~$1 per million tokens); 2) mid-range ($8/m) and 3) top end ($25-50/m)… | 32 comments on LinkedIn
2024-04-09 · youtube.com
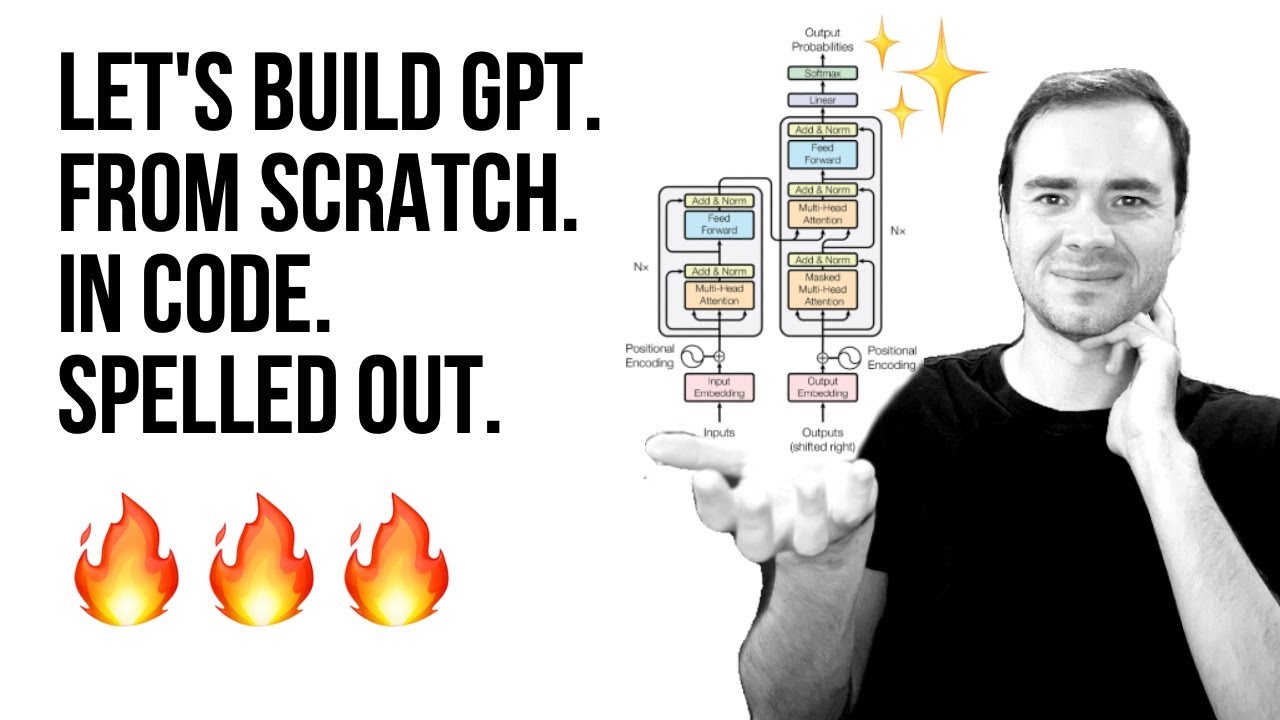
We build a Generatively Pretrained Transformer (GPT), following the paper "Attention is All You Need" and OpenAI's GPT-2 / GPT-3. We talk about connections to ChatGPT, which has taken the world by storm. We watch GitHub Copilot, itself a GPT, help us write a GPT (meta :D!) . I…
2024-04-09 · theverge.com

More AI image generation tools at your fingertips.
2024-04-08 · marktechpost.com

In the ever-evolving landscape of artificial intelligence, businesses face the perpetual challenge of harnessing vast amounts of unstructured data. Meet RAGFlow, a groundbreaking open-source AI project that promises to revolutionize how companies extract insights and answer…
2024-04-08 · dev.to
In a previous post, I demonstrated how to implement RAG using the Load-Transform-Embed-Store...
2024-04-05 · dev.to
In the world of LLMs, there is a phenomenon known as "hallucinations." These hallucinations are...
2024-04-05 · marktechpost.com

The top open source Large Language Models available for commercial use are as follows. Llama - 2 Meta released Llama 2, a set of pretrained and refined LLMs, along with Llama 2-Chat, a version of Llama 2. These models are scalable up to 70 billion parameters. It was discovered…
2024-04-02 · justine.lol
I wrote 84 new matmul kernels to improve llamafile CPU performance.
2024-04-02 · news.mit.edu
Researchers find large language models use a simple mechanism to retrieve stored knowledge when they respond to a user prompt. These mechanisms can be leveraged to see what the model knows about different subjects and possibly to correct false information it has stored.
2024-04-02 · databricks.com
2024-04-01 · marktechpost.com

What is ChatGPT? ChatGPT, developed by OpenAI, is an AI platform renowned for its conversational AI capabilities. Leveraging the power of the Generative Pre-trained Transformer models, ChatGPT generates human-like text responses across various topics, from casual conversations…
2024-03-30 · thegradient.pub
Is Attention all you need? Mamba, a novel AI model based on State Space Models (SSMs), emerges as a formidable alternative to the widely used Transformer models, addressing their inefficiency in processing long sequences.
2024-03-29 · nextplatform.com
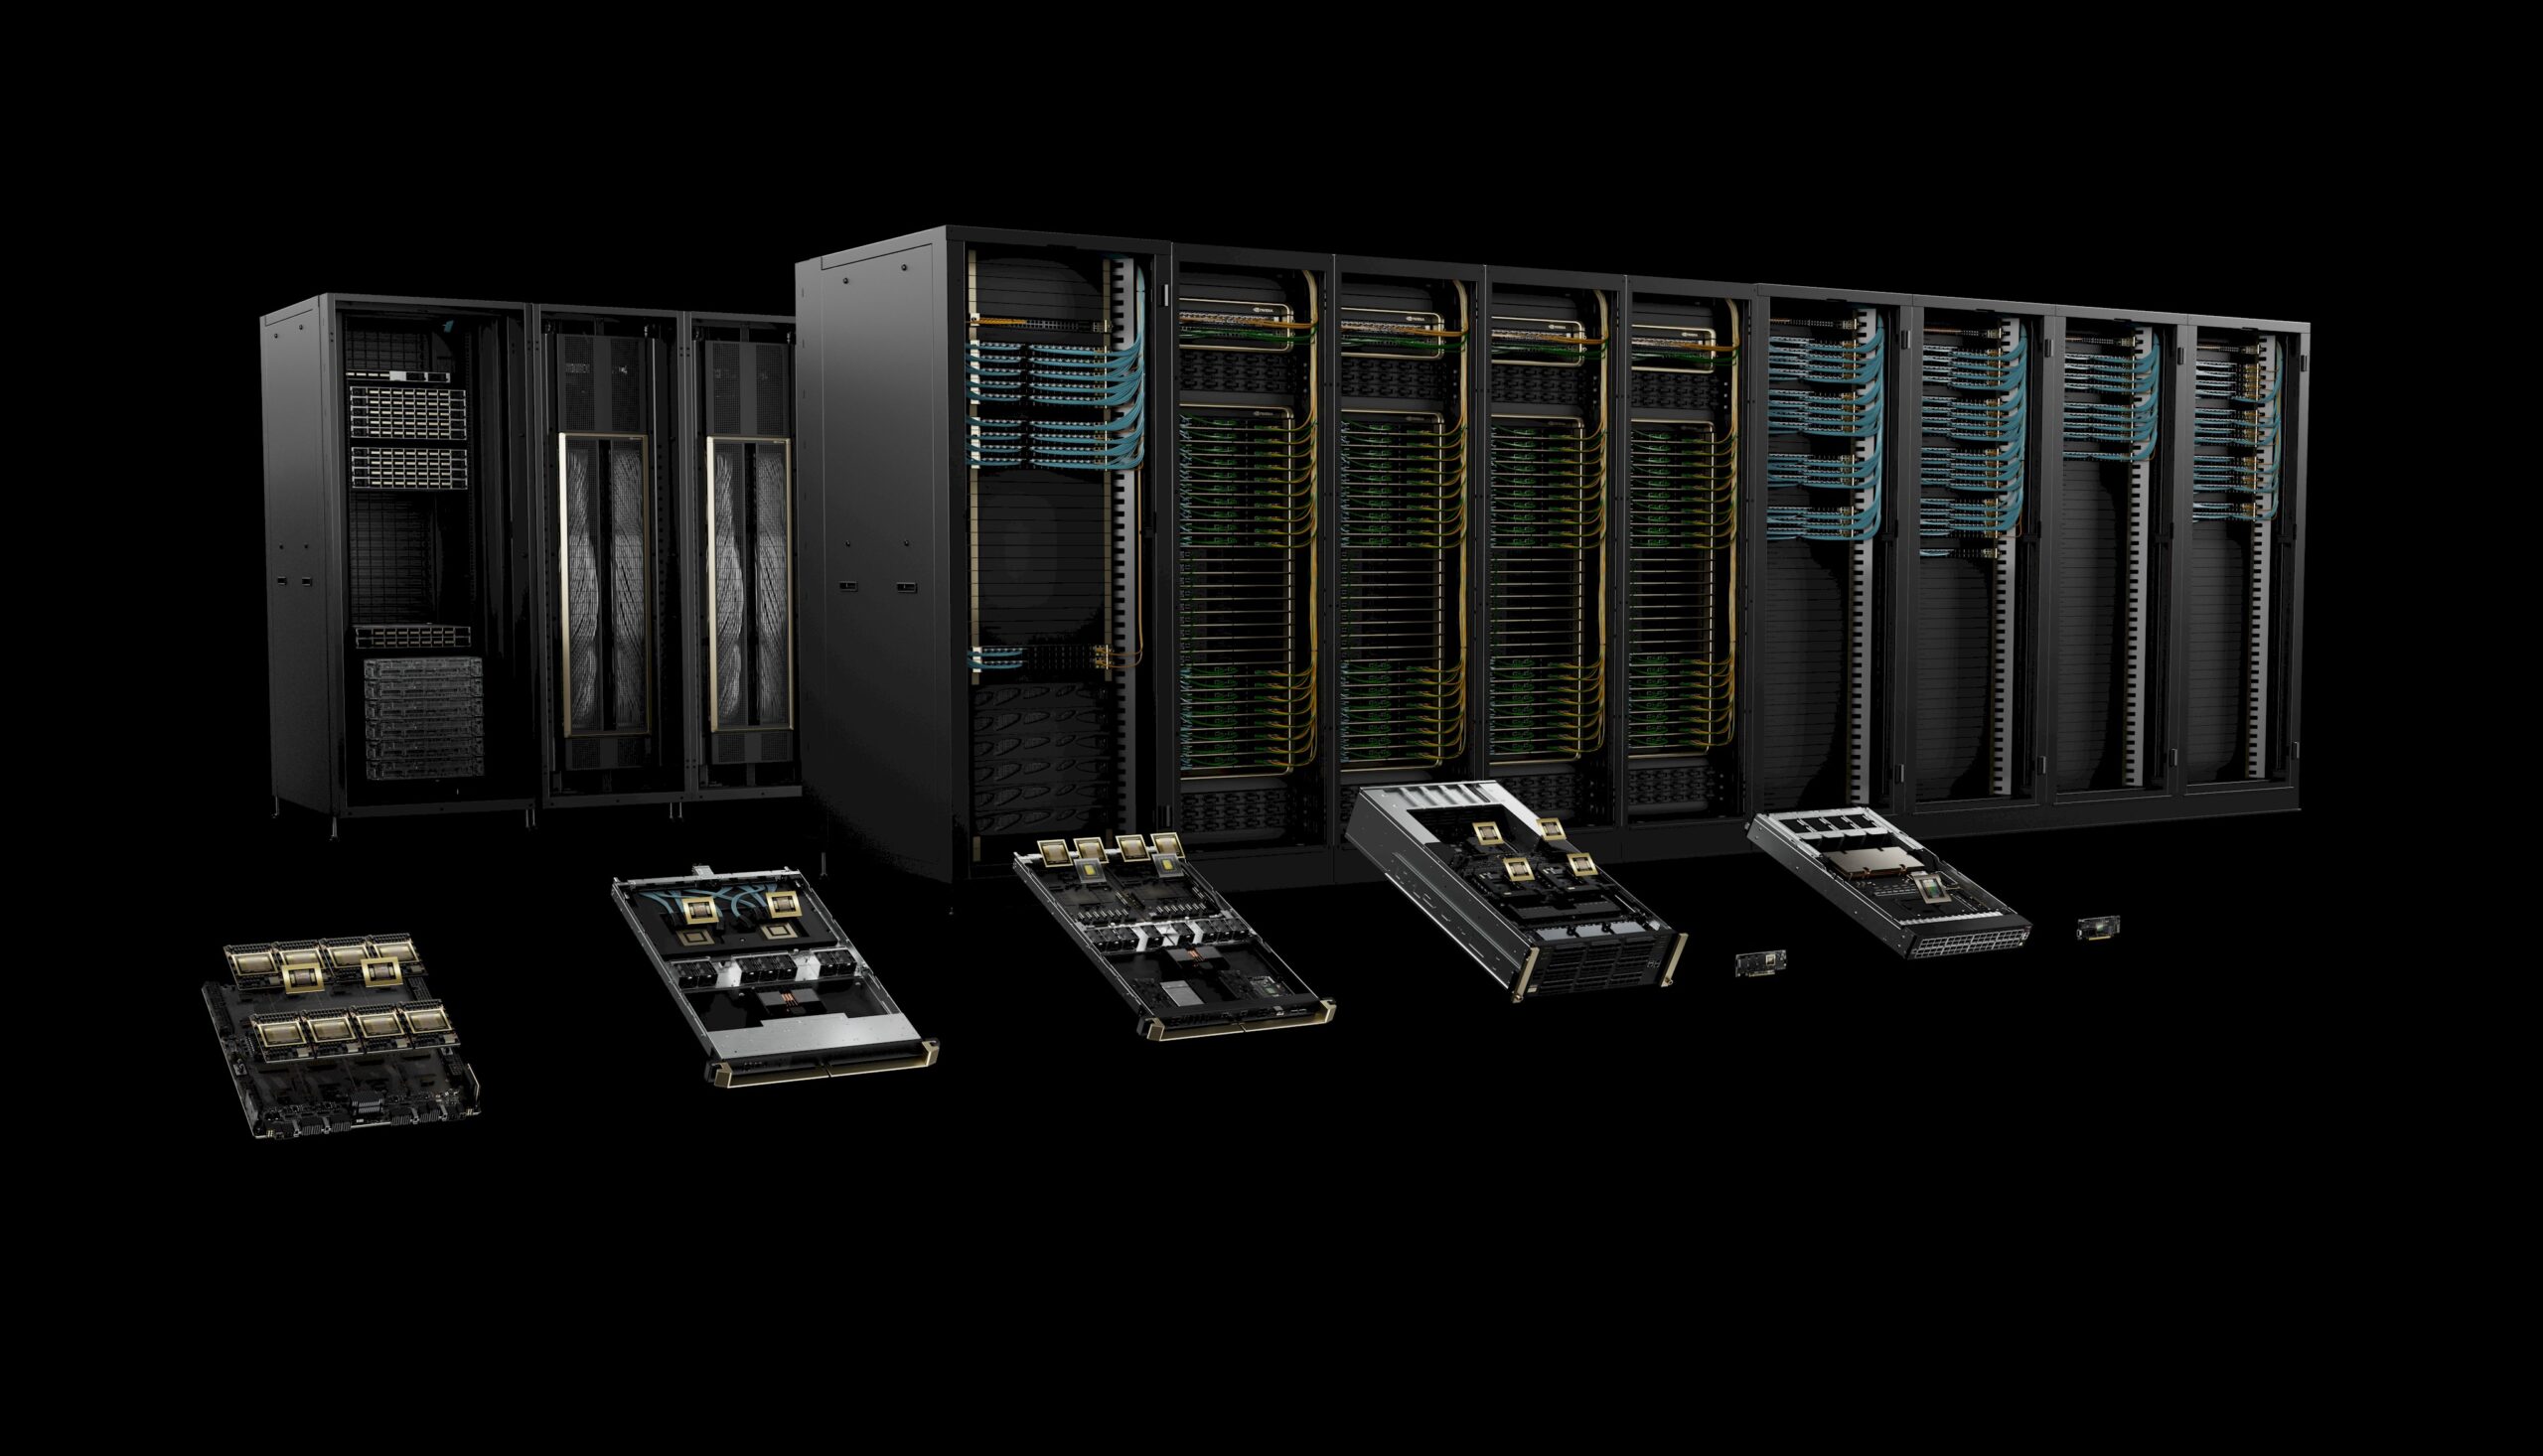
We like datacenter compute engines here at The Next Platform, but as the name implies, what we really like are platforms – how compute, storage,
2024-03-29 · quantamagazine.org

Large language models do better at solving problems when they show their work. Researchers are beginning to understand why.
2024-03-11 · towardsdatascience.com
Language models (LLMs) have revolutionized the field of natural language processing (NLP) over the last few years, achieving…
2024-03-11 · towardsdatascience.com
Reference architecture patterns and mental models for working with Large Language Models (LLM’s)
2024-03-11 · answer.ai
We’re releasing an open source system, based on FSDP and QLoRA, that can train a 70b model on two 24GB GPUs.
2024-03-11 · towardsdatascience.com
Training a specialized LLM over your own data is easier than you think…
2024-03-07 · axios.com
The search giant is unifying its AI-assistant efforts under one name and trying to show it can match rivals.
2024-03-05 · explainextended.com
A complete GPT2 implementation as a single SQL query in PostgreSQL.
2024-03-05 · linkedin.com
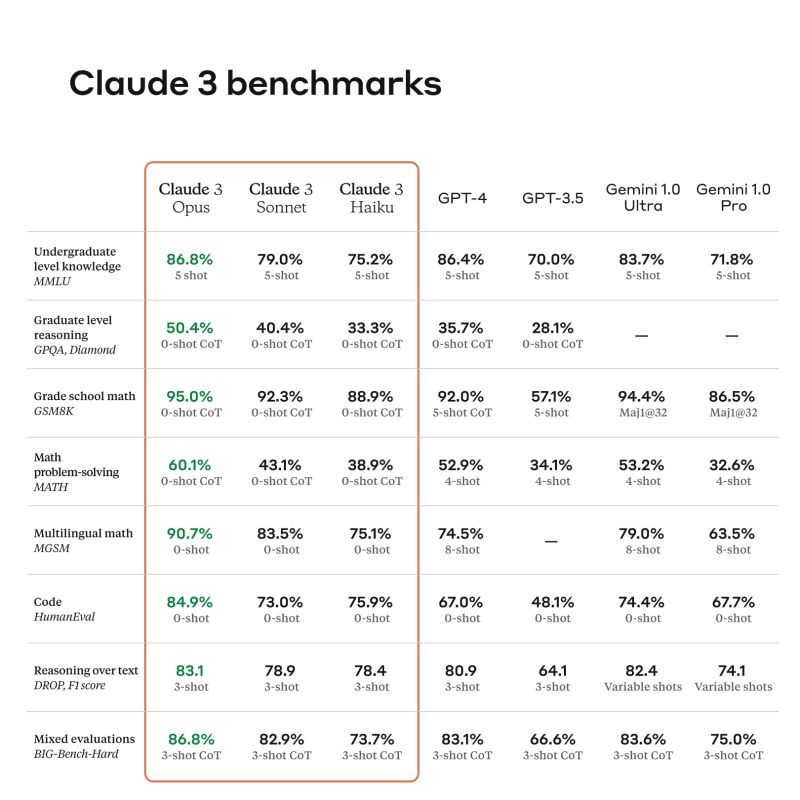
Today, we're announcing the Claude 3 model family, which sets new industry benchmarks across a wide range of cognitive tasks. The family includes three… | 429 comments on LinkedIn
2024-03-05 · qz.com
The Amazon-backed AI startup said its "most intelligent model" outperformed OpenAI's powerful GPT-4
2024-03-05 · digiday.com
OpenAI's custom GPTs and GPT Store could proffer a potential new platform for publishers to drive referral traffic.
2024-02-29 · github.com
Implementing a ChatGPT-like LLM in PyTorch from scratch, step by step - rasbt/LLMs-from-scratch
2024-02-29 · marktechpost.com

Understanding how well they comprehend and organize information is crucial in advanced language models. A common challenge arises in visualizing the intricate relationships between different document parts, especially when using complex models like the Retriever-Answer Generator…
2024-02-29 · dataconomy.com
Step into the future of video creation with Google Lumiere, the latest breakthrough from Google Research that promises to redefine
2024-02-29 · towardsdatascience.com

Keep up with the latest ML research
2024-02-29 · marktechpost.com

Prompt engineering has burgeoned into a pivotal technique for augmenting the capabilities of large language models (LLMs) and vision-language models (VLMs), utilizing task-specific instructions or prompts to amplify model efficacy without altering core model parameters. These…
2024-02-29 · simonwillison.net
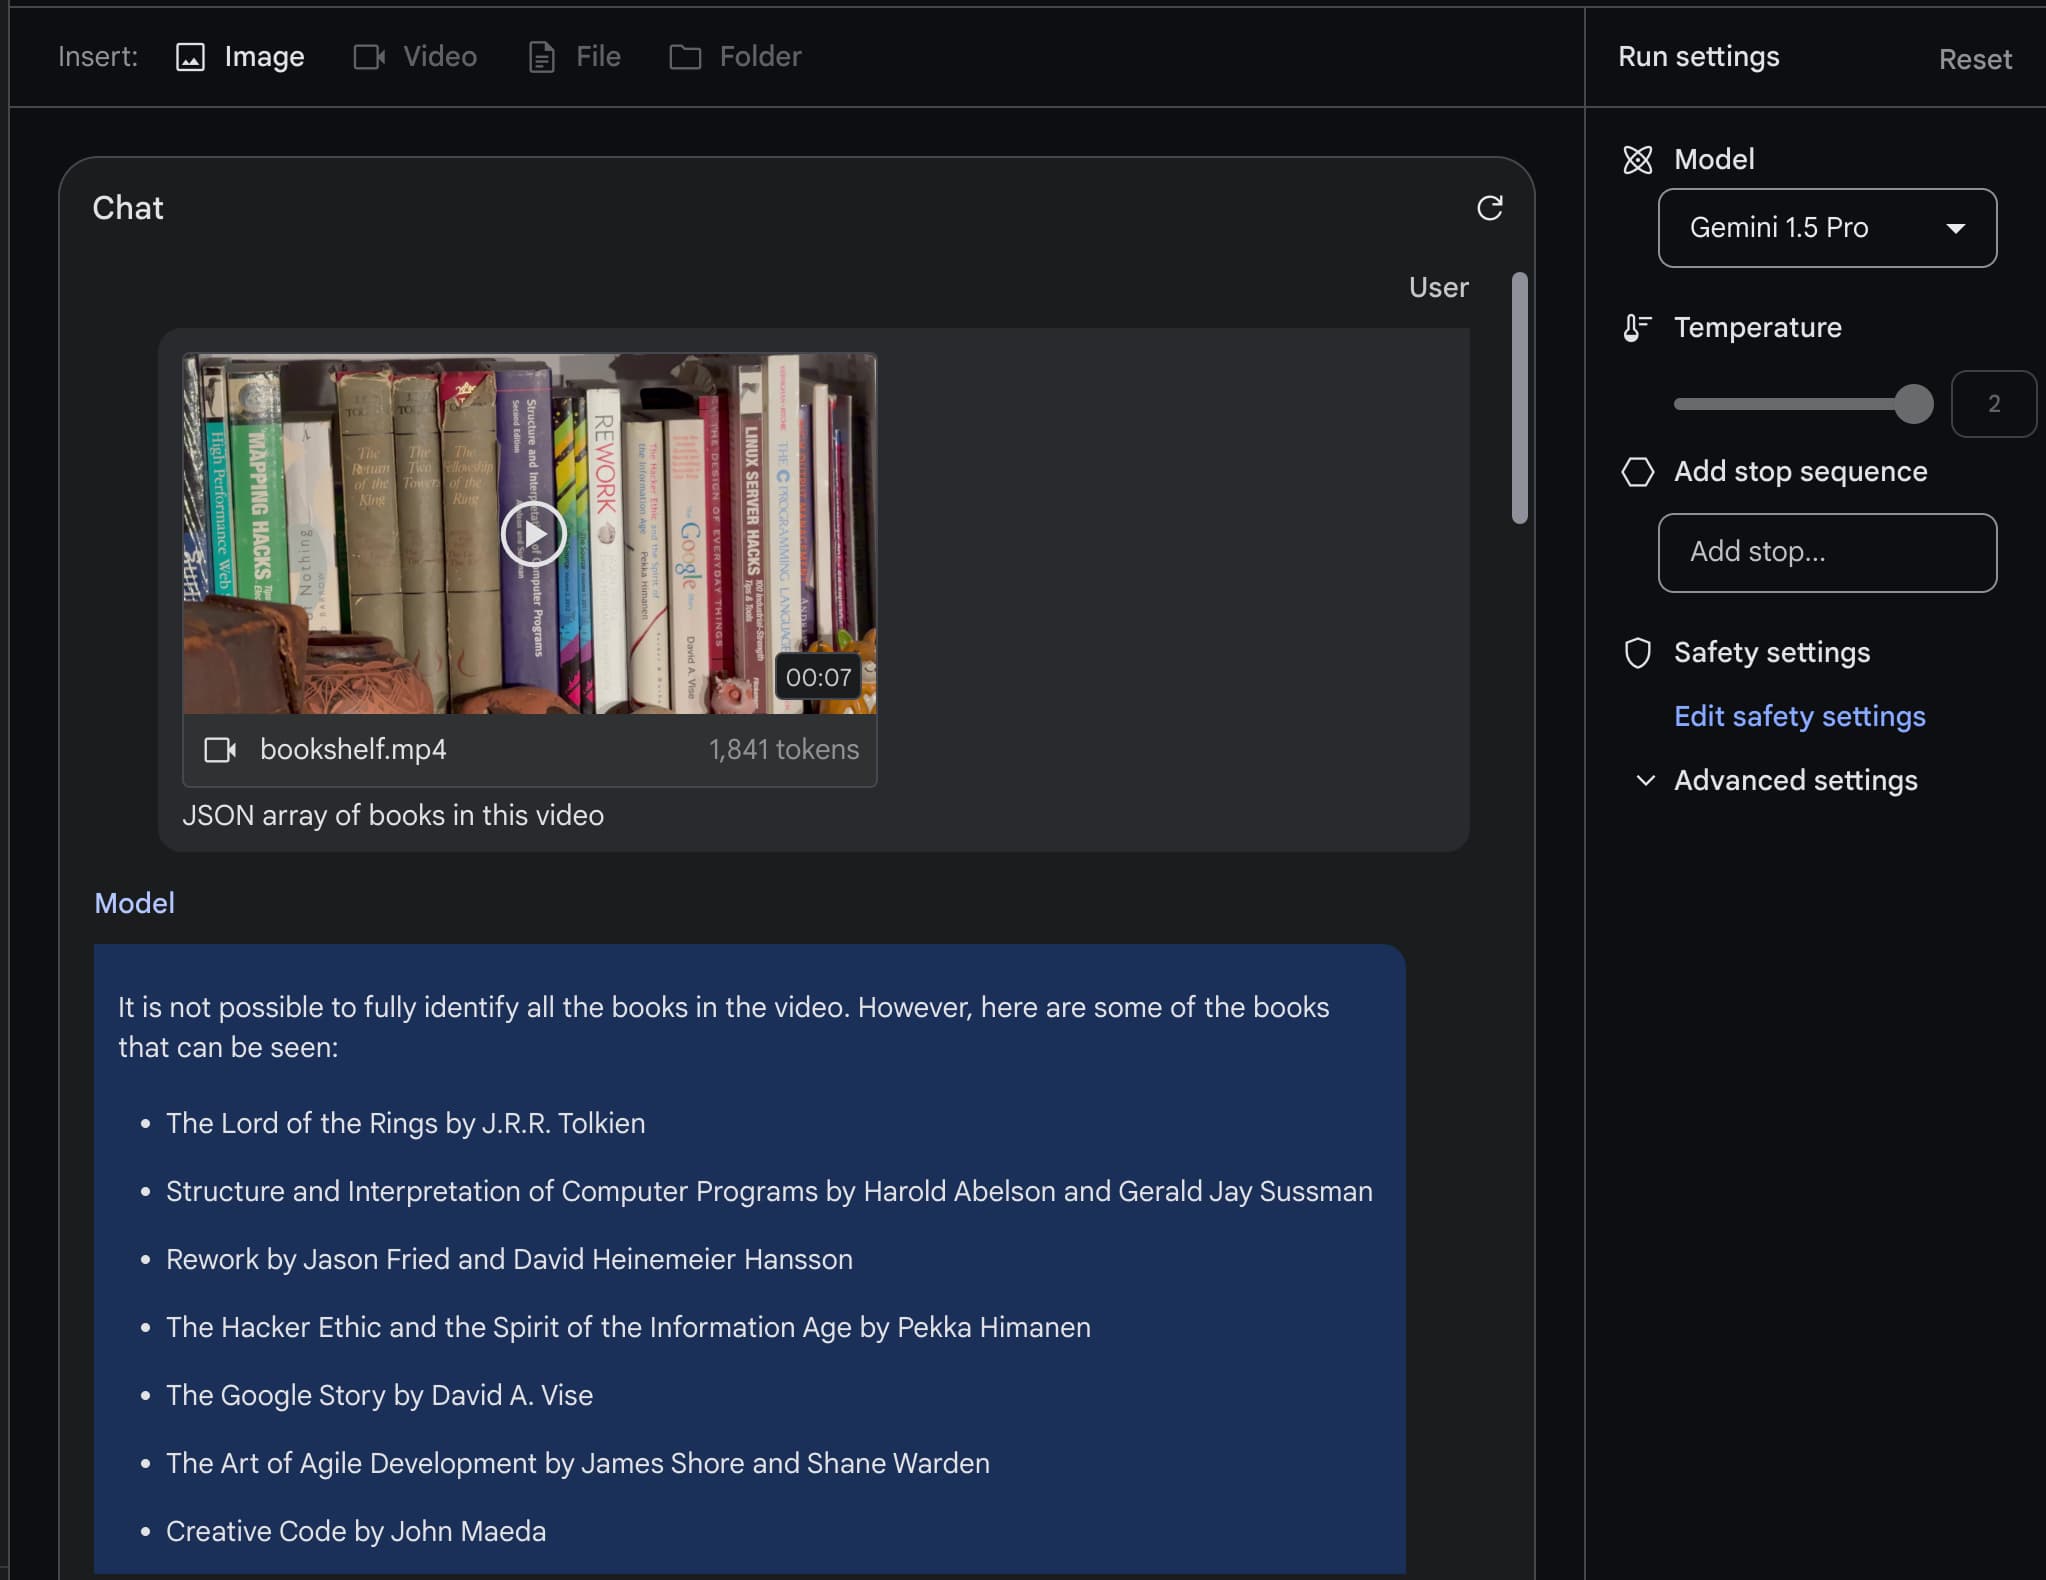
Last week Google introduced Gemini Pro 1.5, an enormous upgrade to their Gemini series of AI models. Gemini Pro 1.5 has a 1,000,000 token context size. This is huge—previously that …
2024-02-29 · towardsdatascience.com
This blog post will look at the “Direct Preference Optimization: Your Language Model is Secretly a Reward Model” paper and its findings.
2024-02-29 · every.to
When it comes to context windows, size matters
2024-02-29 · towardsdatascience.com

The Math and the Code Behind Attention Layers in Computer Vision
2024-02-29 · arxiv.org

Recent research, such as BitNet, is paving the way for a new era of 1-bit Large Language Models (LLMs). In this work, we introduce a 1-bit LLM variant, namely BitNet b1.58, in which every single...
2024-02-29 · towardsdatascience.com
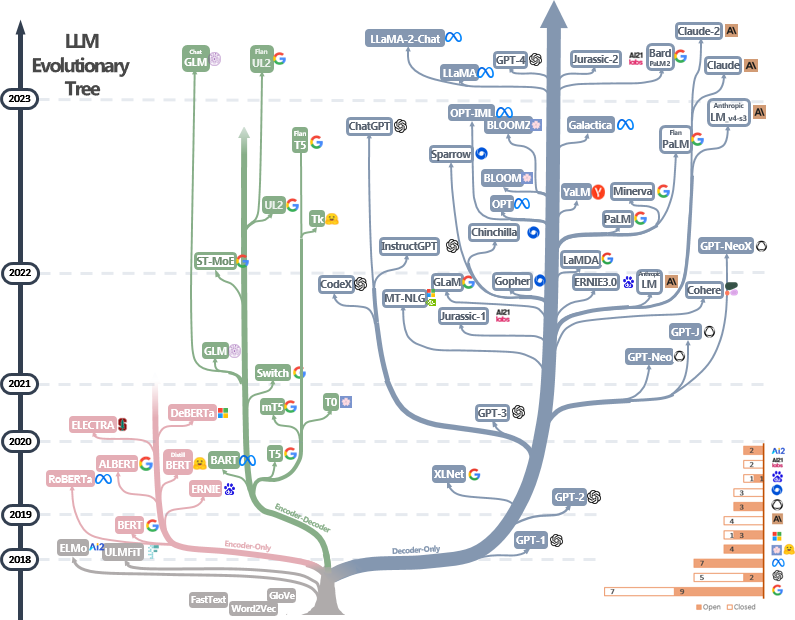
How do we communicate effectively with LLMs?
2024-02-29 · dataconomy.com
Are you looking for the news everyday for Sora early access like us? Well you are absolutely right because OpenAI's
2024-02-29 · mistral.ai
Mistral Large is our flagship model, with top-tier reasoning capacities. It is also available on Azure.
2024-02-28 · wired.com
Sure, anyone can use OpenAI’s chatbot. But with smart engineering, you can get way more interesting results.
2024-02-22 · claude.ai
Talk with Claude, an AI assistant from Anthropic
2024-02-22 · webdesignerdepot.com

In the rapidly evolving world of artificial intelligence, the ability to communicate effectively with AI tools has become an indispensable skill. Whether you're generating content, solving complex data problems, or creating stunning digital art, the quality of the outcomes you…
2024-02-22 · shyam.blog
A deep dive into the internals of a small transformer model to learn how it turns self-attention calculations into accurate predictions for the next token.
2024-02-22 · open.substack.com
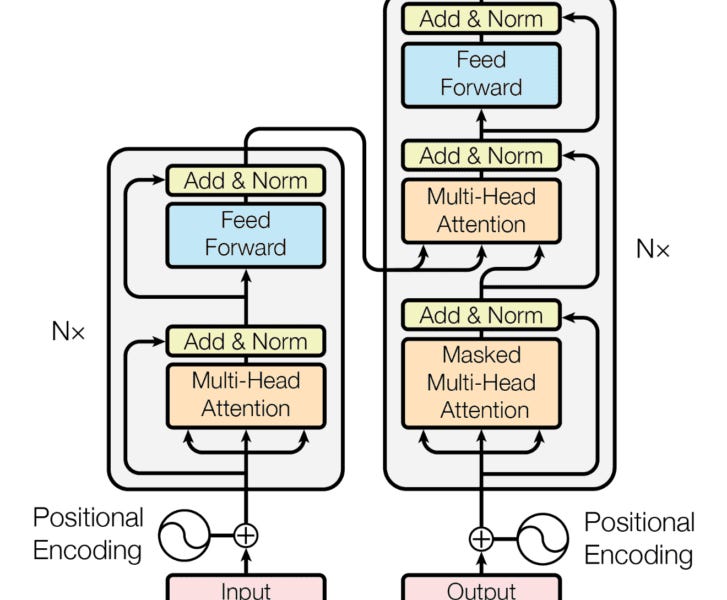
We will deep dive into understanding how transformer model work like BERT(Non-mathematical Explanation of course!). system design to use the transformer to build a Sentiment Analysis
2024-02-22 · blocksandfiles.com
Startup Groq has developed an machine learning processor that it claims blows GPUs away in large language model workloads – 10x faster than an Nvidia GPU at 10 percent of the cost, and needing a tenth of the electricity. Update: Groq model compilation time and time from access…
2024-02-22 · media.licdn.com
2024-02-22 · semianalysis.com
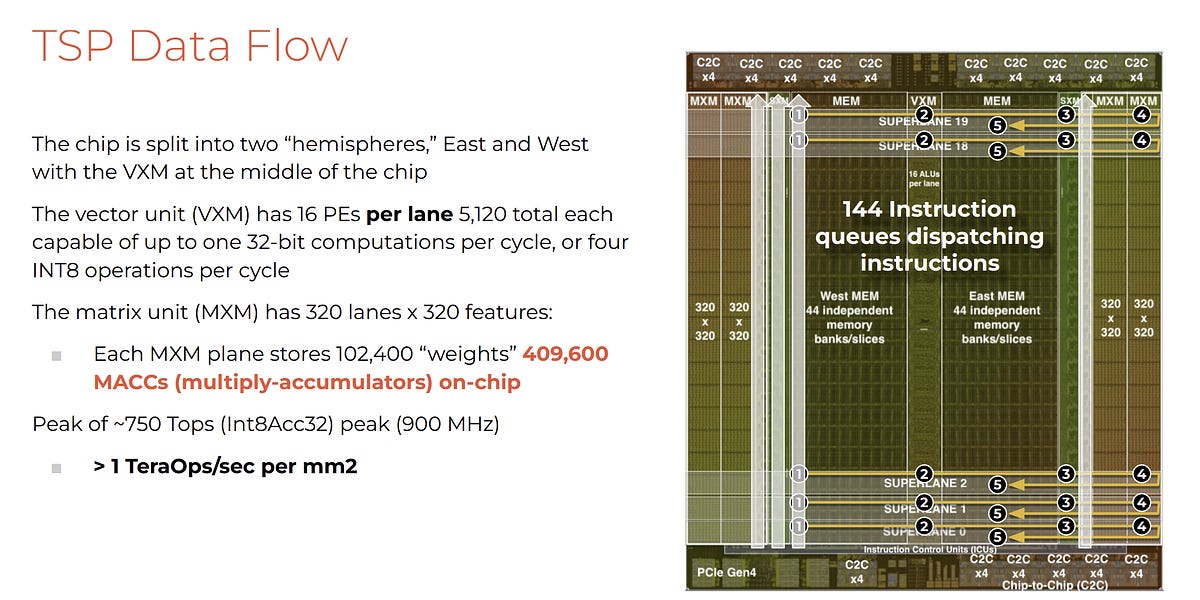
Faster than Nvidia? Dissecting the economics
2024-02-20 · marktechpost.com

In artificial intelligence, the capacity of Large Language Models (LLMs) to negotiate mirrors a leap toward achieving human-like interactions in digital negotiations. At the heart of this exploration is the NEGOTIATION ARENA, a pioneering framework devised by researchers from…