llms
905 bookmarks · page 6 of 19
2026-01-04 · semiengineering.com

A new technical paper titled “Prefill vs. Decode Bottlenecks: SRAM-Frequency Tradeoffs and the Memory-Bandwidth Ceiling” was published by researchers at Uppsala University. Abstract “Energy consumption dictates the cost and environmental impact of deploying Large Language…
Our simulation methodology combines OpenRAM for energy modeling, LLMCompass for latency simulation, and ScaleSIM for systolic array operational intensity.
Counter-intuitively, high compute frequency can reduce total energy by reducing execution time and consequently decreasing static energy consumption more than the resulting dynamic power increase
2026-01-03 · magazine.sebastianraschka.com

From DeepSeek-V3 to Kimi K2: A Look At Modern LLM Architecture Design
2026-01-03 · ollama.com
Search for models on Ollama.
2026-01-03 · minimaxir.com
The problem with Nano Banana Pro is that it’s too good.
2026-01-03 · minimaxir.com
Nano Banana allows 32,768 input tokens and I’m going to try to use them all dammit.
2026-01-03 · openai.com

We’re releasing a new class of reinforcement learning algorithms, Proximal Policy Optimization (PPO), which perform comparably or better than state-of-the-art approaches while being much simpler to implement and tune. PPO has become the default reinforcement learning algorithm…
2026-01-02 · magazine.sebastianraschka.com
In June, I shared a bonus article with my curated and bookmarked research paper lists to the paid subscribers who make this Substack possible.
★ 2026-01-01 · simonwillison.net
This is the third in my annual series reviewing everything that happened in the LLM space over the past 12 months. For previous years see Stuff we figured out about …
It turned out that the real unlock of reasoning was in driving tools.
notable result is that AI assisted search actually works now.
2025-12-31 · sebastianraschka.com

A curated list of LLM research papers from July–December 2025, organized by reasoning models, inference-time scaling, architectures, training efficiency, and...
Reasoning
Reinforcement Learning
2025-12-31 · magazine.sebastianraschka.com
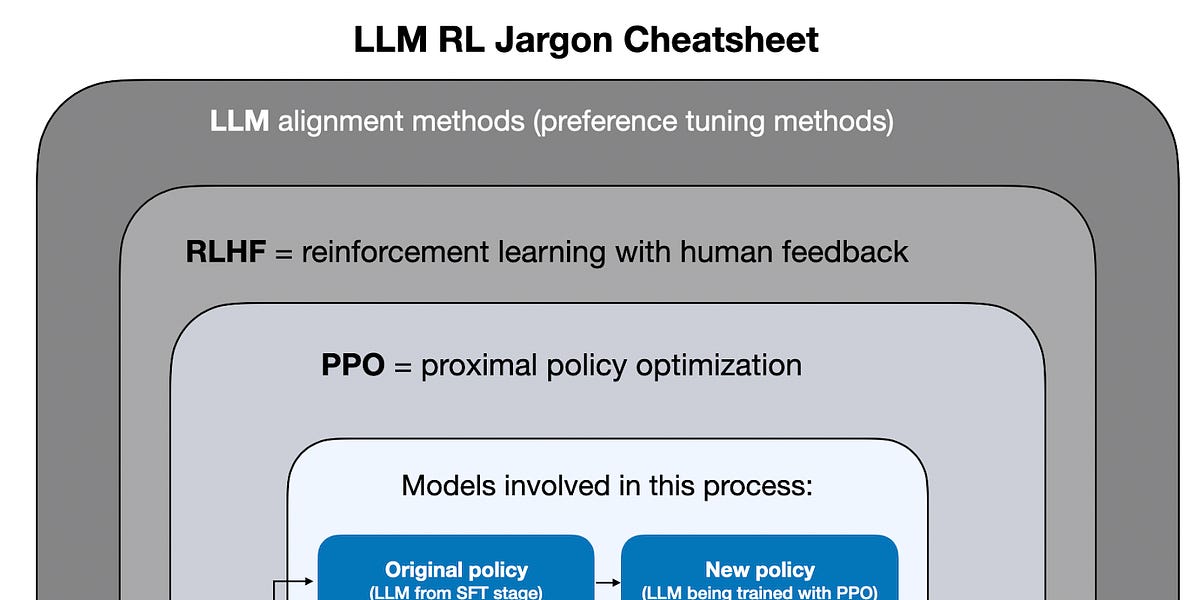
Understanding GRPO and New Insights from Reasoning Model Papers
the muted response to GPT-4.5 and Llama 4 (non-reasoning) models suggests we are approaching the limits of what scaling model size and data alone can achieve.
★ 2025-12-31 · sebastianraschka.com
A 2025 review of large language models, from DeepSeek R1 and RLVR to inference-time scaling, benchmarks, architectures, and predictions for 2026.
DeepSeek released their R1 paper in January 2025, which showed that reasoning-like behavior can be developed with reinforcement learning, it was a really big deal
DeepSeek R1 was released as an open-weight model
2025-12-28 · platform.claude.com

Claude API Documentation
2025-12-26 · catalinionescu.dev
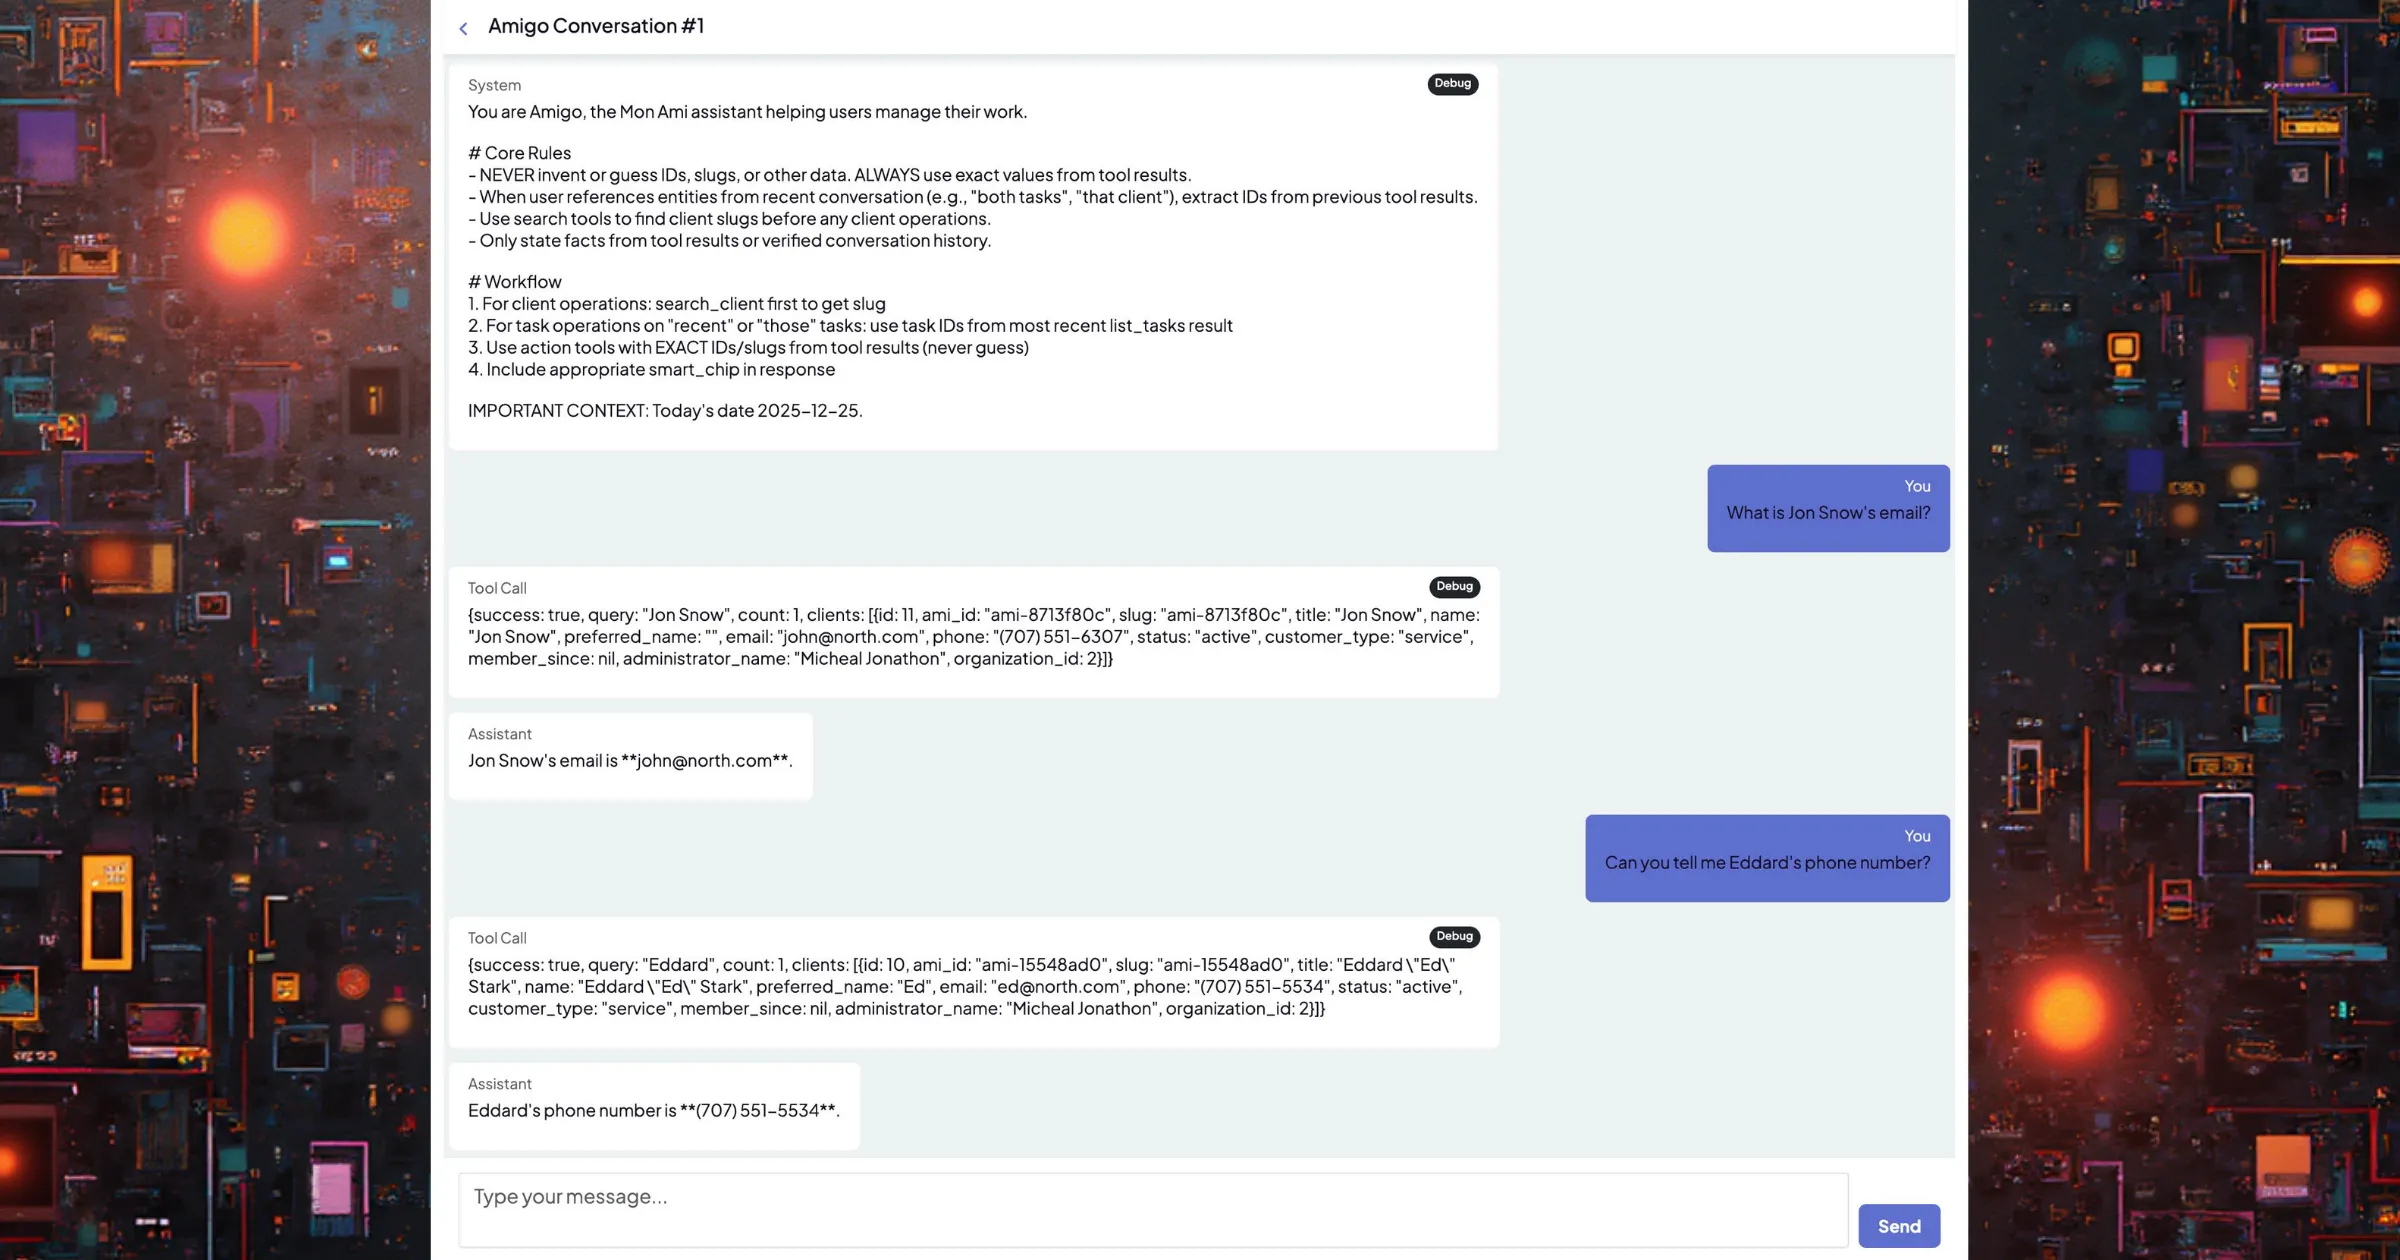
We run a multi-tenant Rails application with sensitive data and layered authorization. In this post, I walk through how I added the first AI agent tool using RubyLLM, Pundit policies, and our existing Algolia search, without introducing a parallel system or loosening constraints.
2025-12-23 · amanxai.com
In this article, I’ll walk you through a complete guide to LangGraph from the ground up. LangGraph Explained from Scratch.
In LangChain, this usually means moving from user input to a prompt, then to the LLM, and finally to the output
ollama pull llama3
2025-12-19 · karpathy.bearblog.dev
2025 Year in Review of LLM paradigm changes
Reinforce
Reinforcement Learning from Verifiable Rewards (RLVR)
2025-12-19 · ngrok.com
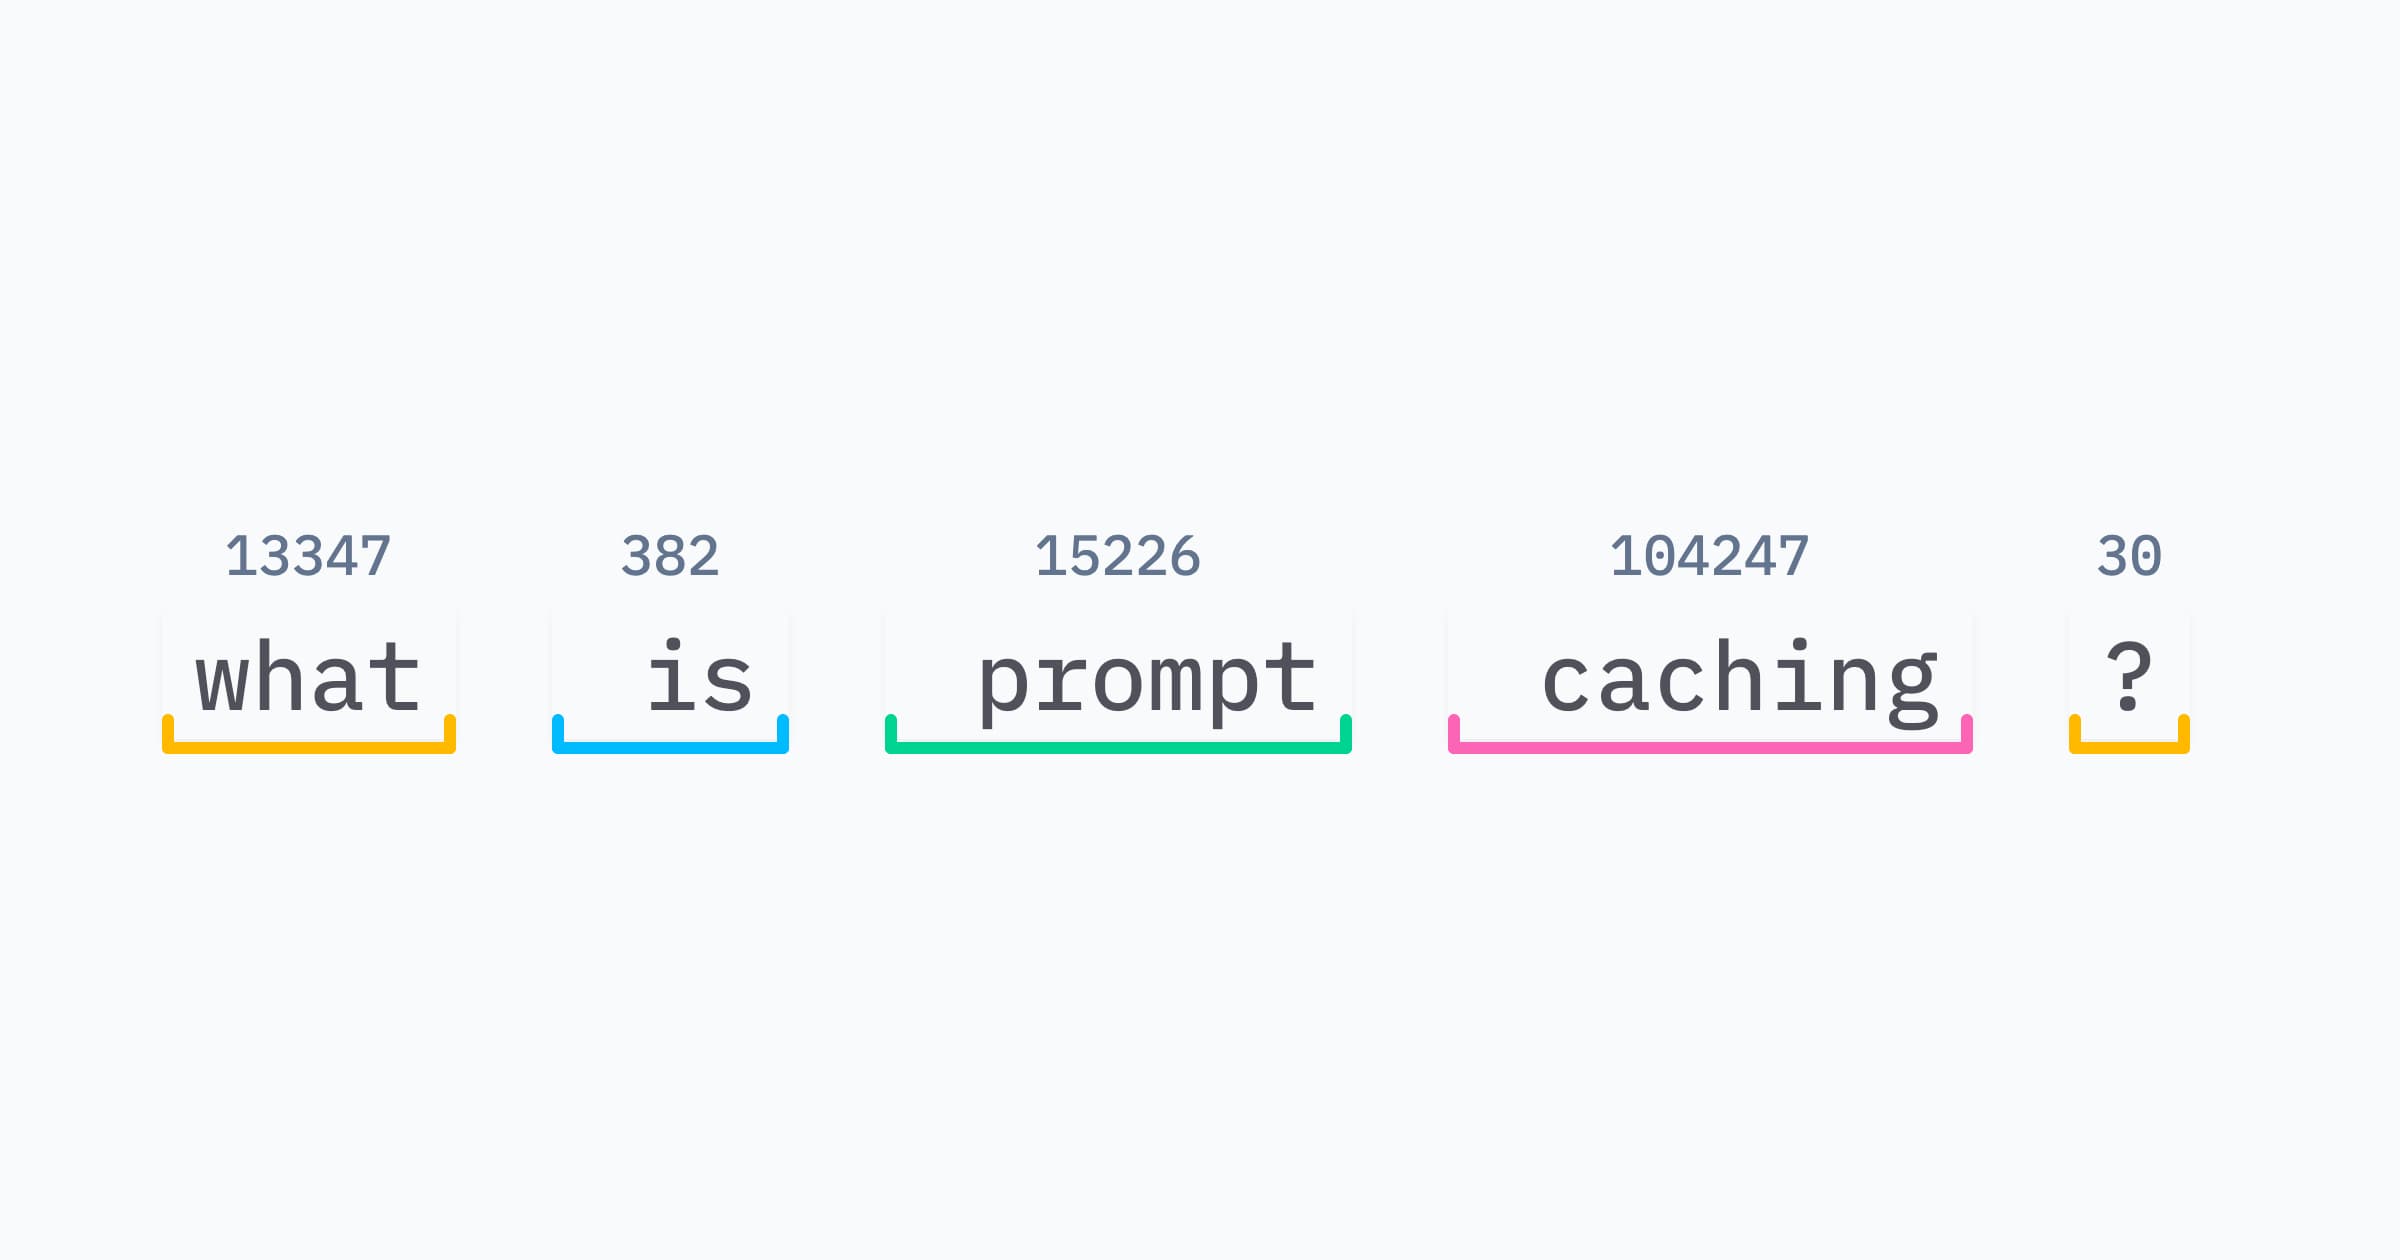
A far more detailed explanation of prompt caching than anyone asked for.
2025-12-15 · dataconomy.com
The AI industry has a trust problem that mirrors a paradox Daniel Kahneman identified decades ago in human decision-making: people
2025-12-12 · open.substack.com
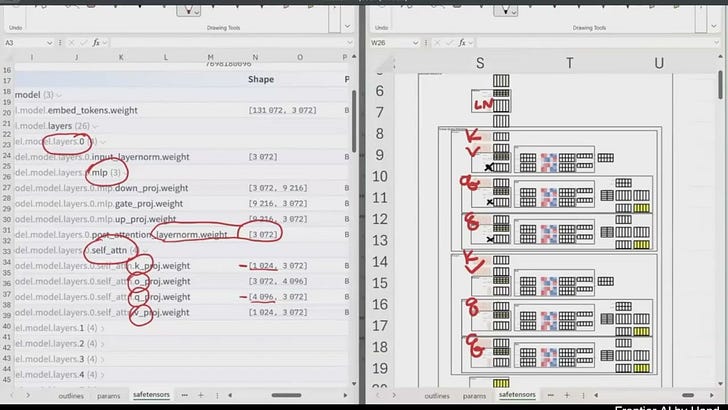
Frontier AI by hand ✍️
2025-12-11 · venturebeat.com
2025-12-05 · gemini.google.com
Meet Gemini, Google’s AI assistant. Get help with writing, planning, brainstorming, and more. Experience the power of generative AI.
2025-11-26 · statology.org

2025-11-23 · philschmid.de
A step-by-step practical guide on building AI agents using Gemini 3 Pro, covering tool integration, context management, and best practices for creating effective and reliable agents.
2025-11-22 · theverge.com

Amazon sued Perplexity this month over its Comet browser, which uses AI agents to do online shopping on your behalf. This is the first major front in the war over who gets to browse the web.
2025-11-10 · marktechpost.com
Learn how different memory systems affect multi-agent planning. Comparing Memory Systems for LLM Agents highlights key performance metrics.
Plain Vector RAG
sublinear scaling
2025-11-04 · marktechpost.com
Compare the top 7 large language models and systems for coding in 2025. Discover which ones excel for software engineering tasks.
OpenAI GPT-5 / GPT-5-Codex Anthropic Claude 3.5 Sonnet / Claude 4.x Sonnet with Claude Code Google Gemini 2.5 Pro Meta Llama 3.1 405B Instruct DeepSeek-V2.5-1210 (with DeepSeek-V3 as the successor) Alibaba Qwen2.5-Coder-32B-Instruct Mistral Codestral 25.01
Core coding quality: HumanEval, MBPP / MBPP EvalPlus, code generation and repair quality on standard Python tasks. Repo and bug-fix performance: SWE-bench Verified (real GitHub issues), Aider Polyglot (whole-file edits), RepoBench, LiveCodeBench. Context and long-context behavior: Documented…
2025-11-03 · quantamagazine.org
If language is what makes us human, what does it mean now that large language models have gained “metalinguistic” abilities?
2025-11-02 · blog.sshh.io
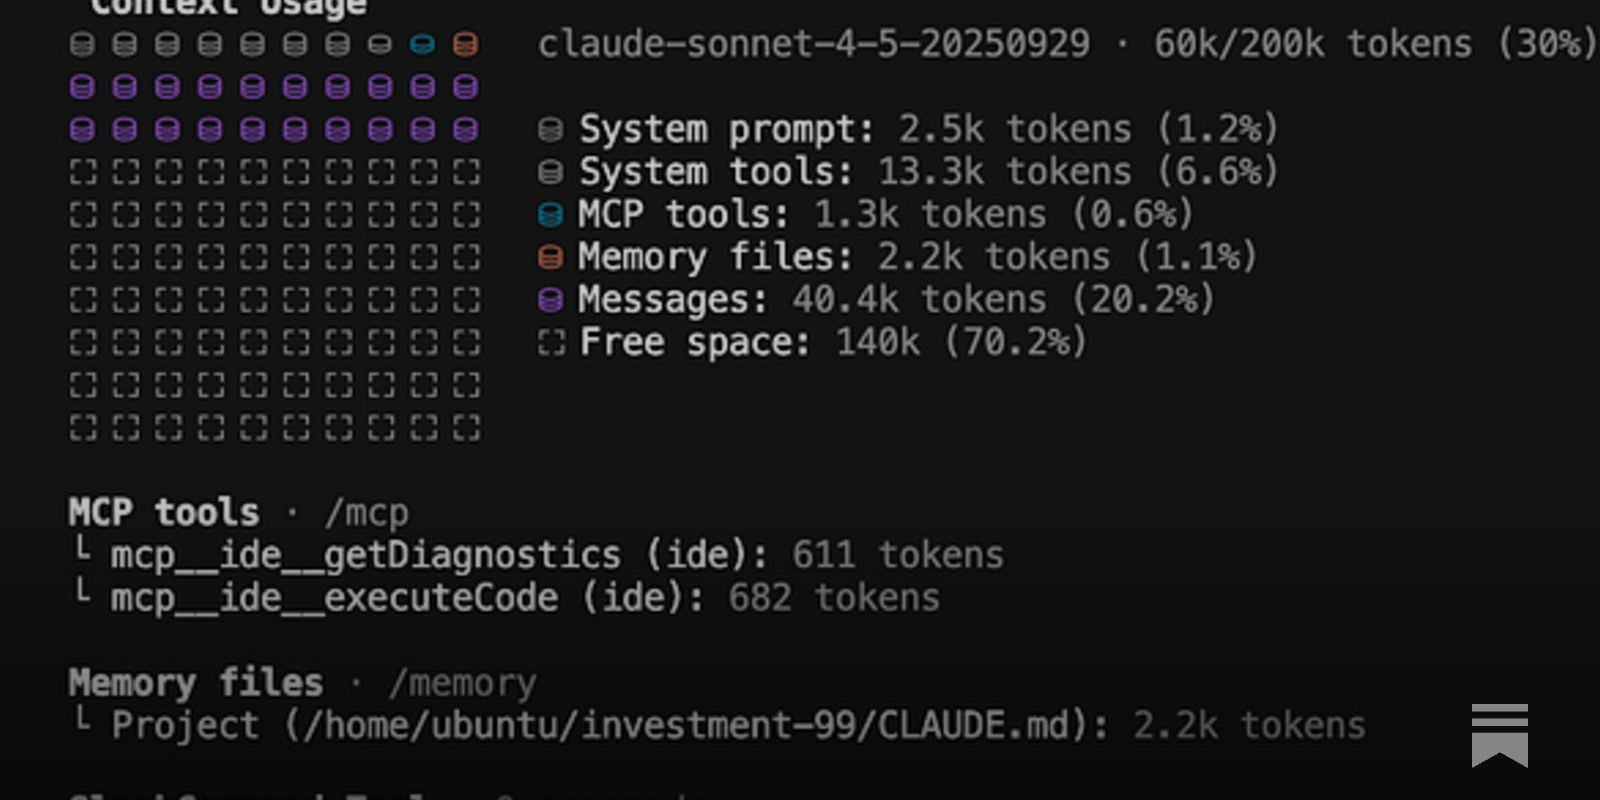
A brain dump of all the ways I've been using Claude Code.
2025-11-01 · chatgpt.com

A conversational AI system that listens, learns, and challenges
2025-10-28 · open.substack.com
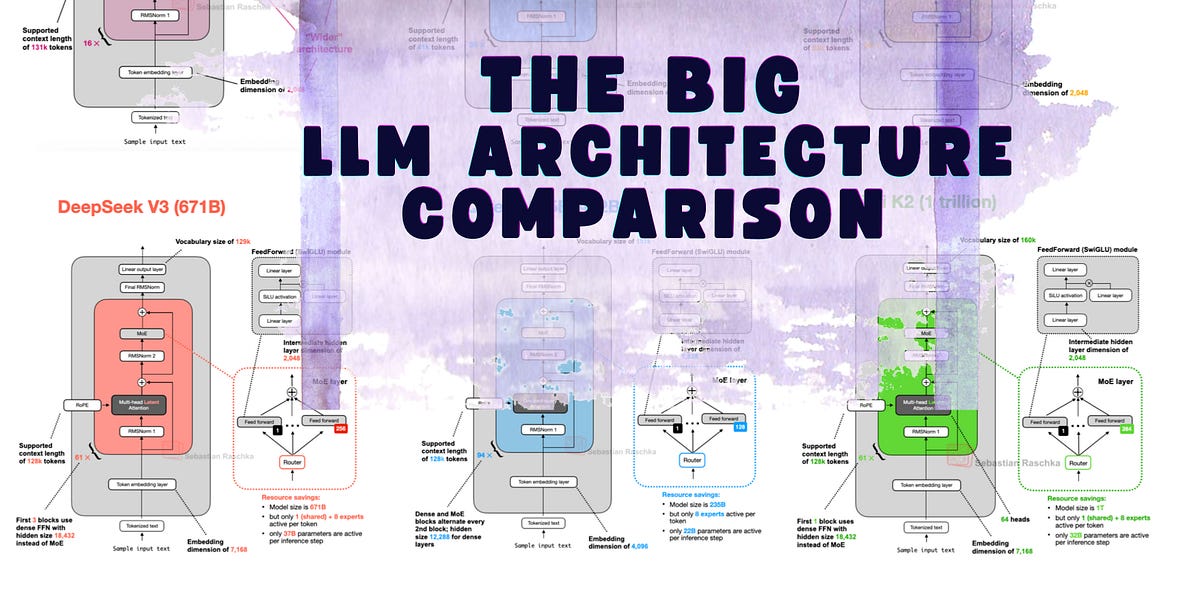
From DeepSeek-V3 to Kimi K2: A Look At Modern LLM Architecture Design
this section, I’ll focus on two key architectural techniques introduced in DeepSeek V3 that improved its computational efficiency and distinguish it from many other LLMs:
Multi-Head Latent Attention (MLA)
2025-10-27 · github.com

Codes/Notebooks for AI Projects. Contribute to Marktechpost/AI-Tutorial-Codes-Included development by creating an account on GitHub.
2025-10-26 · marktechpost.com
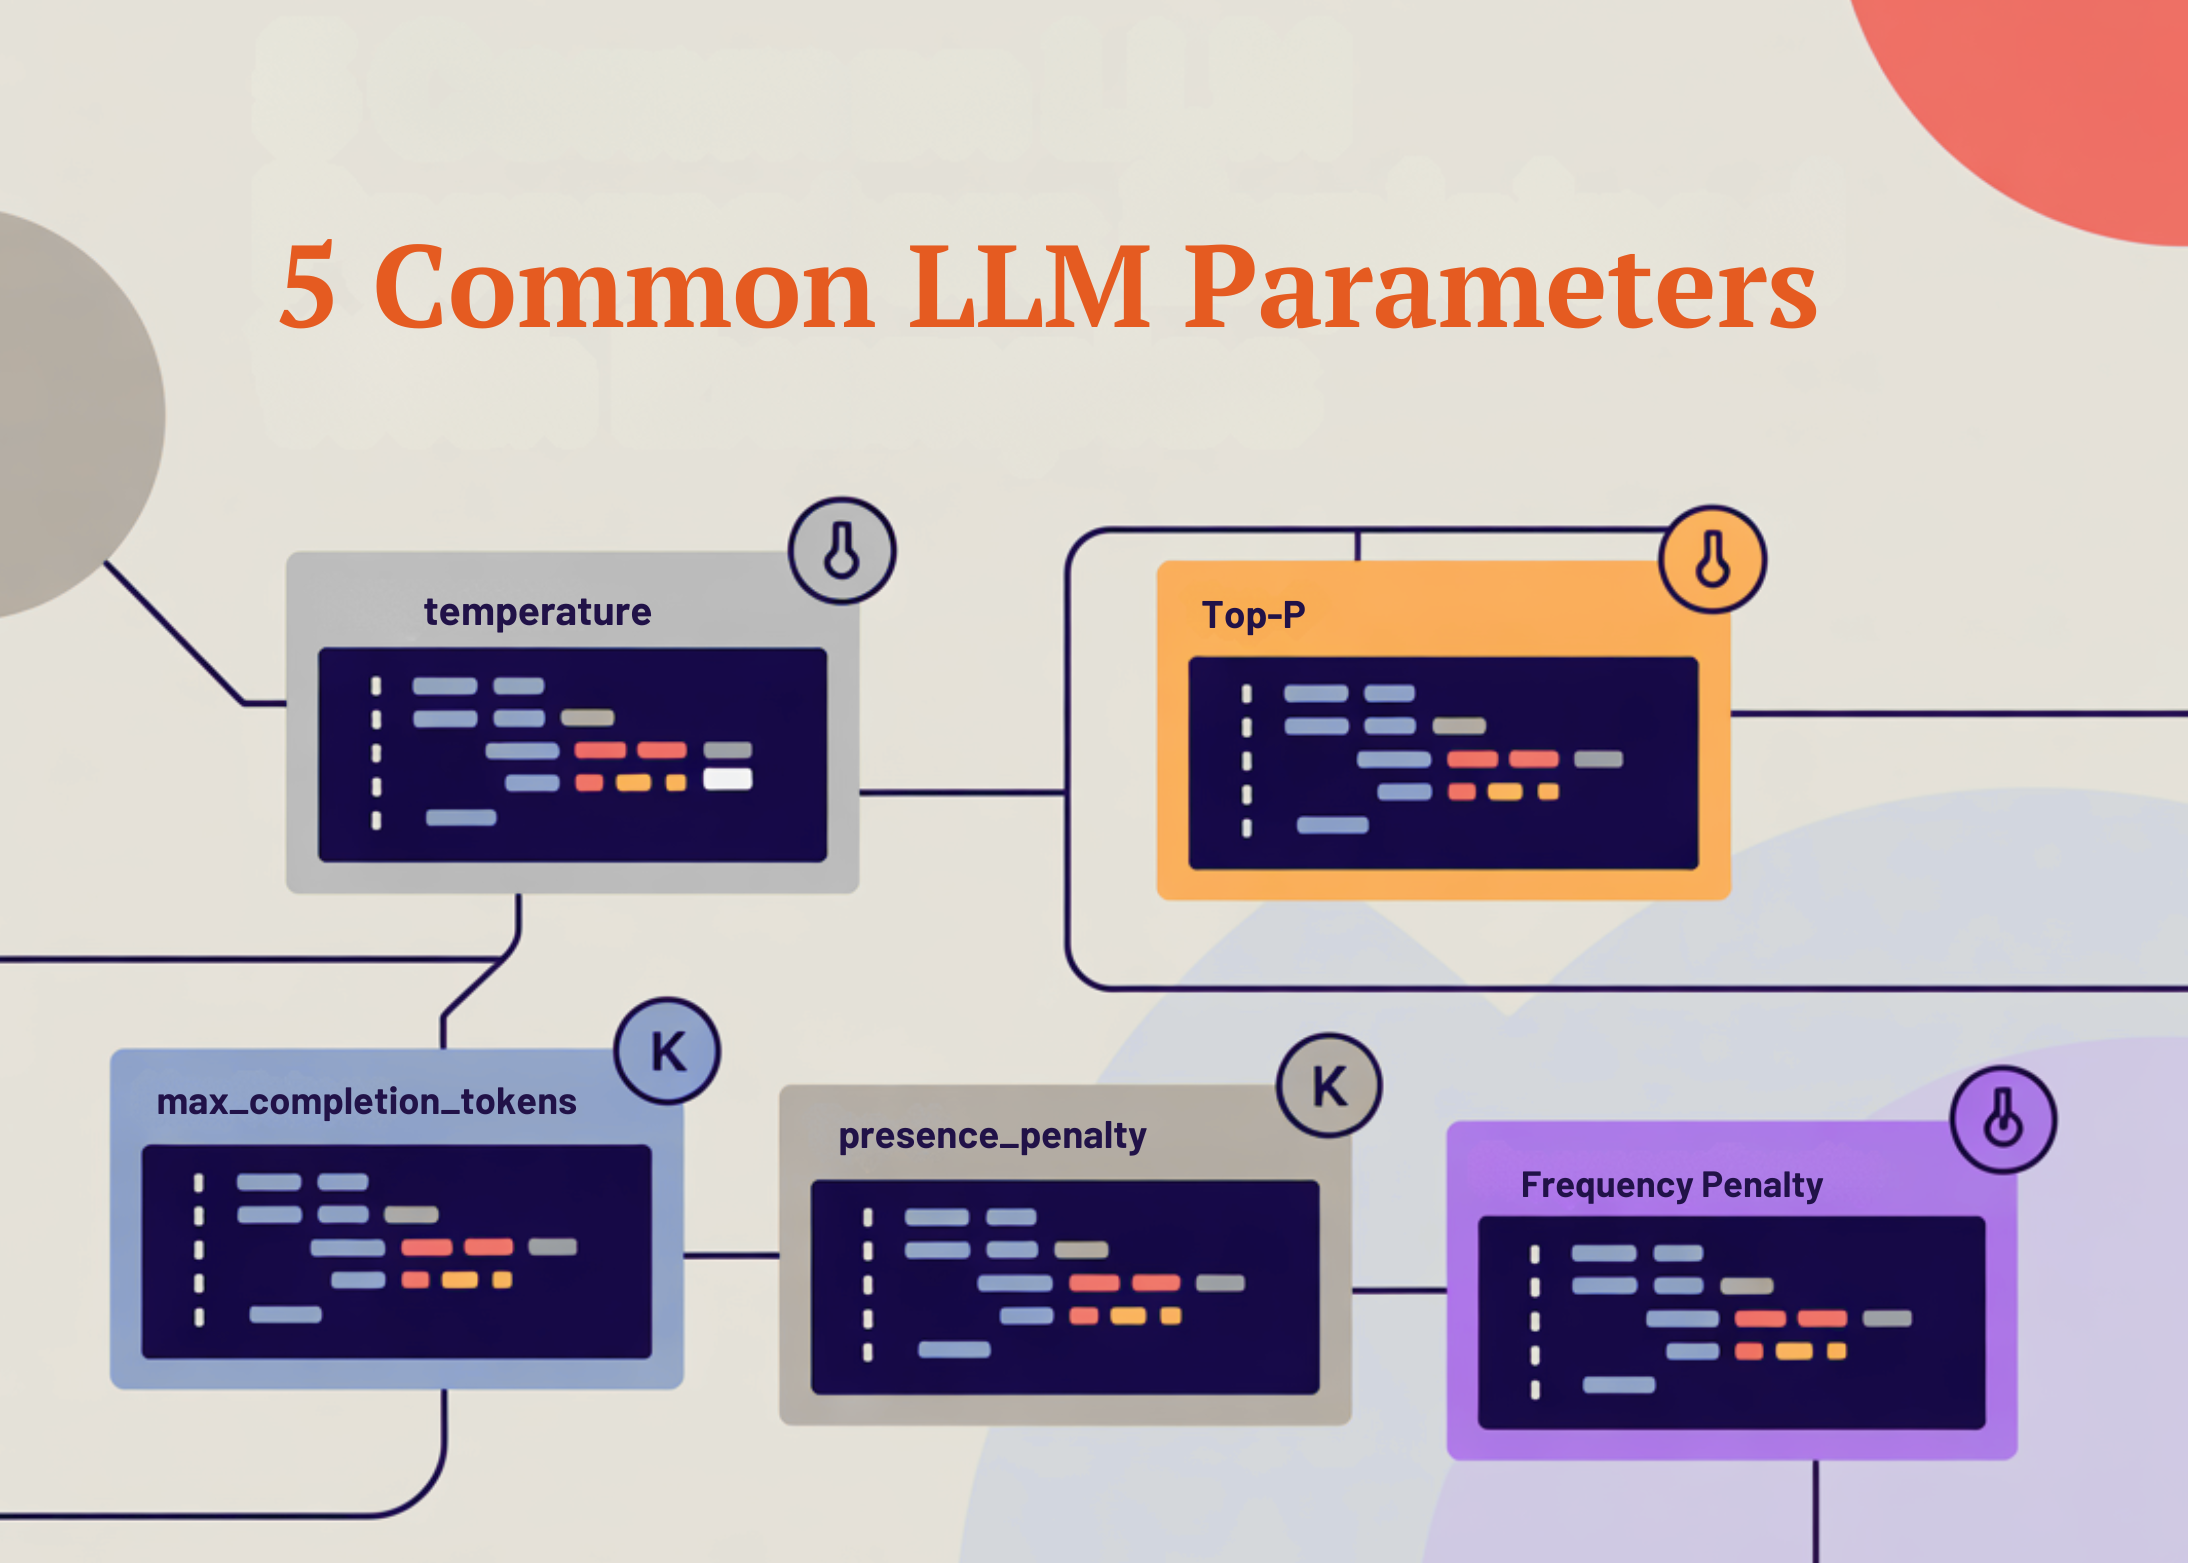
Learn the 5 common LLM parameters explained with examples to optimize your model's performance and generate desired results.
max_completion_tokens, temperature, top_p, presence_penalty, and frequency_penalty
Max Tokens is the maximum number of tokens the model can generate during a run
2025-10-22 · anildash.com
A blog about making culture. Since 1999.
2025-10-22 · simonwillison.net
I gave a talk last night at Claude Code Anonymous in San Francisco, the unofficial meetup for coding agent enthusiasts. I decided to talk about a dichotomy I’ve been struggling …
2025-10-19 · ollama.com
Ollama now supports Alibaba's Qwen3-VL.
2025-10-17 · venturebeat.com
Verbalized Sampling (VS)
Generate 5 responses with their corresponding probabilities, sampled from the full distribution
2025-10-14 · steipete.me
A practical guide to working with AI coding agents without the hype.
2025-10-14 · machinelearningmastery.com
Making developers awesome at machine learning.
2025-10-14 · amanxai.com
In this article, I'll take you through a step-by-step guide to fine-tuning LLMs with LoRA. A Guide to Fine-Tuning LLMs using LoRA.
2025-10-14 · marktechpost.com
Seven LLM generation parameters: max tokens, temperature, top-p, top-k, penalties, stop sequences, tuning guidance, defaults
stop sequences
presence penalties
2025-10-13 · stratechery.com

OpenAI is making a play to be the Windows of AI: the all-encompassing platform that controls both hardware supplier and software developers.
2025-10-06 · open.substack.com
Plus prompt injection attacks against Sora 2 cameos and notes on DSPy and Litestream 0.5.0
2025-10-05 · mng.bz
Understand LLM reasoning by creating your own reasoning model–from scratch! LLM reasoning models have the power to tackle truly challenging problems that require finding the right path through multiple steps. In Build A Reasoning Model (From Scratch) you’ll learn how to build a…
2025-10-05 · magazine.sebastianraschka.com
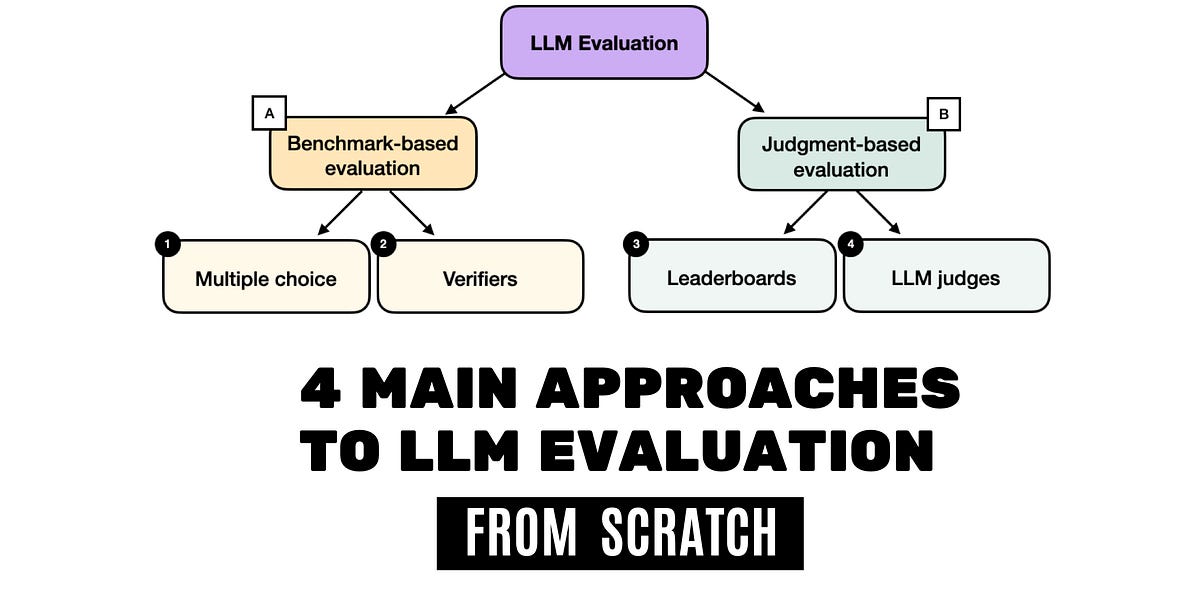
Multiple-Choice Benchmarks, Verifiers, Leaderboards, and LLM Judges with Code Examples
four common ways of evaluating trained LLMs in practice: multiple choice, verifiers, leaderboards, and LLM judges
training loss, perplexity, and rewards, but they are usually used internally during model development.)
2025-10-04 · marktechpost.com
A Coding Guide to Build an Autonomous Agentic AI for Time Series Forecasting with Darts and Hugging Face. A Step by step guide
2025-10-03 · thinkingmachines.ai

How LoRA matches full training performance more broadly than expected
2025-10-03 · nytimes.com

The new A.I. app generated videos of store robberies and home intrusions — even bomb explosions on city streets — that never happened.
2025-10-02 · si.inc
How we spent under half a million dollars to build a 30 petabyte data storage cluster in downtown San Francisco
2025-09-28 · marktechpost.com
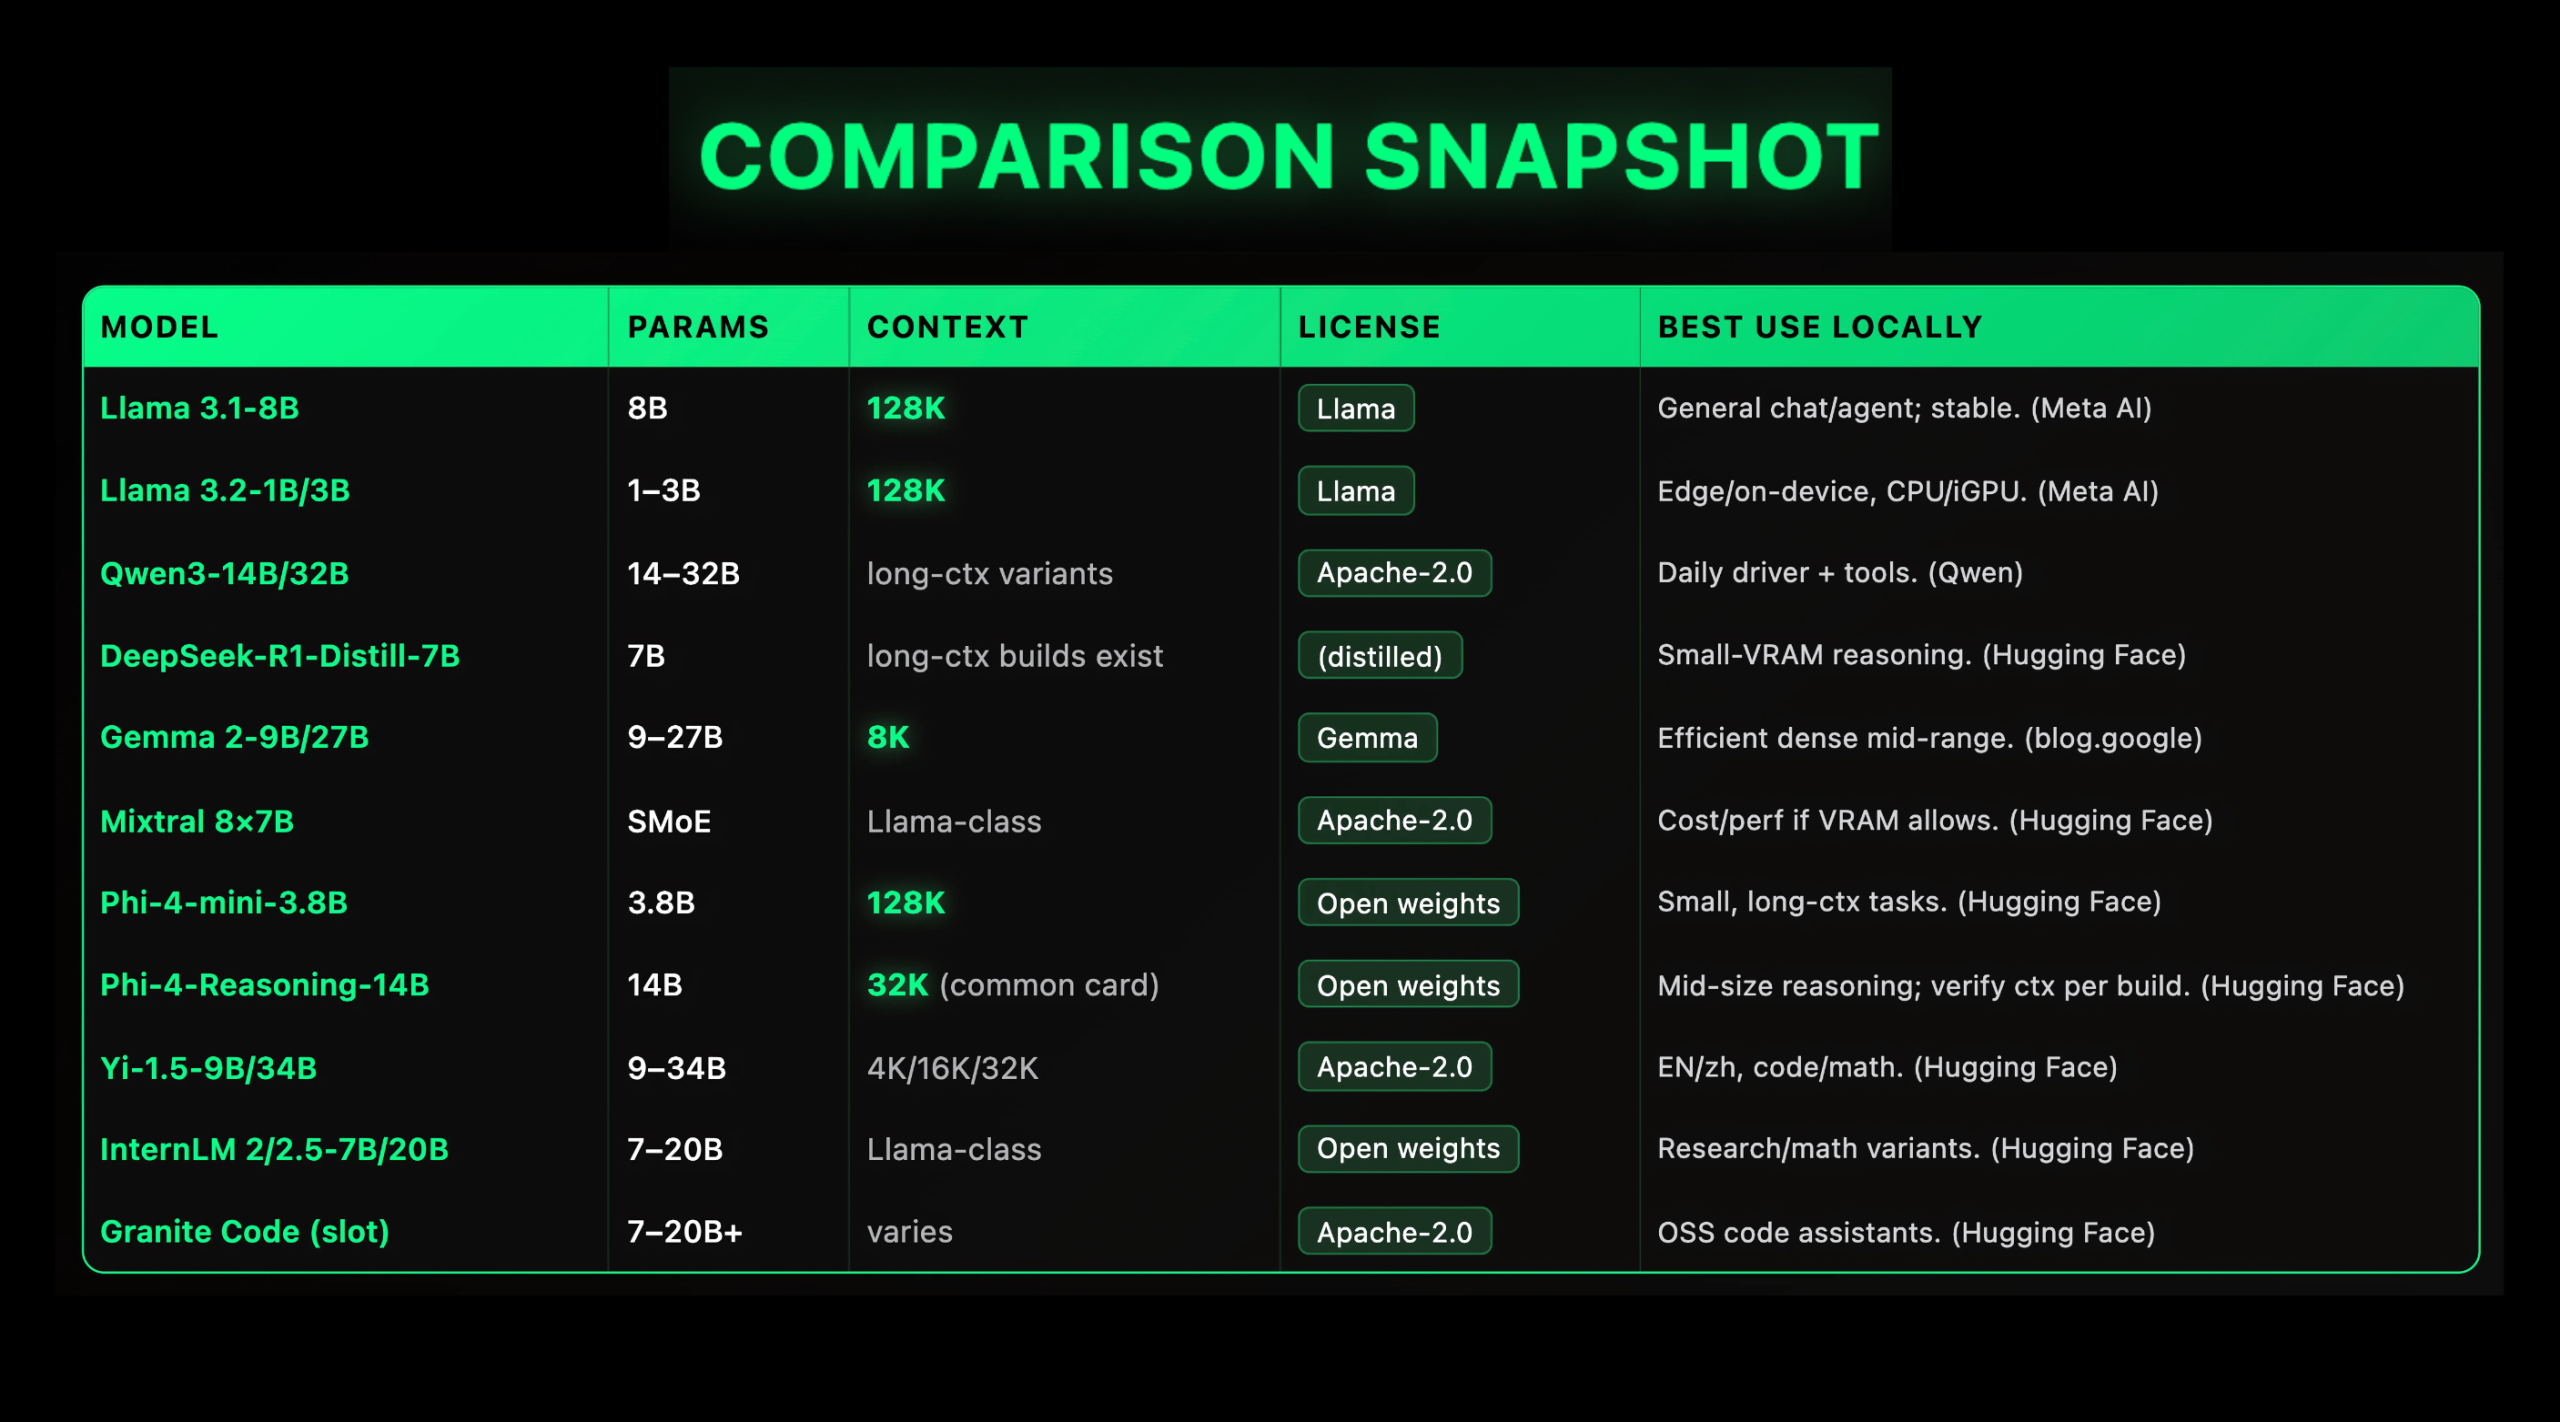
Compare top local LLMs for 2025: context windows, VRAM tiers, licenses, quantization, runtimes, dense vs MoE tradeoffs clearly
2025-09-24 · kdnuggets.com
In this article, we discuss five cutting-edge NLP trends that will shape 2026.
transformers’ biggest weakness remains the high compute time and memory consumption of self-attention
Approaches like linear attention and sparse attention
2025-09-24 · simonwillison.net
OpenAI half-relased this model earlier this month, adding it to their Codex CLI tool but not their API. Today they've fixed that - the new model can now be accessed …