Top 38 Python Libraries for Data Science, Data Visualization & Machine Lear
This article compiles the 38 top Python libraries for data science, data visualization & machine learning, as best determined by KDnuggets staff.
This article compiles the 38 top Python libraries for data science, data visualization & machine learning, as best determined by KDnuggets staff.
Hands-on tutorial to effectively use different Regression Algorithms
Compendium of free ML reading resources.

Multiplying matrices is among the most fundamental and compute-intensive operations in machine learning. Consequently, there has been significant work on efficiently approximating matrix...
Using “Kneedle” algorithmus detecting knees with Python package “kneed”
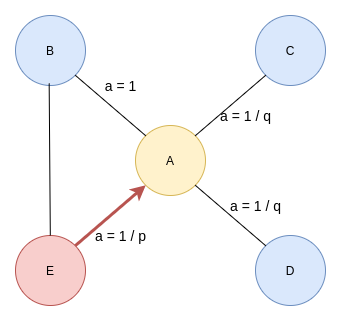
An in-depth guide to understanding node2vec algorithm and its hyper-parameters

The story of a decade-plus long journey toward a unified forecasting model.
A one-stop-shop for all your tokenization needs
OpenCV is not the only one
This is part 3 of a series on bot programming originally published on the Coder One blog. Part 1:...
Why conformal prediction for uncertainty estimation can improve your predictions
Essential guide to various dimensionality reduction techniques in Python
Intel(R) Extension for Scikit-learn is a seamless way to speed up your Scikit-learn application.
Papers With Code highlights trending Machine Learning research and the code to implement it.
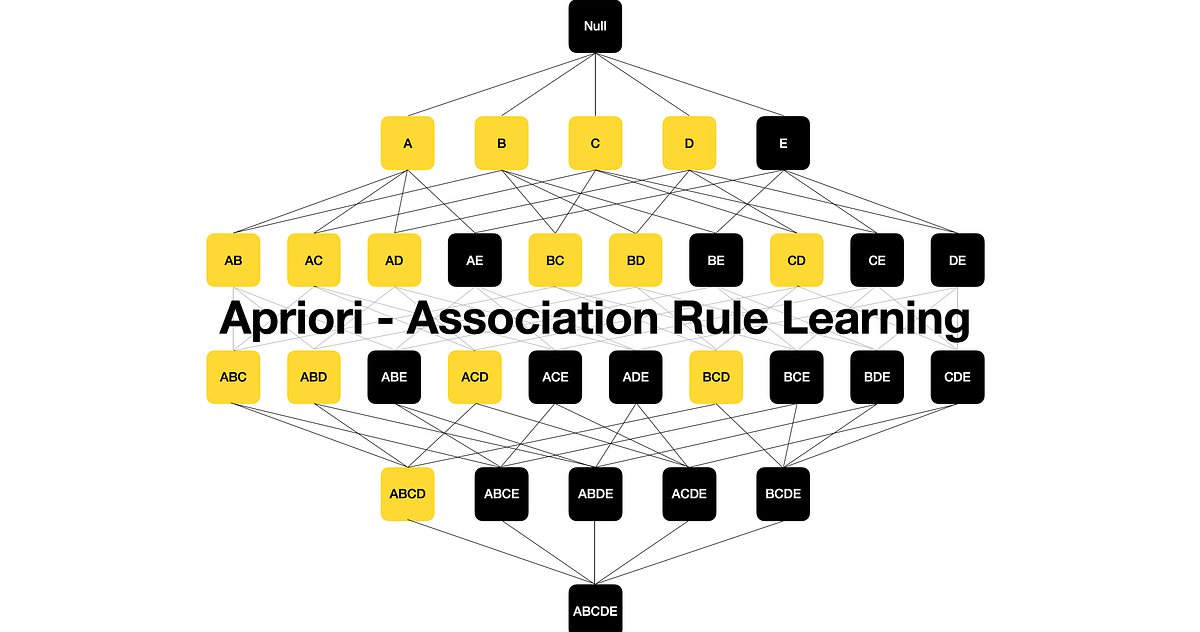
Explanation and examples of frequent itemset mining and association rule learning over relational databases in Python
Different Kinds of Correlation Coefficients in a Deeper Look
What companies can learn from employee turnover data
With Streamlit creating a deploying a web app can be very easy!
Similarity search is one of the fastest-growing domains in AI and machine learning. At its core, it is the process of matching relevant pieces of information together.
In this article, I’ll show you five ways to load data in Python. Achieving a speedup of 3 orders of magnitude.

2284 methods • 143838 papers with code.
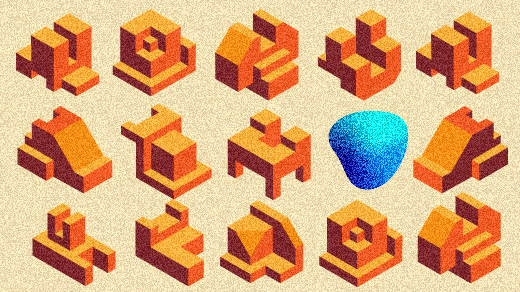
For all their triumphs, AI systems can’t seem to generalize the concepts of “same” and “different.” Without that, researchers worry, the quest to create truly intelligent machines may be hopeless.
Combining tree-boosting with Gaussian process and mixed effects models - fabsig/GPBoost
In August, I set out to improve the machine learning ecosystem for Ruby and wasn’t sure where it would go. Over the next 5 months, I ended up...
This is a draft of a book for learning data analysis with the R language. This book emphasizes hands activities. Comments and suggestions are welcome.
Data Augmentation is one of the most important topics in Deep Computer Vision. When you train your neural network, you should do data augmentation like… ALWAYS. Otherwise, you are not using your…
Sentiment Analysis, or Opinion Mining, is a subfield of NLP (Natural Language Processing) that aims to extract attitudes, appraisals, opinions, and emotions from text. Inspired by the rapid migration…
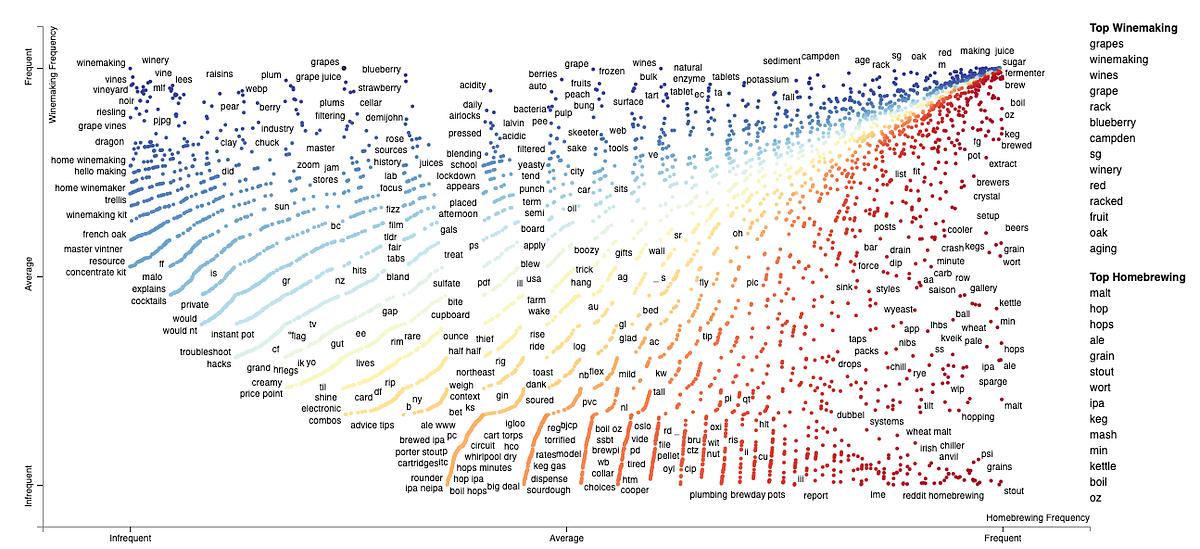
Scroll down to see how to interpret a plot created by a great tool for comparing two classes and their corpora.
In marketing analytics, conjoint analysis is a technique used to gain specific insights about consumers’ preferences. Often derived from consumer surveys, conjoint analysis can tell us, for instance…
Evaluating object detection models is not straightforward because each image can have many objects and each object can belong to different classes. This means that we need to measure if the model…
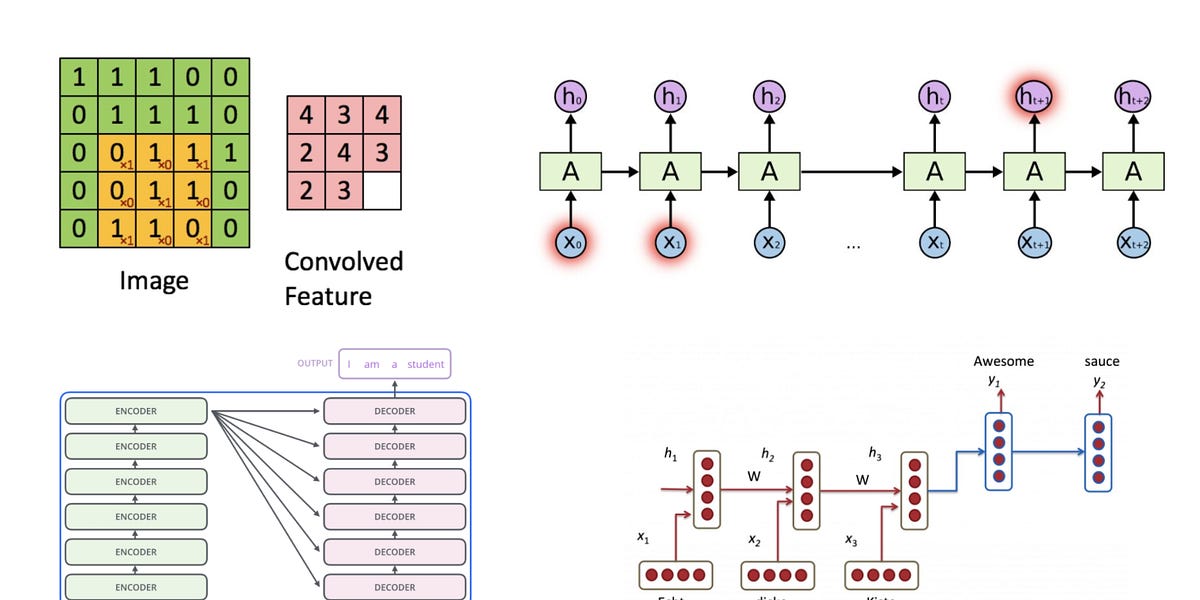
A collection of high-impact machine learning blog posts.
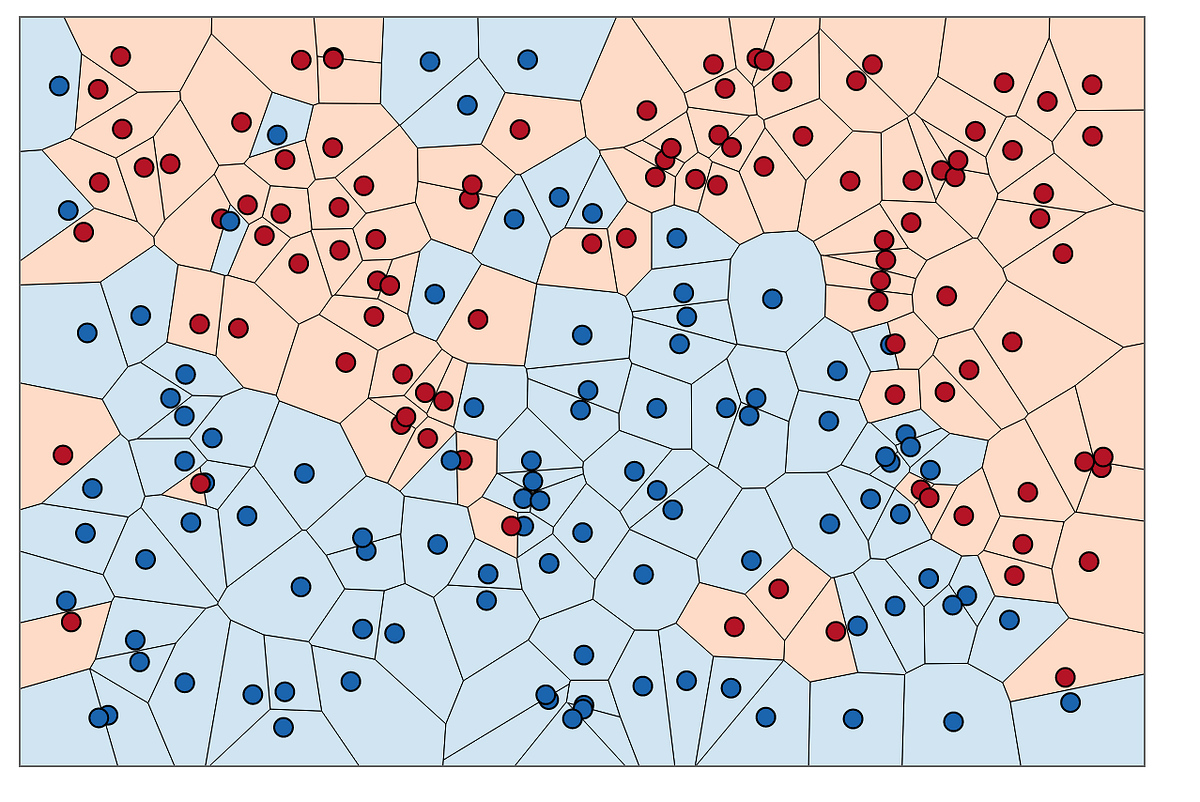
We are excited to announce that this year’s NeurIPS 2021 Conference will host a first-of-its-kind competition in large scale approximate…
Creating Spotify recommendations with data science
Experimentation is widely used at tech startups to make decisions on whether to roll out new product features, UI design changes, marketing campaigns and more, usually with the goal of improving…
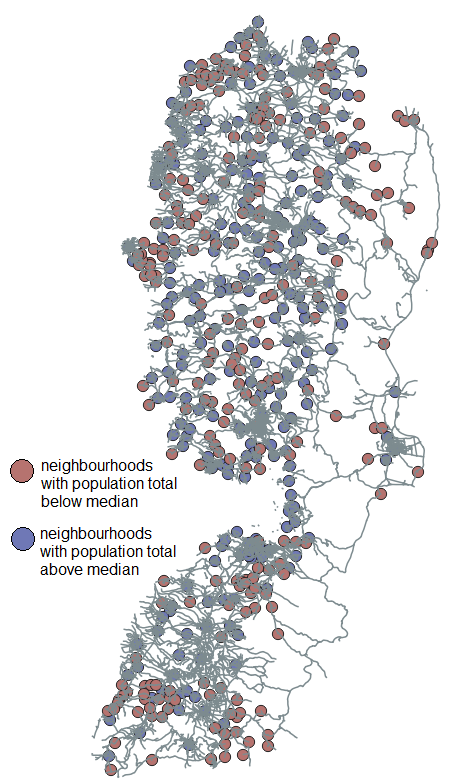
Combining data science and econometrics for an introduction to the DeepIV framework, including a full Python code tutorial.
Word on the street is that PyTorch lightning is a much better version of normal PyTorch. But what could it possibly have that it brought such consensus in our world? Well, it helps researchers scale…
In this story, we are going to discuss an application of dynamic programming techniques to an optimization algorithm. Through the process of developing an optimal solution, we get to study a variety…
Building the raw materials for personalization at scale
Essential extensions that will boost your productivity in Jupyter Notebook.
Find out about all of the projects of Meta Open Source.
Machine-learning algorithms can quickly process thousands of hours of natural soundscapes

Modern AI systems approach tasks like recognising objects in images and predicting the 3D structure of proteins as a diligent student would prepare for an exam. By training on many example...
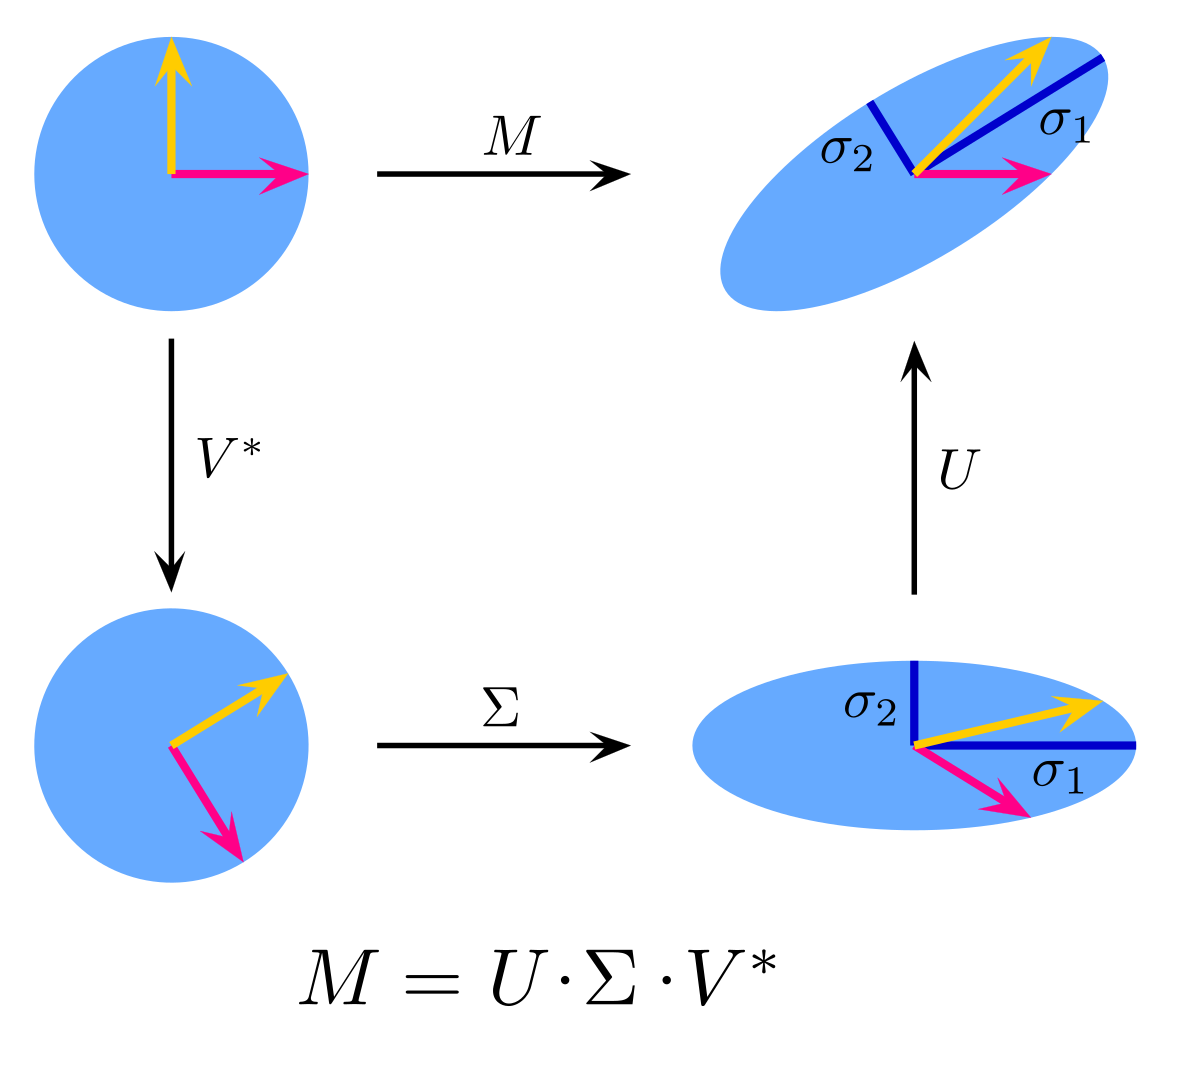
In linear algebra, the singular value decomposition (SVD) is a factorization of a real or complex matrix into a rotation, followed by a rescaling followed by another rotation. It generalizes the eigendecomposition of a square normal matrix with an orthonormal eigenbasis to any…