LLM Research Papers: The 2024 List

A curated list of interesting LLM-related research papers from 2024, shared for those looking for something to read over the holidays.
A curated list of interesting LLM-related research papers from 2024, shared for those looking for something to read over the holidays.
Compute costs scale with the square of the input size. That’s not great.
This is probably why Google charges twice as much, per token, for Gemini 1.5 Pro once the context gets longer than 128,000 tokens. Generating token number 128,001 requires comparisons with all 128,000 previous tokens, making it significantly more expensive than producing the first or 10th or 100th…
In a series of papers, Princeton computer scientist Tri Dao and several collaborators have developed FlashAttention, which calculates attention in a way that minimizes the number of these slow memory operations.
Implement a ChatGPT-like LLM in PyTorch from scratch, step by step - rasbt/LLMs-from-scratch

Large Language Models (LLMs) have become a cornerstone of artificial intelligence, driving advancements in natural language processing and decision-making tasks. However, their extensive power demands, resulting from high computational overhead and frequent external memory…

The artificial intelligence start-up said the new system, OpenAI o3, outperformed leading A.I. technologies on tests that rate skills in math, science, coding and logic.
A post for developers with advice and workflows for building effective AI agents

Large Language Models (LLMs) have achieved remarkable advancements in natural language processing (NLP), enabling applications in text generation, summarization, and question-answering. However, their reliance on token-level processing—predicting one word at a time—presents…
However, their reliance on token-level processing—predicting one word at a time—presents challenges
LCMs perform computations in a high-dimensional embedding space. This space represents abstract units of meaning, referred to as concepts, wh
Tables, Images, figures or handwriting are not problem anymore ! Full Code provided.

Large language models (LLMs) can understand and generate human-like text by encoding vast knowledge repositories within their parameters. This capacity enables them to perform complex reasoning tasks, adapt to various applications, and interact effectively with humans. However…

This blog explores a detailed comparison between the OpenAI API and LangChain, highlighting key differences in performance and developer experience and the low level code for why these differences exist.

A.I. insiders are falling for Claude, a chatbot from Anthropic. Is it a passing fad, or a preview of artificial relationships to come?
Speed up your LLM inference

There has been an increasing amount of fear, uncertainty and doubt (FUD) regarding AI Scaling laws. A cavalcade of part-time AI industry prognosticators have latched on to any bearish narrative the…
Other areas that deliver model improvements with more compute include Synthetic Data Generation, Proximal Policy Optimization (PPO), Functional Verifiers, and other training infrastructure for reasoning
we will outline the old pre-training scaling trend as well as the new scaling trends for post-training and inference time.
It’s largely up to companies to test whether their AI is capable of superhuman harm. At Anthropic, the Frontier Red Team assesses the risk of catastrophe.

In large language models (LLMs), “hallucination” refers to instances where models generate semantically or syntactically plausible outputs but are factually incorrect or nonsensical. For example, a hallucination occurs when a model provides erroneous information, such as stating…

Compare AI models easily! All providers in one place.

LLMs are driving major advances in research and development today. A significant shift has been observed in research objectives and methodologies toward an LLM-centric approach. However, they are associated with high expenses, making LLMs for large-scale utilization inaccessible…
KV cache is used for autoregressive decoding in LLMs. It stores key-value pairs in multi-headed attention during the pre-filling phase of inference.
PCIe interfaces become a limiting factor, especially when transferring the cache from the CPU to the GPU for computation.
A Step-by-Step Guide
Navigate Tomorrow's Intelligence Today
Kapa.ai turns your knowledge base into a reliable and production-ready LLM-powered AI assistant that answers technical questions instantly. Trusted by 100+ startups and enterprises incl. OpenAI, Docker, Mapbox, Mixpanel and NextJS.
Psst, kid, want some cheap and small LLMs?

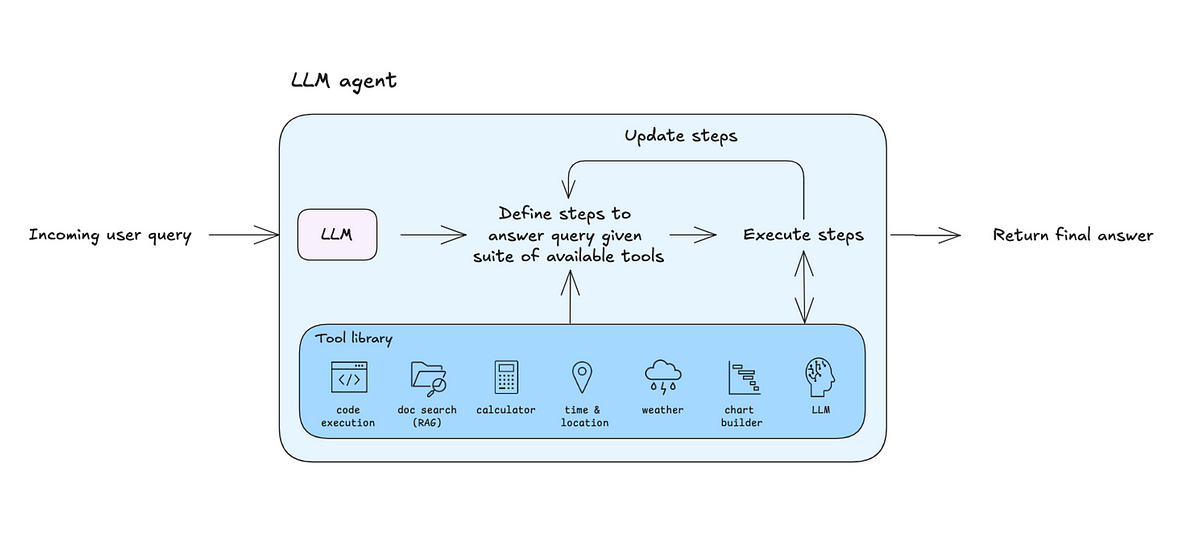
The advent of LLMs has propelled advancements in AI for decades. One such advanced application of LLMs is Agents, which replicate human reasoning remarkably. An agent is a system that can perform complicated tasks by following a reasoning process similar to humans: think…
Notes from the Latent Space paper club. Follow along or start your own! - eugeneyan/llm-paper-notes
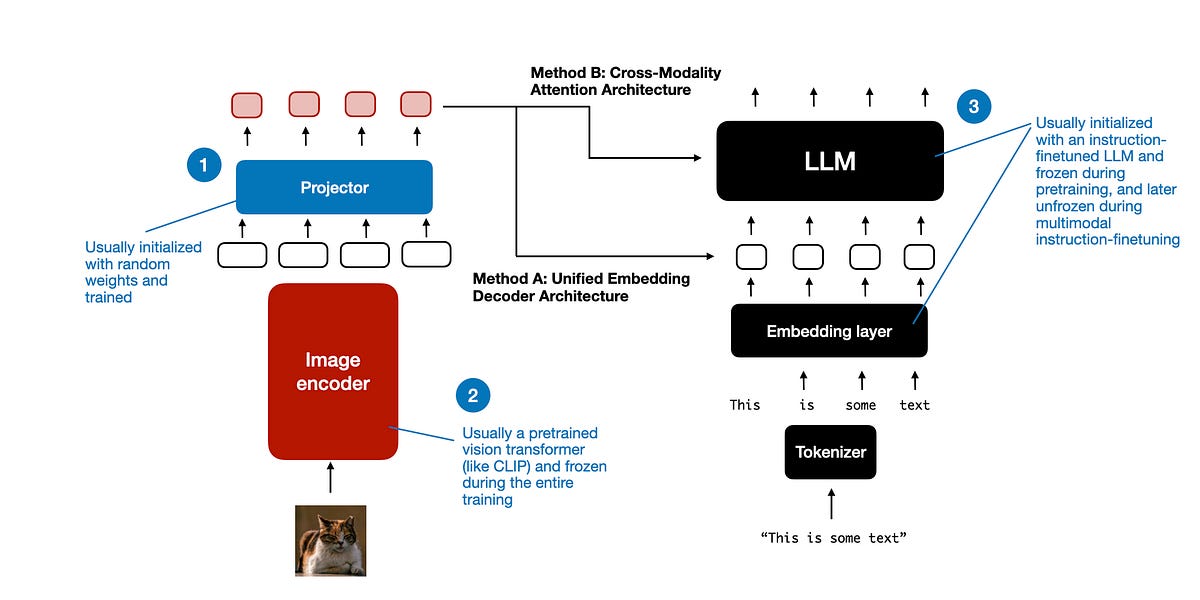
An introduction to the main techniques and latest models
Are they good or bad?
9 October 2024, Mathias Parisot, Jakub Zavrel.Even in the red hot global race for AI dominance, you publish and you perish, unless your peers pick up your work, build further on it, and you manage to drive real progress in the field. And of course, we are all very curious who is…

Natural Language Processing (NLP) has rapidly evolved in the last few years, with transformers emerging as a game-changing innovation. Yet, there are still notable challenges when using NLP tools to develop applications for tasks like semantic search, question answering, or…

The power of a robust honor code—and abundant institutional resources
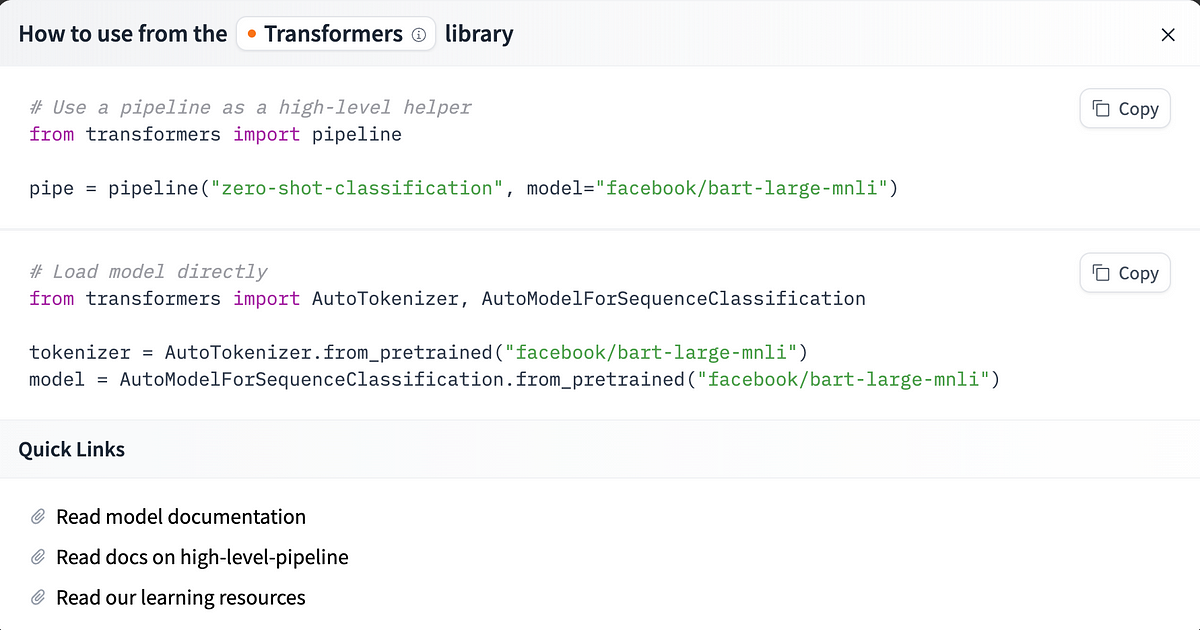
Pulling pre-trained models out of the box for your use case
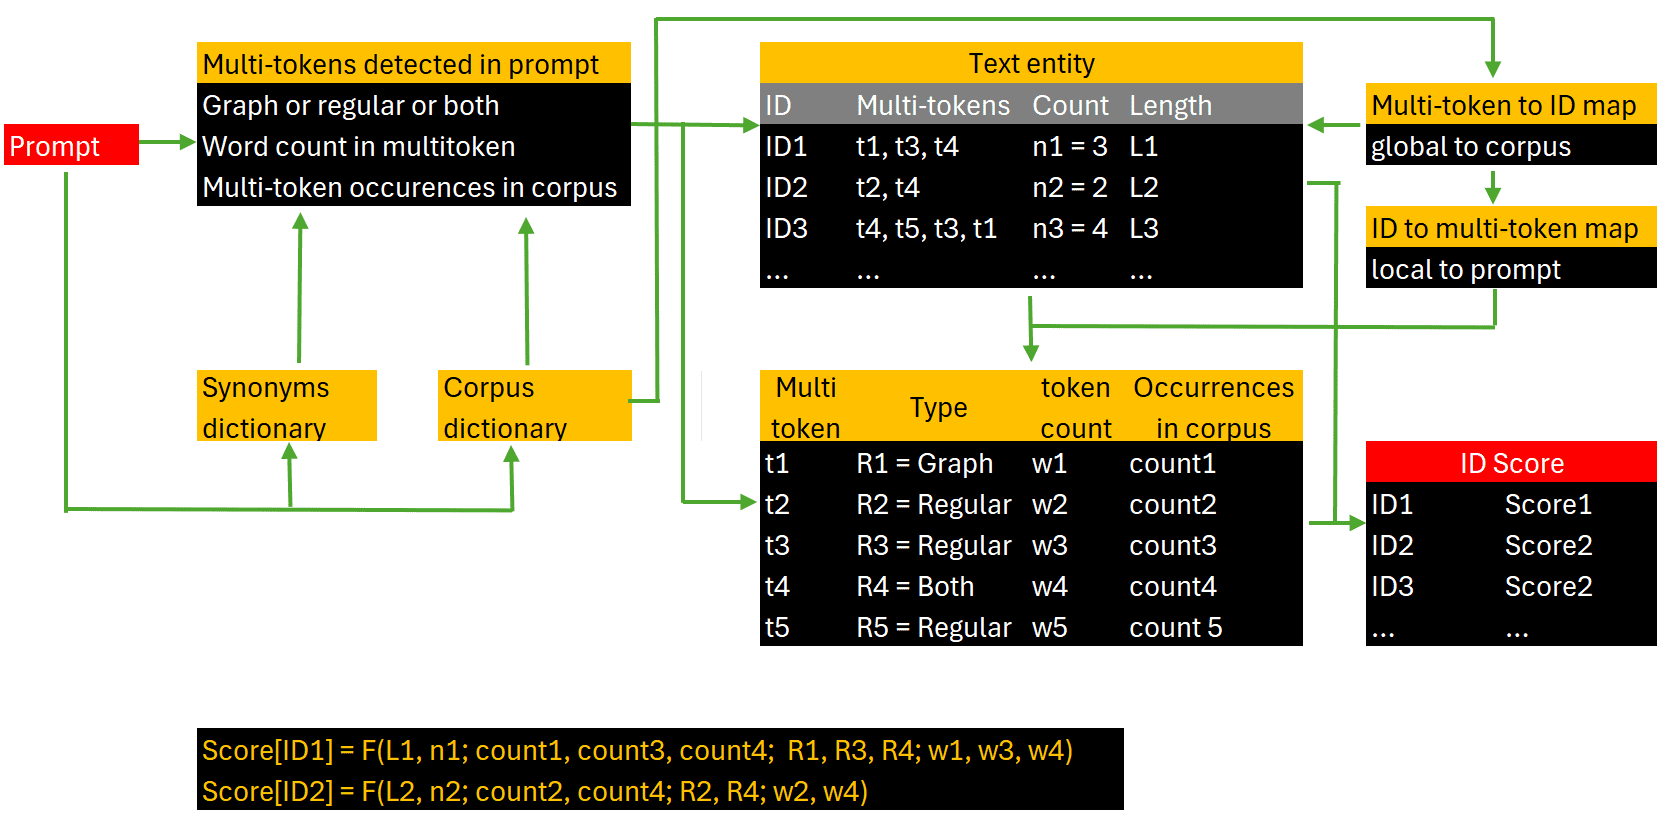
LLM Chunking, Indexing, Scoring and Agents, in a Nutshell. The new PageRank of RAG/LLM. With details on building relevancy scores.

The popular online chatbot can now access and deliver information from across the internet in real time, including news, stock prices and sports scores.
A discussion of how Anthropic's researchers developed Claude's new computer use skill, along with some relevant safety considerations

In this article, I share the five essential LLM tools that I currently find indispensable, and which have the potential to help revolutionize the way you work.

Anthropic, the AI vendor second in size only to OpenAI, has a powerful family of generative AI models called Claude. These models can perform a range of

Nvidia quietly launched a groundbreaking AI model that surpasses OpenAI’s GPT-4 and Anthropic’s Claude 3.5, signaling a major shift in the competitive landscape of artificial intelligence.
Implementing a ChatGPT-like LLM in PyTorch from scratch, step by step - rasbt/LLMs-from-scratch


Meta's recent release of Llama 3.1 has stirred excitement in the AI community, offering an array of remarkable applications. This groundbreaking model, particularly the 405B variant, stands out for its superior performance and open-source accessibility, outpacing even top-tier…
Understanding the mechanistic interpretability research problem and reverse-engineering these large language models
Discover and create custom versions of ChatGPT that combine instructions, extra knowledge, and any combination of skills.
Llama 3.1 is the latest version of Meta's large language models, with a new model weight, 405 billion parameters, the biggest model it's trained.
The newly unveiled Llama 3.1 collection of 8B, 70B, and 405B large language models (LLMs) is narrowing the gap between proprietary and open-source models. Their open nature is attracting more…

Meta announced the release of Llama 3.1, the most capable model in the LLama Series. This latest iteration of the Llama series, particularly the 405B model, represents a substantial advancement in open-source AI capabilities, positioning Meta at the forefront of AI innovation…
Meta llama 3.1 405b kicks off a fresh chapter for open-source language models. This breakthrough brings unmatched skills to AI
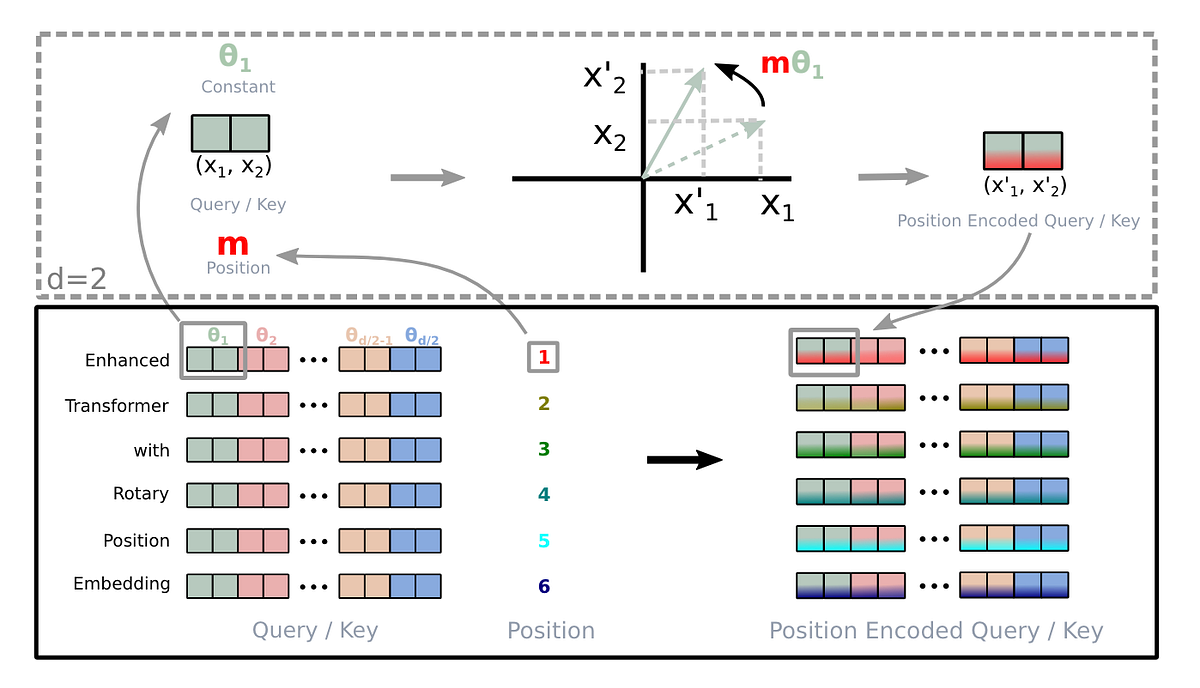
A deep dive into absolute, relative, and rotary positional embeddings with code examples
Introducing Claude 3.5 Sonnet—our most intelligent model yet. Sonnet now outperforms competitor models and Claude 3 Opus on key evaluations, at twice the speed.

ChatGPT maker OpenAI is working on a novel approach to its artificial intelligence models in a project code-named “Strawberry,” according to a person familiar with the matter and internal documentation reviewed by Reuters.
Attention, as a core layer of the ubiquitous Transformer architecture, is a bottleneck for large language models and long-context applications. FlashAttention (and FlashAttention-2) pioneered an approach to speed up attention on GPUs by minimizing memory reads/writes, and is now…
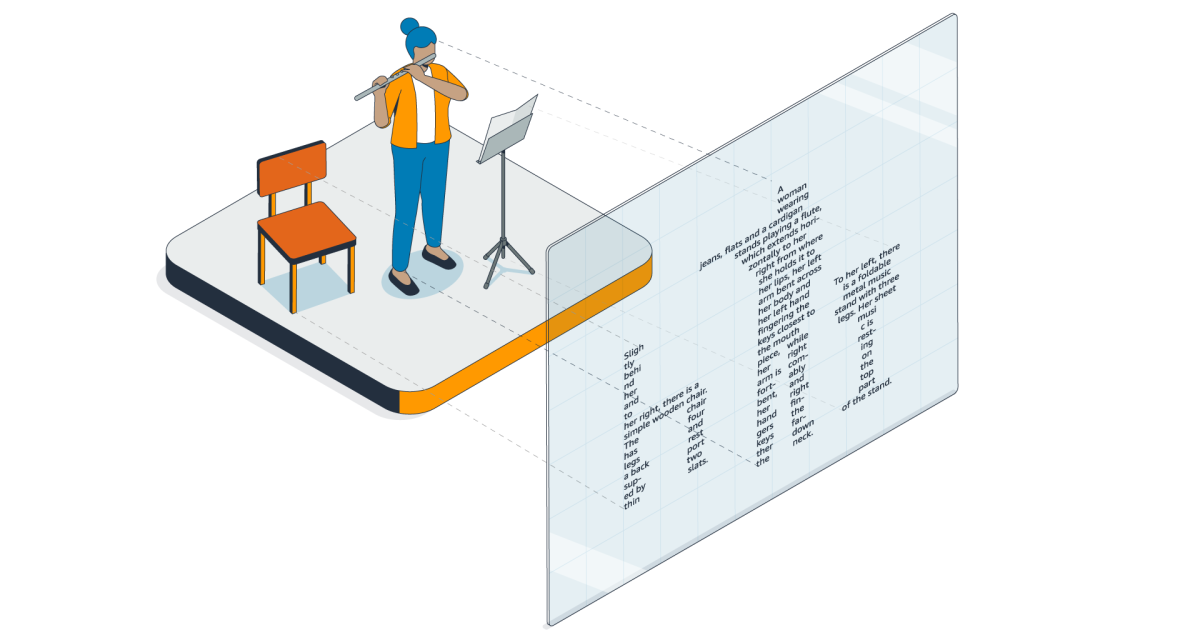
In addition to its practical implications, recent work on “meaning representations” could shed light on some old philosophical questions.
Introduction In this post, I want to introduce Mark, a simple CLI tool that uses Markdown and its syntax to interact naturally with the GPT4-vision/GPT4o models.