llama
271 bookmarks · page 5 of 6
2023-10-20 · lightning.ai
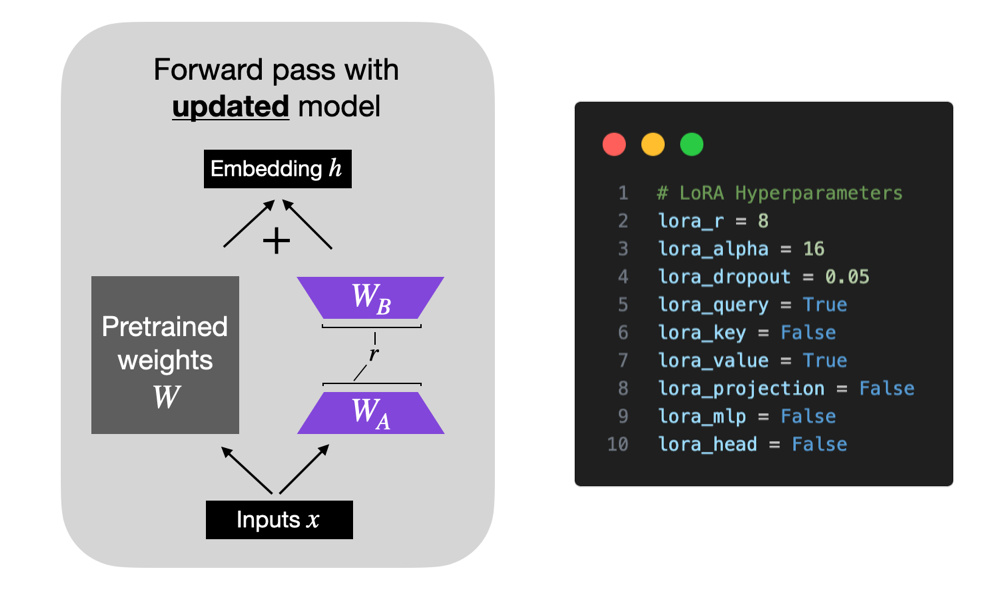
LoRA is one of the most widely used, parameter-efficient finetuning techniques for training custom LLMs. From saving memory with QLoRA to selecting the optimal LoRA settings, this article provides practical insights for those interested in applying it.
2023-10-20 · flyte.org
As a machine learning engineer who has witnessed the rise of Large Language Models (LLMs), I find it daunting to comprehend how the ecosystem surrounding LLMs is developing.
2023-10-20 · anyscale.com
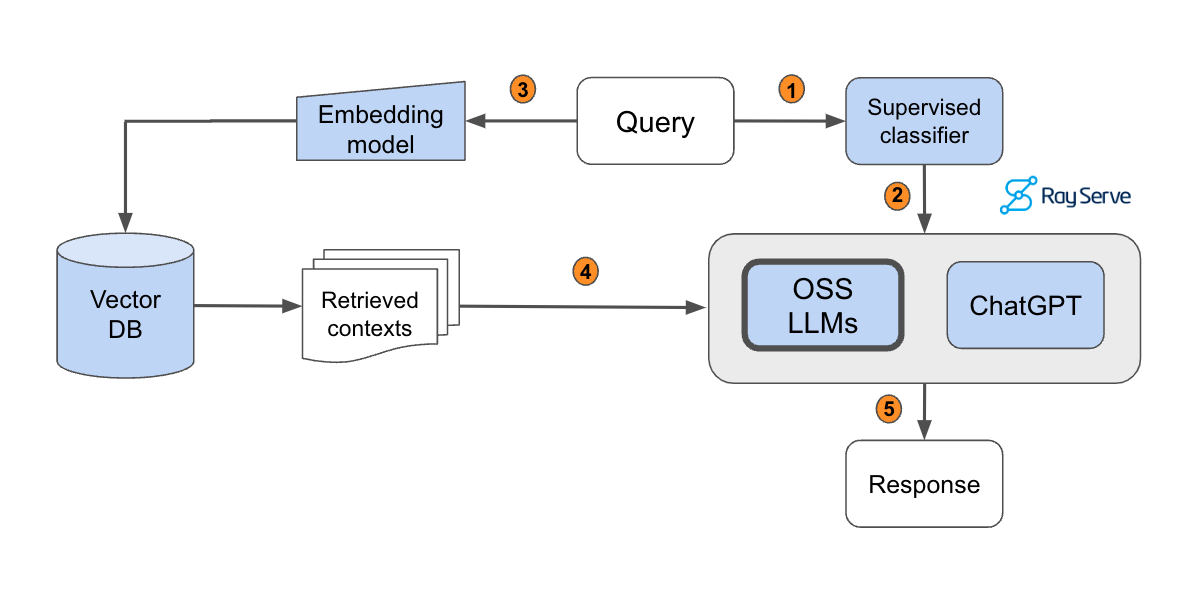
In this guide, we will learn how to develop and productionize a retrieval augmented generation (RAG) based LLM application, with a focus on scale and evaluation.
2023-10-17 · 12mv2.com

Hey everyone! I’ve mostly started sharing my favorite memos and transcripts over at A Letter a Day, but as it’s more of a tasting menu, I’m reticent to post multiple memos or tran…
2023-10-07 · hpcwire.com
When discussing GenAI, the term "GPU" almost always enters the conversation and the topic often moves toward performance and access. Interestingly, the word "GPU" is assumed to mean "Nvidia" products. (As an aside, the popular Nvidia hardware used in GenAI are not technically...
2023-09-25 · towardsdatascience.com
Data Curation, Transformers, Training at Scale, and Model Evaluation
2023-09-25 · blog.briankitano.com
I want to provide some tips from my experience implementing a paper. I'm going to cover my tips so far from implementing a dramatically scaled-down versio...
2023-09-24 · aman.ai
Aman's AI Journal | Course notes and learning material for Artificial Intelligence and Deep Learning Stanford classes.
2023-08-30 · towardsdatascience.com
How to fine-tune Llama and other LLMs with one tool
2023-08-27 · marktechpost.com

A multifaceted challenge has arisen in the expansive realm of natural language processing: the ability to adeptly comprehend and respond to intricate and lengthy instructions. As communication nuances become more complicated, the shortcomings of prevailing models in dealing with…
2023-08-07 · marktechpost.com

Recent language models can take long contexts as input; more is needed to know about how well they use longer contexts. Can LLMs be extended to longer contexts? This is an unanswered question. Researchers at Abacus AI conducted multiple experiments involving different schemes…
2023-08-06 · nanonets.com
Using ChatGPT & OpenAI's GPT API, this code tutorial teaches how to chat with PDFs, automate PDF tasks, and build PDF chatbots.
2023-08-06 · turingpost.com

Practical Advice from Experts: Fine-Tuning, Deployment, and Best Practices
2023-08-01 · newyorker.com
My town, once celebrated for its laid-back weirdness, is now a turbocharged tech megalopolis being shaped by exiles from places like Silicon Valley.
2023-07-28 · dataconomy.com
Navigating the maze of pricing plans for digital services can sometimes be a daunting task. Today, we are unveiling Midjourney
2023-07-28 · turingpost.com

Exploring the Development of the 3 Leading Open LLMs and Their Chatbot Derivatives
2023-07-24 · a16z.com
A reference architecture for the LLM app stack. It shows the most common systems, tools, and design patterns used by AI startups and tech companies.
2023-07-24 · simonwillison.net
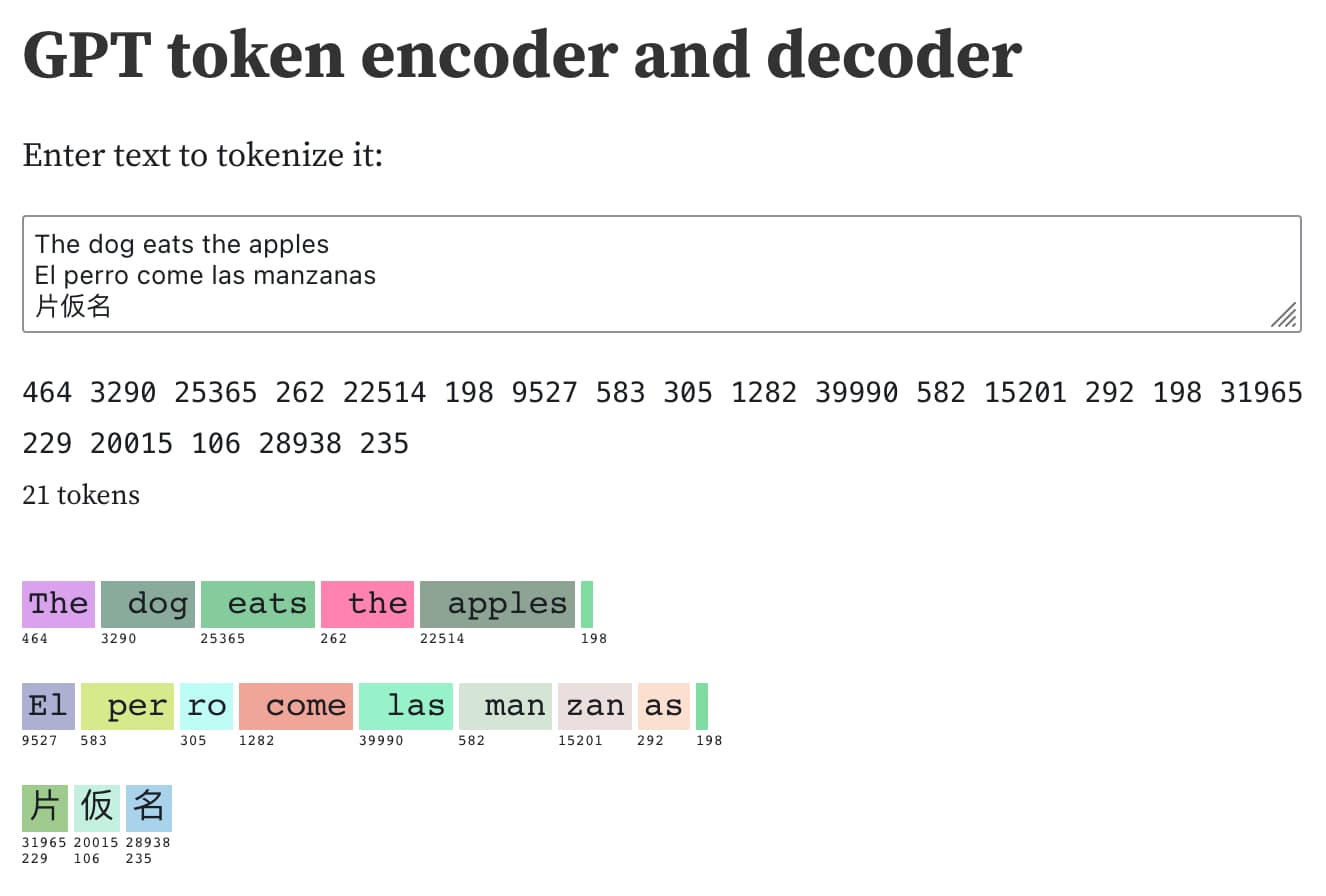
Large language models such as GPT-3/4, LLaMA and PaLM work in terms of tokens. They take text, convert it into tokens (integers), then predict which tokens should come next. Playing …
2023-07-23 · blog.gopenai.com
tldr; techniques to speed up training and inference of LLMs to use large context window up to 100K input tokens during training and…
2023-07-23 · lightning.ai
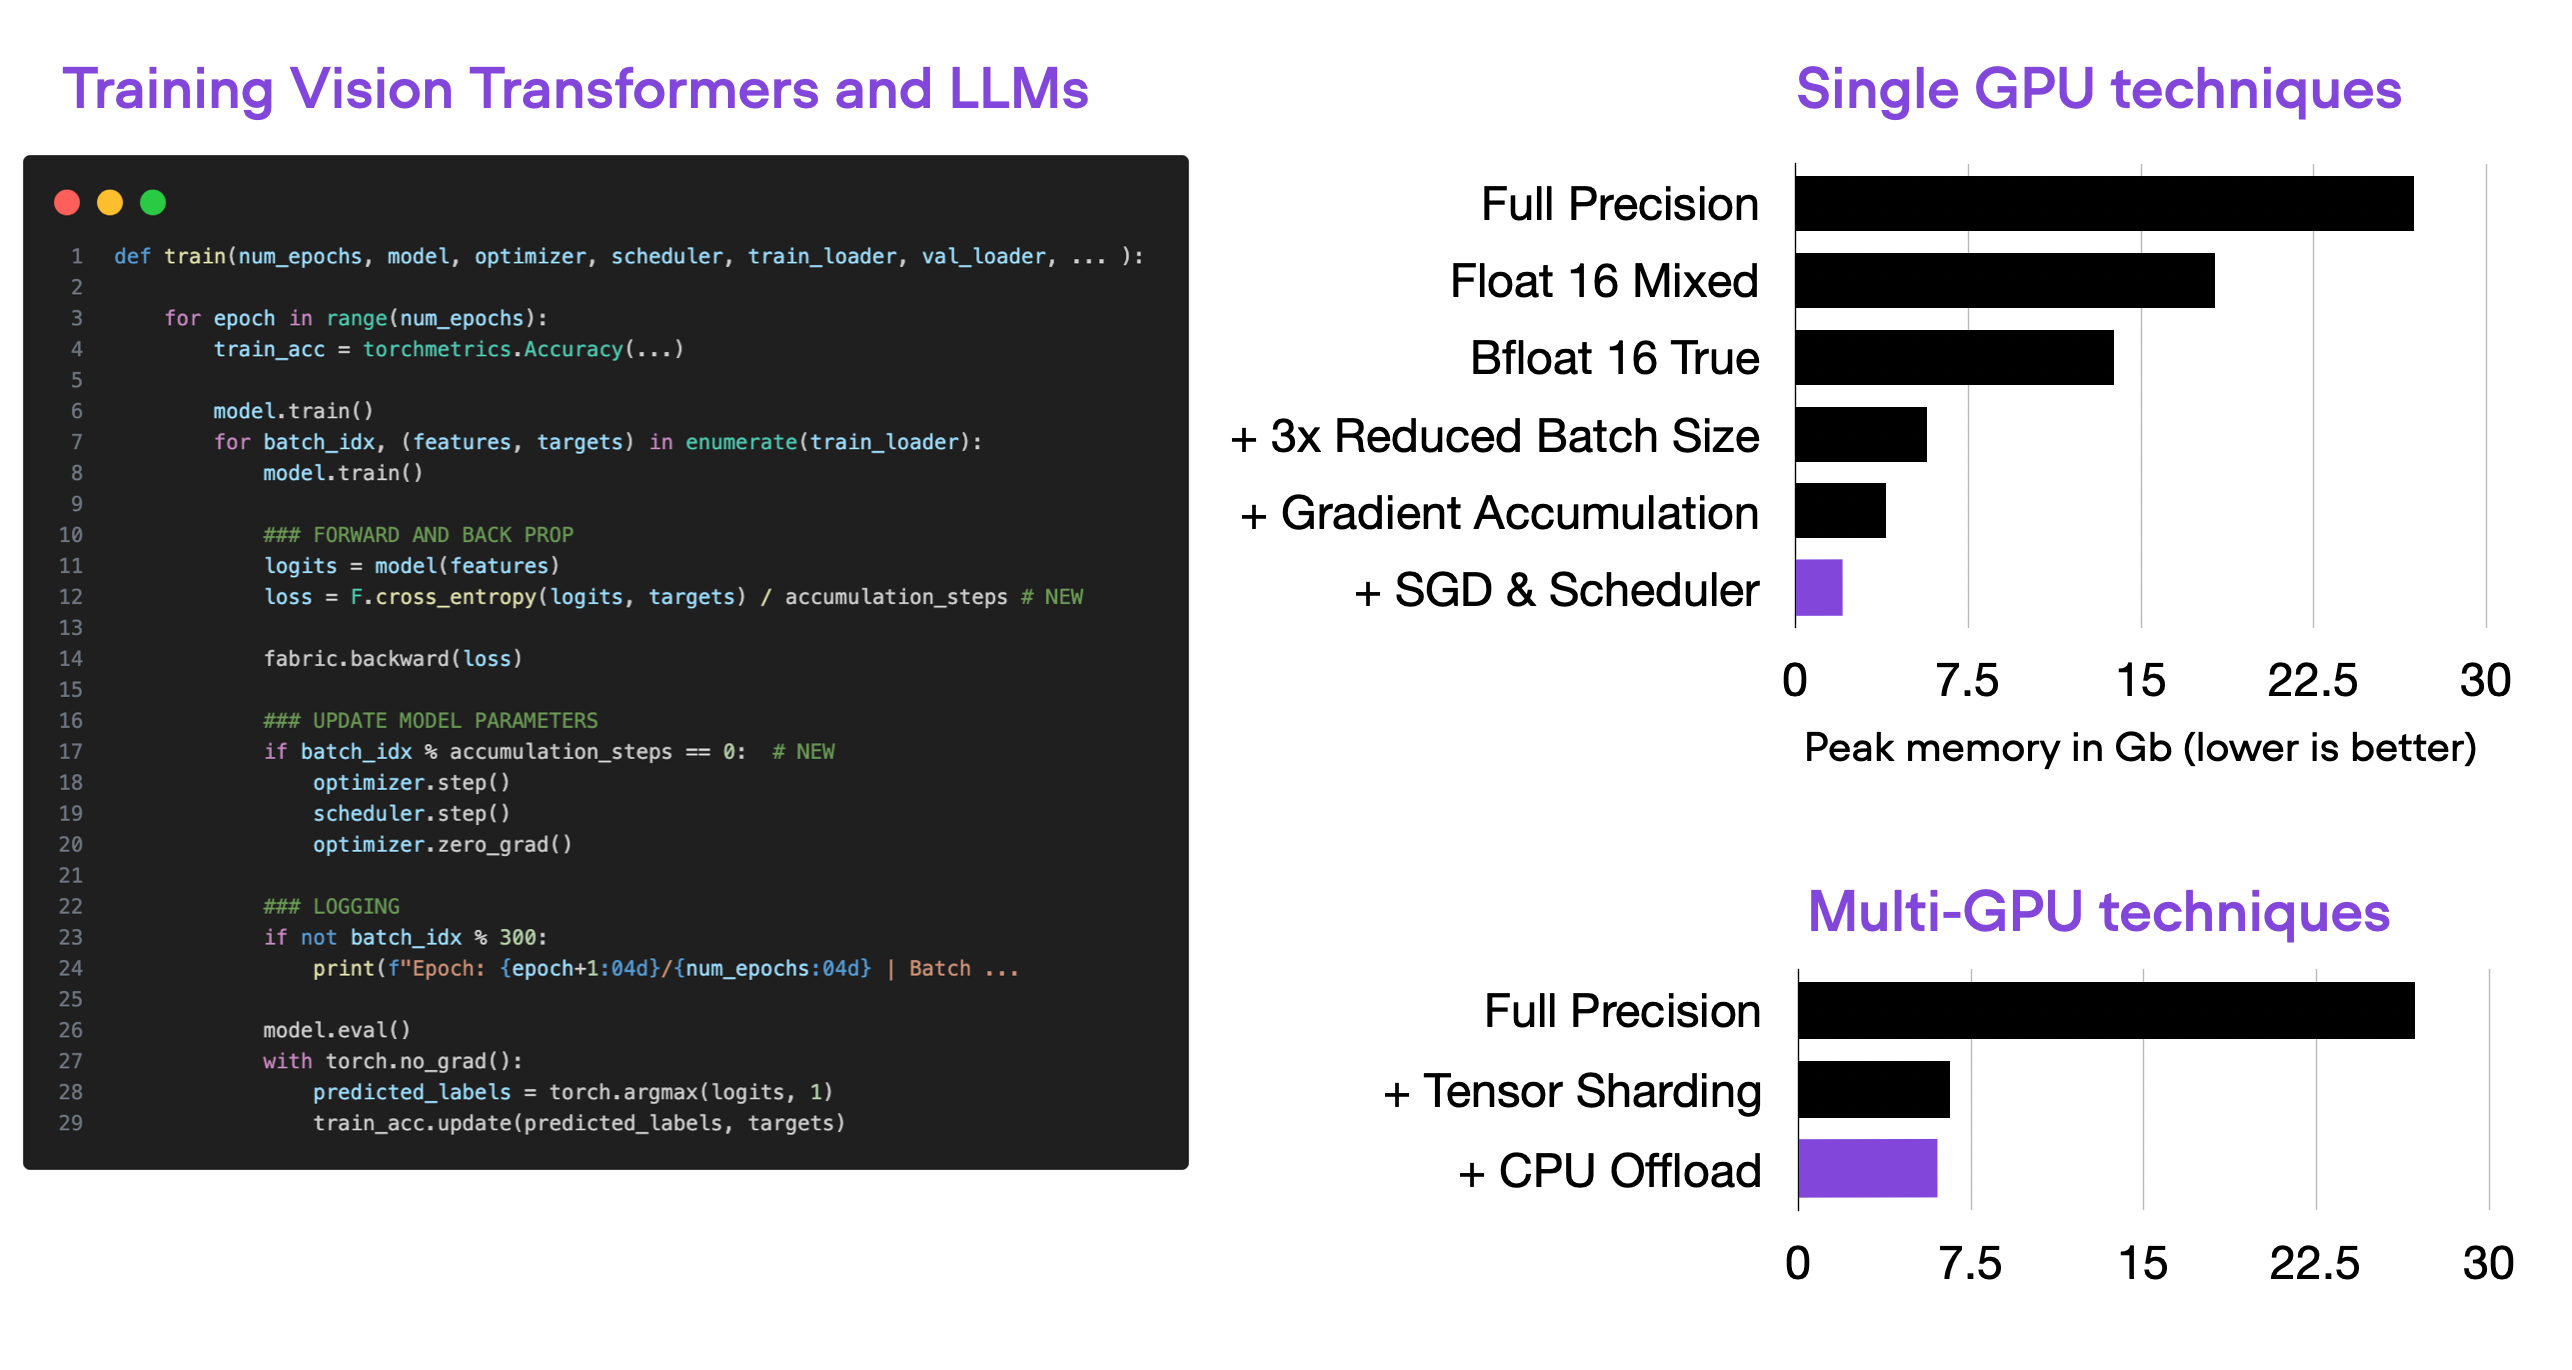
This article provides a series of techniques that can lower memory consumption in PyTorch (when training vision transformers and LLMs) by approximately 20x without sacrificing modeling performance and prediction accuracy.
2023-07-23 · linkedin.com
It crazy how far the ML field has come when it comes to fine-tuning LLMs. A year ago: it was challenging to fine-tune GPT-2 (1.5B) on a single GPU without… | 76 comments on LinkedIn
2023-07-23 · venturebeat.com
A comprehensive guide on how to use Meta's LLaMA 2, the new open-source AI model challenging OpenAI's ChatGPT and Google's Bard.
2023-07-22 · nextplatform.com

We learn a lot of lessons from the hyperscalers and HPC centers of the world, and one of them is that those who control their own software control their
2023-07-22 · towardsdatascience.com
How LLaMA is making open-source cool again
2023-07-22 · venturebeat.com

Not only has LLaMA been trained on more data, with more parameters, the model also performs better than its predecessor, according to Meta.
2023-07-22 · venturebeat.com

MosaicML claims that the MPT-7B-8K LLM exhibits exceptional proficiency in summarization and answering tasks compared to previous models.
2023-07-12 · github.com

A curated list of practical guide resources of LLMs (LLMs Tree, Examples, Papers) - Mooler0410/LLMsPracticalGuide
2023-06-19 · kdnuggets.com

Falcon LLM, is the new large language model that has taken the crown from LLaMA.
2023-06-19 · towardsdatascience.com
Get started using Falcon-7B, Falcon-40B, and their instruct versions
2023-06-08 · github.com

Seamlessly integrate LLMs into scikit-learn.
2023-06-02 · spectrum.ieee.org

GPUs may dominate, but CPUs could be perfect for smaller AI models
2023-05-19 · informationisbeautiful.net

AI is getting very chatty! Here’s a visualisation charting the rise of Large Language Models like GPT4, LaMDA, LLaMa, PaLM and their bots...
2023-05-05 · github.com

OpenLLaMA, a permissively licensed open source reproduction of Meta AI’s LLaMA 7B trained on the RedPajama dataset - openlm-research/open_llama
2023-05-03 · github.com

A guidance language for controlling large language models. - guidance-ai/guidance
2023-04-29 · sebastianraschka.com
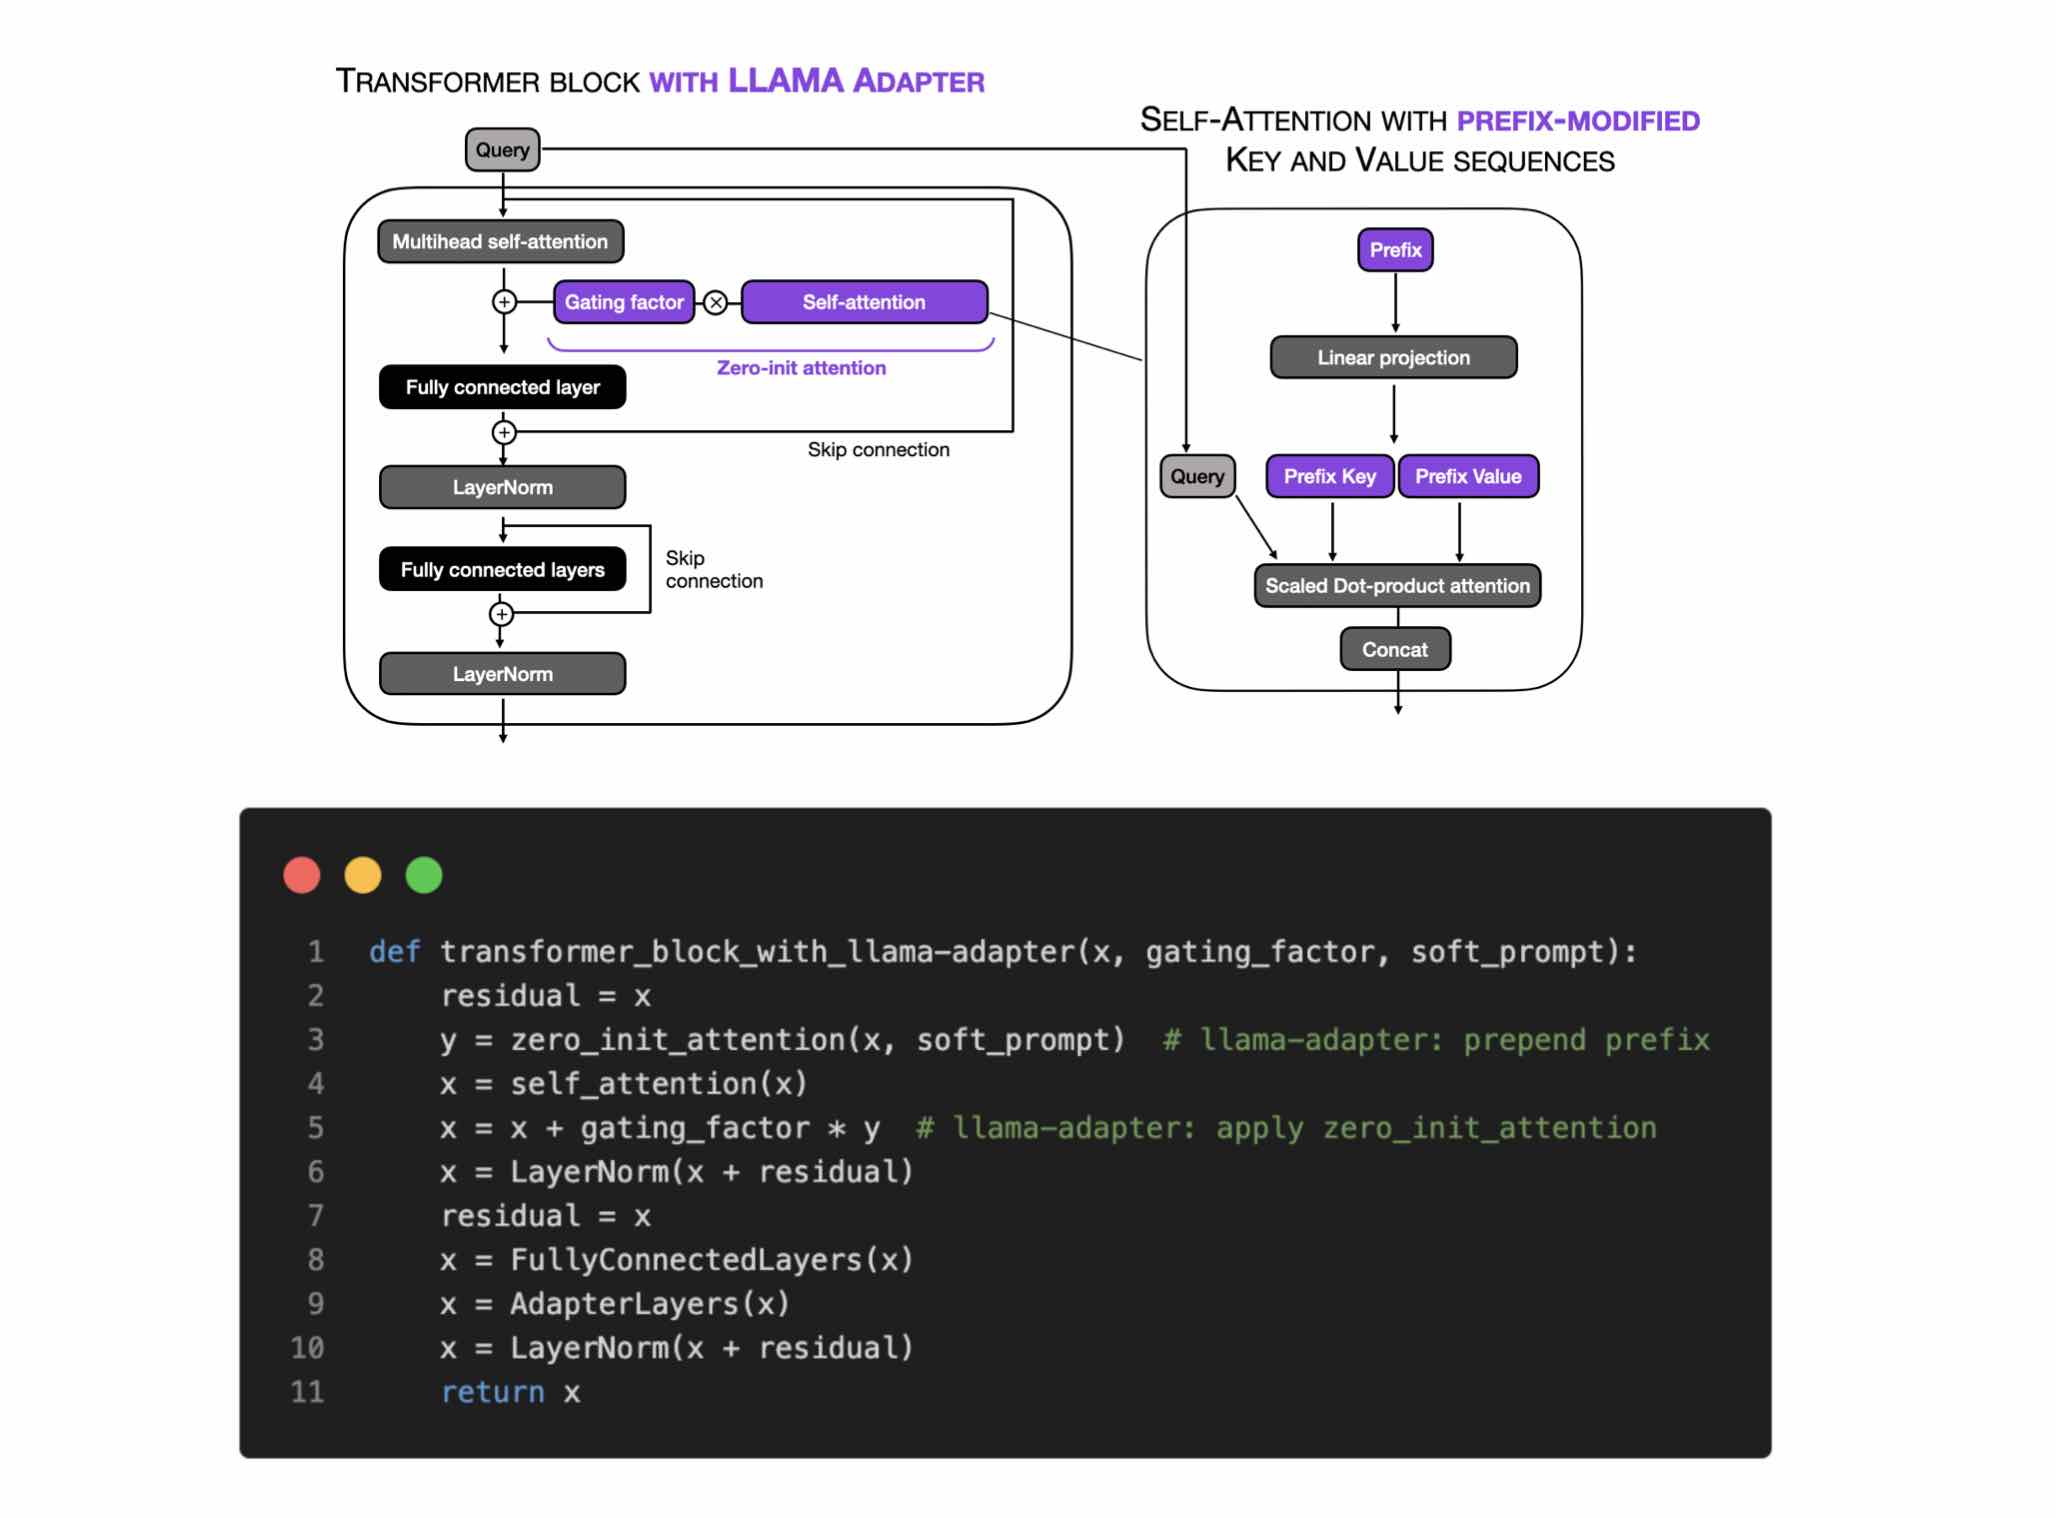
In the rapidly evolving field of AI, using large language models in an efficient and effective manner is becoming more and more important. In this article, y...
2023-04-29 · thesequence.substack.com
Created by researchers from UC Berkeley, CMU, Stanford, and UC San Diego, Vicuna is part of the new wave of models that use Meta's LLaMA as its foundation.
2023-04-25 · datamachina.substack.com
Your own LLM. MiniGPT-4. WebGPT on WebGPU. Transformers from scratch. ChatGTP Plugins demo live. Whisper JAX. LLaVA. MetaAI DINO SoTA Computer Vision. Autonomous agents in LangChain. RedPajama.
2023-04-21 · thesequence.substack.com
Sundays, The Sequence Scope brings a summary of the most important research papers, technology releases and VC funding deals in the artificial intelligence space.
2023-04-21 · crfm.stanford.edu
2023-04-19 · washingtonpost.com

An analysis of a chatbot data set by The Washington Post reveals the proprietary, personal, and often offensive websites that go into an AI’s training data.
2023-04-19 · magazine.sebastianraschka.com
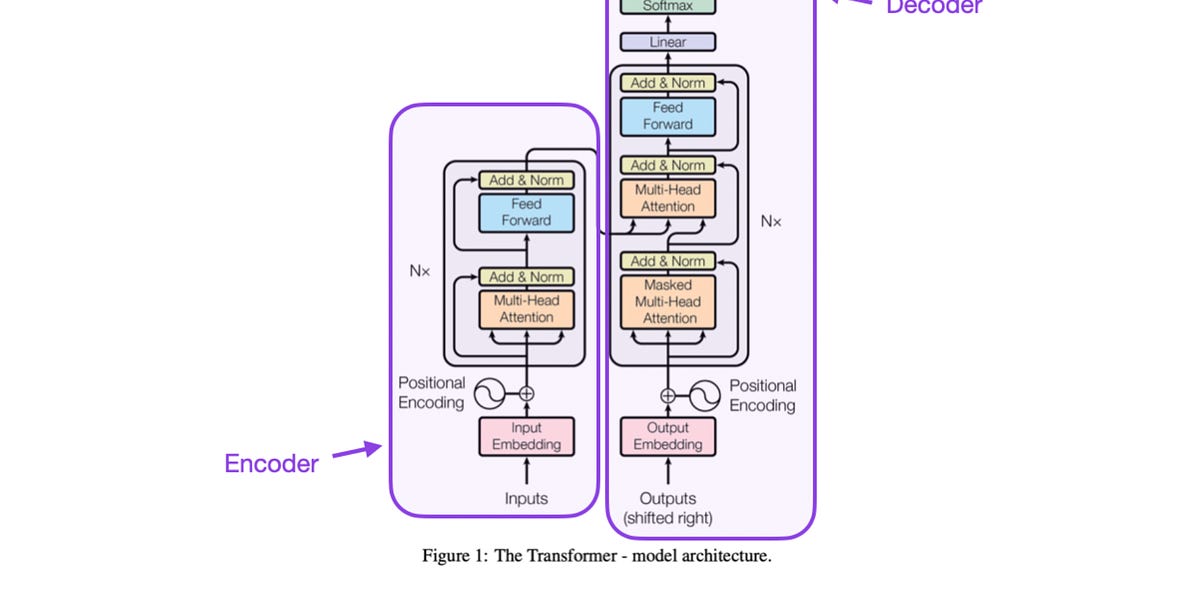
A Cross-Section of the Most Relevant Literature To Get Up to Speed
2023-04-16 · arstechnica.com
Dolly 2.0 could spark a new wave of fully open source LLMs similar to ChatGPT.
2023-04-13 · ruxu.dev

2023-04-08 · huggingface.co
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
2023-03-15 · cocktailpeanut.github.io
Dead simple way to run LLaMA on your computer
2023-03-03 · analyticsvidhya.com
The article talks about R packages with a range of functions, including data manipulation, data visualization, machine learning, etc.
2023-02-25 · arstechnica.com
LLaMA-13B reportedly outperforms ChatGPT-like tech despite being 10x smaller.
2022-12-07 · towardsdatascience.com
An intuitive understanding of how AI-generated art is made by Stable Diffusion, Midjourney, or DALL-E
2022-11-23 · deepnote.com
Explore data with Python & SQL, work together with your team, and share insights that lead to action — all in one place with Deepnote.
2022-10-08 · fastcompany.com
If you thought text-to-image AI was unbelievable, wait until you see how it compresses images.