llama
271 bookmarks · page 4 of 6
2024-08-04 · marktechpost.com

Meta's recent release of Llama 3.1 has stirred excitement in the AI community, offering an array of remarkable applications. This groundbreaking model, particularly the 405B variant, stands out for its superior performance and open-source accessibility, outpacing even top-tier…
2024-07-24 · venturebeat.com
Llama 3.1 is the latest version of Meta's large language models, with a new model weight, 405 billion parameters, the biggest model it's trained.
2024-07-24 · developer.nvidia.com
The newly unveiled Llama 3.1 collection of 8B, 70B, and 405B large language models (LLMs) is narrowing the gap between proprietary and open-source models. Their open nature is attracting more…
2024-07-24 · marktechpost.com

Meta announced the release of Llama 3.1, the most capable model in the LLama Series. This latest iteration of the Llama series, particularly the 405B model, represents a substantial advancement in open-source AI capabilities, positioning Meta at the forefront of AI innovation…
2024-07-24 · dataconomy.com
Meta llama 3.1 405b kicks off a fresh chapter for open-source language models. This breakthrough brings unmatched skills to AI
2024-07-14 · pytorch.org
Attention, as a core layer of the ubiquitous Transformer architecture, is a bottleneck for large language models and long-context applications. FlashAttention (and FlashAttention-2) pioneered an approach to speed up attention on GPUs by minimizing memory reads/writes, and is now…
2024-07-08 · oranlooney.com
2024-07-04 · anyscale.com
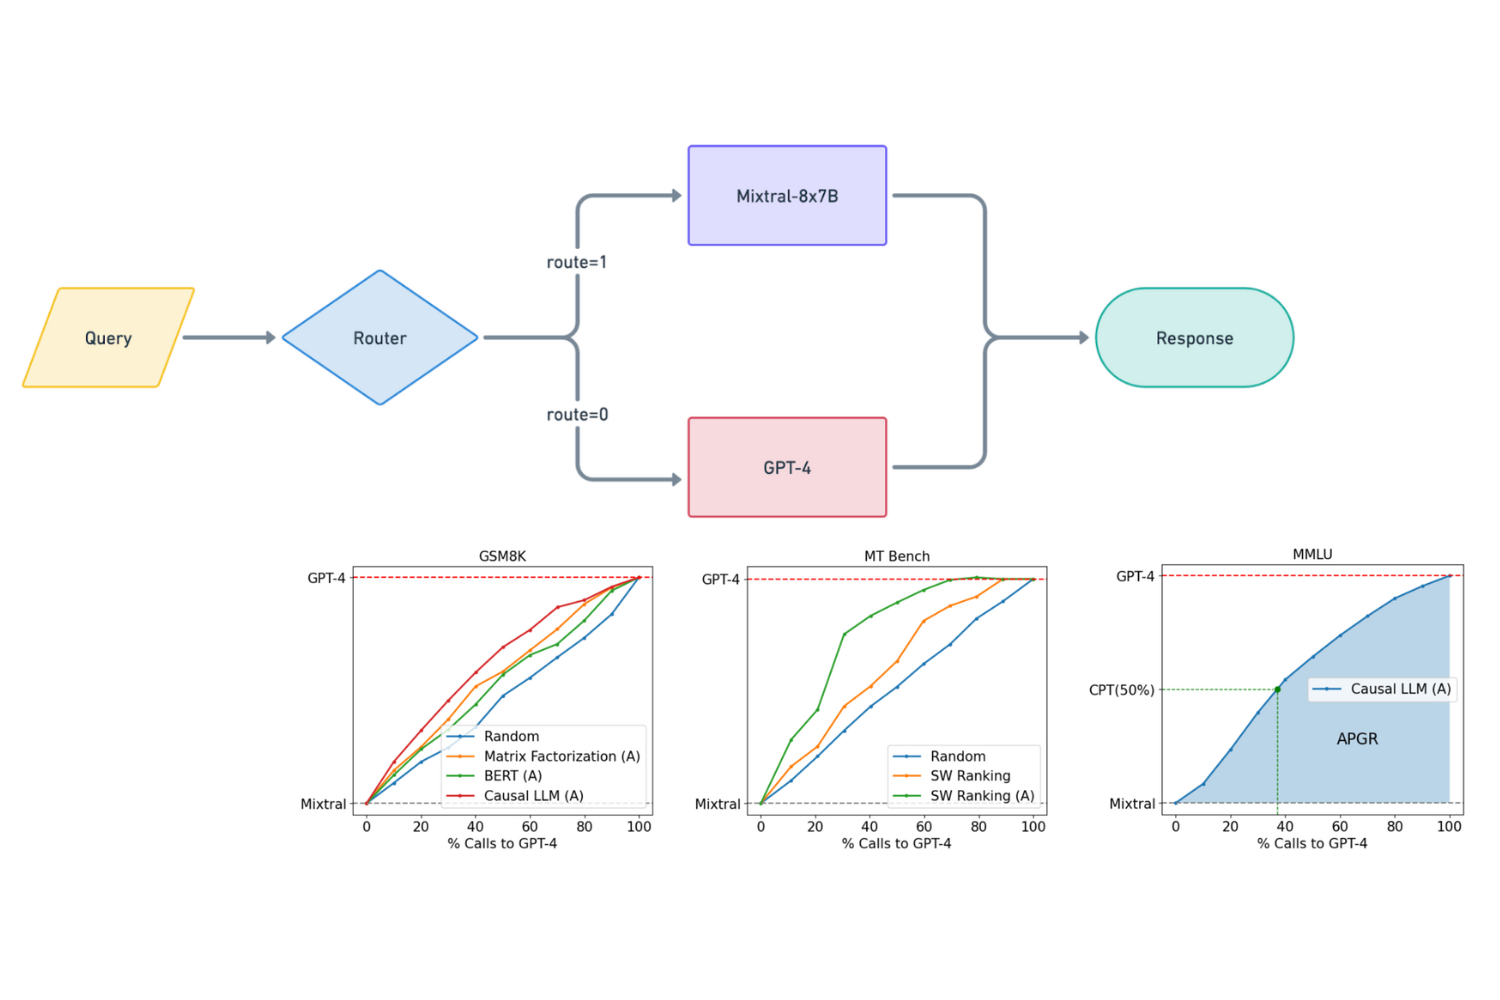
Anyscale is the leading AI application platform. With Anyscale, developers can build, run and scale AI applications instantly.
2024-07-03 · wccftech.com
Nscale has tested AMD's flagship Instinct MI300X AI accelerator utilizing the GEMM tuning framework, achieving 7x faster performance.
2024-06-28 · marktechpost.com

The Sohu AI chip by Etched is a thundering breakthrough, boasting the title of the fastest AI chip to date. Its design is a testament to cutting-edge innovation, aiming to redefine the possibilities within AI computations and applications. At the center of Sohu's exceptional…
2024-06-27 · venturebeat.com

AI startup Gradient and cloud platform Crusoe teamed up to extend the context window of Meta's Llama 3 models to 1 million tokens.
2024-06-20 · marktechpost.com

In the rapidly advancing field of Artificial Intelligence (AI), effective use of web data can lead to unique applications and insights. A recent tweet has brought attention to Firecrawl, a potent tool in this field created by the Mendable AI team. Firecrawl is a state-of-the-art…
2024-06-13 · spectrum.ieee.org
GPU maker tops new MLPerf benchmarks on graph neural nets and LLM fine-tuning
2024-06-11 · marktechpost.com

Choosing large language models (LLMs) tailored for specific tasks is crucial for maximizing efficiency and accuracy. With natural language processing (NLP) advancements, different models have emerged, each excelling in unique domains. Here is a comprehensive guide to the most…
2024-05-28 · thenewstack.io

Performance testing shows integrating Tantivy’s full-text search engine library into vector search significantly improves speed and performance.
2024-05-26 · thediff.co

if the centralizing forces of data and compute hold, open and closed-source AI cannot both dominate long-term
2024-05-24 · marktechpost.com

Vision-language models (VLMs), capable of processing both images and text, have gained immense popularity due to their versatility in solving a wide range of tasks, from information retrieval in scanned documents to code generation from screenshots. However, the development of…
2024-05-21 · github.com

llama3 implementation one matrix multiplication at a time - naklecha/llama3-from-scratch
2024-05-21 · marktechpost.com

Artificial intelligence (AI) has revolutionized various fields by introducing advanced models for natural language processing (NLP). NLP enables computers to understand, interpret, and respond to human language in a valuable way. This field encompasses text generation…
2024-05-21 · thenewstack.io

While RAG will remain a staple of production applications, Gemini 1.5 Pro and similar models will help enterprise data science teams.
2024-05-13 · sebastianraschka.com
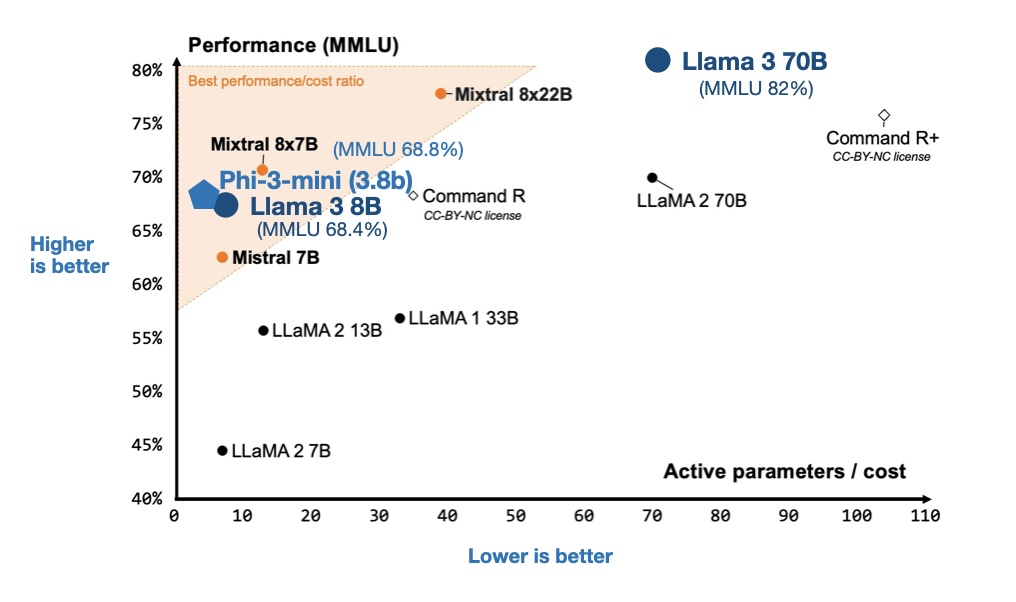
What a month! We had four major open LLM releases: Mixtral, Meta AI's Llama 3, Microsoft's Phi-3, and Apple's OpenELM. In my new article, I review and discus...
2024-05-12 · cs.utexas.edu
2024-05-12 · marktechpost.com

The capacity of large language models (LLMs) to produce adequate text in various application domains has caused a revolution in natural language creation. These models are essentially two types: 1) Most model weights and data sources are open source. 2) All model-related…
2024-05-11 · thenewstack.io

There are still some limitations when summarizing very large documents. Here are some ways to mitigate these effects.
2024-05-08 · arxiv.org

Large language models such as GPT and Llama are trained with a next-token prediction loss. In this work, we suggest that training language models to predict multiple future tokens at once results...
2024-04-25 · marktechpost.com

Are you curious about the intricate world of large language models (LLMs) and the technical jargon that surrounds them? Understanding the terminology, from the foundational aspects of training and fine-tuning to the cutting-edge concepts of transformers and reinforcement…
2024-04-25 · marktechpost.com
Prompt Fuzzer: The Prompt Fuzzer is an interactive tool designed to evaluate the security of GenAI application system prompts by simulating various dynamic LLM-based attacks. It assesses security by analyzing the results of these simulations, helping users fortify their system…
2024-04-19 · theverge.com
The models have some pretty good general knowledge.
2024-04-15 · magazine.sebastianraschka.com
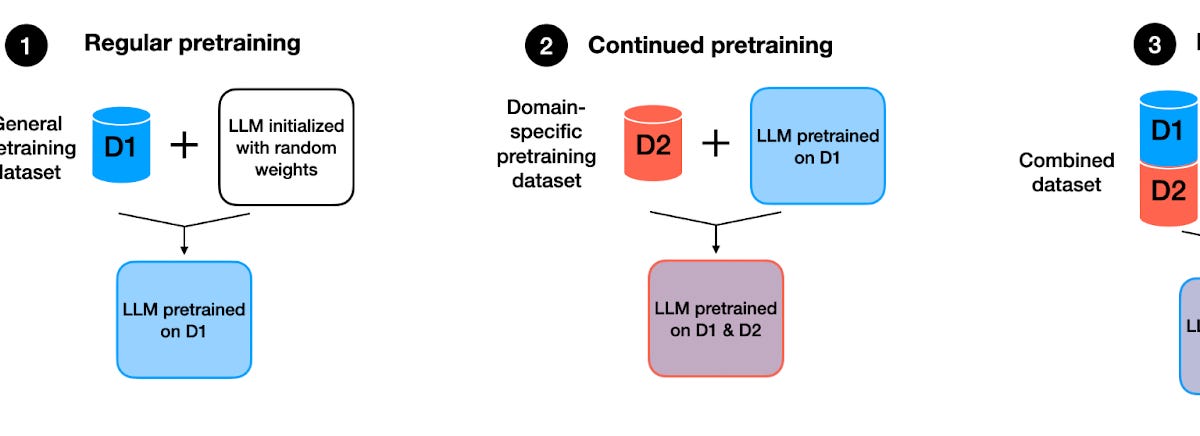
Discussing AI Research Papers in March 2024
2024-04-14 · arstechnica.com
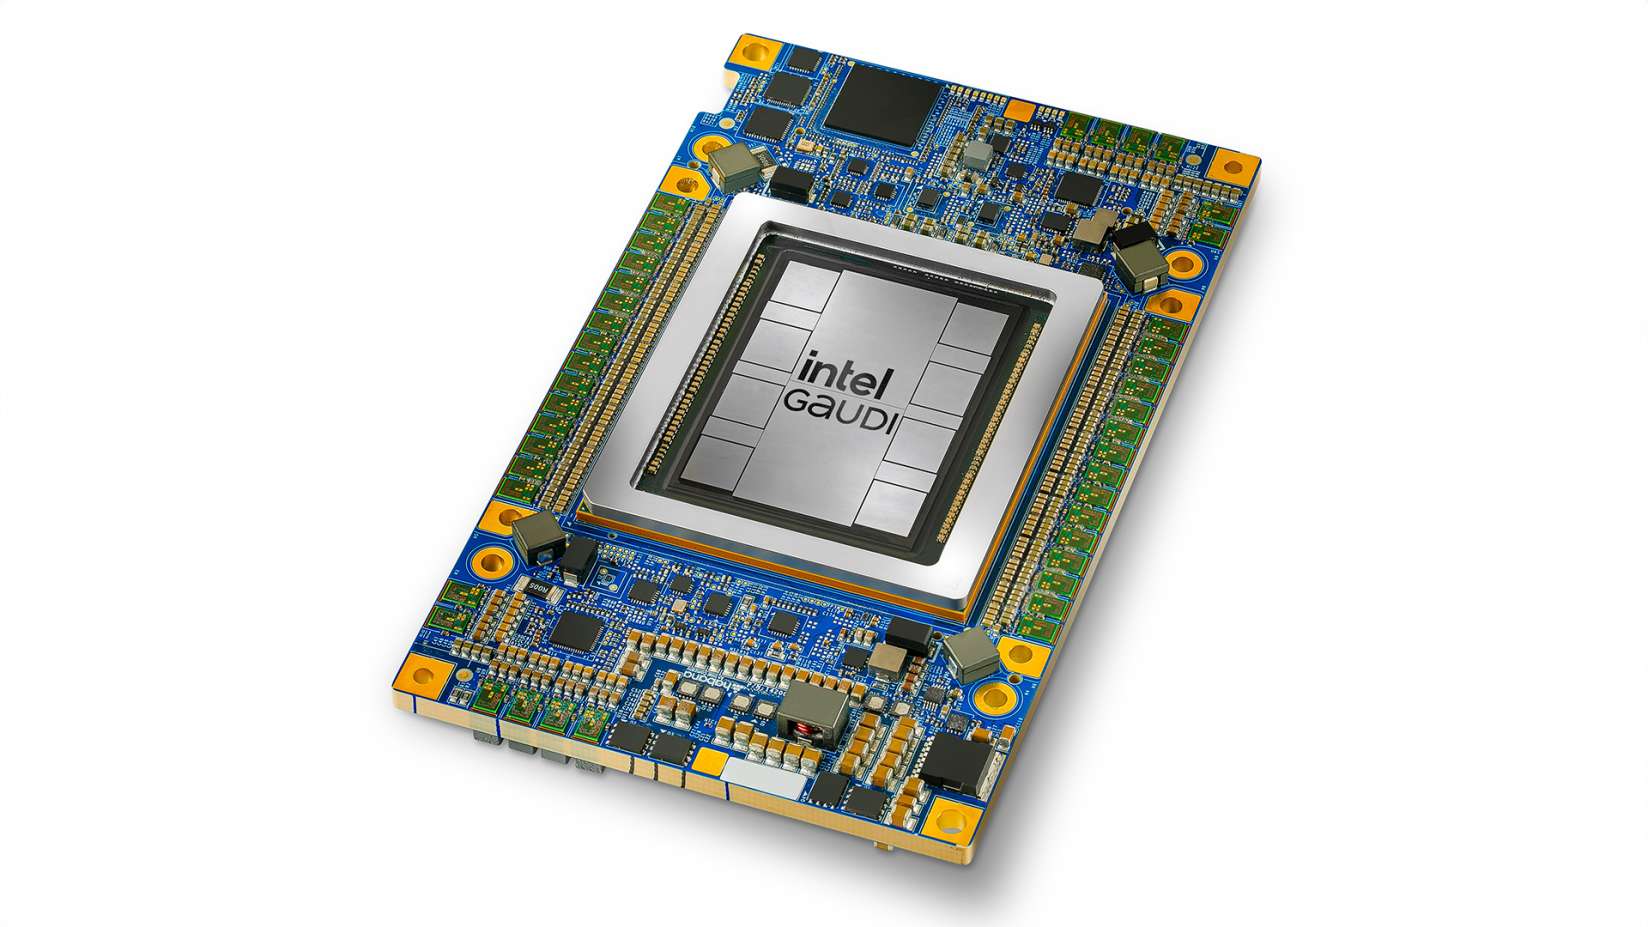
Intel claims 50% more speed when running AI language models vs. the market leader.
2024-04-12 · open.substack.com
GPT-4 Profitability, Cost, Inference Simulator, Parallelism Explained, Performance TCO Modeling In Large & Small Model Inference and Training
2024-04-05 · marktechpost.com

The top open source Large Language Models available for commercial use are as follows. Llama - 2 Meta released Llama 2, a set of pretrained and refined LLMs, along with Llama 2-Chat, a version of Llama 2. These models are scalable up to 70 billion parameters. It was discovered…
2024-04-02 · justine.lol
I wrote 84 new matmul kernels to improve llamafile CPU performance.
2024-03-11 · towardsdatascience.com
Language models (LLMs) have revolutionized the field of natural language processing (NLP) over the last few years, achieving…
2024-03-11 · towardsdatascience.com
Reference architecture patterns and mental models for working with Large Language Models (LLM’s)
2024-03-11 · answer.ai
We’re releasing an open source system, based on FSDP and QLoRA, that can train a 70b model on two 24GB GPUs.
2024-03-11 · towardsdatascience.com
Training a specialized LLM over your own data is easier than you think…
2024-02-29 · github.com
Implementing a ChatGPT-like LLM in PyTorch from scratch, step by step - rasbt/LLMs-from-scratch
2024-02-29 · dataconomy.com
Step into the future of video creation with Google Lumiere, the latest breakthrough from Google Research that promises to redefine
2024-02-29 · towardsdatascience.com
This blog post will look at the “Direct Preference Optimization: Your Language Model is Secretly a Reward Model” paper and its findings.
2024-02-29 · towardsdatascience.com
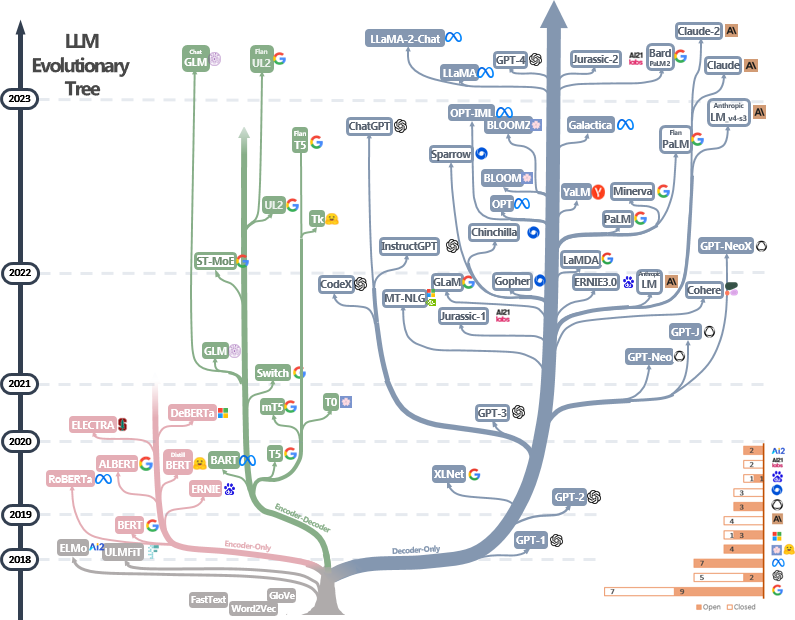
How do we communicate effectively with LLMs?
2024-02-29 · mistral.ai
Mistral Large is our flagship model, with top-tier reasoning capacities. It is also available on Azure.
2024-02-22 · blocksandfiles.com
Startup Groq has developed an machine learning processor that it claims blows GPUs away in large language model workloads – 10x faster than an Nvidia GPU at 10 percent of the cost, and needing a tenth of the electricity. Update: Groq model compilation time and time from access…
2024-02-22 · analyticsvidhya.com
A complete guide to data exploration in R explains how to read data sets in R, explore data in R, impute missing values in your dataset, merge in R, etc
2024-02-15 · dataconomy.com
AI community is once again filled with excitement as Bard is now Gemini and Gemini Advanced offering users an exceptional
2024-01-17 · blog.llamaindex.ai
LlamaIndex is a simple, flexible data framework for connecting custom data sources to large language models (LLMs).
2024-01-16 · magazine.sebastianraschka.com
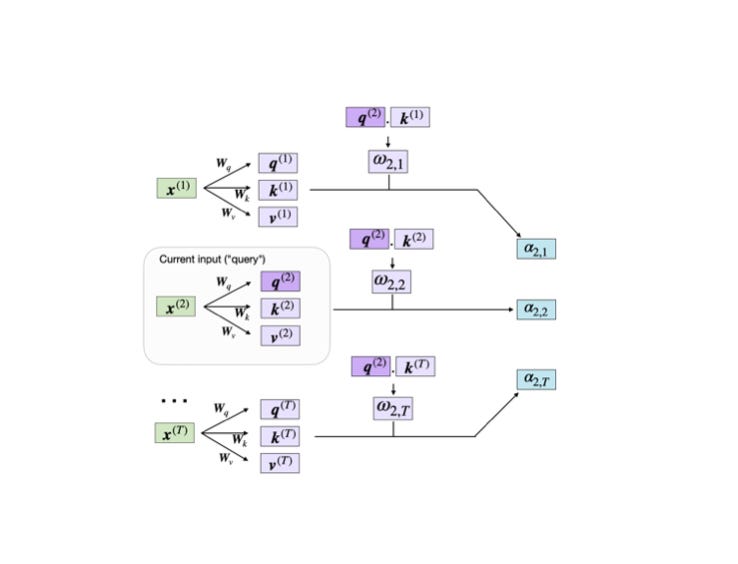
This article will teach you about self-attention mechanisms used in transformer architectures and large language models (LLMs) such as GPT-4 and Llama.
2024-01-07 · jaykmody.com
Implementing a GPT model from scratch in NumPy.
2024-01-07 · magazine.sebastianraschka.com
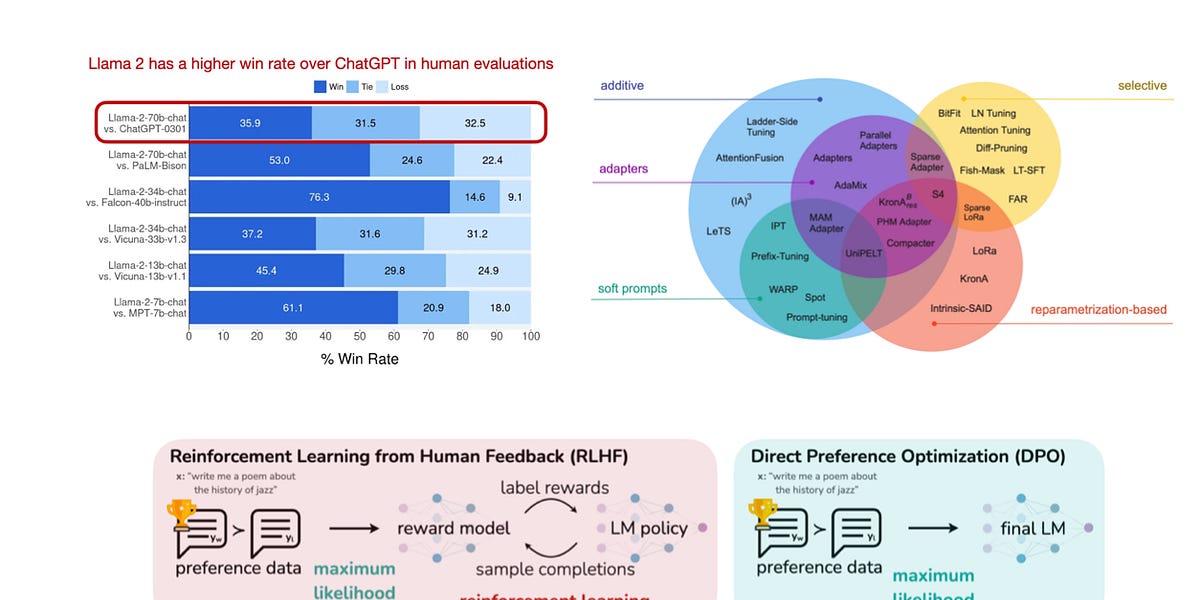
This year has felt distinctly different. I've been working in, on, and with machine learning and AI for over a decade, yet I can't recall a time when these fields were as popular and rapidly evolving as they have been this year. To conclude an eventful 2023 in machine learning…
2023-10-20 · marktechpost.com

The emergence of Large Language Models (LLMs) in natural language processing represents a groundbreaking development. These models, trained on vast amounts of data and leveraging immense computational resources, promise to transform human interactions with the digital world. As…