llama
271 bookmarks · page 3 of 6
2025-05-11 · github.com

🔥 Turn entire websites into LLM-ready markdown or structured data. Scrape, crawl and extract with a single API. - mendableai/firecrawl
2025-05-03 · thecleverprogrammer.com

In this article, I'll take you through a list of 10 hands-on LLM projects with Python you should try to master LLMs. LLM Projects with Python.
2025-04-30 · arxiv.org

Measuring progress is fundamental to the advancement of any scientific field. As benchmarks play an increasingly central role, they also grow more susceptible to distortion. Chatbot Arena has emerged as the go-to leaderboard for ranking the most capable AI systems. Yet, in this…
2025-04-21 · kdnuggets.com

Enhance language models with real-time document retrieval and dynamic knowledge integration using retrieval-augmented generation and LlamaIndex.
2025-04-20 · readtrung.com
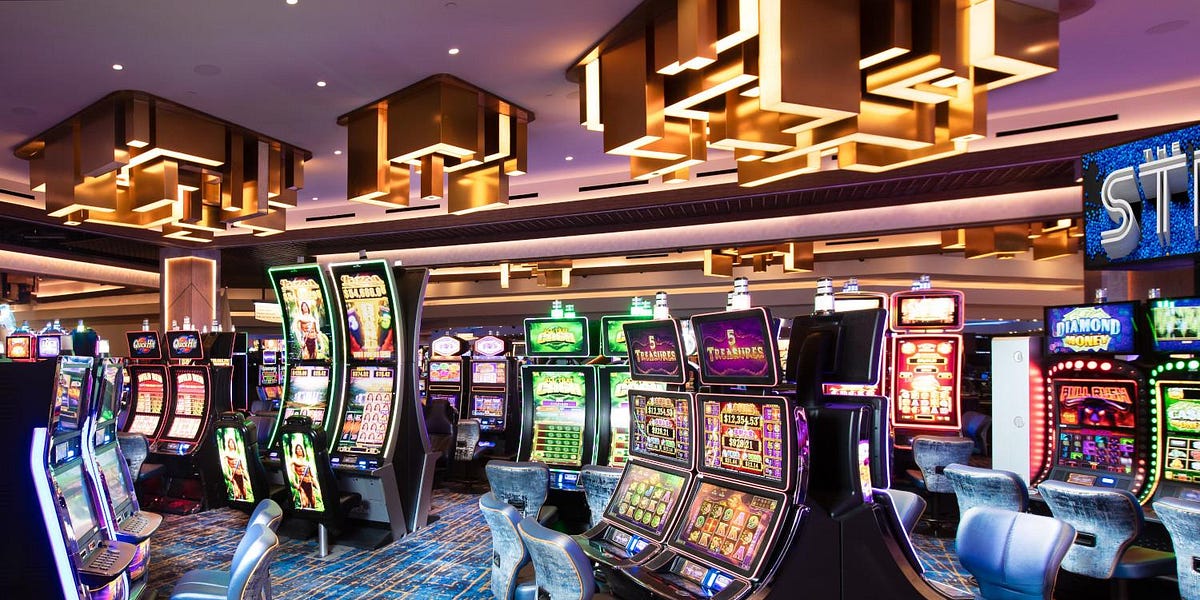
Slot Machines are the workhorse of Las Vegas casinos. After decades of design tweaks, the "crack cocaine of gambling" brings in more revenue than every other casino game combined.
2025-04-20 · sebastianraschka.com
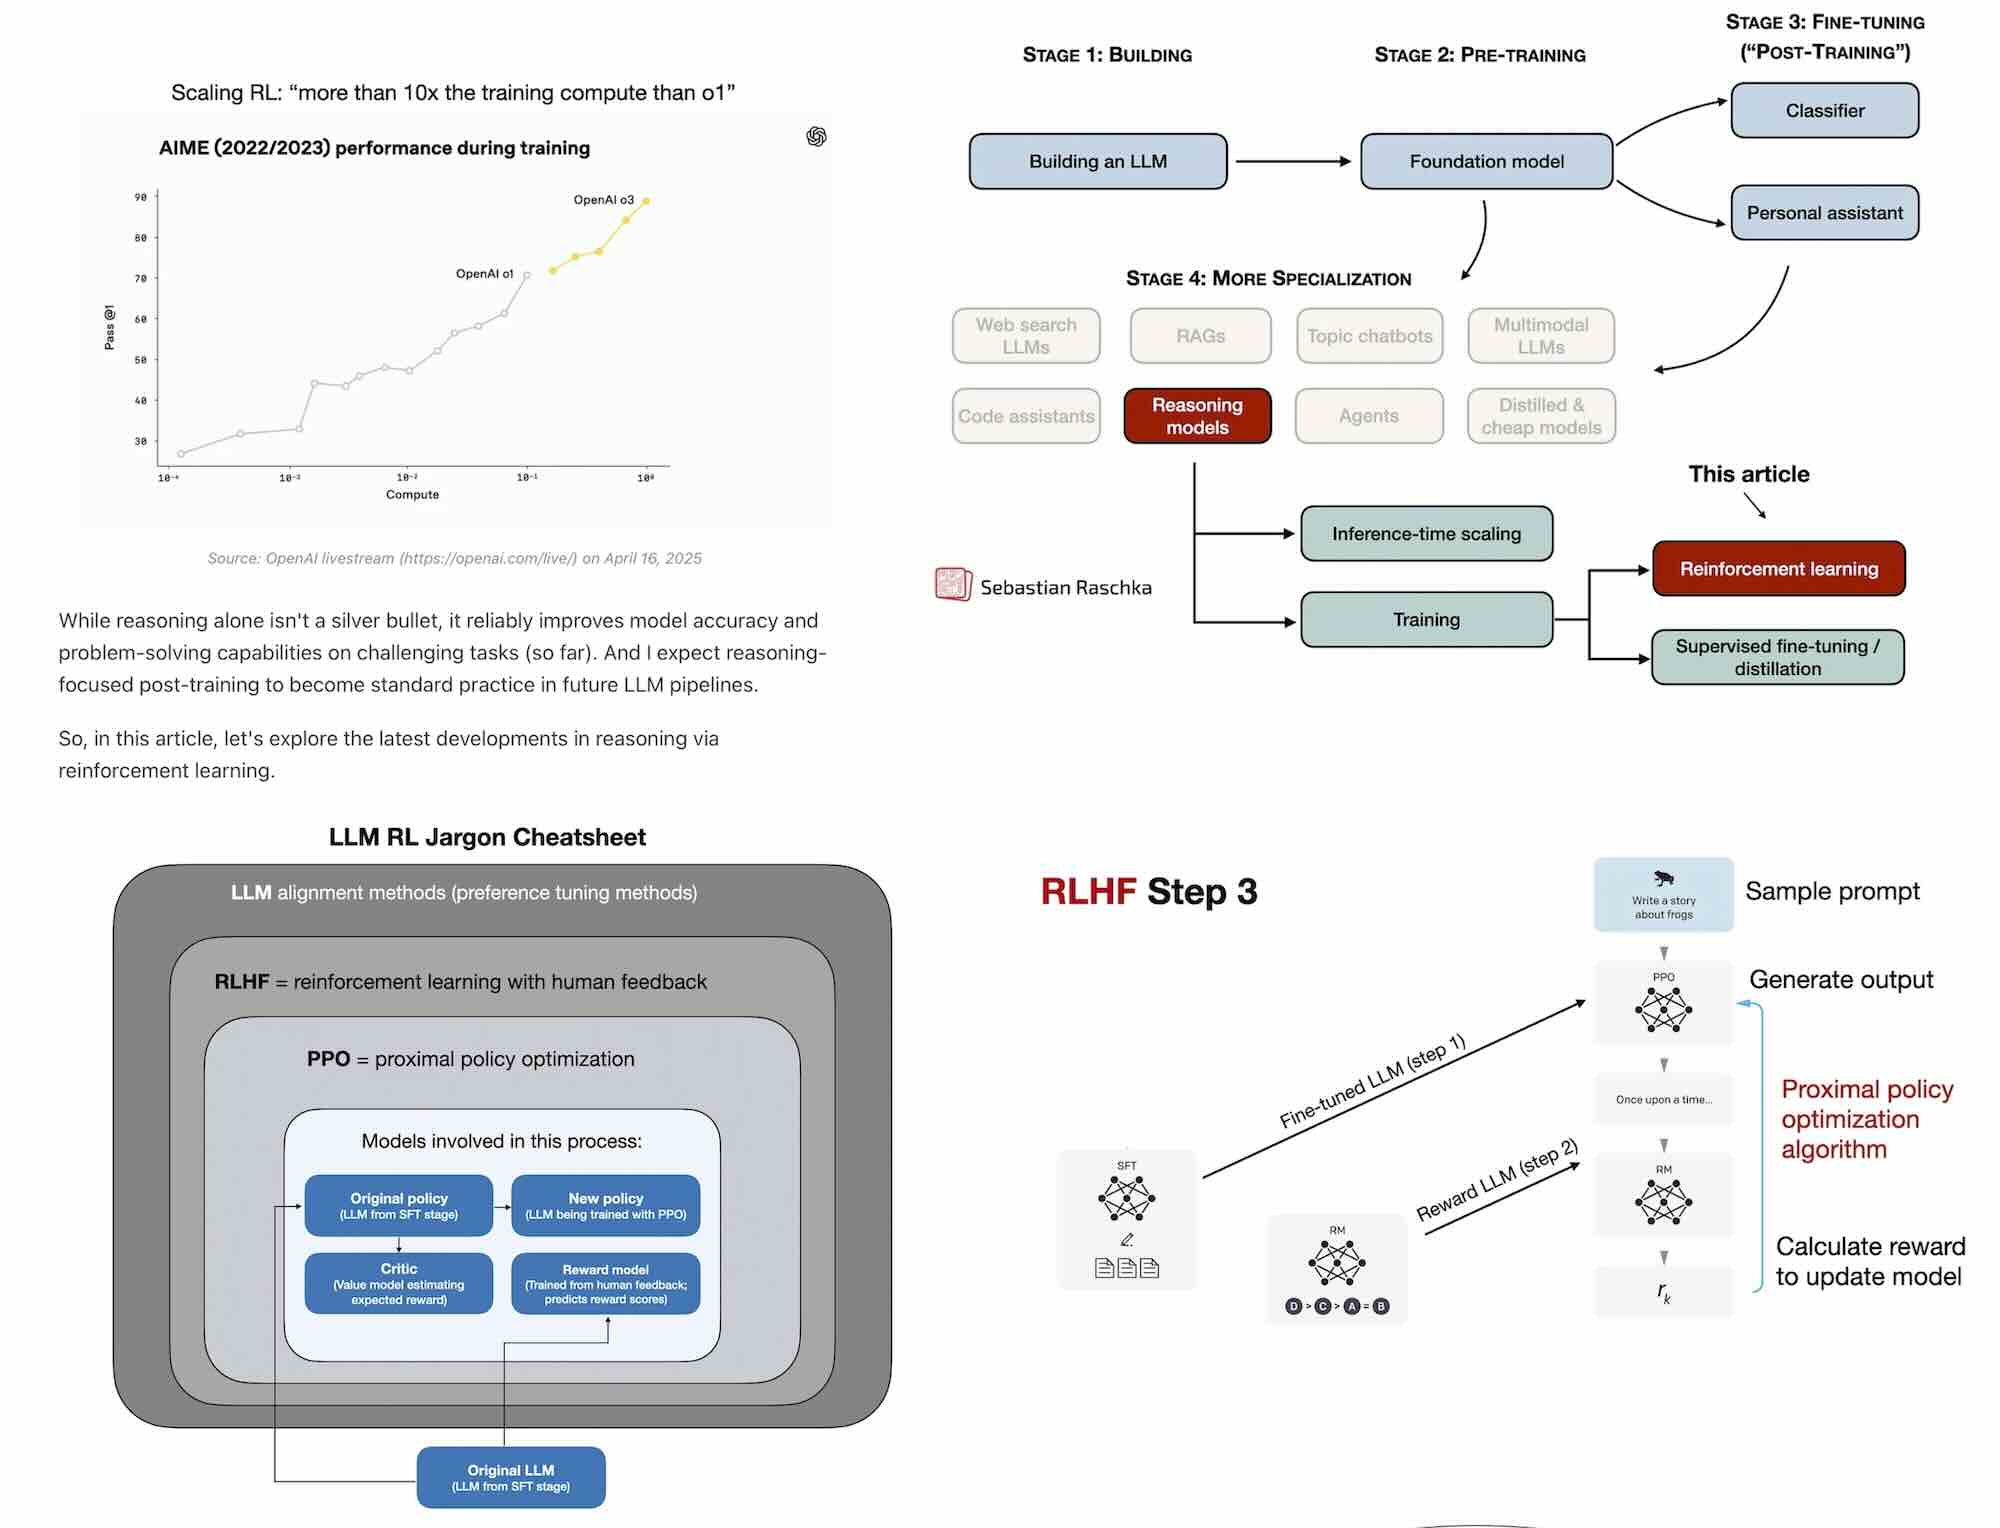
A lot has happened this month, especially with the releases of new flagship models like GPT-4.5 and Llama 4. But you might have noticed that reactions to these releases were relatively muted. Why? One reason could be that GPT-4.5 and Llama 4 remain conventional models, which…
2025-04-17 · arxiv.org
2025-04-08 · elenacross7.medium.com

MCP, short for Model Context Protocol, is the hot new standard behind how Large Language Models (LLMs) like Claude, GPT, or Cursor integrate with tools and data. It’s been described as the “USB-C for…
★ 2025-04-07 · huggingface.co
A Blog post by Ksenia Se on Hugging Face
four advanced attention mechanisms which improve how models handle long sequences, cut memory use and make attention learnable
Self-Attention which lets each token “look” at all others
2025-04-07 · techmeme.com

By Matteo Wong / The Atlantic. View the full context on Techmeme.
2025-04-06 · ai.meta.com

We’re introducing Llama 4 Scout and Llama 4 Maverick, the first open-weight natively multimodal models with unprecedented context support and our first built using a mixture-of-experts (MoE) architecture.
2025-04-04 · venturebeat.com

Articul8's specialized models tackle complex industrial sequences where timing and order matter, challenging the one-size-fits-all approach to enterprise AI.
2025-03-26 · machinelearningmastery.com
In this article, we explore 10 of the Python libraries every developer should know in 2025.
2025-03-22 · eugeneyan.com
Model architectures, data generation, training paradigms, and unified frameworks inspired by LLMs.
2025-03-12 · dataconomy.com
Model cards are documentation tools in machine learning that provide essential information about models, promoting transparency, trust, and ethical considerations in AI systems.
2025-03-11 · open.substack.com
Plus CSS view transitions and a major update to llm-openrouter
2025-03-09 · techcrunch.com

A federal judge is allowing an AI-related copyright lawsuit against Meta to move forward, although he dismissed part of the suit. In Kadrey vs. Meta,
2025-03-08 · open.substack.com
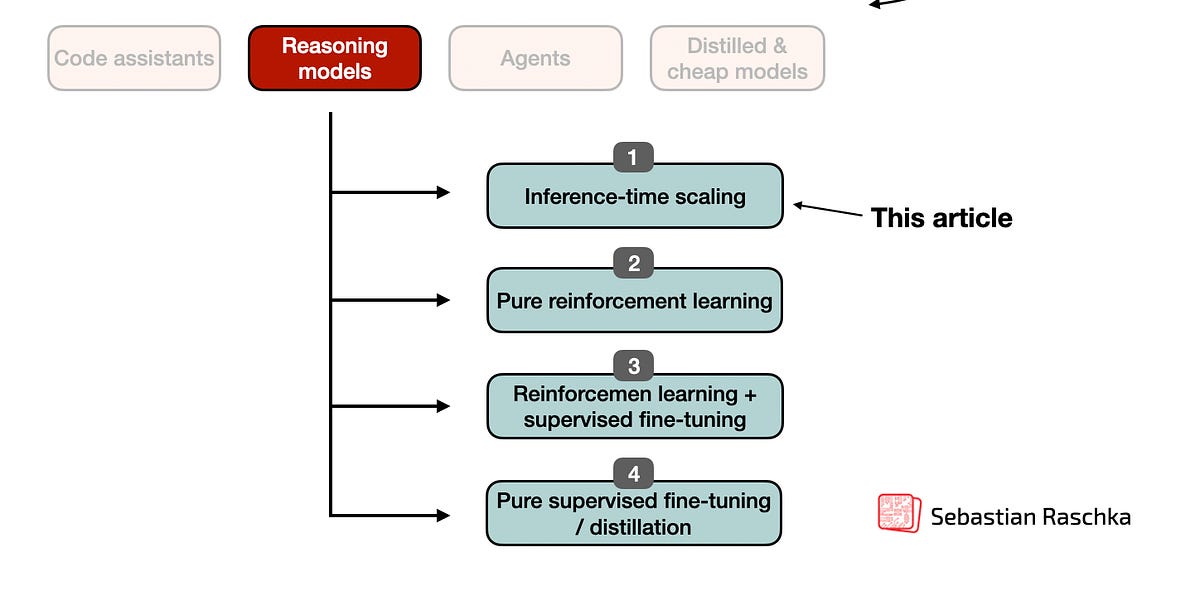
Part 1: Inference-Time Compute Scaling Methods
2025-03-04 · simonwillison.net
This release of the `llm-ollama` plugin adds support for [schemas](https://simonwillison.net/2025/Feb/28/llm-schemas/), thanks to a [PR by Adam Compton](https://github.com/taketwo/llm-ollama/pull/36). Ollama provides very robust support for this pattern thanks to their…
2025-02-24 · linkedin.com

OpenAI's president Greg Brockman recently shared this cool template for prompting their reasoning models o1/o3. Turns out, this is great for ANY reasoning… | 32 comments on LinkedIn
2025-02-21 · artificialanalysis.ai
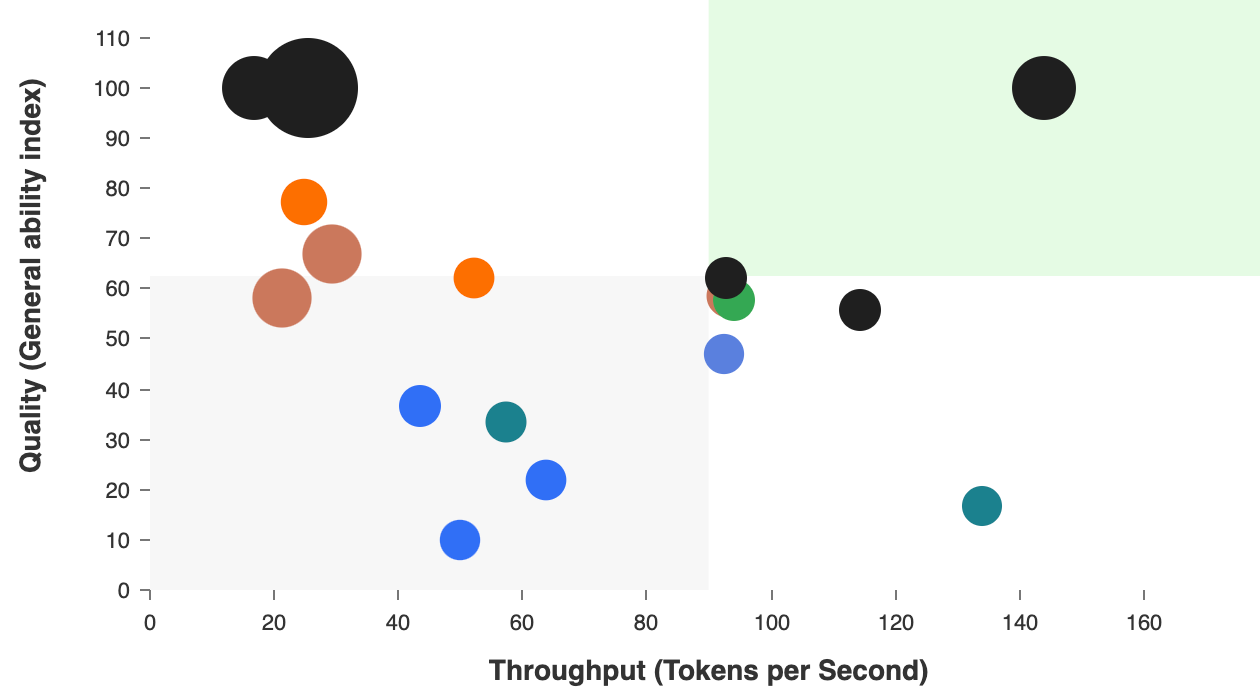
Comparison and ranking the performance of over 30 AI models (LLMs) across key metrics including quality, price, performance and speed (output speed - tokens per second & latency - TTFT), context window & others.
2025-02-17 · digiday.com
Marketers should be wary of open-source programs promoted by purveyors with a walled garden history.
2025-02-07 · simonwillison.net
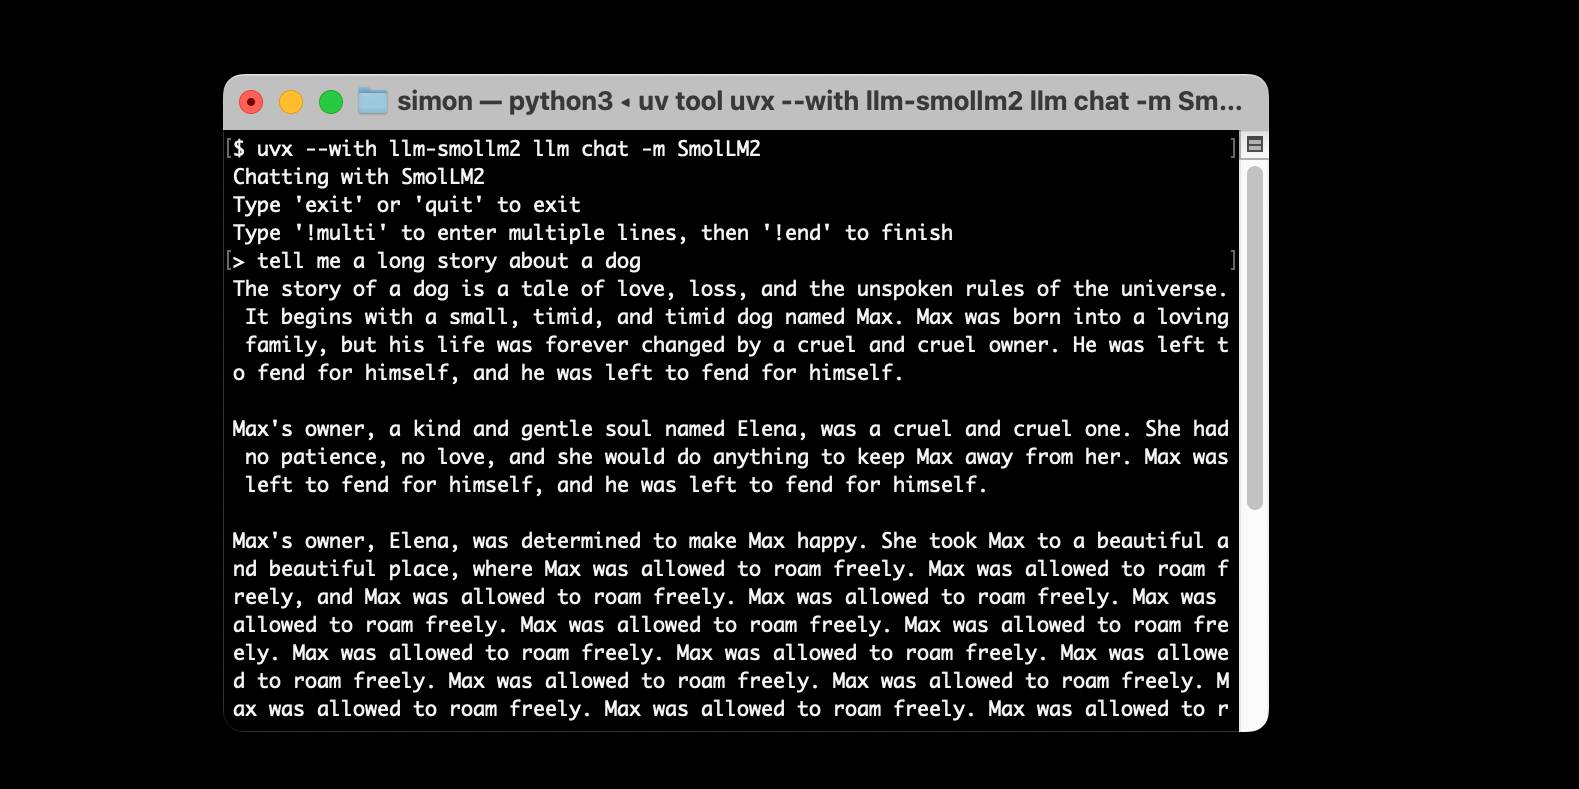
I just released llm-smollm2, a new plugin for LLM that bundles a quantized copy of the SmolLM2-135M-Instruct LLM inside of the Python package. This means you can now pip install …
2025-02-02 · marktechpost.com
In our previous tutorial, we built an AI agent capable of answering queries by surfing the web. However, when building agents for longer-running tasks, two critical concepts come into play: persistence and streaming. Persistence allows you to save the state of an agent at any…
2025-01-29 · asteriskmag.com
By 2030, leading AI labs will need data centers so massive they will require the power equivalent of some of America’s largest cities. Will they be able to find it?
2025-01-29 · reuters.com

The unusual timing of the Qwen 2.5-Max's release points to the pressure DeepSeek's meteoric rise in the past three weeks has placed on overseas rivals and domestic competition.
2025-01-27 · newsletter.languagemodels.co

A recipe for reasoning LLMs
2025-01-26 · marktechpost.com

AI has entered an era of the rise of competitive and groundbreaking large language models and multimodal models. The development has two sides, one with open source and the other being propriety models. DeepSeek-R1, an open-source AI model developed by DeepSeek-AI, a Chinese…
2025-01-23 · simonwillison.net
New release of my [LLM](https://llm.datasette.io/) CLI tool and Python library. A bunch of accumulated fixes and features since the start of December, most notably: - Support for OpenAI's [o1 model](https://platform.openai.com/docs/models#o1) …
2025-01-23 · nytimes.com

The company built a cheaper, competitive chatbot with fewer high-end computer chips than U.S. behemoths like Google and OpenAI, showing the limits of chip export control.
2025-01-20 · simonwillison.net
DeepSeek are the Chinese AI lab who dropped the best currently available open weights LLM on Christmas day, DeepSeek v3. That model was trained in part using their unreleased R1 …
2025-01-18 · sebastianraschka.com
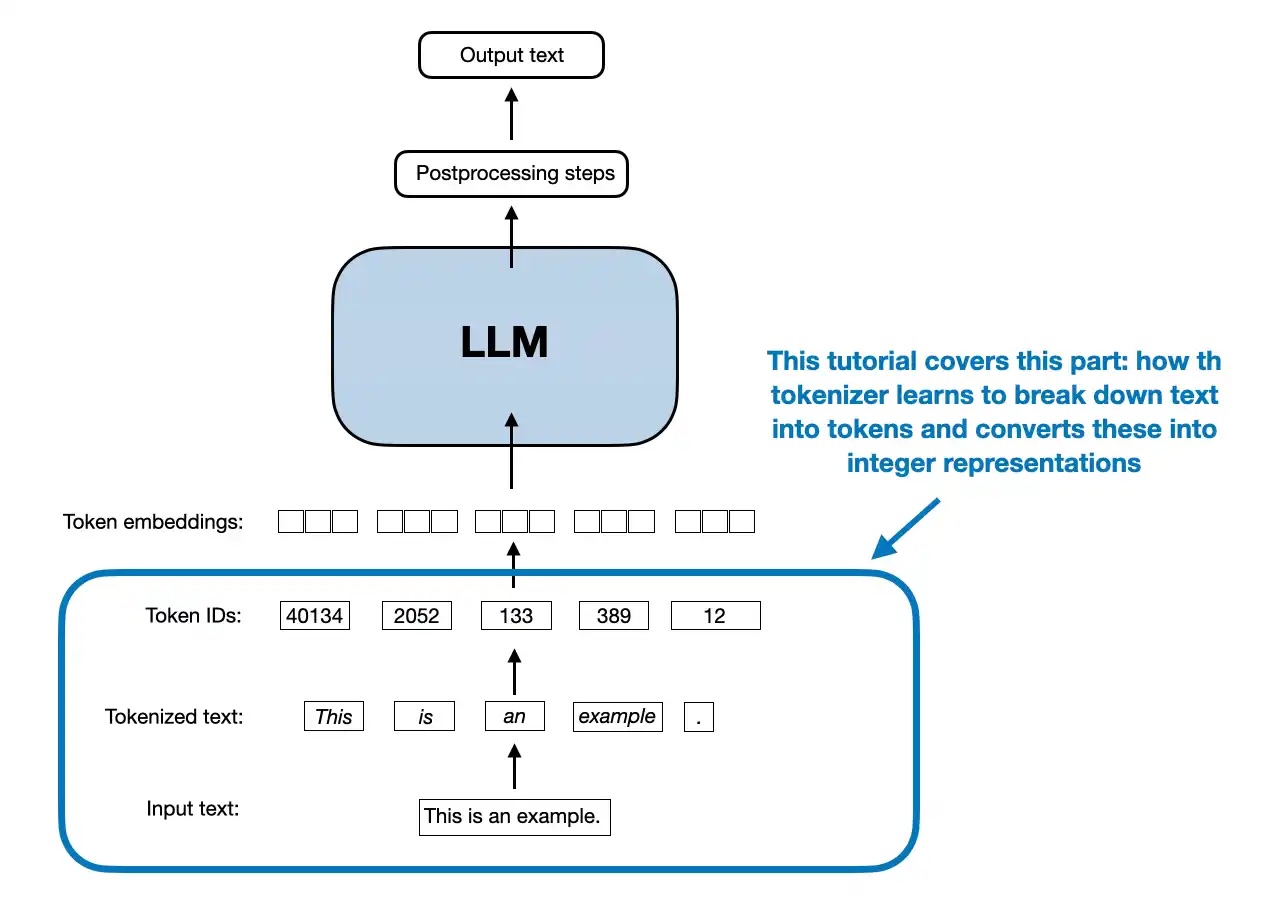
This is a standalone notebook implementing the popular byte pair encoding (BPE) tokenization algorithm, which is used in models like GPT-2 to GPT-4, Llama 3,...
★ 2025-01-14 · latent.space

We picked 50 paper/models/blogs across 10 fields in AI Eng: LLMs, Benchmarks, Prompting, RAG, Agents, CodeGen, Vision, Voice, Diffusion, Finetuning. If you're starting from scratch, start here.
Note: gist: https://gist.github.com/bjpcjp/117ecf144c062c3c933f2690e7ece5c2
2025-01-12 · open.substack.com
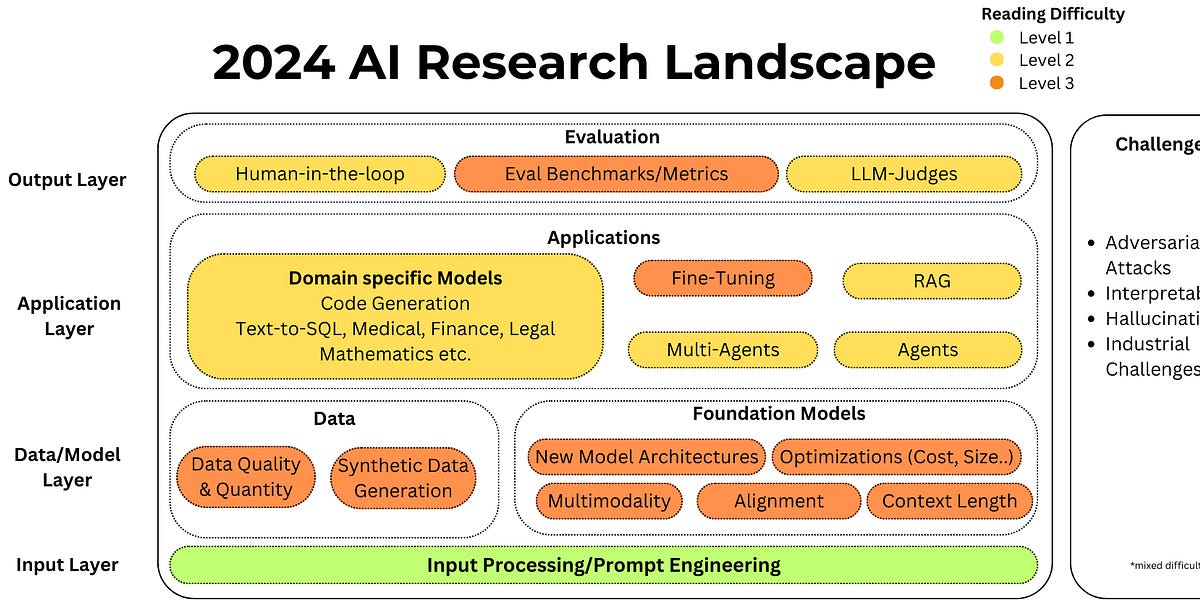
A comprehensive list of some of the most impactful generative papers from last year
2025-01-07 · apolloresearch.ai

A long reading list of evals papers with recommendations and comments by the evals team.
★ 2024-12-22 · arstechnica.com
Compute costs scale with the square of the input size. That’s not great.
This is probably why Google charges twice as much, per token, for Gemini 1.5 Pro once the context gets longer than 128,000 tokens. Generating token number 128,001 requires comparisons with all 128,000 previous tokens, making it significantly more expensive than producing the first or 10th or 100th…
In a series of papers, Princeton computer scientist Tri Dao and several collaborators have developed FlashAttention, which calculates attention in a way that minimizes the number of these slow memory operations.
2024-12-21 · github.com
Implement a ChatGPT-like LLM in PyTorch from scratch, step by step - rasbt/LLMs-from-scratch
2024-12-21 · marktechpost.com

Large Language Models (LLMs) have become a cornerstone of artificial intelligence, driving advancements in natural language processing and decision-making tasks. However, their extensive power demands, resulting from high computational overhead and frequent external memory…
2024-12-12 · towardsdatascience.com
Speed up your LLM inference
★ 2024-12-12 · semianalysis.com

There has been an increasing amount of fear, uncertainty and doubt (FUD) regarding AI Scaling laws. A cavalcade of part-time AI industry prognosticators have latched on to any bearish narrative the…
Other areas that deliver model improvements with more compute include Synthetic Data Generation, Proximal Policy Optimization (PPO), Functional Verifiers, and other training infrastructure for reasoning
we will outline the old pre-training scaling trend as well as the new scaling trends for post-training and inference time.
2024-12-07 · countless.dev

Compare AI models easily! All providers in one place.
2024-12-05 · towardsdatascience.com
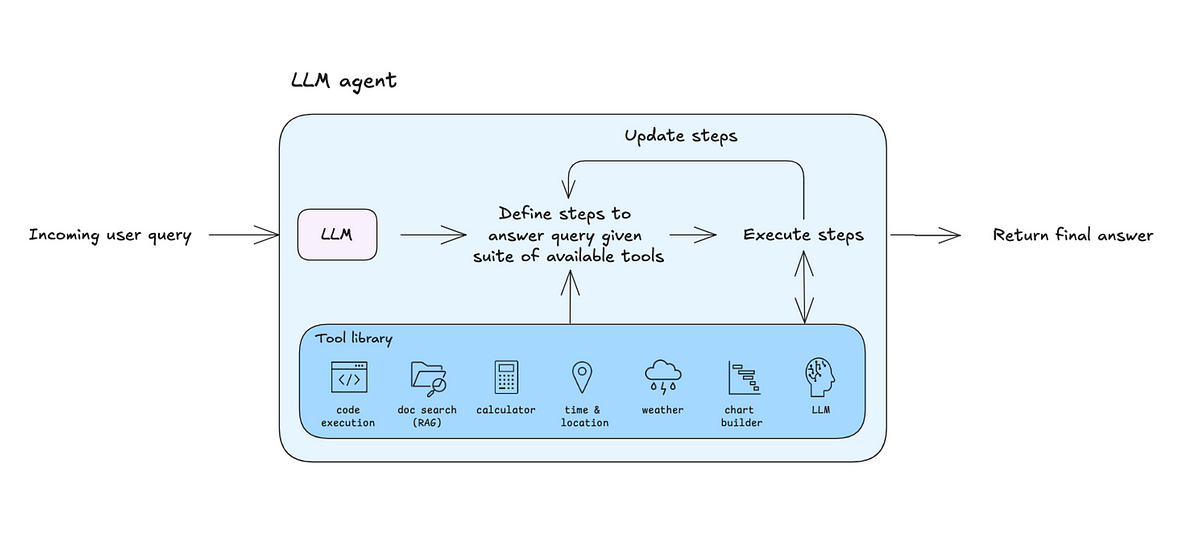
A Step-by-Step Guide
2024-12-05 · aiworld.eu
Navigate Tomorrow's Intelligence Today
2024-11-29 · steelph0enix.github.io
Psst, kid, want some cheap and small LLMs?
2024-11-26 · thenewstack.io
PyTorch has emerged as a top choice for researchers and developers due to its relative ease of use and continuing improvement in performance.
★ 2024-11-26 · github.com

Notes from the Latent Space paper club. Follow along or start your own! - eugeneyan/llm-paper-notes
2024-11-24 · open.substack.com
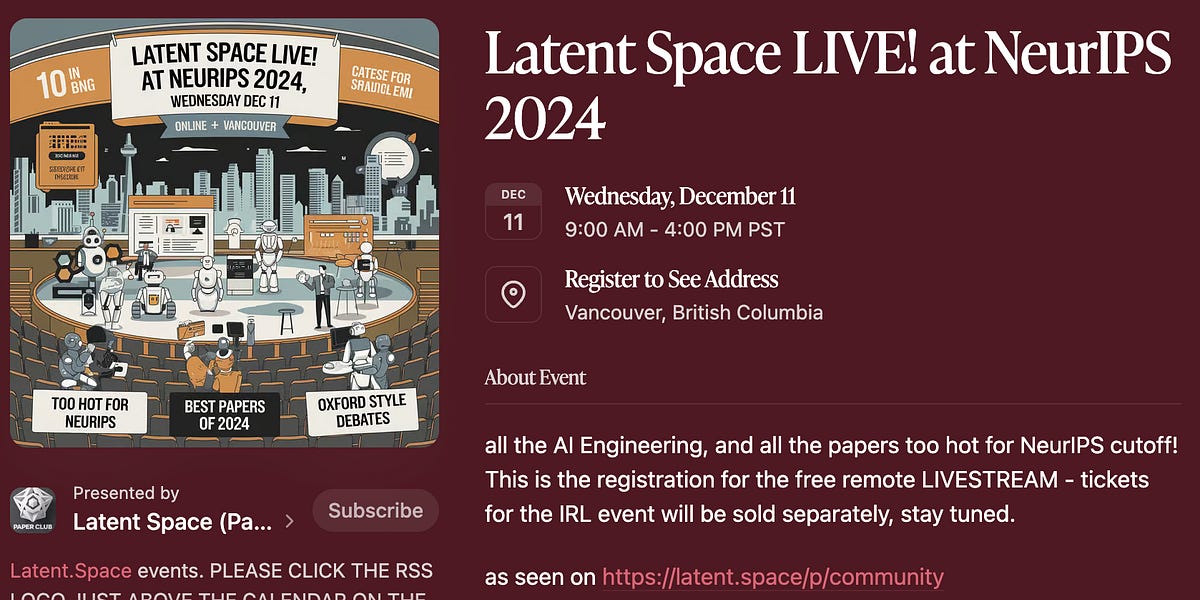
Your ultimate Paper Club Starter Kit, from your friends at the Latent Space Paper Club, where we have now read 100 papers. Also: Announcing Latent Space Paper Club LIVE! at Neurips 2024! Join us!
2024-11-21 · magazine.sebastianraschka.com
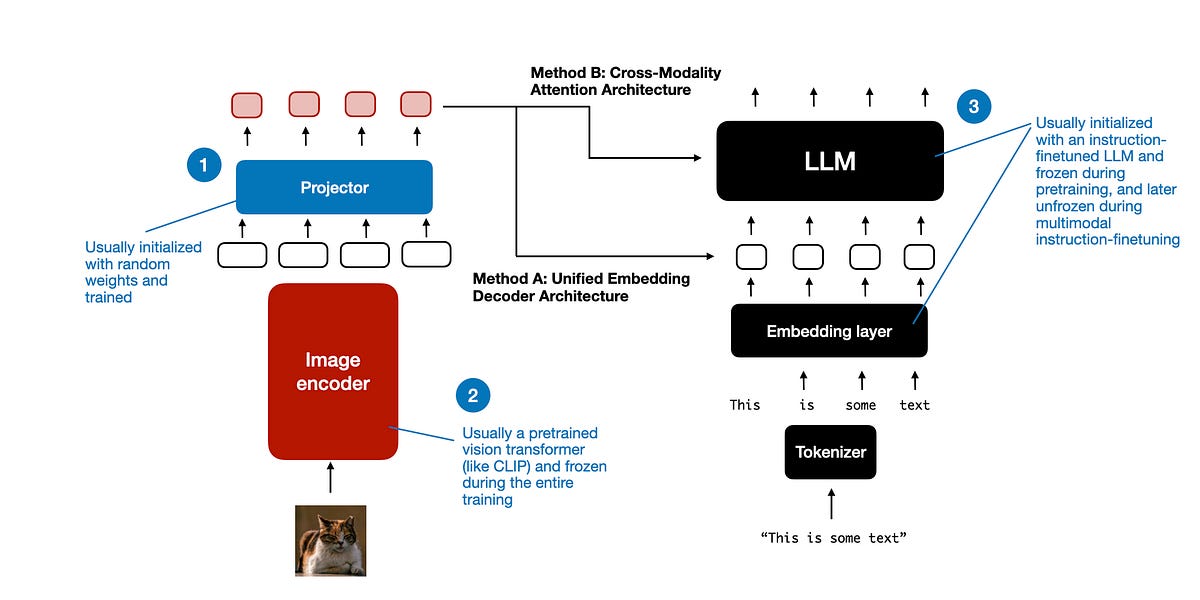
An introduction to the main techniques and latest models
2024-11-17 · open.substack.com
Are they good or bad?
2024-10-17 · venturebeat.com

Nvidia quietly launched a groundbreaking AI model that surpasses OpenAI’s GPT-4 and Anthropic’s Claude 3.5, signaling a major shift in the competitive landscape of artificial intelligence.