Similarity Search, Part 3: Blending Inverted File Index and Product Quantiz
In the first two parts of this series we have discussed two fundamental algorithms in information retrieval: inverted file index and…
In the first two parts of this series we have discussed two fundamental algorithms in information retrieval: inverted file index and…
Hierarchical Navigable Small World graphs (HNSW) is an algorithm that allows for efficient nearest neighbor search, and the Sentence…
Similarity search is a popular problem where given a query Q we need to find the most similar documents to it among all the documents D.
Learn a powerful technique to effectively compress large data
Explore how similarity information can be incorporated into hash function
Understand how to hash data and reflect its similarity by constructing random hyperplanes
Dive into combinations of LSH functions to guarantee a more reliable search
Implementing variational inference from scratch
Understand survival analysis, its use in the industry, and how to apply it in Python
How do hazards and maximum likelihood estimates predict event rankings?
An in-depth exploration of autoencoders and dimensionality reduction
Chapter I. Why you should learn about non-Euclidean ML
How to visualize decision tree models with this useful library
Let’s explore how hierarchical clustering works and how it builds clusters based on pairwise distances.
A guide to understanding support vector machines for classification: from theory to scikit-learn implementation.
Reducing the dimension of a dataset using methods such as PCA
Applying causal machine learning to trim the campaign target audience
Learn what vector search is and the metrics pertinent to decide the distance (or similarity) between objects.
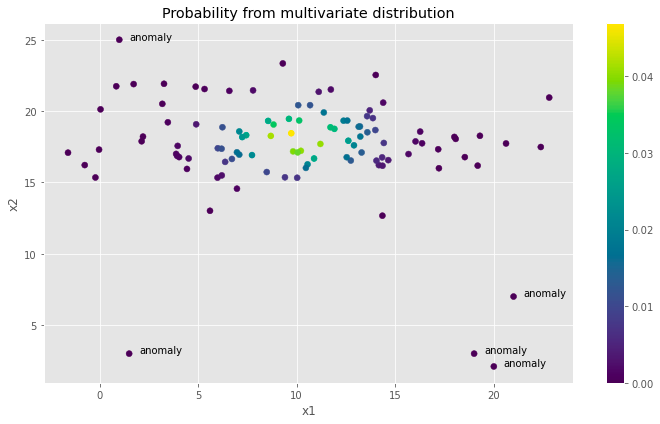
Basics of anomaly detection, its use-cases, and an implementation of simple yet powerful algorithm in Python
To be successful as a Data Scientist, you’re often put in positions where you need to find groups within your data. One key business use-case is finding clusters of customers that behave similarly. And that’s a powerful skill that I’m going to help you...
Spectral clustering is a method of clustering data points based on their similarity or affinity,...
Hardware Development and the Physical Frontier
Master Sklearn pipelines for effortless and efficient machine learning. Discover the art of building, optimizing, and scaling models with ease. Level up your data preprocessing skills and supercharge your ML workflow today
Make stronger and simpler models by leveraging natural order
The Similarity Engine's use cases include item-to-item similarity for text and image modality and user-to-item personalized recommendations based on a user’s historical behavior data.
The most important LightGBM parameters, what they do, and how to tune them
Create insights from frequent patterns using market basket analysis with Python
Recursive queries are a straightforward solution to querying hierarchical trees. However, one loop in the relationship references results in a failing or never ending query when cycle detection is not used.
Dive into an end-to-end demo of a high-performance semantic search engine leveraging GPU acceleration, efficient indexing techniques, and…
These curated papers would step up your machine-learning knowledge.
Exploring the Latest Enhancements and Features of PyCaret 3.0
Understanding the most underrated trick in applied Machine Learning
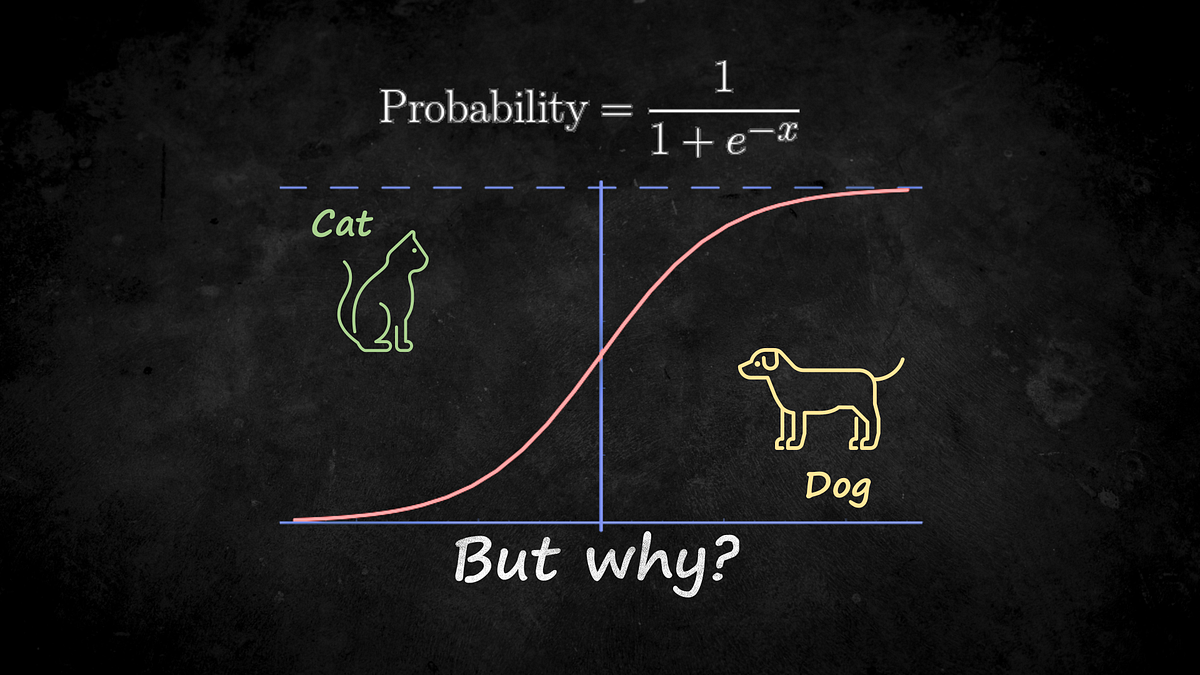
Why do we use the logistic and softmax functions? Thermal physics may have an answer.
Unsupervised learning has always been fascinating to me. It is a way to learn about data without manual labeling effort and allows for the…
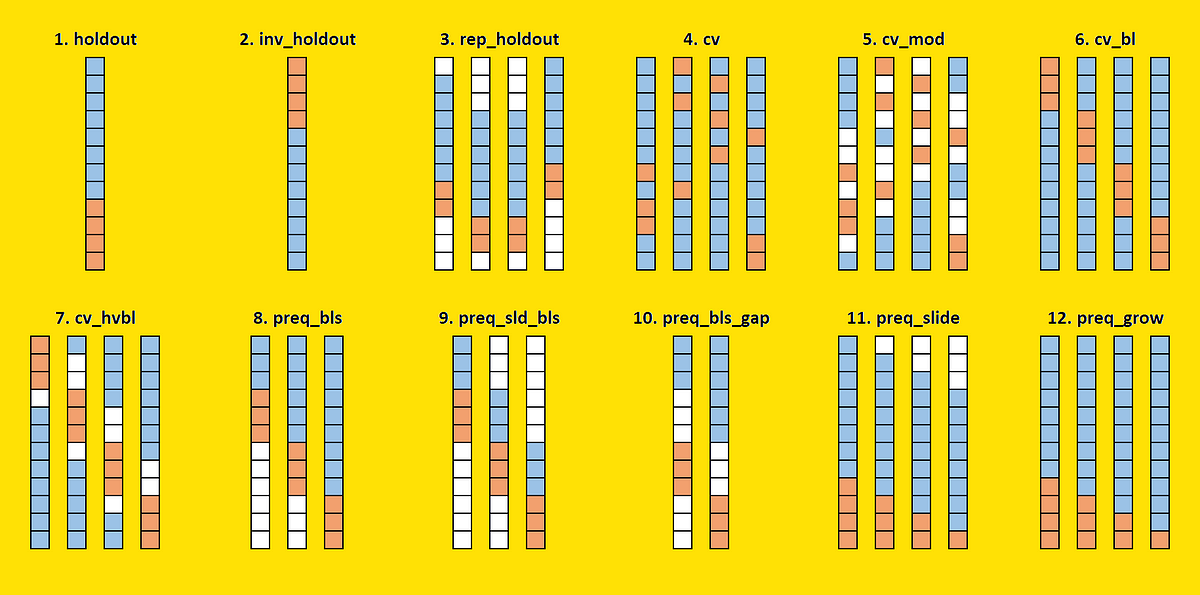
How to find the best performance estimation approach for time-series forecasts among 12 strategies proposed in the literature. With Python…
The Jaccard index, also known as the Jaccard similarity coefficient, is a statistic used for gauging the similarity and diversity of sample sets. It is defined in general taking the ratio of two sizes, the intersection size divided by the union size, also called intersection…
A quick guide on how to make clean-looking, interactive Python plots to validate your data and model
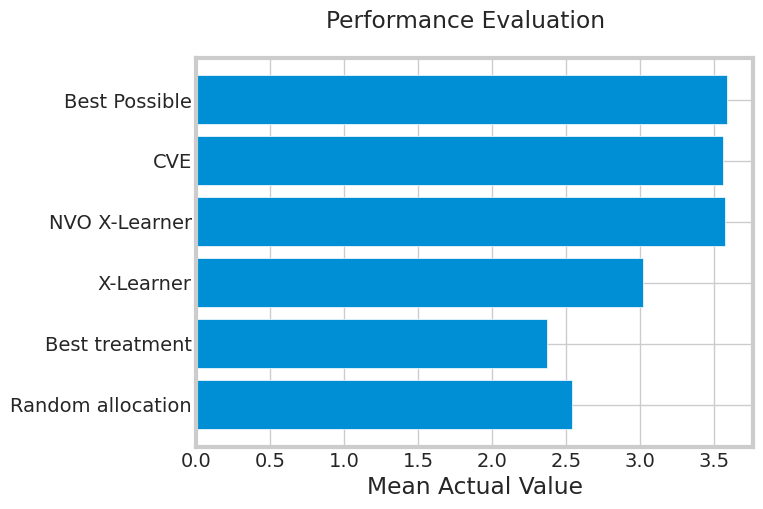
How to adjust CATE to consider costs associated with your treatments
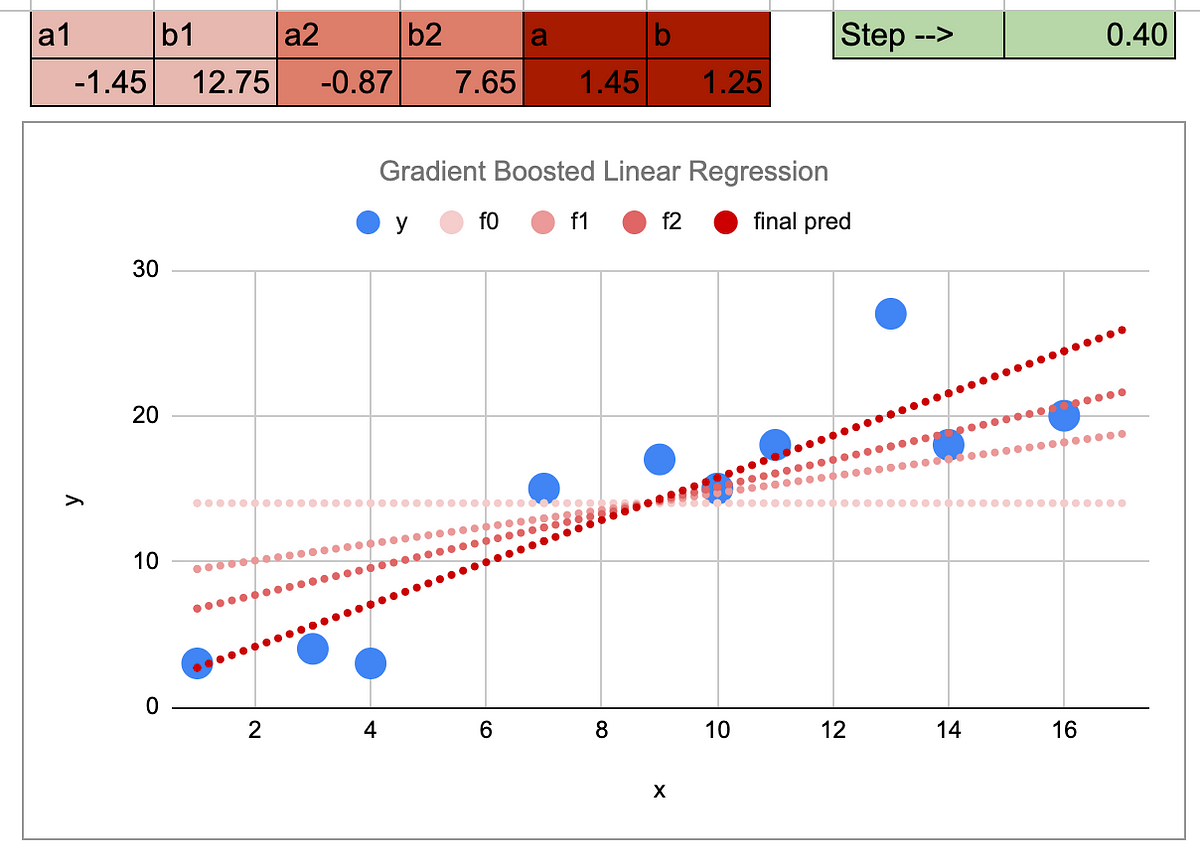
To even better understand Gradient Boosting
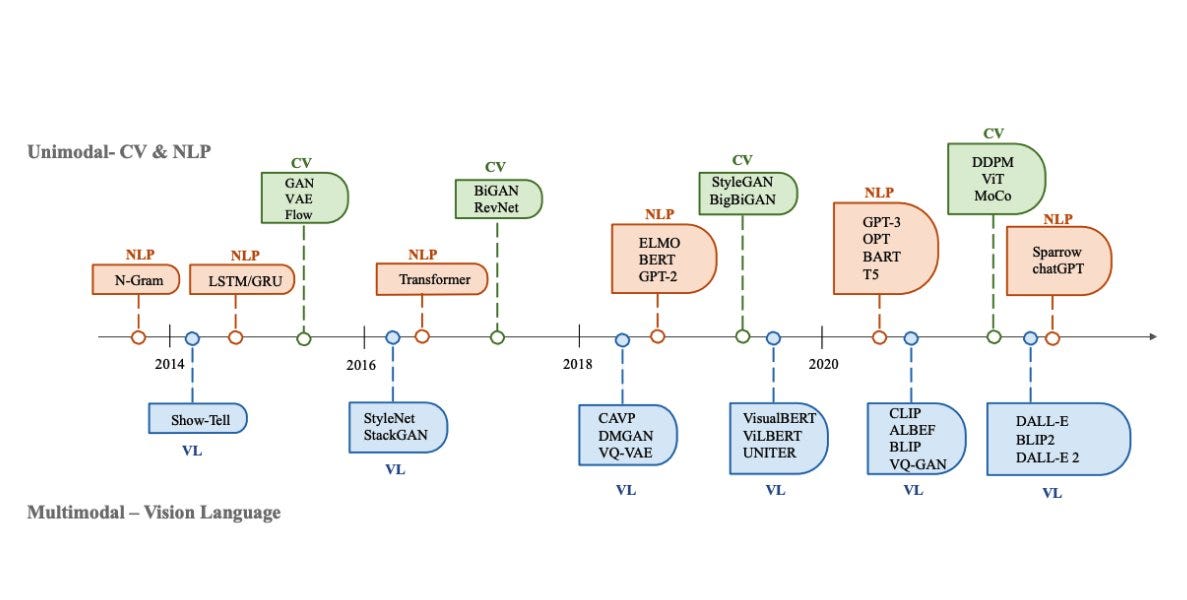
The top ML Papers of the Week (Mar 6 - Mar 12)
Patterns, backed by Y Combinator, is building a platform that allows customers to piece together components to build an AI-powered app.
Use natural language to test the behavior of your ML models
A primer on the math, logic, and pragmatic application of JS Divergence — including how it is best used in drift monitoring
Covers how to choose the similarity measure when item embeddings are available
A gentle dive into this unusual feature selection technique