A Deep Dive into Autoencoders and Their Relationship to PCA and SVD
An in-depth exploration of autoencoders and dimensionality reduction
An in-depth exploration of autoencoders and dimensionality reduction
The fear of being duped is ubiquitous, but excessive scepticism makes it harder to trust one another and cooperate
This version of Rails has been years in the conceptual making. It’s the fulfillment of a vision to present a truly full-stack approach to web development that tackles both the front- and back-end challenges with equal vigor. An omakase menu that includes everything from the…
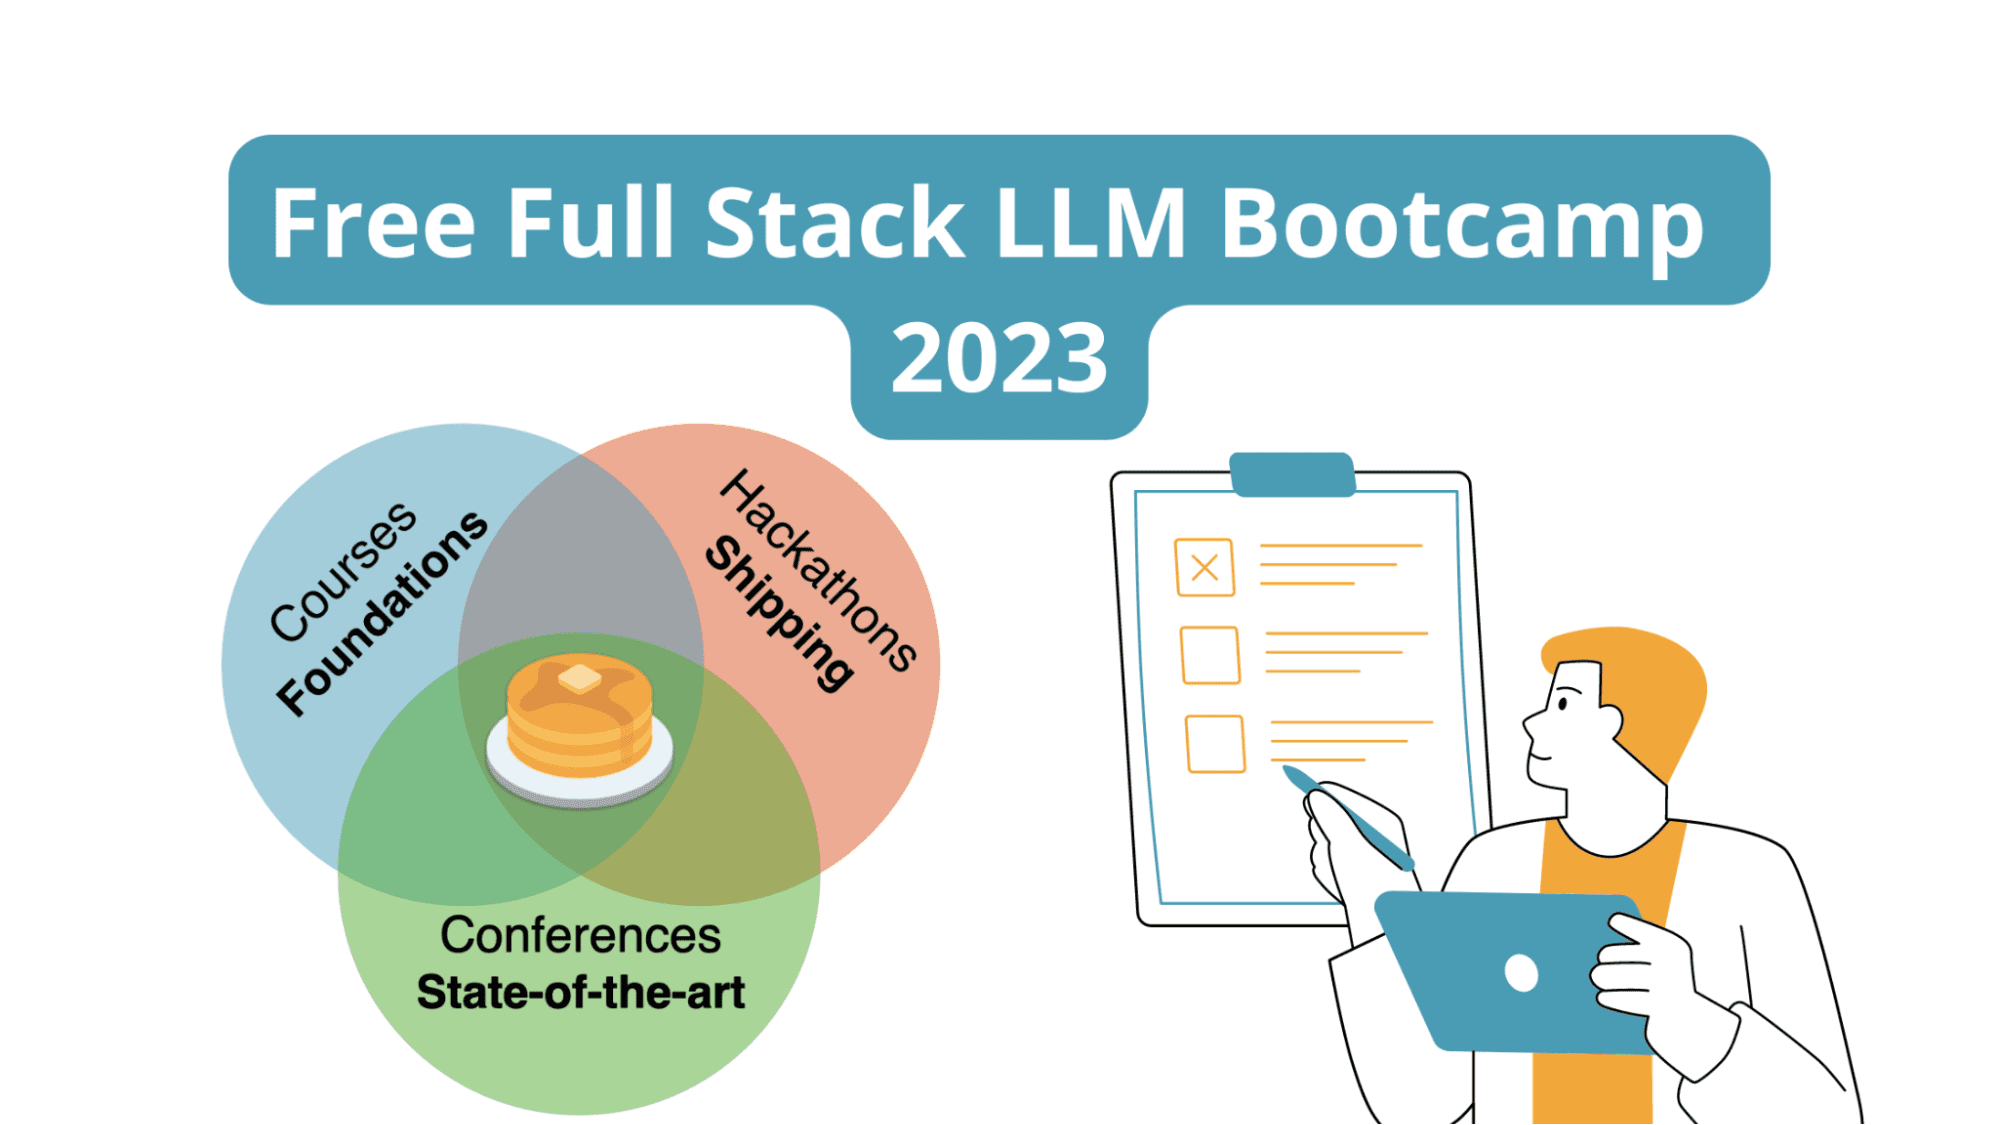
Want to learn more about LLMs and build cool LLM-powered applications? This free Full Stack LLM Bootcamp is all you need!
A one-hit wonder is never enough.
How Arabs, Malabarians and Portuguese shaped the world in search of the 'black gold'
The model quickly top the Open LLM Leaderboard that ranks the performance of open source LLMs.

A spreadsheet on ad platform Xandr’s website revealed a massive collection of “audience segments” used to target consumers based on highly specific, sometimes intimate information and inferences

Social media has a content problem. It's not the content itself, although the list of toxic material is long. The problem is the sheer volume of content. Instead of trusting in self-regulation, the United States could use its regulation of Wall Street after 2008 as a roadmap for…
GPT, explained simply, in a metaphor of potion.

A beginner's guide to understanding autonomous AI agents and their importance.
Chapter I. Why you should learn about non-Euclidean ML

Learn how to check and understand the status of a systemd service using the systemctl command.
tldr; techniques to speed up training and inference of LLMs to use large context window up to 100K input tokens during training and…
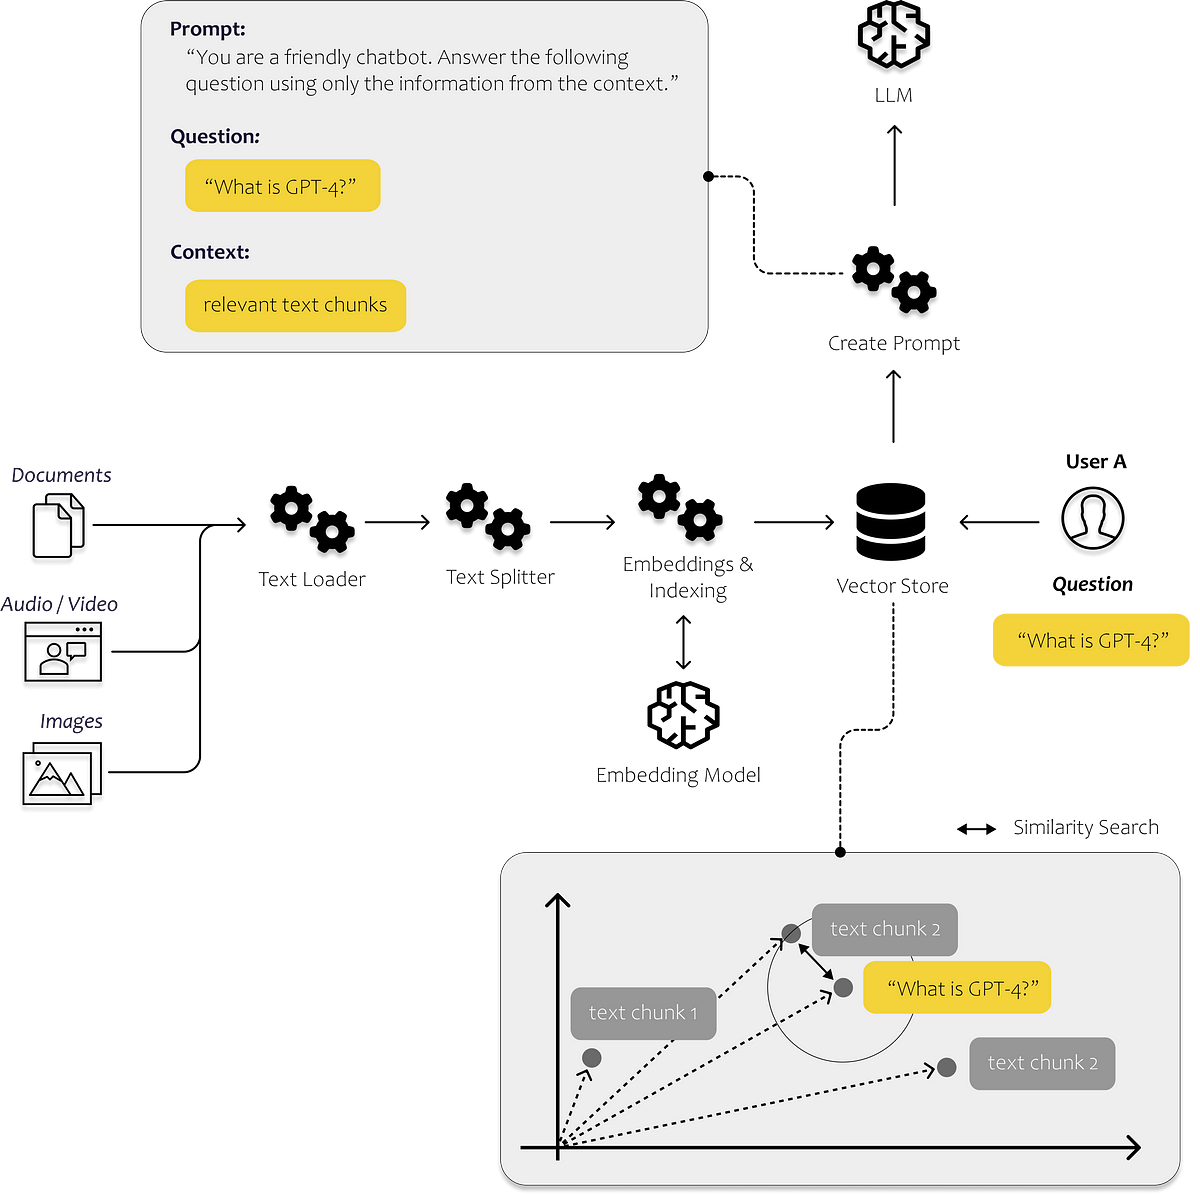
A step-by-step tutorial to document loaders, embeddings, vector stores and prompt templates
How to visualize decision tree models with this useful library

The Observe.AI contact center LLM showed a 35% increase in accuracy compared to GPT-3.5 when automatically summarizing conversations.
Let’s explore how hierarchical clustering works and how it builds clusters based on pairwise distances.
With the release of PyTorch 2.0 and ROCm 5.4, we are excited to announce that LLM training works out of the box on AMD MI250 accelerators with zero code changes and at high performance!

10 ChatGPT Plugins for Data Science Cheat Sheet • Noteable Plugin: The ChatGPT Plugin That Automates Data Analysis • 3 Ways to Access Claude AI for Free • What are Vector Databases and Why Are They Important for LLMs? • A Data Scientist’s Essential Guide to Exploratory Data…
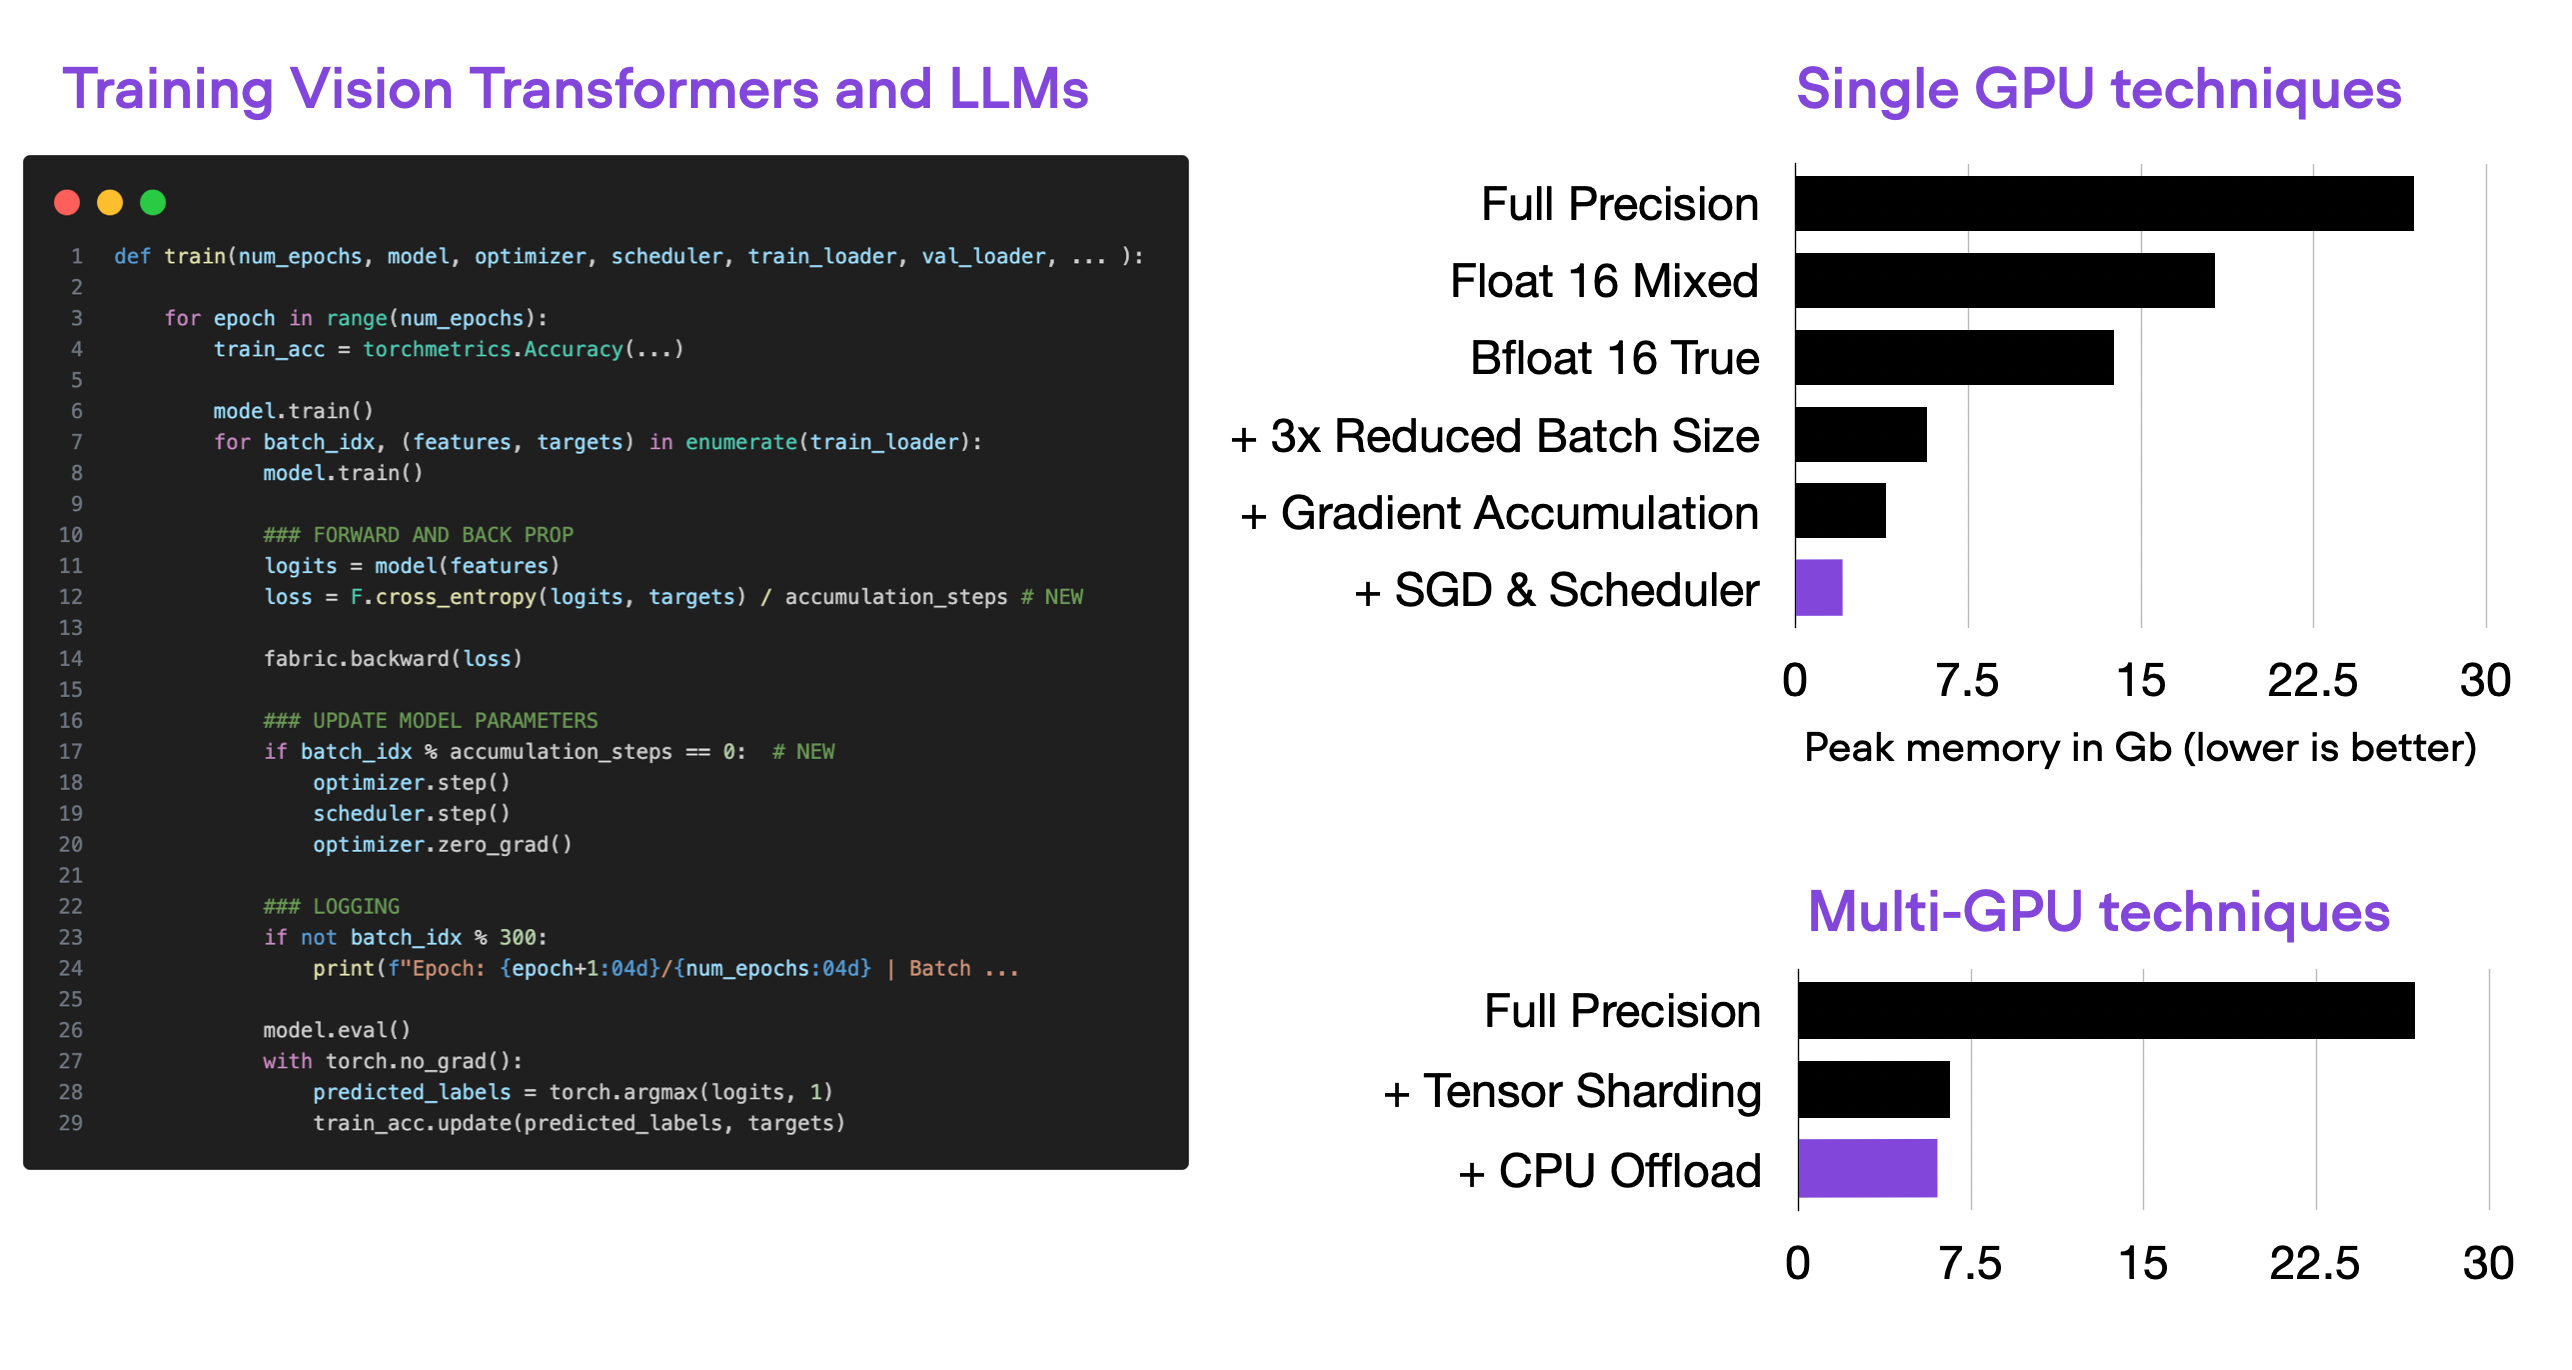
This article provides a series of techniques that can lower memory consumption in PyTorch (when training vision transformers and LLMs) by approximately 20x without sacrificing modeling performance and prediction accuracy.
Thanks to gems, it is easy to implement a search engine into Rails applications. Of course, you have to choose which gem to use. While there are countless options, four stand out as the best. You will be happy with any of these options.
Running Falcon-7B in the cloud as a microservice

Leveraging a company’s proprietary knowledge is critical to its ability to compete and innovate, especially in today’s volatile environment. Organizational innovation is fueled through effective and agile creation, management, application, recombination, and deployment of…
In Linux, there are shell built-in commands which you are already using but never paid attention to. Learn more about them in this tutorial.
Transform your life with these ChatGPT’s hidden gems.
Anthropic, the AI startup founded by ex-OpenAI execs, has released its newest chatbot, Claude 2. It's ostensibly improved in several ways.
A guide to understanding support vector machines for classification: from theory to scikit-learn implementation.
Reducing the dimension of a dataset using methods such as PCA

Google is launching its AI-backed note-taking tool to "a small group of users in the US," the company said in a blog post. Formerly referred to as Project Tailwind at Google I/O earlier this year, the new app is now known as NotebookLM (the LM stands for Language Model). The…
Applying causal machine learning to trim the campaign target audience
In part one of this series on Devise, we'll cover the basics of the Devise gem.
Developed by ETH Zürich, the language explores new paradigms for LLM programming.

Chapter 16, Reusing Previous Computations, is now finished!

Looking at the sample sets of generated images that Meta has shared in its blog post about CM3leon, the results are impressive.
Minimal first-steps instructions to get CUDA running on a standard system.
It crazy how far the ML field has come when it comes to fine-tuning LLMs. A year ago: it was challenging to fine-tune GPT-2 (1.5B) on a single GPU without… | 76 comments on LinkedIn

archived 22 Jul 2023 03:08:13 UTC
A comprehensive guide on how to use Meta's LLaMA 2, the new open-source AI model challenging OpenAI's ChatGPT and Google's Bard.

We learn a lot of lessons from the hyperscalers and HPC centers of the world, and one of them is that those who control their own software control their
Psychologists have been studying a very basic cognitive function that appears to be of increasing importance - how do we choose what to believe as true or false? We live in a world awash in information, and access to essentially the world's store of knowledge is now a trivial…

A simple geometric idea has been used to power advances in information theory, cryptography and even blockchain technology.
How LLaMA is making open-source cool again
Understanding one of the most effective techniques to improve the effectiveness of prompts in LLM applications.