Nano Banana Pro is the best AI image generator, with caveats
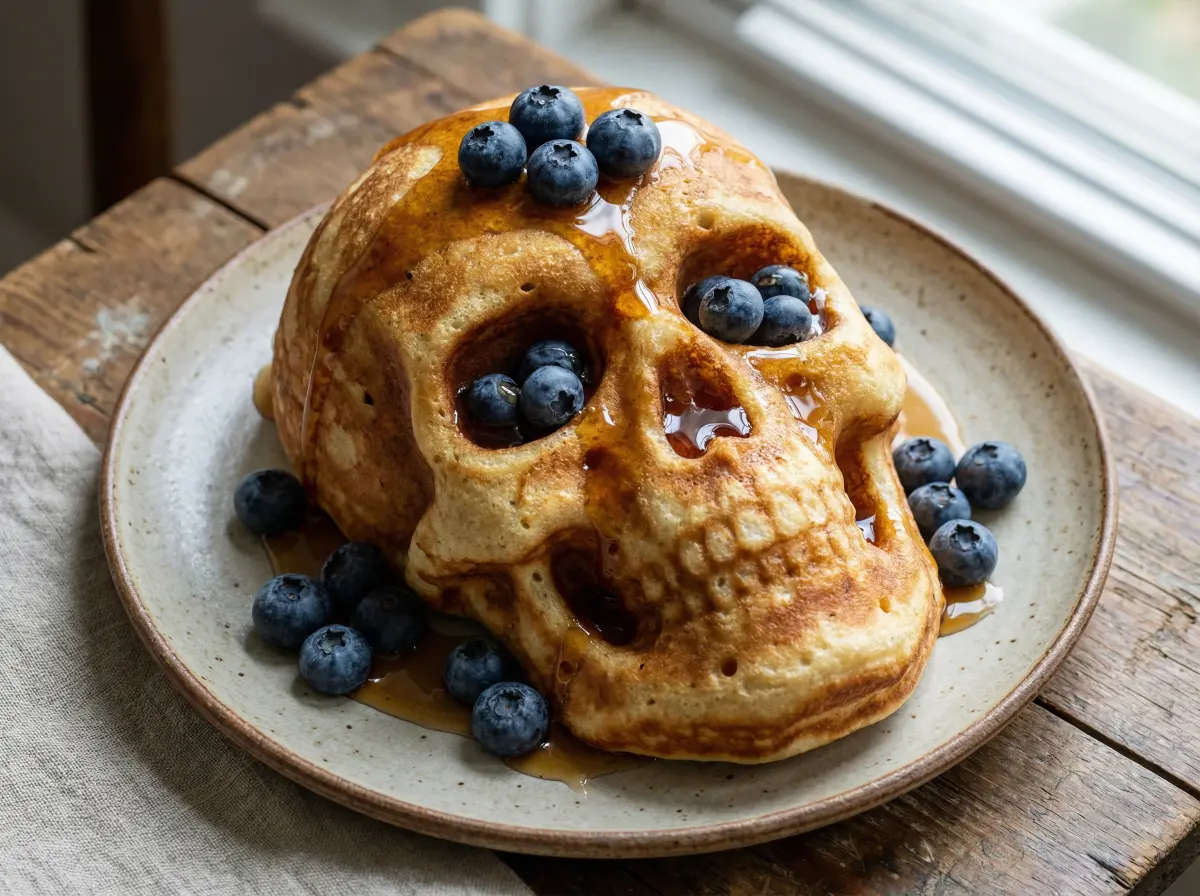
The problem with Nano Banana Pro is that it’s too good.
The problem with Nano Banana Pro is that it’s too good.
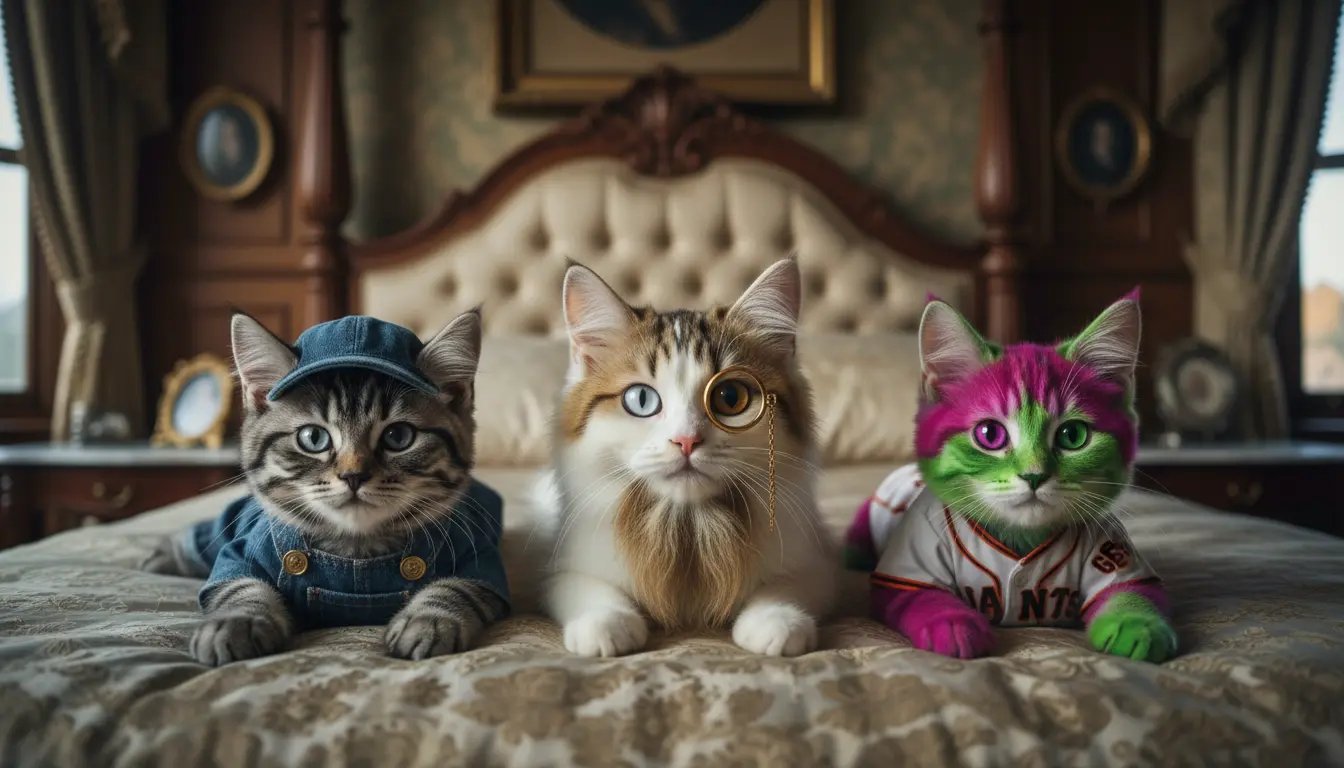
Nano Banana allows 32,768 input tokens and I’m going to try to use them all dammit.

market technique for determining consumer price preferences

We’re releasing a new class of reinforcement learning algorithms, Proximal Policy Optimization (PPO), which perform comparably or better than state-of-the-art approaches while being much simpler to implement and tune. PPO has become the default reinforcement learning algorithm…
Great articles and essays by the world's best journalists and writers.

The brain is much less like a machine than it is like the murmurations of a flock of starlings or an orchestral symphony
In June, I shared a bonus article with my curated and bookmarked research paper lists to the paid subscribers who make this Substack possible.
Co-Packaged Optics (CPO) has long promised to transform datacenter connectivity, but it has taken a long time for the technology to come to market, with tangible deployment-ready products only arriving in 2025.
copper-based scale-up solutions, such as NVLink, provide tremendous bandwidth of 7.2 Tbit/s per GPU – soon to be 14.4 Tbit/s per GPU in the Rubin generation, yet copper-based links are limited in range to two meters
Rubin
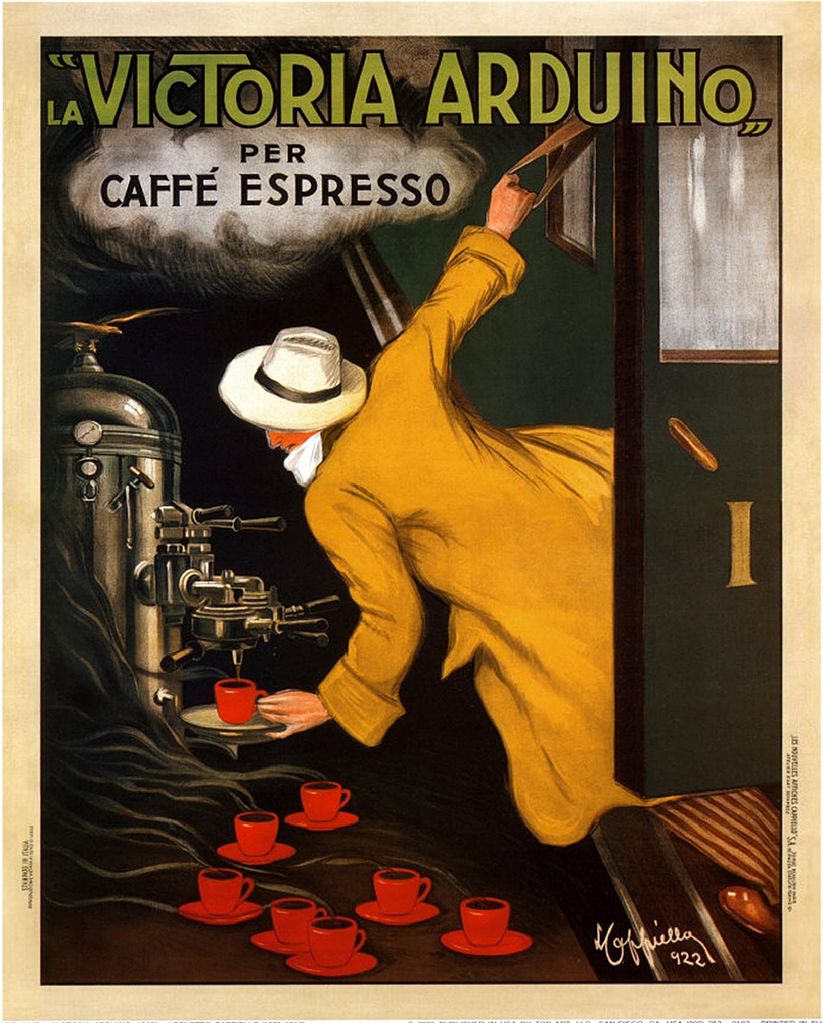
Espresso is neither bean nor roast. It is a method of pressurized coffee brewing that ensures speedy delivery, and it has birthed a whole culture.
I am a huge fan of gistpreview.github.io, the site by Leon Huang that lets you append ?GIST_id to see a browser-rendered version of an HTML page that you have saved …
Any file hosted in a GitHub Gist can be accessed via a direct URL that looks like this
This is my favorite HTTP header! It means I can hit these files with a fetch() call from any domain on the internet, which is fantastic for building HTML tools that do useful things with content hosted in a Gist.
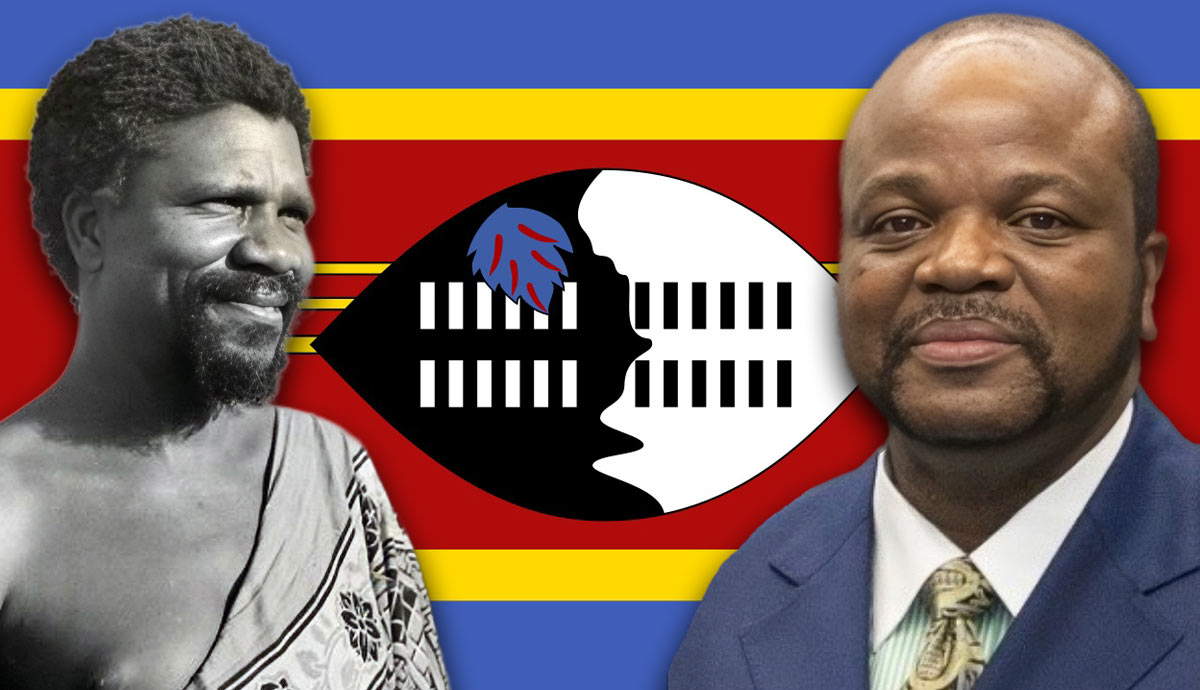
With a history of expansion, struggle, and scandal, Eswatini’s monarchy continues to make headlines.
December 11, 2025 – “I’d been working at Balthazar for a few months when Debra pulled me aside to tell me they knew I’d lied on my resume. Was I fired?”
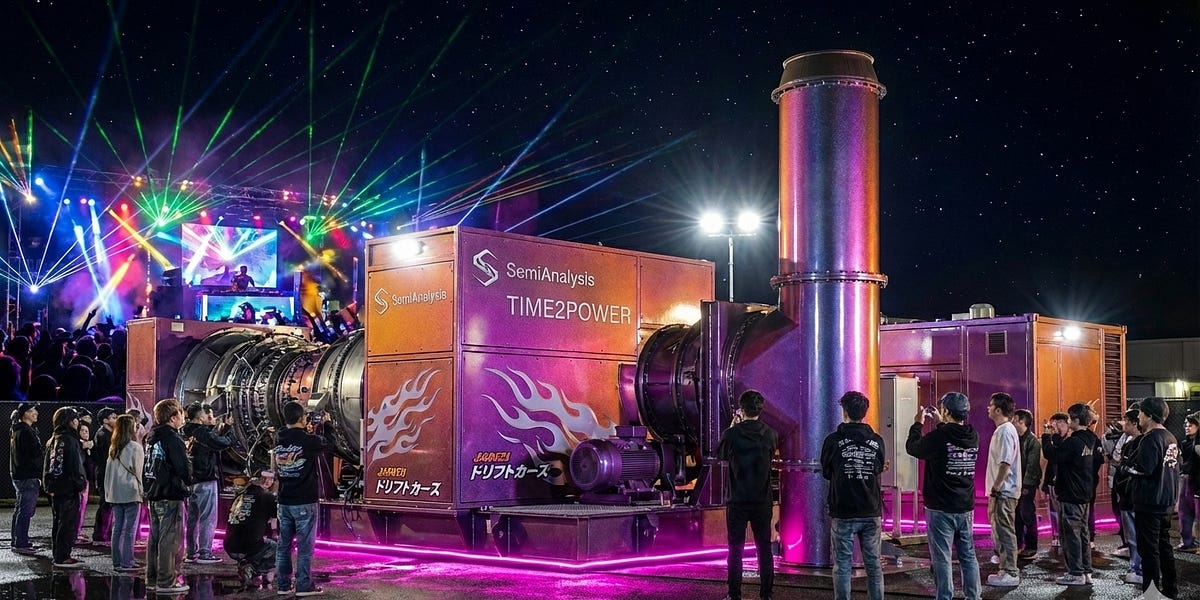
Bring Your Own Generation, Sayonara Electric Grid, Turbines vs. Recips. vs. Fuel Cells, Why Not Build More CCGTs?, Onsite Power TCO
This is the third in my annual series reviewing everything that happened in the LLM space over the past 12 months. For previous years see Stuff we figured out about …
It turned out that the real unlock of reasoning was in driving tools.
notable result is that AI assisted search actually works now.
Posted by alpswd - 620 votes and 361 comments

A firsthand look at winter camping in Quartzsite, Arizona—where nomads find affordable meals, unexpected community, and a place to belong.
Want to level up your data science toolkit? Here are some Python libraries that'll make your work easier.

The discovery could bolster efforts to make the U.S. less dependent on China for minerals essential for renewable power.

Why Silicon Valley's Defense Obsession is Missing the Real Path to American Reindustrialization
Origami is not just a hobby but also a technique that proved itself useful in mathematics, engineering, and medicine. Here are some origami instructions!

A curated list of LLM research papers from July–December 2025, organized by reasoning models, inference-time scaling, architectures, training efficiency, and...
Reasoning
Reinforcement Learning
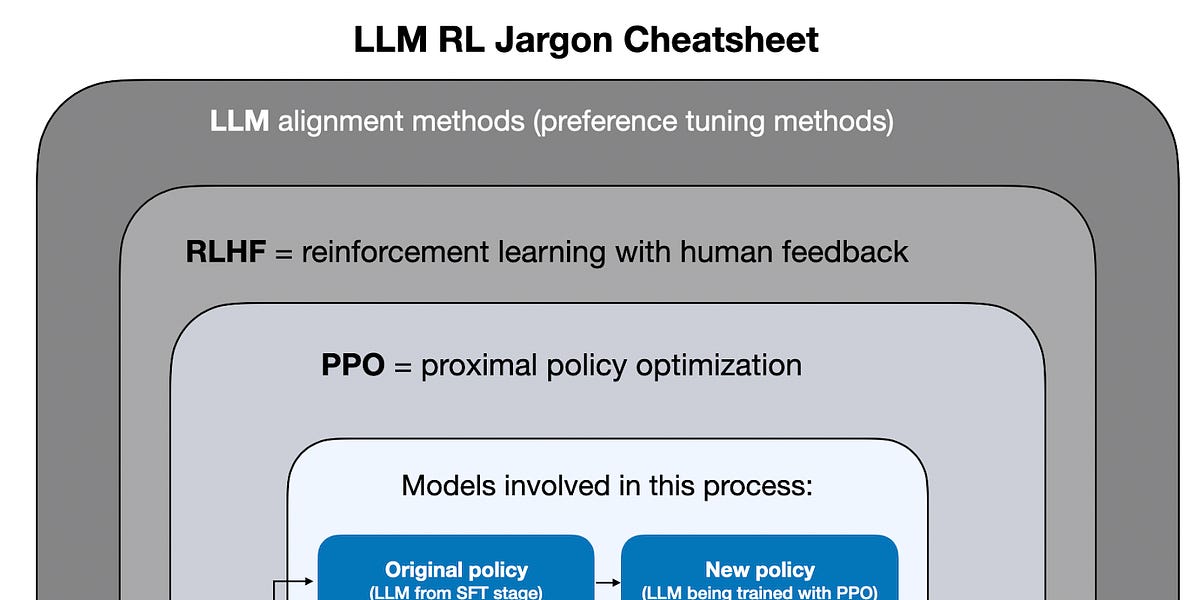
Understanding GRPO and New Insights from Reasoning Model Papers
the muted response to GPT-4.5 and Llama 4 (non-reasoning) models suggests we are approaching the limits of what scaling model size and data alone can achieve.
A 2025 review of large language models, from DeepSeek R1 and RLVR to inference-time scaling, benchmarks, architectures, and predictions for 2026.
DeepSeek released their R1 paper in January 2025, which showed that reasoning-like behavior can be developed with reinforcement learning, it was a really big deal
DeepSeek R1 was released as an open-weight model

Delroy Lindo already deserved an Oscar nomination. He might finally get one for his role as Delta Slim in Ryan Coogler's Sinners.
Reposting my Inkhaven post on ontology of advice here. …

As space rock 2024 YR4 became more likely to hit Earth than anything of its size had ever been before, scientists all over the world mobilized to protect the planet.
Recently, a former patient contacted me about his wife. “She had a recent stroke which has caused cognitive decline along with slow-growing dementia,” he told me via text. “Never, ever had a urinary tract infection in her life, she has now had four in the last three months. We…

A major link in Tesla’s 4680 battery supply chain has just snapped. South Korean battery material supplier L&F Co. announced...
If you can recognize their signature move, then forewarned is forearmed.
How to use finger trees to solve problems by choosing the appropriate monoid measure.

The rise of "zero-click" searches may signal the coming effect of AI shopping on product discovery and decision-making.

A 1983 book inspired a triple murder and led to a major First Amendment case. Its until-now anonymous author is a 77-year-old great-grandmother wrestling with decades of guilt.
Claude API Documentation
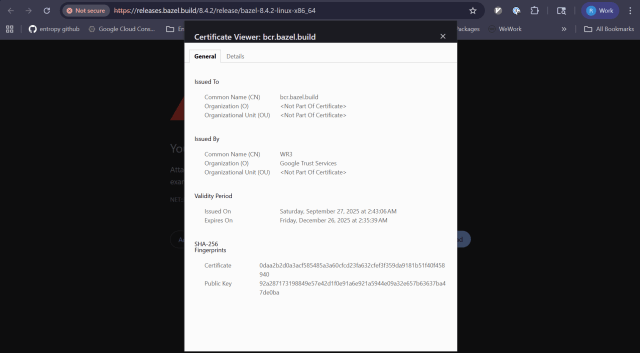
Yesterday, the Bazel team at Google did not have a very Merry Boxing Day. An SSL certificate expired for and as shown in this screenshot from the github issue. This expired certificate apparently b…
Mercury has long baffled astronomers because it defies much of what we know about planet formation. A new space mission arriving in 2026 might solve the mystery.

The worst toy is one with many pieces that my kids dump on the ground and then play with for only 2 minutes.
uv’s speed comes from engineering decisions, not just Rust. Static metadata, dropping legacy formats, and standards that didn’t exist five years ago.
Inside the world of extreme-privacy consultants, who, for the right fee, will make you and your personal information very hard to find
The study guides and glossaries that were most popular in 2025.
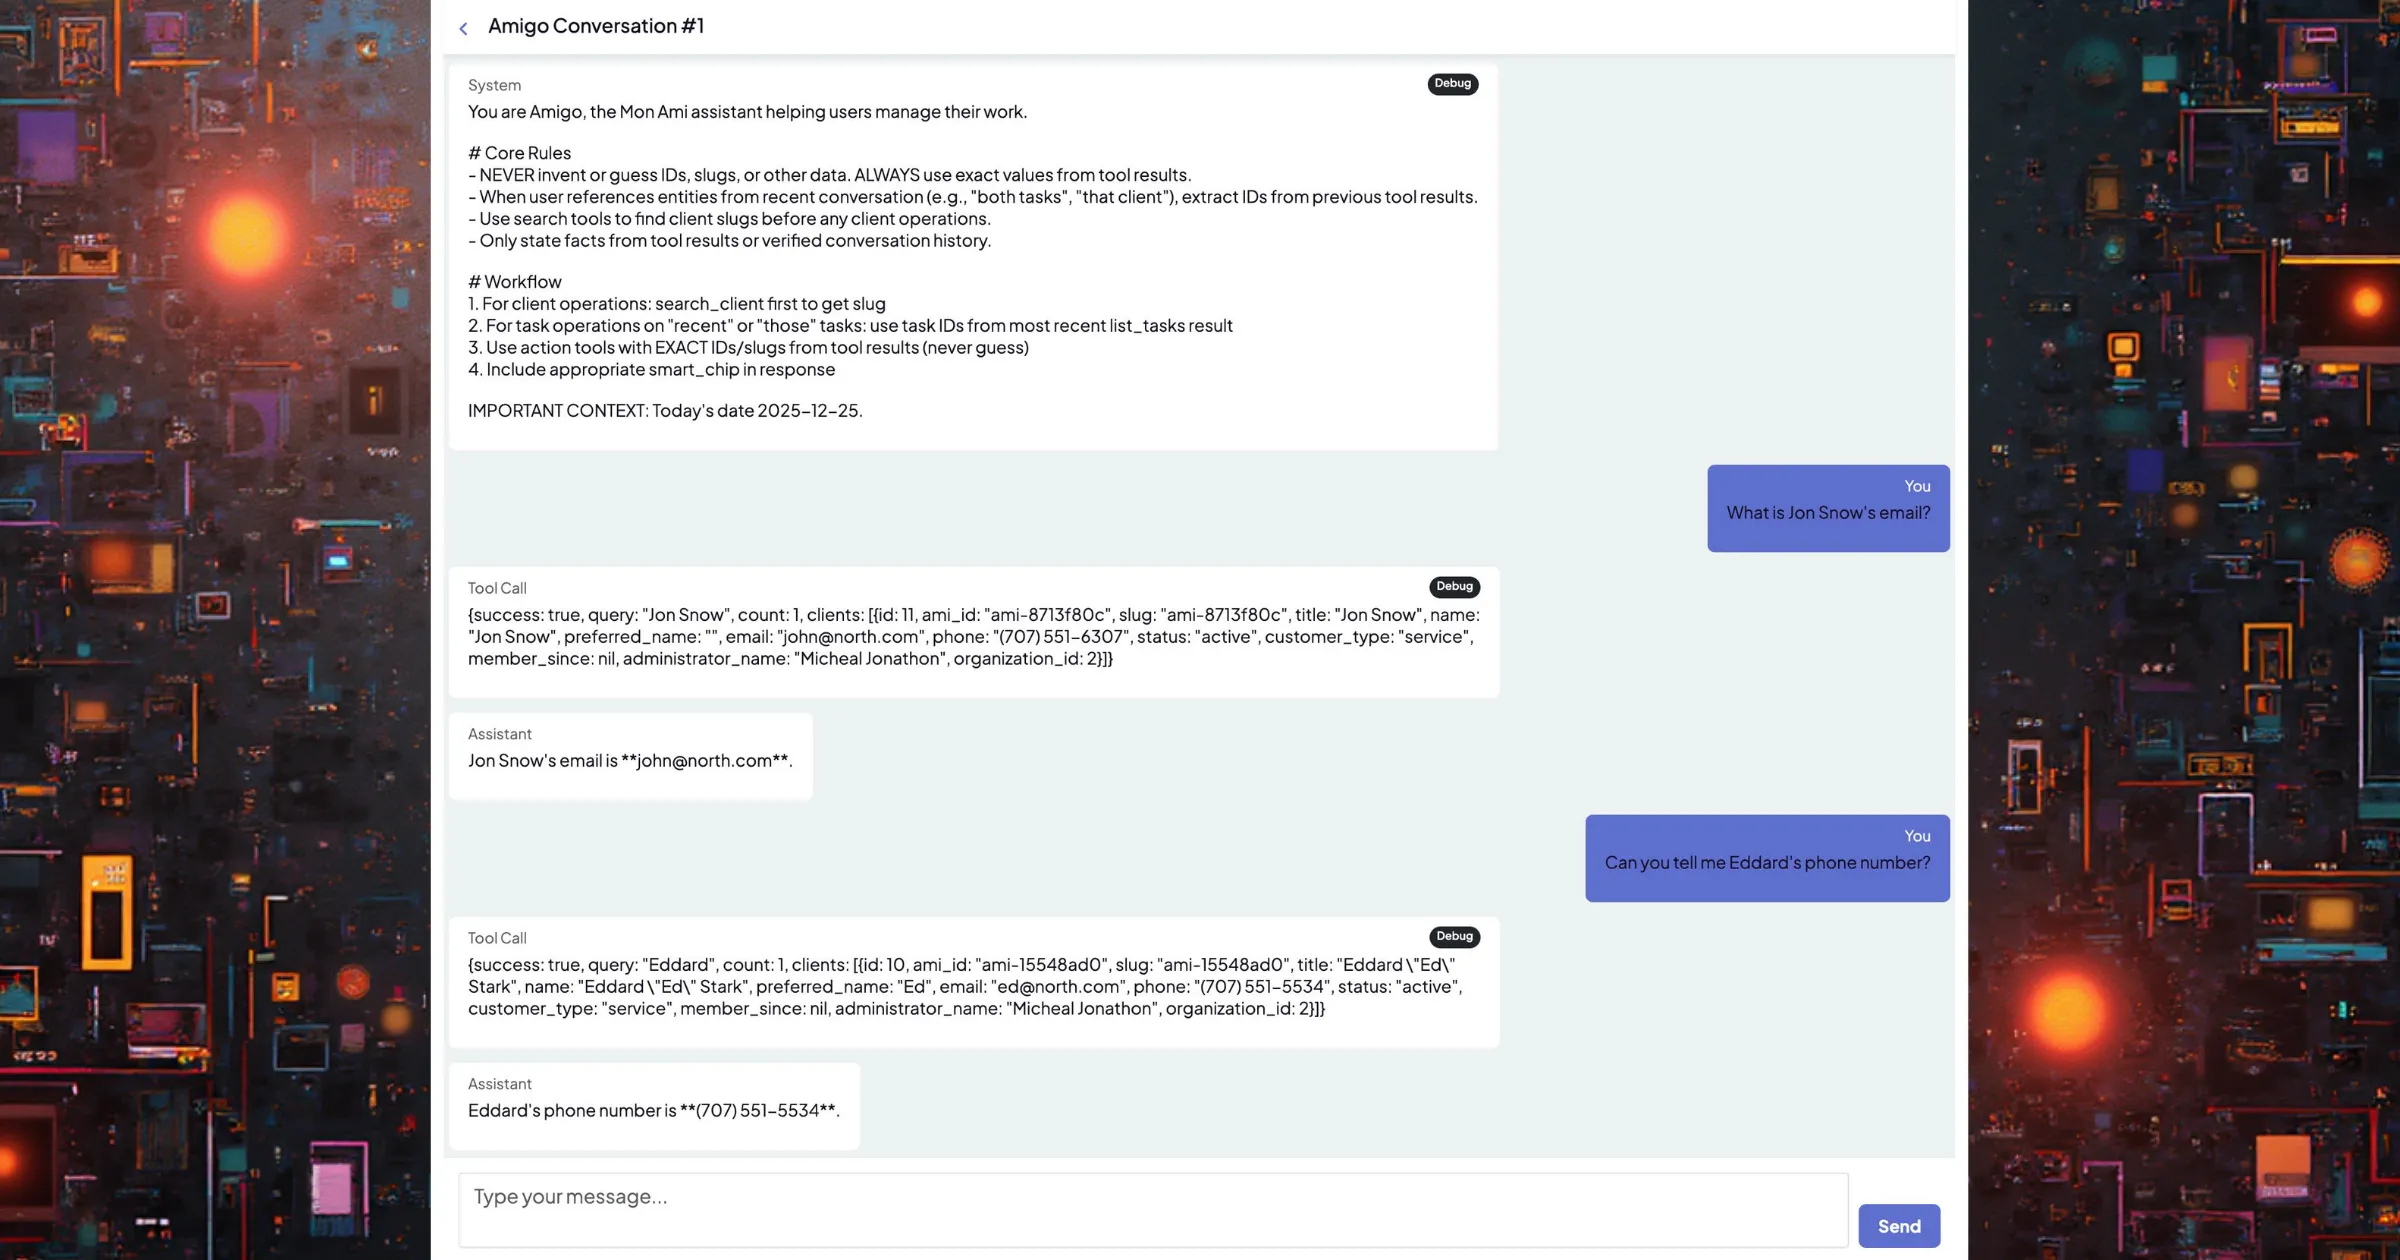
We run a multi-tenant Rails application with sensitive data and layered authorization. In this post, I walk through how I added the first AI agent tool using RubyLLM, Pundit policies, and our existing Algolia search, without introducing a parallel system or loosening constraints.
Von Maur has made a different play than several other retailers. Is it working?
Merry Christmas! Today I turn an earlier LW shortform into a full post and discuss "unknown knowns" "obvious" ideas that are actually hard to discuss…

The word “buttery” in the title refers to croissants, which make an especially rich foundation for this golden-topped baked breakfast classic. Toasting the croissants before building the casserole adds caramelized notes that can stand up to the bits of browned sausage, sage and…
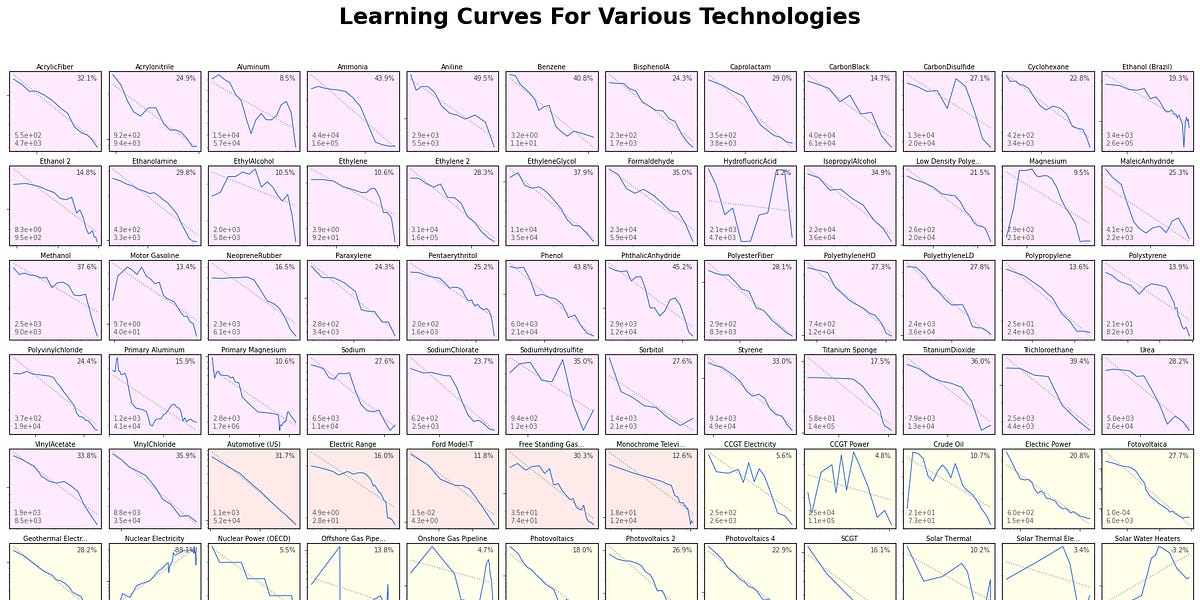
We’ve talked several times on this substack (as well as in my book), about the learning curve, the observation that costs of a produced good tend to fall by some constant proportion for every cumulative doubling of production volume: go from 100 to 200 units, costs might fall by…
Starbucks ascended as a "third space." Maybe it should run like a 3PL.
In this article, I’ll walk you through a complete guide to LangGraph from the ground up. LangGraph Explained from Scratch.
In LangChain, this usually means moving from user input to a prompt, then to the LLM, and finally to the output
ollama pull llama3
Securely store, share, and access your important files and photos. Anytime, anywhere.

Spotify's library was scraped in the name of music preservation, but will this make illegally training AI even easier?