deep-learning
477 bookmarks · page 2 of 10
2023-04-08 · semiengineering.com
A new technical paper titled “TPU v4: An Optically Reconfigurable Supercomputer for Machine Learning with Hardware Support for Embeddings” was published by researchers at Google. Abstract: “In response to innovations in machine learning (ML) models, production workloads changed…
2023-04-07 · ai.facebook.com
2023-04-05 · nextplatform.com
Sponsored Feature: Training an AI model takes an enormous amount of compute capacity coupled with high bandwidth memory. Because the model training can be
2023-03-31 · medium.com

Start with Autoencoders to better understand GANs
2023-03-31 · johanwind.github.io
I explain what is so unique about the RWKV language model.
2023-03-29 · techmeme.com
Mike Wheatley / SiliconANGLE: Cerebras open sources seven GPT-based LLMs, ranging from 111M to 13B parameters and trained using its Andromeda supercomputer for AI, on GitHub and Hugging Face
2023-03-20 · zeta-alpha.com

Who Is publishing the most Impactful AI research right now? With the breakneck pace of innovation in AI, it is crucial to pick up some signal as soon as possible. No one has the time to read everything, but these 100 papers are sure to bend the road as to where our AI technology…
2023-03-15 · cocktailpeanut.github.io
Dead simple way to run LLaMA on your computer
2023-03-15 · semiengineering.com
A list of artificial intelligence used in semiconductor manufacturing tools from February 2023.
2023-03-05 · semiengineering.com
A new technical paper titled “APOSTLE: Asynchronously Parallel Optimization for Sizing Analog Transistors Using DNN Learning” was published by researchers at UT Austin and Analog Devices. Abstract “Analog circuit sizing is a high-cost process in terms of the manual effort…
2023-02-25 · arstechnica.com
LLaMA-13B reportedly outperforms ChatGPT-like tech despite being 10x smaller.
2023-02-09 · ai.googleblog.com
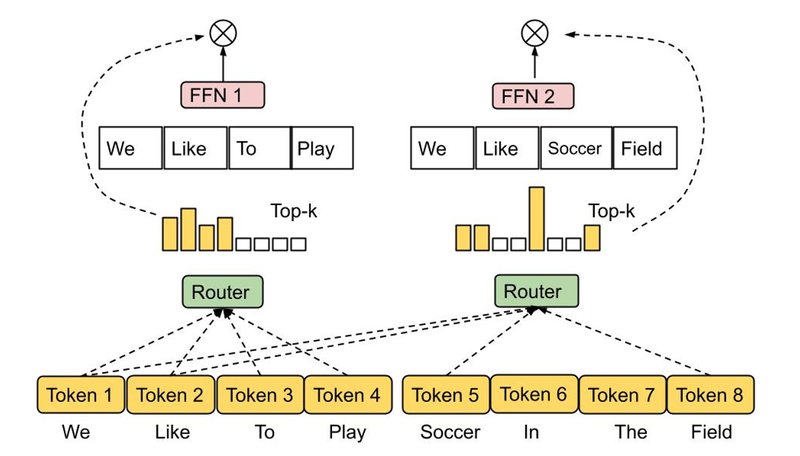
Posted by Sanjiv Kumar, VP and Google Fellow, Google Research (This is Part 4 in our series of posts covering different topical areas of research a...
2023-02-07 · lilianweng.github.io
Many new Transformer architecture improvements have been proposed since my last post on “The Transformer Family” about three years ago. Here I did a big refactoring and enrichment of that 2020 post — restructure the hierarchy of sections and improve many sections with more…
2023-02-03 · towardsdatascience.com

A critical analysis of Google’s impressive new text-to-image generation tool
2023-02-03 · vice.com

The regurgitation of training data exposes image diffusion models to a number of privacy and copyright risks.
2023-01-29 · marginalrevolution.com

Find it here, via Ryan Watkins. Further improvement is required, but the pace of current breakthroughs is remarkable.
2023-01-24 · arxiv.org

During the last two years there has been a plethora of large generative models such as ChatGPT or Stable Diffusion that have been published. Concretely, these models are able to perform tasks such...
2023-01-20 · timdettmers.com
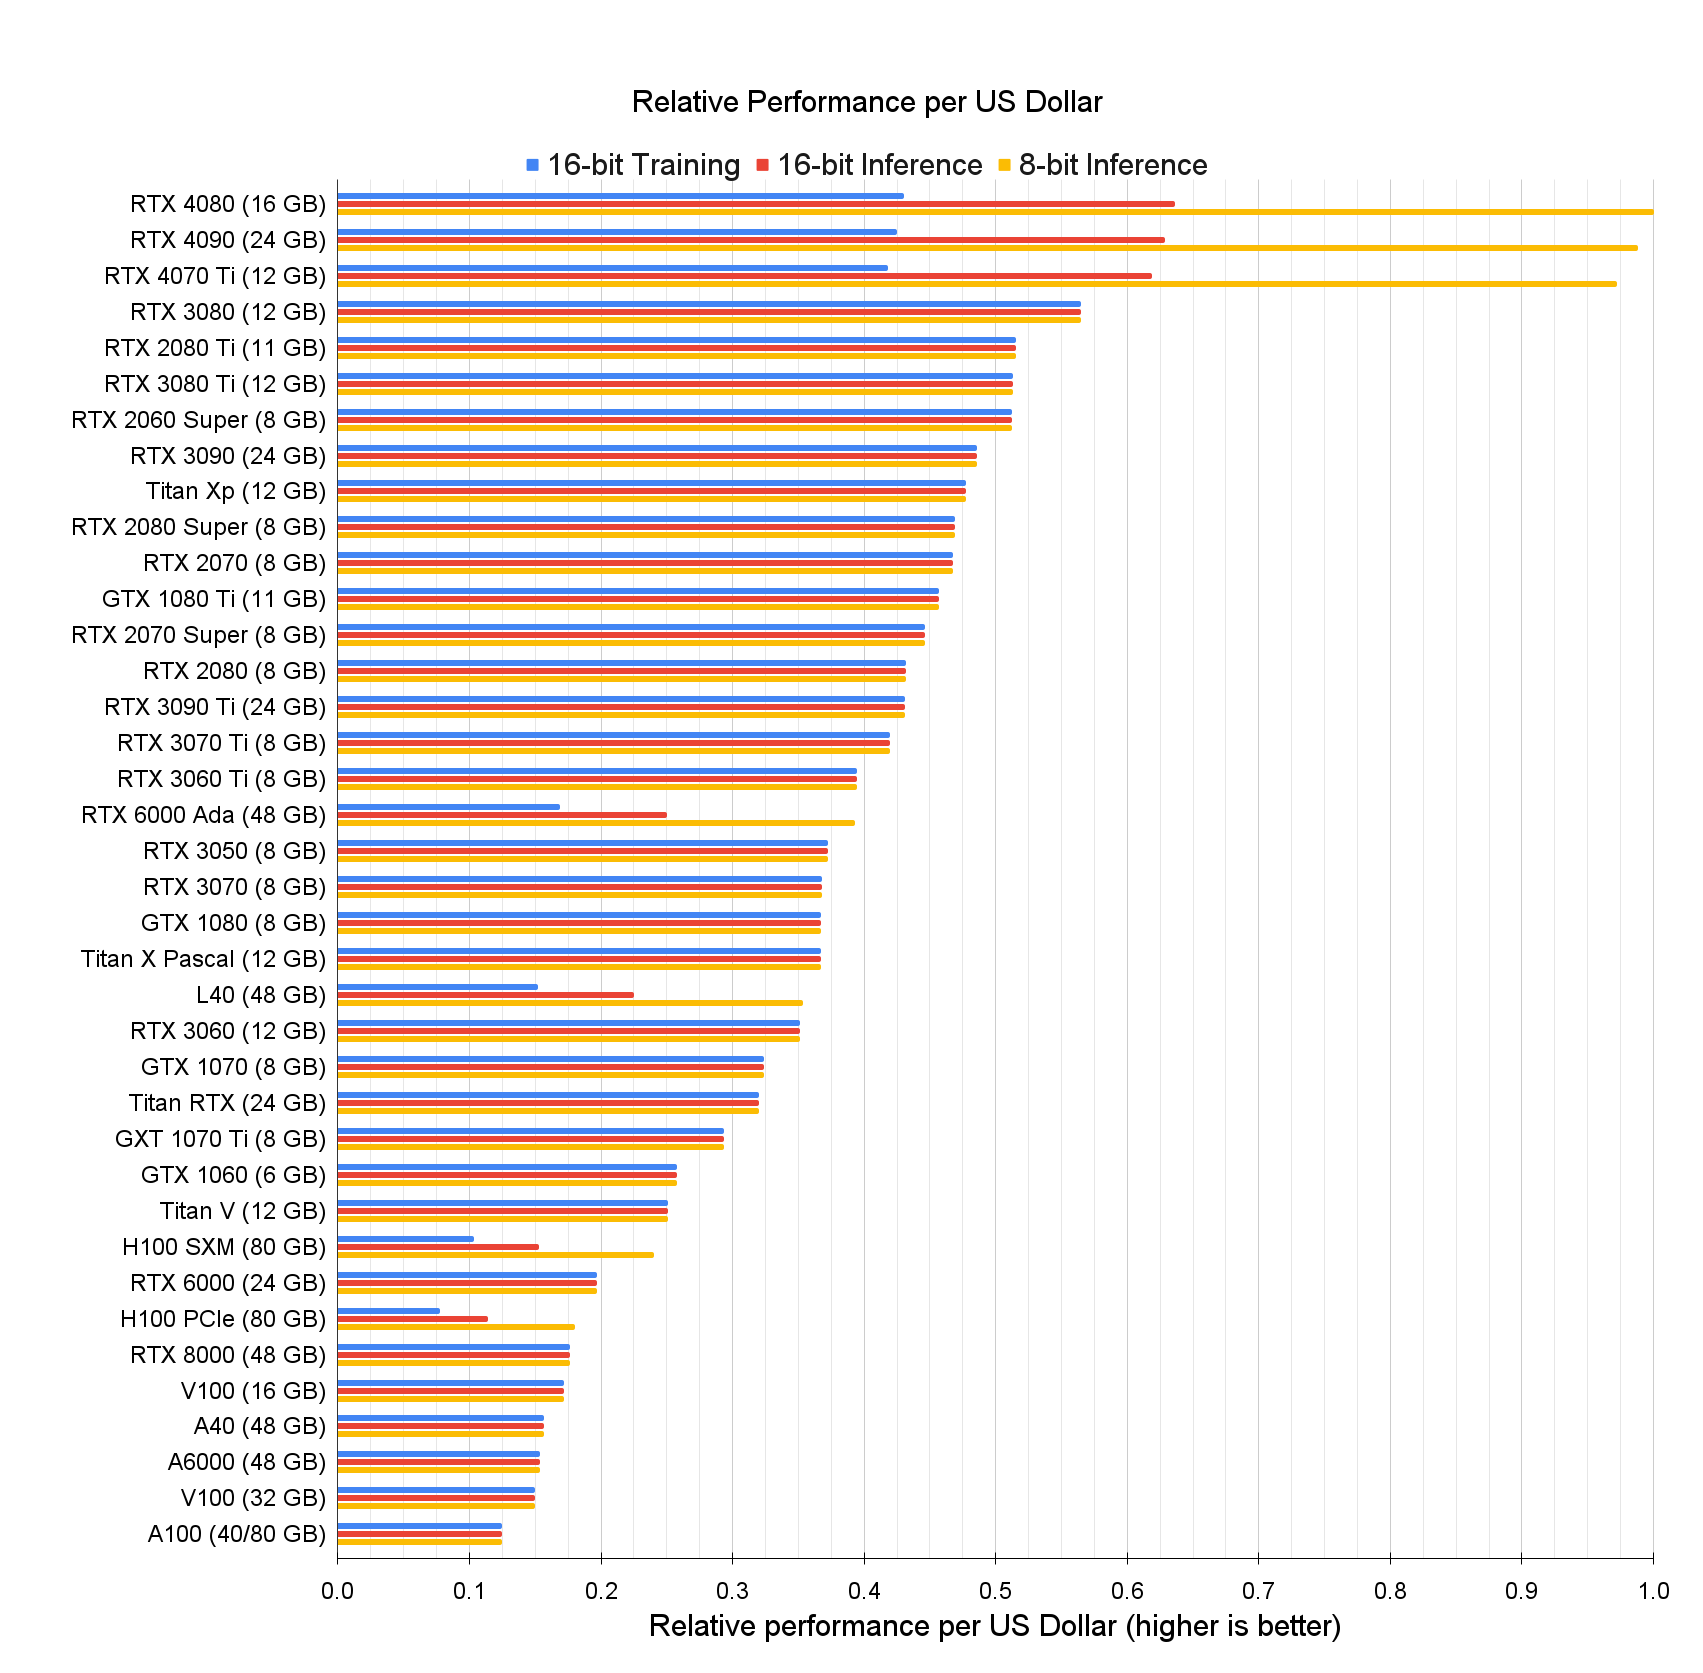
Here, I provide an in-depth analysis of GPUs for deep learning/machine learning and explain what is the best GPU for your use-case and budget.
2023-01-17 · towardsdatascience.com

An example use case of using Variational Autoencoders (VAE) to detect anomalies in all types of data
2023-01-13 · towardsdatascience.com

Wasserstein distance helps WGANs outperform vanilla GANs and VAEs. This post explains why so using some easy math.
2023-01-13 · thenextweb.com
Many developers who use Python for machine learning are now switching to PyTorch. Find out why and what the future could hold for TensorFlow.
2023-01-12 · infoq.com

Geoffrey Hinton, professor at the University of Toronto and engineering fellow at Google Brain, recently published a paper on the Forward-Forward algorithm (FF), a technique for training neural networks that uses two forward passes of data through the network, instead of…
2023-01-05 · quantamagazine.org
Judea Pearl, a pioneering figure in artificial intelligence, argues that AI has been stuck in a decades-long rut. His prescription for progress? Teach machines to understand the question why.
2022-12-18 · github.com

Implementation of Vision Transformer, a simple way to achieve SOTA in vision classification with only a single transformer encoder, in Pytorch - lucidrains/vit-pytorch
2022-12-16 · ben-evans.com

The wave of enthusiasm around generative networks feels like another Imagenet moment - a step change in what ‘AI’ can do that could generalise far beyond the cool demos. What can it create, and where are the humans in the loop?
2022-12-11 · arxiv.org
2022-12-10 · entertainment.slashdot.org

Alphabet's DeepMind has built an AI tool that can help generate rough film and stage scripts Engadget's Kris Holt reports: Dramatron is a so-called "co-writing" tool that can generate character descriptions, plot points, location descriptions and dialogue. The idea is that human…
2022-12-10 · towardsdatascience.com
Adapting federated learning to your own datasets
2022-12-07 · stratechery.com

The first obvious casualty of large language models is homework: the real training for everyone, though, and the best way to leverage AI, will be in verifying and editing information.
2022-12-07 · towardsdatascience.com
An intuitive understanding of how AI-generated art is made by Stable Diffusion, Midjourney, or DALL-E
2022-11-28 · towardsdatascience.com
Everything you need to know to use YOLOv7 in custom training scripts
2022-11-28 · towardsdatascience.com

Introduction to reinforcement learning terminologies, basics, and concepts (model-free, model-based, online, offline RL)
2022-11-15 · tomshardware.com
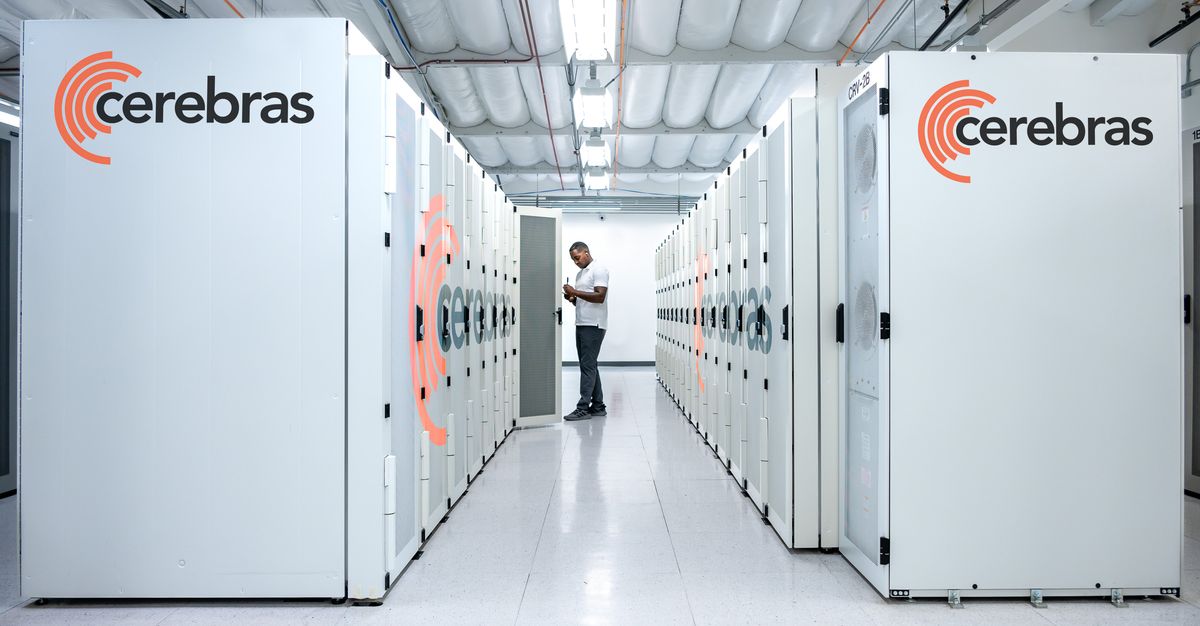
The world's largest chip scales to new heights.
2022-10-17 · undark.org
Scientist Gary Marcus argues that “deep learning” is not the only path to true artificial intelligence.
2022-10-14 · github.com

Pure python implementation of product quantization for nearest neighbor search - matsui528/nanopq
2022-10-14 · towardsdatascience.com

The best indexing approach for billion-sized vector datasets
2022-10-14 · towardsdatascience.com
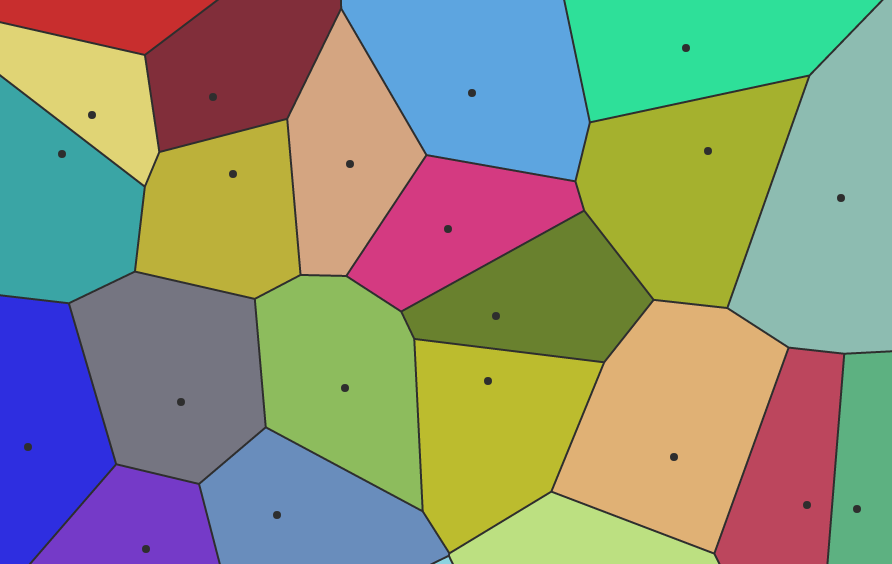
Find out how the inverted file index (IVF) is implemented alongside product quantization (PQ) for a fast and efficient approximate nearest…
2022-10-13 · towardsdatascience.com

Efficient vector quantization for machine learning optimizations (eps. vector quantized variational autoencoders), better than straight…
2022-10-08 · fastcompany.com
If you thought text-to-image AI was unbelievable, wait until you see how it compresses images.
2022-09-20 · towardsdatascience.com
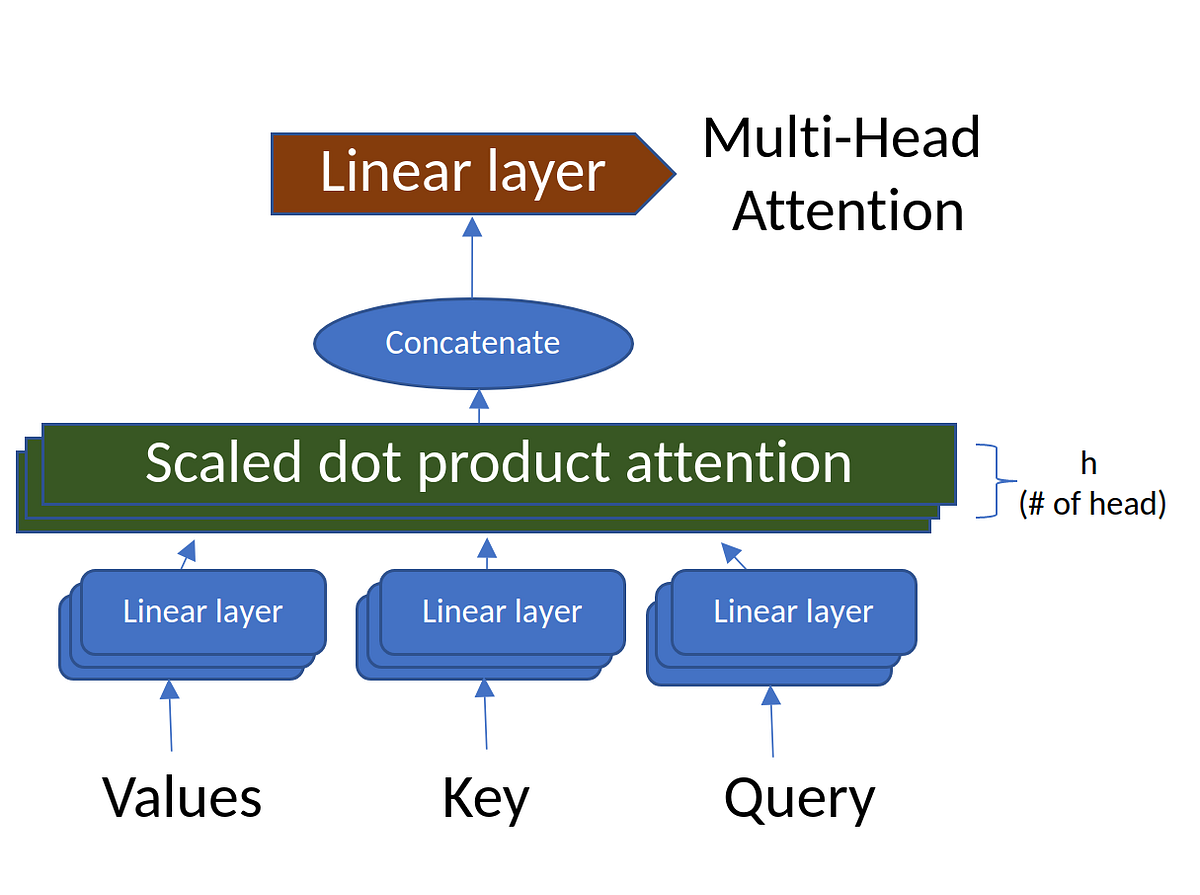
Attention, Self-Attention, Multi-head Attention, Masked Multi-head Attention, Transformers, BERT, and GPT
2022-09-20 · towardsdatascience.com
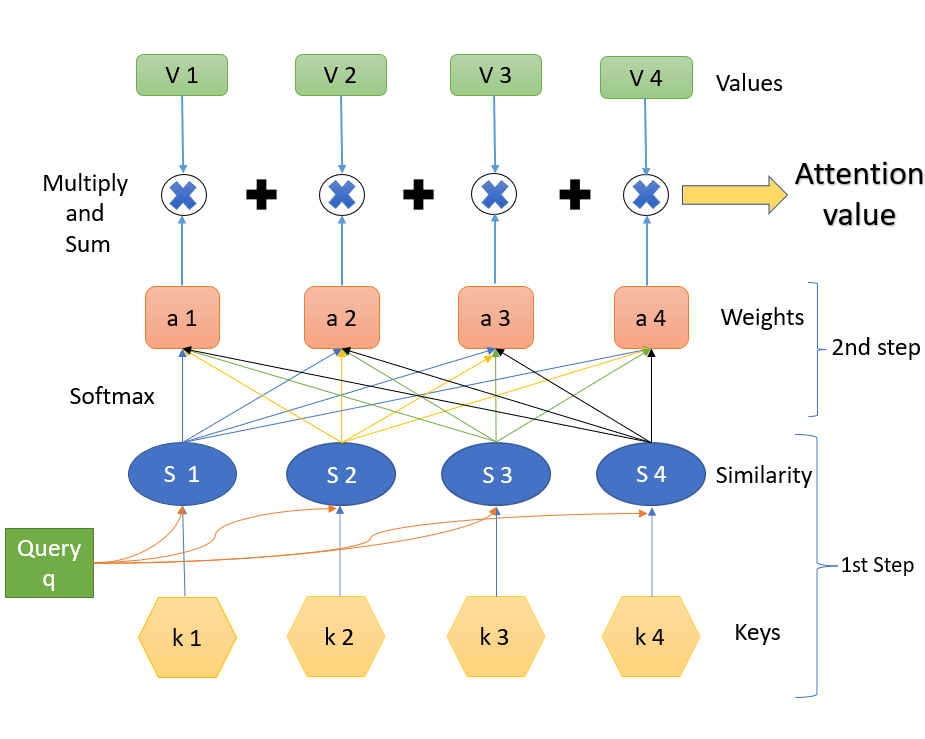
Attention, Self-Attention, Multi-head Attention, and Transformers
2022-09-10 · wnycstudios.org
Two scientists inadvertently open the Pandora’s Box of WMDs. What now?
2022-09-05 · mlwhiz.com
this post is explaining how permutation importance works and how we can code it using ELI5
2022-08-09 · amazon.science

To mark the occasion of the eighth Federated Logic Conference (FloC), Amazon’s Byron Cook, Daniel Kröning, and Marijn Heule discussed automated reasoning’s prospects.
2022-07-30 · towardsdatascience.com
AI for complex data
2022-07-30 · towardsdatascience.com
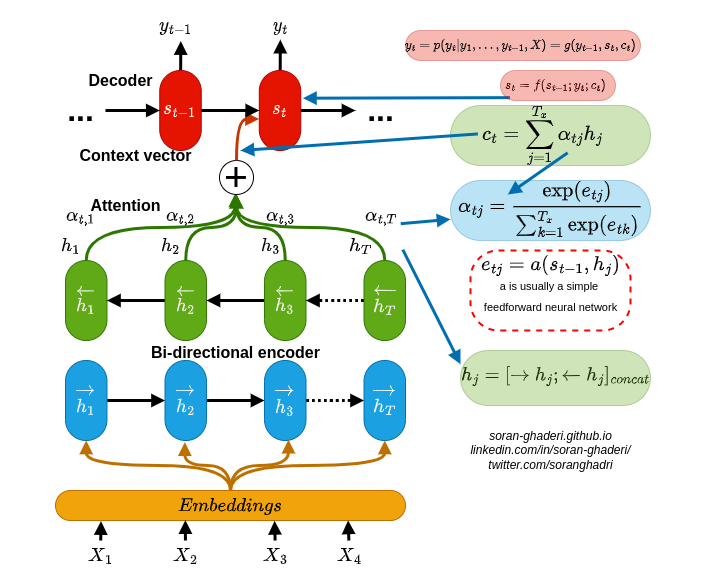
The brain, the mathematics, and DL — research frontiers in 2022
2022-07-24 · github.com

The fastai book, published as Jupyter Notebooks.
2022-07-18 · github.com

Interactive deep learning book with multi-framework code, math, and discussions. Adopted at 500 universities from 70 countries including Stanford, MIT, Harvard, and Cambridge. - d2l-ai/d2l-en
2022-07-18 · d2l.ai
2022-07-14 · towardsdatascience.com
An overview of DCGAN architecture with a step-by-step guide to building it yourself