Inside the AMD Radeon Instinct MI300A's Giant Memory Subsystem

AMD acquired ATI in 2006, hoping ATI's GPU expertise would combine with AMD's CPU know-how to create integrated solutions worth more than the sum of their parts.
AMD acquired ATI in 2006, hoping ATI's GPU expertise would combine with AMD's CPU know-how to create integrated solutions worth more than the sum of their parts.
Apple's latest machine learning research could make creating models for Apple Intelligence faster, by coming up with a technique to almost triple the rate of generating tokens when using Nvidia GPUs.

Intel's first Arc B580 GPUs based on the Xe2 "Battlemage" architecture have been leaked & they look quite compelling.
No matter how elegant and clever the design is for a compute engine, the difficulty and cost of moving existing – and sometimes very old – code from the

NVIDIA's Blackwell AI servers to witness a massive shipment volume in Q4 2024, with Microsoft being the most "aggressive" acquirer.

Speed and efficiency are crucial in computer graphics and simulation. It can be challenging to create high-performance simulations that can run smoothly on various hardware setups. Traditional methods can be slow and may not fully utilize the power of modern graphics processing…
Attention, as a core layer of the ubiquitous Transformer architecture, is a bottleneck for large language models and long-context applications. FlashAttention (and FlashAttention-2) pioneered an approach to speed up attention on GPUs by minimizing memory reads/writes, and is now…
Nscale has tested AMD's flagship Instinct MI300X AI accelerator utilizing the GEMM tuning framework, achieving 7x faster performance.
GPU maker tops new MLPerf benchmarks on graph neural nets and LLM fine-tuning
A New Annual Cadence for ML
It is not a coincidence that the companies that got the most “Hopper” H100 allocations from Nvidia in 2023 were also the hyperscalers and cloud builders,
Datacenter GPUs and some consumer cards now exceed performance limits
Beijing will be thrilled by this nerfed silicon
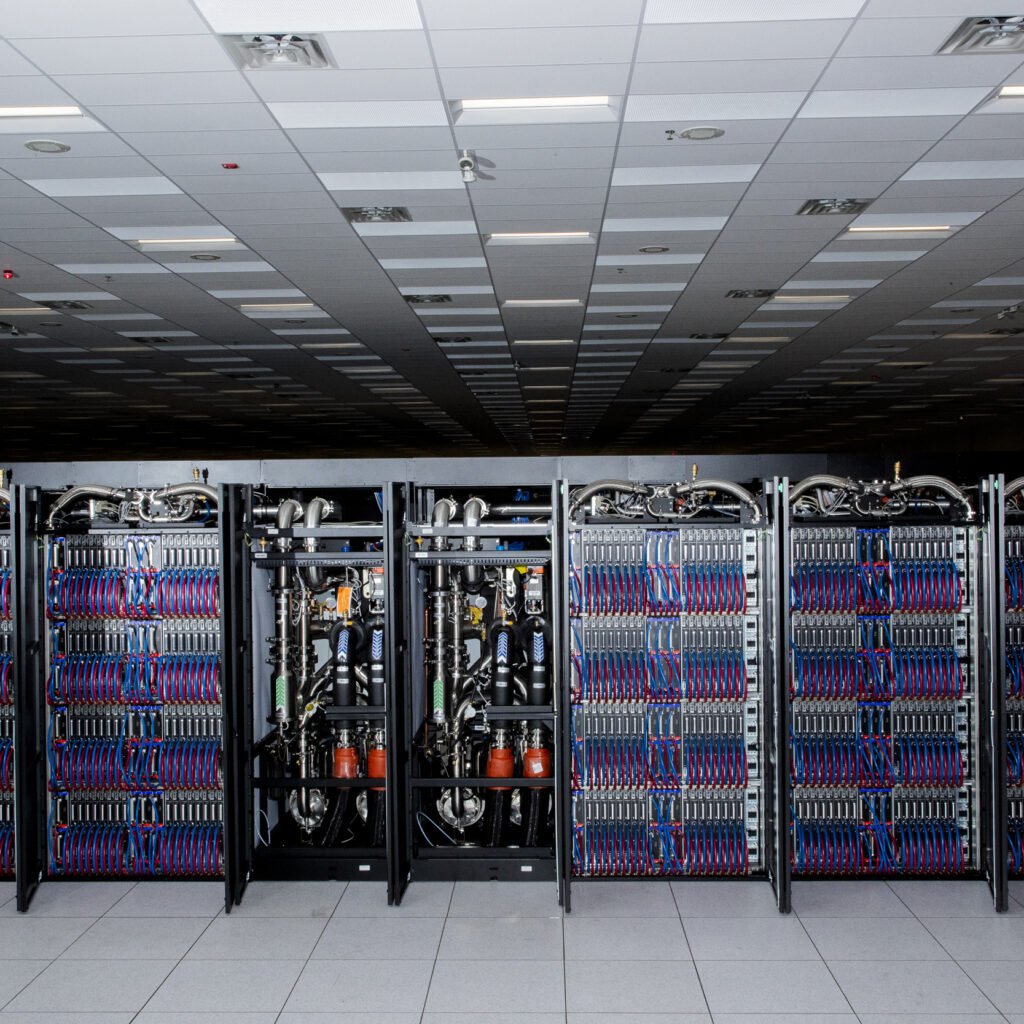
Today is the ribbon-cutting ceremony for the “Venado” supercomputer, which was hinted at back in April 2021 when Nvidia announced its plans for its first
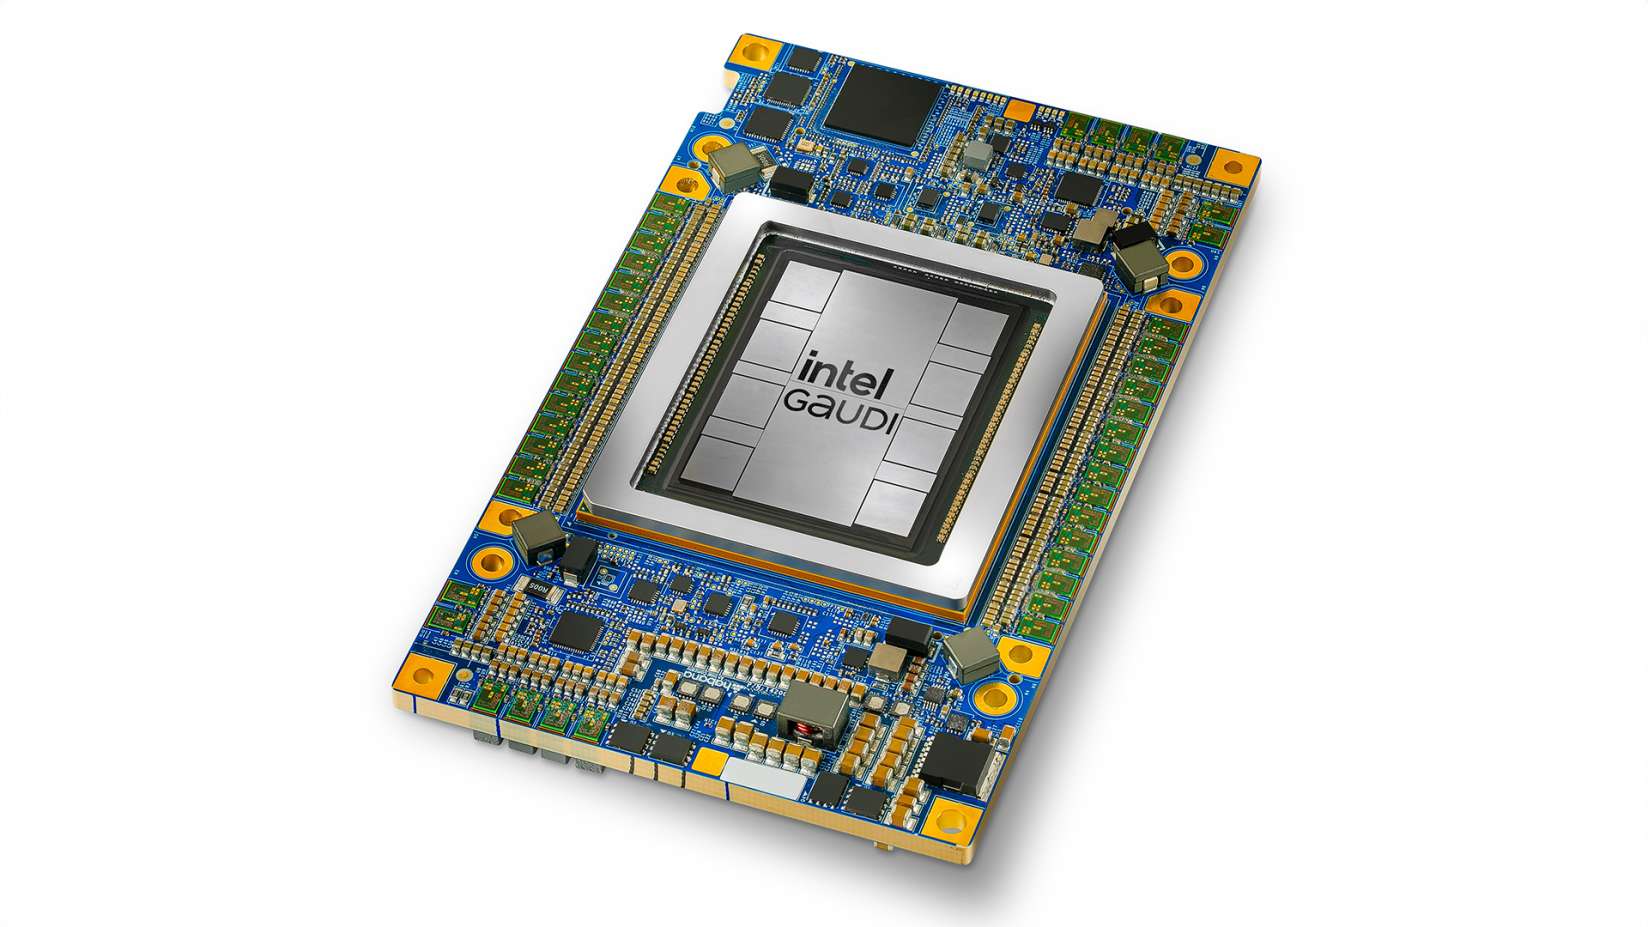
Intel claims 50% more speed when running AI language models vs. the market leader.
GPT-4 Profitability, Cost, Inference Simulator, Parallelism Explained, Performance TCO Modeling In Large & Small Model Inference and Training
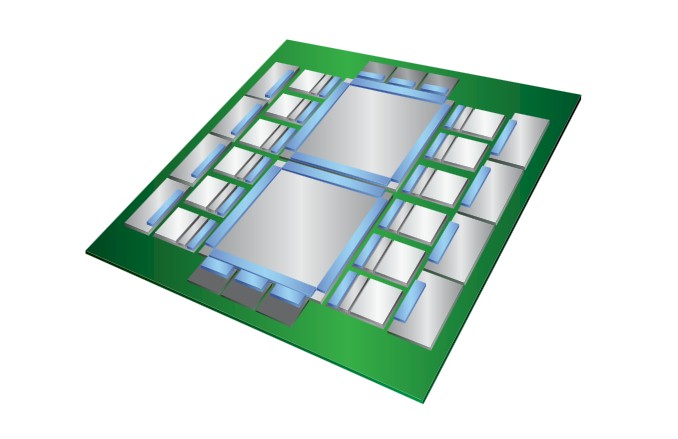
While a lot of people focus on the floating point and integer processing architectures of various kinds of compute engines, we are spending more and more

AMD plans to open-source portions of its ROCm software stack and hardware documentation in a future update to refine its ecosystem.

Lenovo, the firm emerging as a driving force behind AI computing, has expressed tremendous optimism about AMD's Instinct MI300X accelerator.
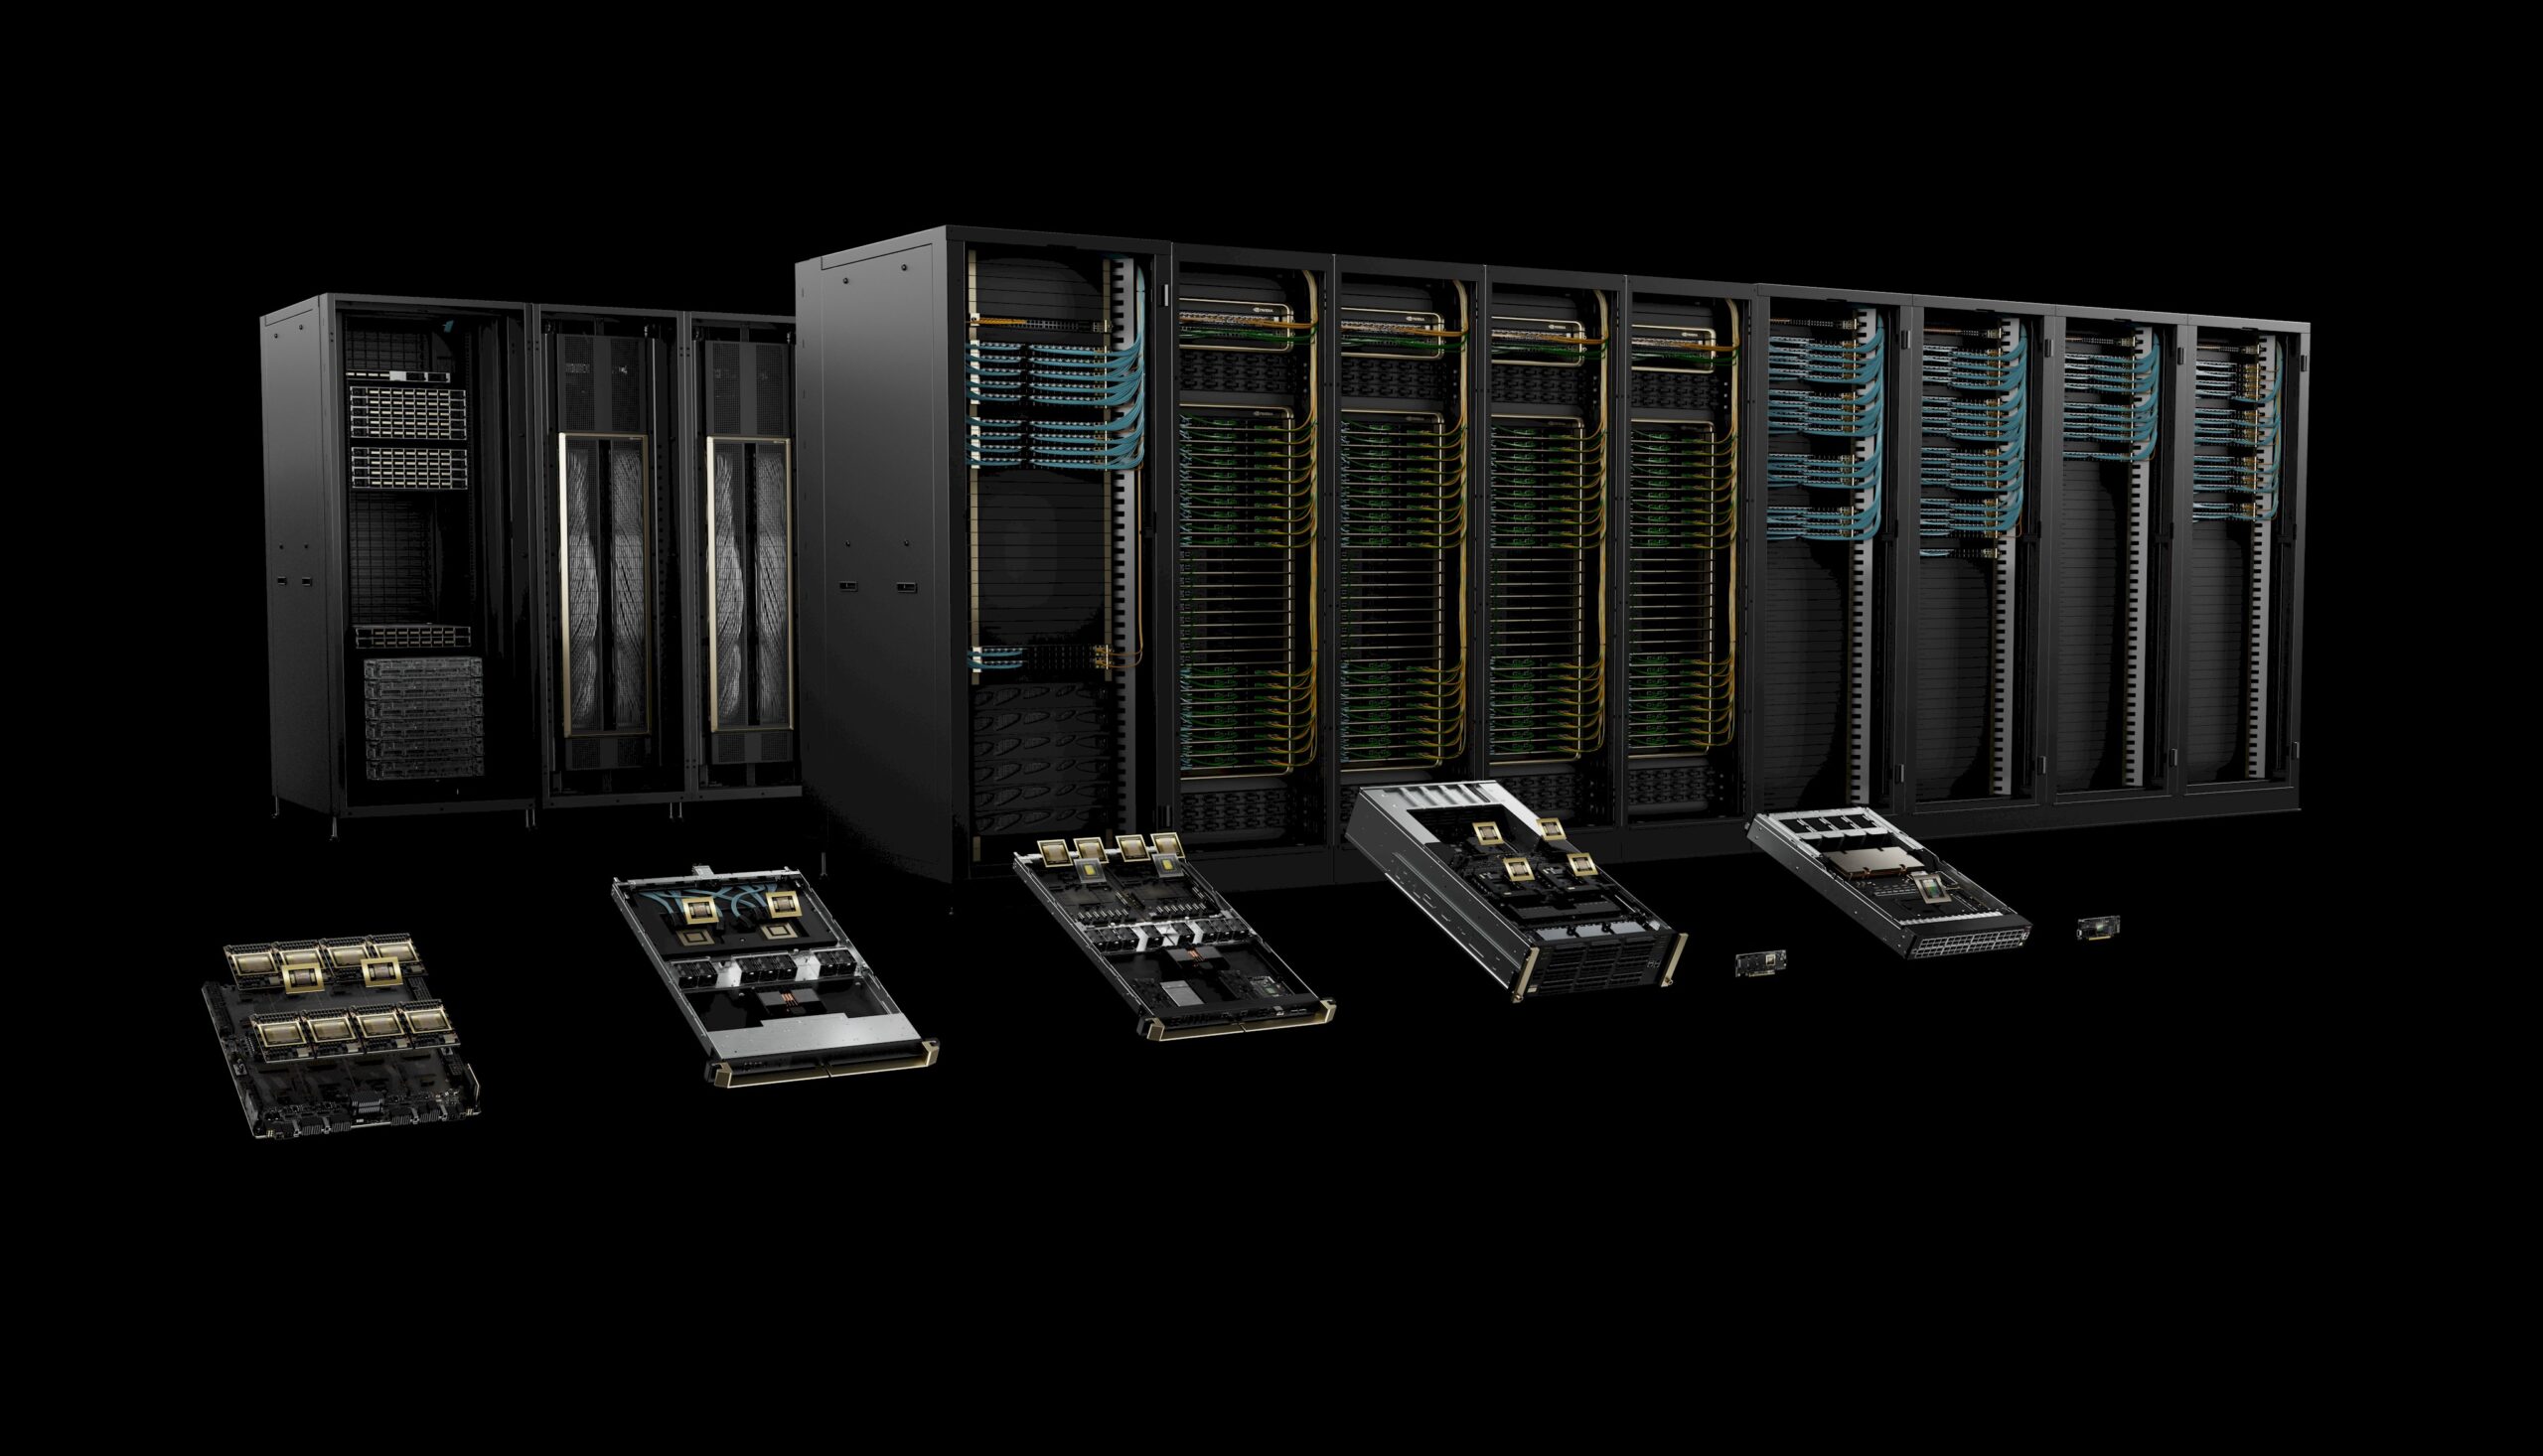
We like datacenter compute engines here at The Next Platform, but as the name implies, what we really like are platforms – how compute, storage,
While there have been efforts by AMD over the years to make it easier to port codebases targeting NVIDIA's CUDA API to run atop HIP/ROCm, it still requires work on the part of developers.

Chafing at their dependence, Amazon, Google, Meta and Microsoft are racing to cut into Nvidia’s dominant share of the market.
When discussing GenAI, the term "GPU" almost always enters the conversation and the topic often moves toward performance and access. Interestingly, the word "GPU" is assumed to mean "Nvidia" products. (As an aside, the popular Nvidia hardware used in GenAI are not technically...
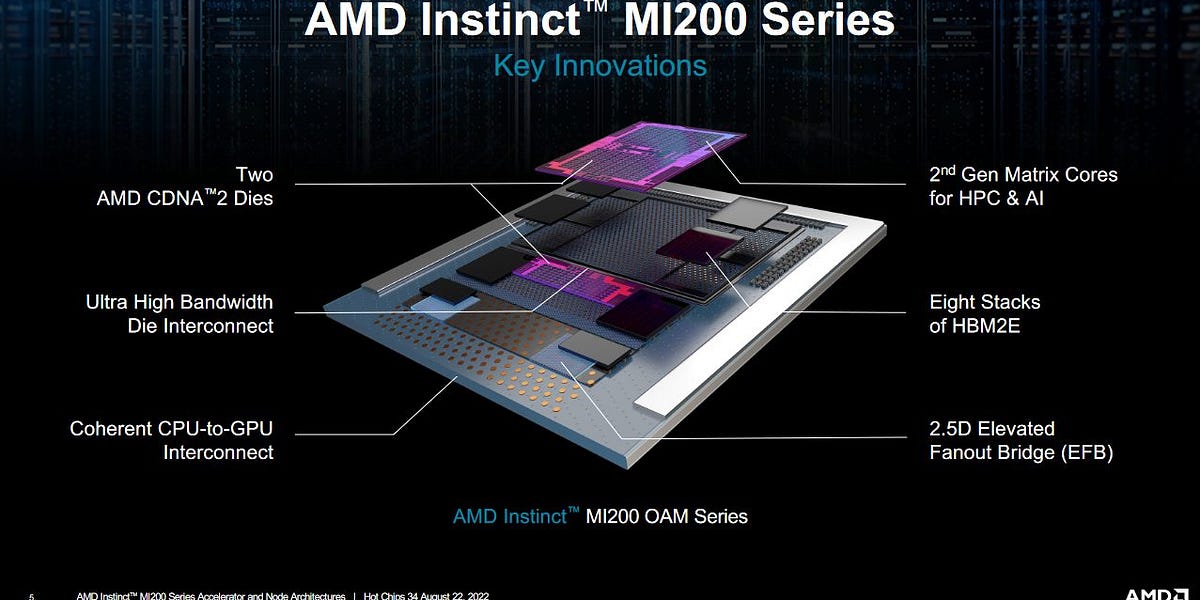
AMD, Nvidia, and Intel have all diverged their GPU architectures to separately optimize for compute and graphics.
We’re releasing Triton 1.0, an open-source Python-like programming language which enables researchers with no CUDA experience to write highly efficient GPU code—most of the time on par with what an expert would be able to produce.
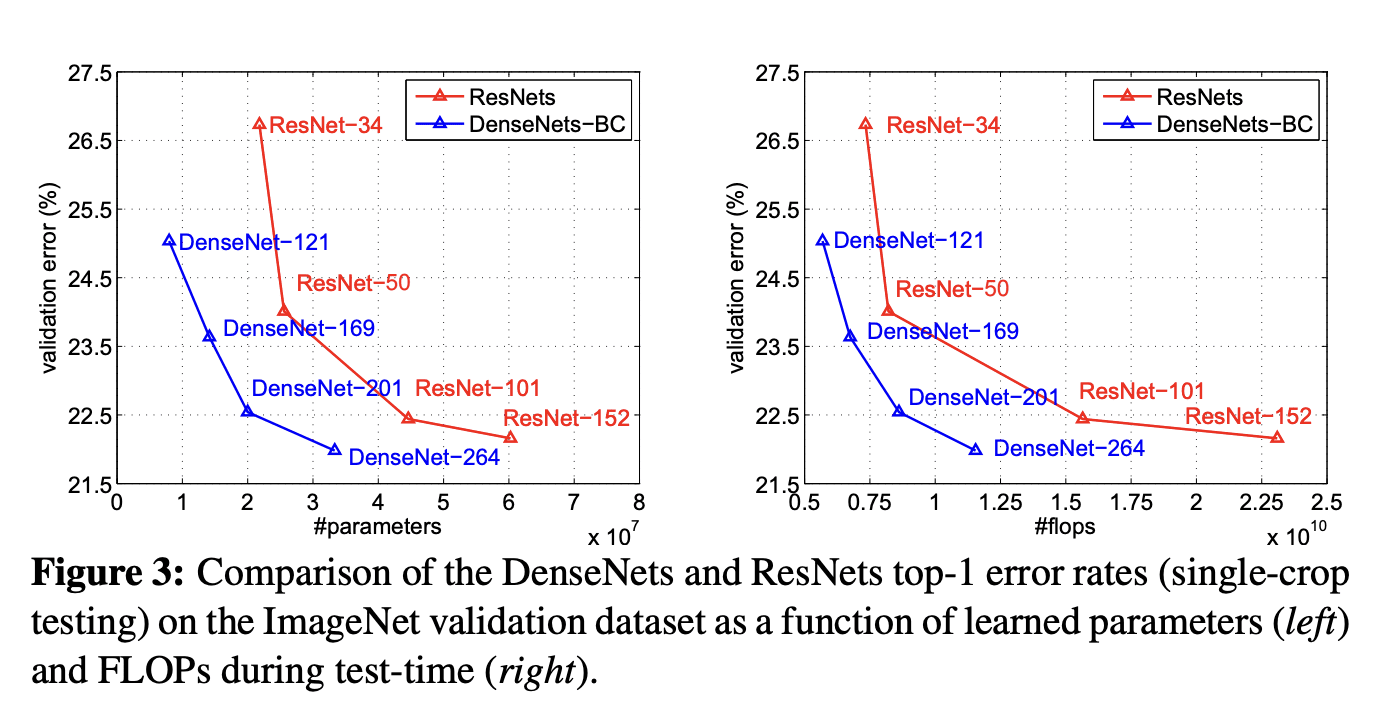
In this article we will learn about its definition, differences and how to calculate FLOPs and MACs using Python packages.
Quarterly Ramp for Nvidia, Broadcom, Google, AMD, AMD Embedded (Xilinx), Amazon, Marvell, Microsoft, Alchip, Alibaba T-Head, ZTE Sanechips, Samsung, Micron, and SK Hynix
GDDR7 is getting closer, says Micron.

Though it'll arrive just in time for mid-cycle refresh from AMD, Nvidia, and Intel, it's unclear if there will be any takers just yet.
Micron $MU looks very weak in AI
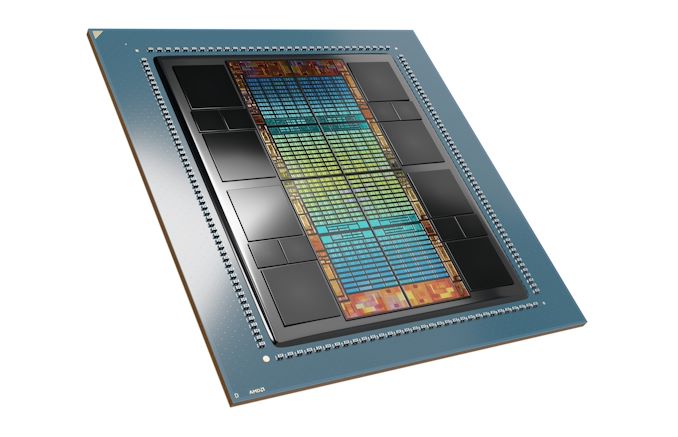
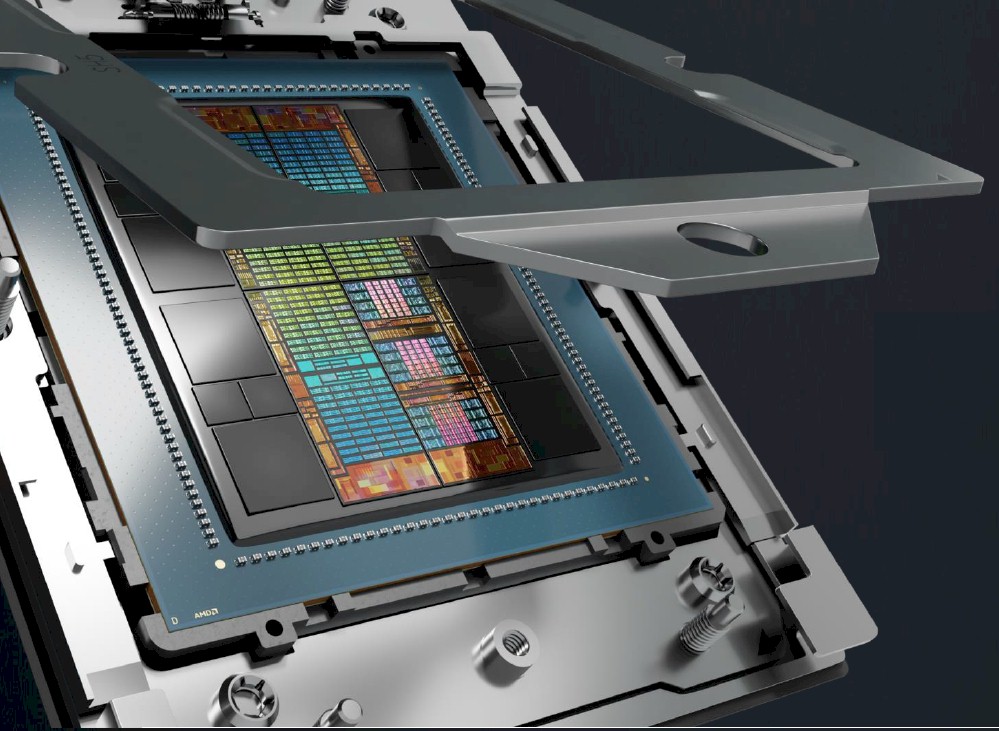
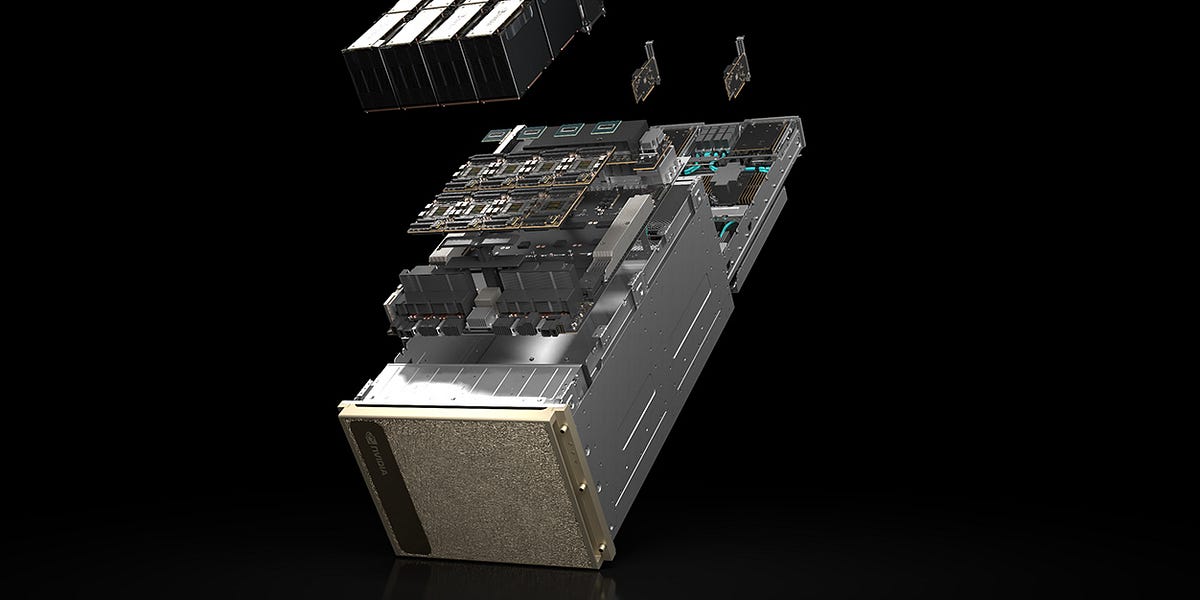
The great thing about the Cambrian explosion in compute that has been forced by the end of Dennard scaling of clock frequencies and Moore’s Law lowering
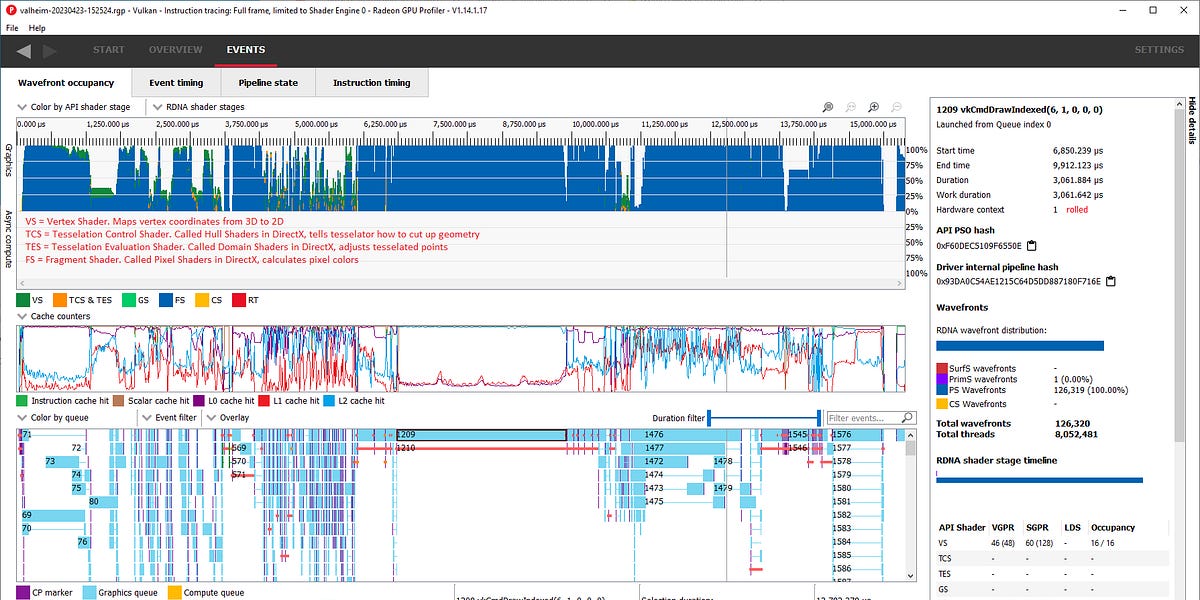
Editor’s Note (6/14/2023): We have a new article that reevaluates the cache latency of Navi 31, so please refer to that article for some new latency data.

GPUs may dominate, but CPUs could be perfect for smaller AI models

Google's new machines combine Nvidia H100 GPUs with Google’s high-speed interconnections for AI tasks like training very large language models.
Earlier this week a letter from an activist imprisoned in France was posted to the internet. Contained within Ivan Alococo’s dispatch from the Villepinte prison
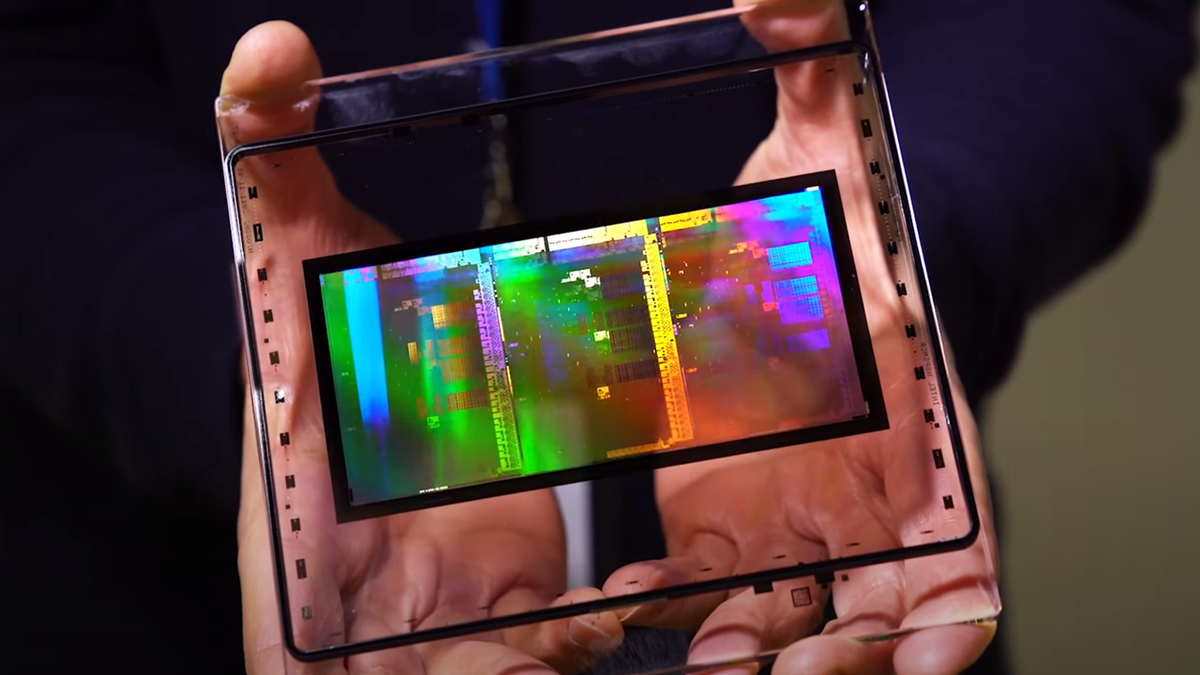
Faster masks, less power.
As computing system become more complex, it is becoming harder for programmers to keep their codes optimized as the hardware gets updated. Autotuners try to alleviate this by hiding as many archite…
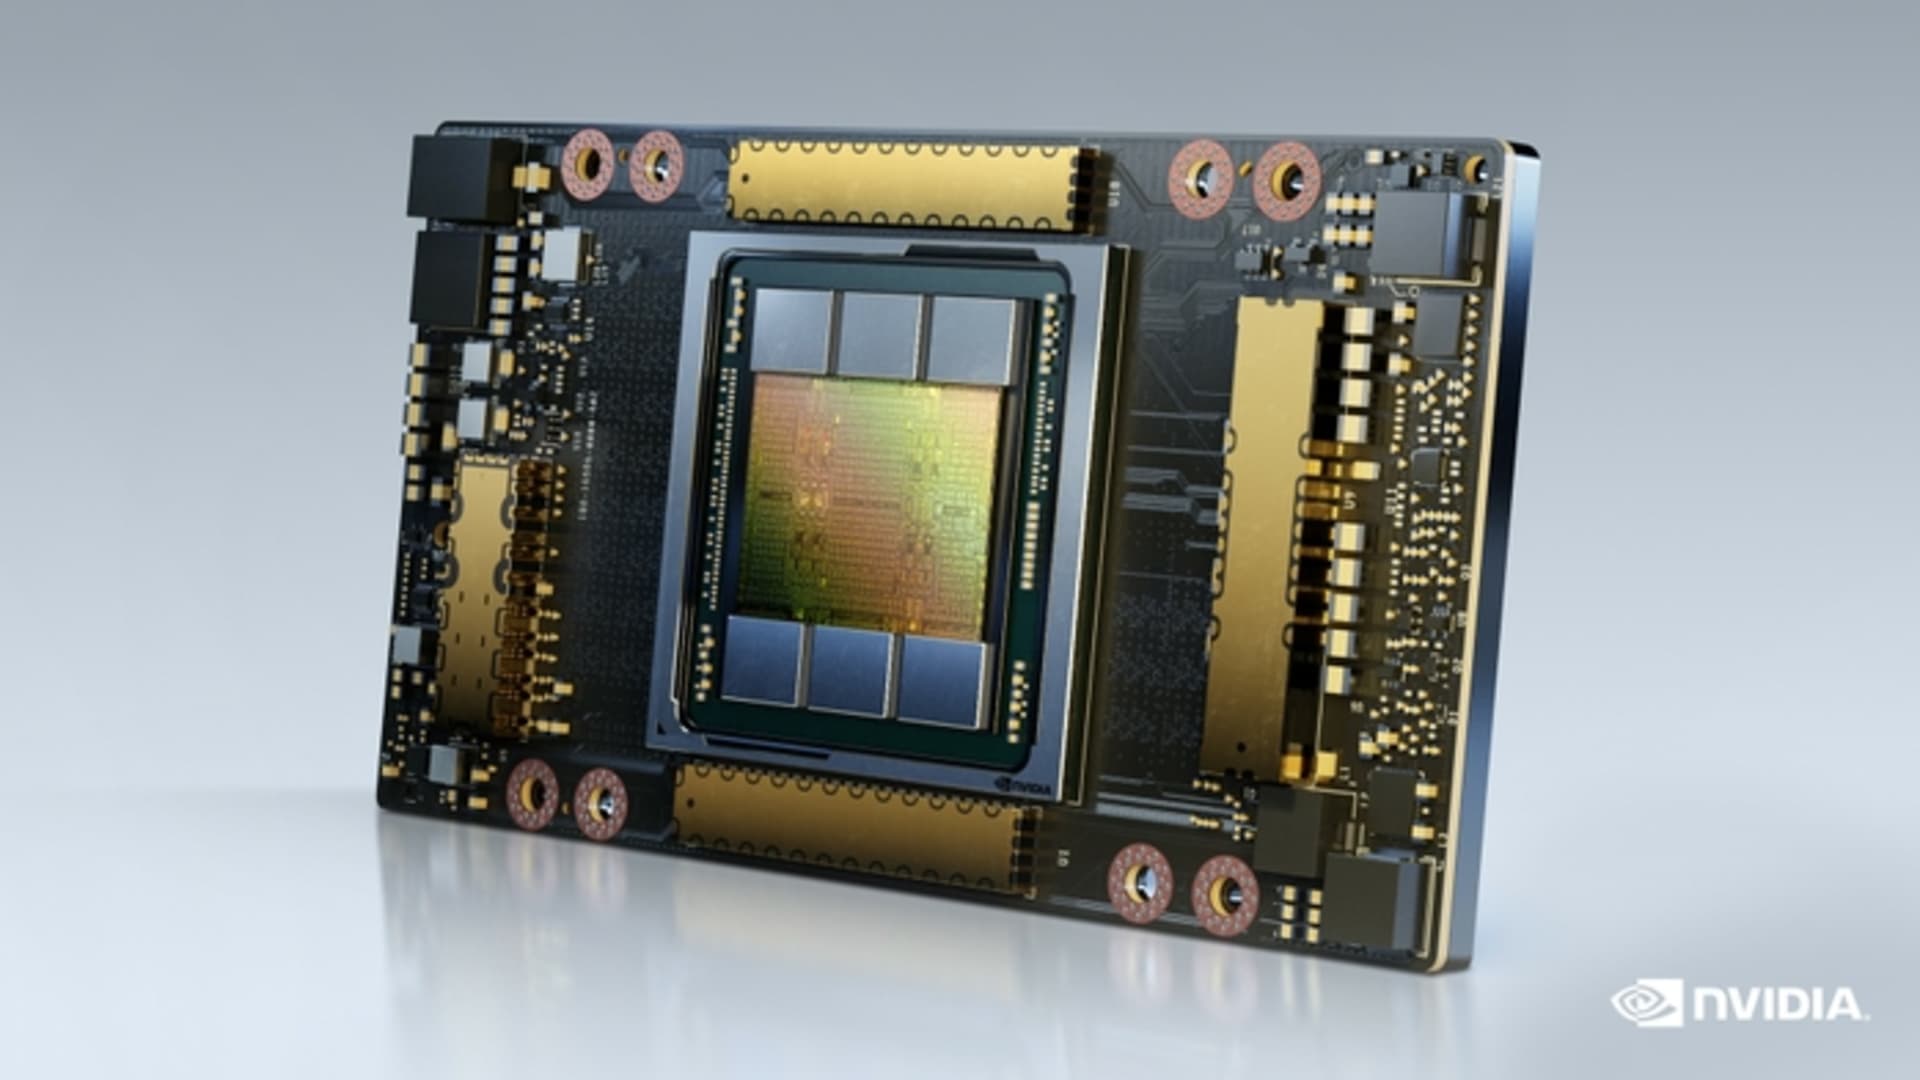
The $10,000 Nvidia A100has become one of the most critical tools in the artificial intelligence industry,
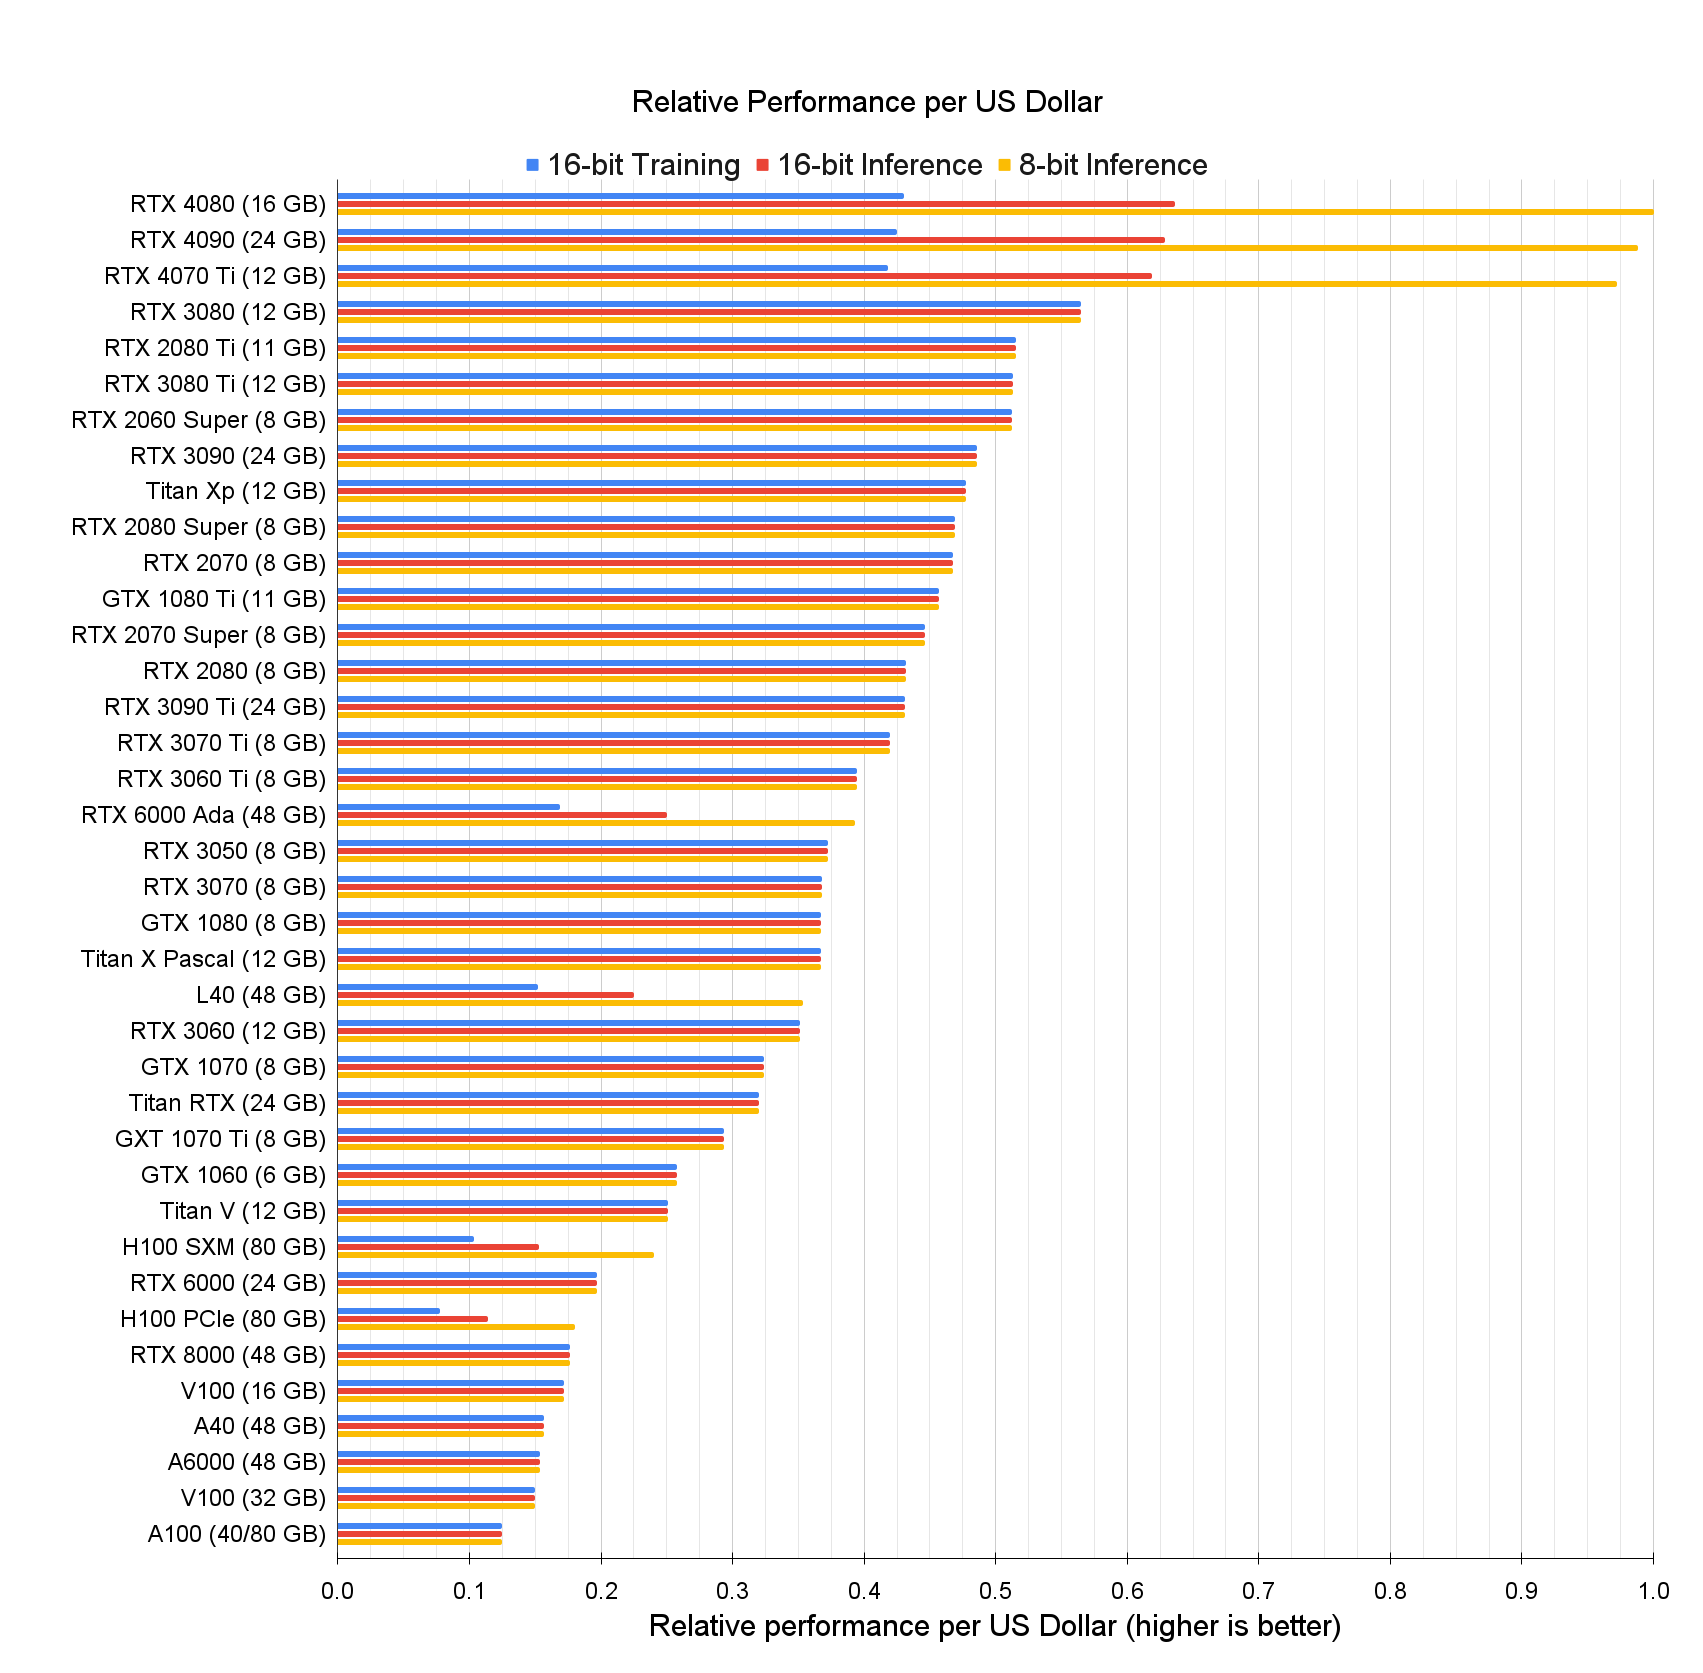
Here, I provide an in-depth analysis of GPUs for deep learning/machine learning and explain what is the best GPU for your use-case and budget.
NVIDIA announces the newest CUDA Toolkit software release, 12.0. This release is the first major release in many years and it focuses on new programming models and CUDA application acceleration…
The Power of PyTorch/XLA and how Amazon SageMaker Training Compiler Simplifies its use

A new video making the rounds purports to show Vietnamese crypto miners preparing used GPUs for resale by blasting them with a pressure washer.
There are two types of packaging that represent the future of computing, and both will have validity in certain domains: Wafer scale integration and
Nvidia has staked its growth in the datacenter on machine learning. Over the past few years, the company has rolled out features in its GPUs aimed neural
Nallatech doesn't make FPGAs, but it does have several decades of experience turning FPGAs into devices and systems that companies can deploy to solve
In this work, we analyze the performance of neural networks on a variety of heterogenous platforms. We strive to find the best platform in terms of raw benchmark performance, performance per watt a…